Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Haozhe Wu |
d2c94396aa | ||
|
Haozhe Wu
|
07e1adcbba | ||
|
Haozhe Wu
|
137689c5c1 | ||
|
Haozhe Wu
|
d77c64e2ce | ||
|
Haozhe Wu
|
94c2a8ffb2 | ||
|
Haozhe Wu
|
1676eaa328 | ||
|
Haozhe Wu
|
6d7d365892 | ||
|
Haozhe Wu
|
fd9e5fc689 | ||
|
Haozhe Wu
|
2f9fa22a56 | ||
|
Teerapat VatpitakandHaozhe Wu
|
39aaa62008 | ||
|
Teerapat Vatpitak
|
220abb10a1 | ||
|
Teerapat Vatpitak
|
14ba958513 | ||
|
Haozhe Wu
|
0e42cbe4c8 | ||
|
Haozhe Wu
|
9769e5b543 | ||
|
Haozhe Wu
|
101eb9b614 | ||
|
Teerapat Vatpitak
|
bdb9dfca55 | ||
|
Haozhe Wu
|
b1acd830d2 | ||
|
Haozhe Wu
|
8f49fe4902 | ||
|
shadowinlifeandshadowinlife
|
e346fa1adf | ||
|
Haozhe Wu
|
55d81a6c53 | ||
|
Haozhe Wu
|
db21715cf9 | ||
|
Teerapat Vatpitak
|
dce3eb94c2 | ||
|
Haozhe Wu
|
1190ee9735 | ||
|
Haozhe Wu
|
eba0f1f8a1 | ||
|
Haozhe Wu
|
298ada79b7 | ||
|
Haozhe Wu
|
7b27f6e3e2 | ||
|
Teerapat Vatpitak
|
02a16a6422 | ||
|
Haozhe Wu
|
6b6683a026 | ||
|
Haozhe Wu
|
45a9f525e4 | ||
|
Haozhe Wu
|
75ecbce1fc | ||
|
Haozhe Wu
|
4604d4c67a | ||
|
Teerapat-Vatpitak
|
16102825b4 | ||
|
Teerapat-Vatpitak
|
2d80b6248c | ||
|
Teerapat-Vatpitak
|
0e0a584d85 | ||
|
Teerapat-Vatpitak
|
32a96fb5b2 | ||
|
Haozhe Wu
|
b41141fa8f | ||
|
Haozhe Wu
|
0678fd195a | ||
|
Haozhe Wu
|
fb7efe76f6 | ||
|
Haozhe Wu
|
9e70dca97c | ||
|
Haozhe Wu
|
e7d72be574 | ||
|
Haozhe Wu
|
3981eb53f8 | ||
|
Peng QianandClaude Opus 4.6
|
ca26b0660a | ||
|
Peng QianandClaude Opus 4.6
|
5d90f3317f | ||
|
Peng QianandClaude Opus 4.6
|
37e287c6c7 | ||
|
Haozhe Wu
|
3daa8dfae8 | ||
|
ykj@hku
|
7320ac8d01 | ||
|
Teerapat Vatpitak
|
96dbdb8050 | ||
|
d 🔹
|
ac955c5692 | ||
|
Teerapat Vatpitak
|
5731868a20 | ||
|
Teerapat Vatpitak
|
b1d363b33c | ||
|
Haozhe Wu
|
fbe37e0f63 | ||
|
Haozhe Wu
|
1e0a7a0dd8 | ||
|
Haozhe Wu
|
bb977f2614 | ||
|
Haozhe Wu
|
209334d609 | ||
|
Haozhe Wu
|
f55ef1ffb9 | ||
|
Teerapat Vatpitak
|
ba7cd19564 | ||
|
Teerapat Vatpitak
|
80e177228f | ||
|
Teerapat Vatpitak
|
51d0188cc5 | ||
|
Teerapat Vatpitak
|
5eb8390921 | ||
|
Hitesh PandClaude Opus 4.7
|
09dd59e9aa | ||
|
Teerapat Vatpitak
|
5eef5f3bd3 | ||
|
Haozhe Wu
|
9fe6698d17 | ||
|
Haozhe Wu
|
79efe1d6a8 | ||
|
Teerapat Vatpitak
|
dd594080c3 | ||
|
Haozhe Wu
|
5f411ddaf7 | ||
|
Haozhe Wu
|
b9a82655bd | ||
|
Haozhe Wu
|
bd722334d3 | ||
|
voidborne-d
|
977fddfbff | ||
|
SJoon99
|
e2535cc7c3 | ||
|
Haozhe Wu
|
52b624d3c8 | ||
|
Haozhe Wu
|
4115960a42 | ||
|
Haozhe Wu
|
4fd82a0952 | ||
|
Haozhe Wu
|
4ae673b6d1 | ||
|
MrBob
|
94d0589638 | ||
|
Haozhe Wu
|
0f4e3d7110 | ||
|
Haozhe Wu
|
d1273171a6 | ||
|
Andrew Barnes
|
947d945827 | ||
|
Haozhe Wu
|
41fa4ad0b0 | ||
|
Haozhe Wu
|
2fc8c90d9f | ||
|
Haozhe Wu
|
946d9ae3b9 | ||
|
Haozhe Wu
|
f917b71960 | ||
|
SiMinus
|
ecf1e51915 | ||
|
Haozhe Wu
|
052277bb56 | ||
|
Haozhe Wu
|
7e167ea238 | ||
|
Haozhe Wu
|
688d388551 | ||
|
Haozhe Wu
|
012a499f74 | ||
|
Haozhe Wu
|
14c97d7c19 | ||
|
Haozhe Wu
|
9454d4a27a | ||
|
RuifengFu
|
5c3d5f98a2 | ||
|
Haozhe Wu
|
fd767f5c29 | ||
|
Haozhe Wu
|
fd7384e472 | ||
|
Haozhe Wu
|
3d812ae5ec | ||
|
Haozhe Wu
|
5bafac3de8 | ||
|
Haozhe Wu
|
319255c54b | ||
|
MB-Ndhlovu
|
c3174bacb9 | ||
|
ykj@hku
|
1cbbaab88e | ||
|
Malibongwe Ndhlovu
|
72e4488a45 | ||
|
Haozhe Wu
|
246d5a0dc3 | ||
|
shadowinlife
|
55972c3e9b | ||
|
Malibongwe Ndhlovu
|
b18f22bc94 | ||
|
Malibongwe Ndhlovu
|
6512c7ba2c | ||
|
Malibongwe Ndhlovu
|
27cc7e74a8 | ||
|
Haozhe Wu
|
cb87c3a37d | ||
|
BigNounce
|
f1f3e00c97 | ||
|
TaoMu
|
6af0a86e2f | ||
|
warren618
|
4dcb33034a | ||
|
warren618
|
aae5a7ec1a | ||
|
warren618
|
300f5c2f4f | ||
|
warren618
|
05fc5cac22 | ||
|
Brandy Goodandgenoshide
|
cd999a8d5b | ||
|
warren618
|
69a4dc69f9 | ||
|
MB-Ndhlovu
|
ffa95a9f51 | ||
|
warren618
|
29fd1f91fa | ||
|
warren618
|
0b9b4d8f64 | ||
|
warren618
|
5c9488d30b | ||
|
warren618
|
0a38ba5ef0 | ||
|
warren618
|
8fdf4f8014 | ||
|
Hamza Mobeen
|
bc62206ad6 | ||
|
Hamza Mobeen
|
4b28a4d1b4 | ||
|
warren618
|
b76af14d00 | ||
|
Mothilal M
|
63ca24867c | ||
|
Hamza Mobeen
|
f9022a3ac4 | ||
|
warren618
|
fc708d15c5 | ||
|
warren618
|
a1040bbb71 | ||
|
warren618
|
b769580389 | ||
|
warren618
|
e6ceb5a3b3 | ||
|
warren618
|
d4c730213f | ||
|
warren618
|
f866e5fb14 | ||
|
warren618
|
b6adee5651 | ||
|
warren618
|
73b179a28d | ||
|
warren618
|
da2df110b1 | ||
|
yule153604and@yule153604
|
0efa443429 | ||
|
warren618
|
93db691583 | ||
|
warren618
|
a35e870aad | ||
|
warren618
|
2c80efcd77 | ||
|
warren618
|
25380bac96 | ||
|
warren618
|
c090d1fce8 | ||
|
warren618
|
8e45d2c4ee | ||
|
warren618
|
2b0a775db0 | ||
|
warren618
|
01996fff7c | ||
|
warren618
|
5709e20a20 | ||
|
warren618
|
c0074da1d2 | ||
|
warren618
|
e2a4654edb | ||
|
warren618
|
6caa1d523f | ||
|
warren618
|
c74a059afb | ||
|
jiakeboge
|
0bd40354bc | ||
|
|
e8e86e1a1d | ||
|
warren618
|
5de1f82e27 | ||
|
warren618
|
4e52ed7e77 | ||
|
warren618
|
59fb021c58 | ||
|
warren618
|
1f8f4a005f | ||
|
warren618
|
940624a2d6 | ||
|
warren618
|
e2de75c3b6 | ||
|
Haozhe Wu
|
cb85af67b5 | ||
|
SoufianoDev
|
e9d04a10e5 | ||
|
warren618
|
66cd96a303 | ||
|
warren618
|
ed47b26b5c | ||
|
warren618
|
0aea8b0150 | ||
|
warren618
|
ddeb371632 | ||
|
warren618
|
a8828c16f3 | ||
|
warren618
|
2772ecb688 |
No files matched your search
@@ -0,0 +1,39 @@
|
||||
{
|
||||
"name": "Vibe-Trading",
|
||||
"image": "mcr.microsoft.com/devcontainers/python:1-3.11-bookworm",
|
||||
"features": {
|
||||
"ghcr.io/devcontainers/features/node:1": {
|
||||
"version": "20"
|
||||
}
|
||||
},
|
||||
"forwardPorts": [
|
||||
8899,
|
||||
5899
|
||||
],
|
||||
"portsAttributes": {
|
||||
"8899": {
|
||||
"label": "Vibe-Trading API",
|
||||
"onAutoForward": "notify",
|
||||
"visibility": "private"
|
||||
},
|
||||
"5899": {
|
||||
"label": "Vibe-Trading Frontend",
|
||||
"onAutoForward": "notify",
|
||||
"visibility": "private"
|
||||
}
|
||||
},
|
||||
"postCreateCommand": "python -m pip install --upgrade pip && python -m pip install -e . && cd frontend && npm install",
|
||||
"customizations": {
|
||||
"vscode": {
|
||||
"extensions": [
|
||||
"ms-python.python",
|
||||
"ms-python.vscode-pylance",
|
||||
"dbaeumer.vscode-eslint",
|
||||
"esbenp.prettier-vscode"
|
||||
],
|
||||
"settings": {
|
||||
"python.defaultInterpreterPath": "/usr/local/bin/python"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -67,7 +67,7 @@ body:
|
||||
attributes:
|
||||
label: Version
|
||||
description: "Run `pip show vibe-trading-ai` to check"
|
||||
placeholder: "e.g., 0.1.3"
|
||||
placeholder: "e.g., 0.1.5"
|
||||
|
||||
- type: input
|
||||
id: environment
|
||||
|
||||
@@ -0,0 +1,32 @@
|
||||
name: Deploy Wiki
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- "wiki/**"
|
||||
- ".github/workflows/wiki-deploy.yml"
|
||||
|
||||
concurrency:
|
||||
group: wiki-deploy
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
name: Deploy to Cloudflare Pages
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
deployments: write
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Deploy wiki
|
||||
uses: cloudflare/wrangler-action@v3
|
||||
with:
|
||||
apiToken: ${{ secrets.CLOUDFLARE_API_TOKEN }}
|
||||
accountId: ${{ secrets.CLOUDFLARE_ACCOUNT_ID }}
|
||||
command: pages deploy wiki --project-name=vibetrading-wiki --branch=main
|
||||
gitHubToken: ${{ secrets.GITHUB_TOKEN }}
|
||||
@@ -0,0 +1,52 @@
|
||||
name: Wiki
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [main]
|
||||
paths:
|
||||
- "wiki/**"
|
||||
- ".github/workflows/wiki.yml"
|
||||
pull_request:
|
||||
branches: [main]
|
||||
paths:
|
||||
- "wiki/**"
|
||||
- ".github/workflows/wiki.yml"
|
||||
|
||||
jobs:
|
||||
validate:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 5
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
|
||||
- uses: actions/setup-node@v4
|
||||
with:
|
||||
node-version: "20"
|
||||
|
||||
- uses: actions/setup-python@v5
|
||||
with:
|
||||
python-version: "3.11"
|
||||
|
||||
- name: Check JavaScript syntax
|
||||
run: |
|
||||
node --check wiki/main.js
|
||||
node --check wiki/theme.js
|
||||
node --check wiki/docs/content.js
|
||||
node --check wiki/docs/main.js
|
||||
|
||||
- name: Check locale JSON
|
||||
run: python -m json.tool wiki/locales/en.json >/dev/null
|
||||
|
||||
- name: Check static site files
|
||||
run: |
|
||||
test -f wiki/index.html
|
||||
test -f wiki/home/index.html
|
||||
test -f wiki/docs/index.html
|
||||
test -f wiki/tutorials/index.html
|
||||
test -f wiki/alpha-library/index.html
|
||||
test -f wiki/research-lab/index.html
|
||||
test -f wiki/_redirects
|
||||
test -f wiki/_headers
|
||||
test -f wiki/assets/icon.png
|
||||
! grep -R "localhost\\|nanobot" wiki --exclude=README.md
|
||||
+38
-1
@@ -1,4 +1,4 @@
|
||||
.venv/
|
||||
.venv/
|
||||
agent/.venv/
|
||||
__pycache__/
|
||||
.pytest_cache/
|
||||
@@ -16,10 +16,21 @@ agent/sessions/
|
||||
agent/runs/
|
||||
agent/.ui_runtime/
|
||||
agent/.tasks/
|
||||
agent/uploads/
|
||||
agent/tests/*_result.json
|
||||
.ruff_cache/
|
||||
frontend/dist/
|
||||
frontend/tsconfig.tsbuildinfo
|
||||
wiki/node_modules/
|
||||
wiki/dist/
|
||||
wiki/.astro/
|
||||
wiki/.vite/
|
||||
wiki/.wrangler/
|
||||
wiki/.cache/
|
||||
.vibe-dev/
|
||||
.vibe-record/
|
||||
.cache/
|
||||
.remotion/
|
||||
|
||||
# DuckDB data cache
|
||||
data/*.duckdb
|
||||
@@ -30,6 +41,8 @@ data/backup/
|
||||
|
||||
# Internal docs (plans, specs)
|
||||
docs/
|
||||
!wiki/docs/
|
||||
!wiki/docs/**
|
||||
data/minutes/
|
||||
data/overnight*.log
|
||||
data/*.log
|
||||
@@ -40,3 +53,27 @@ agent/vibe_trading_ai.egg-info/
|
||||
agent/tests/e2e_backtest/
|
||||
dist/
|
||||
build/
|
||||
|
||||
# Local demo videos (too large for git; link to external host instead)
|
||||
assets/*.mp4
|
||||
|
||||
# Local demo / promo production workspace
|
||||
demo/
|
||||
|
||||
# Manual E2E smoke tests — require live API keys (OpenRouter / yfinance),
|
||||
# would break CI if committed. Kept local; run explicitly when validating
|
||||
# a release.
|
||||
agent/tests/e2e_*.py
|
||||
agent/tests/test_e2e_*.py
|
||||
|
||||
# Local working notes
|
||||
NOTES.md
|
||||
|
||||
# Agent tool aliases (auto-generated mirror of CLAUDE.md)
|
||||
AGENTS.md
|
||||
|
||||
.DS_Store
|
||||
|
||||
# Alpha Zoo wiki artifacts (generated, not source)
|
||||
wiki/alpha-library/manifest.json
|
||||
wiki/alpha-library/content/
|
||||
+122
@@ -0,0 +1,122 @@
|
||||
# Changelog
|
||||
|
||||
All notable changes to Vibe-Trading are documented in this file.
|
||||
This project adheres to [Semantic Versioning](https://semver.org/).
|
||||
|
||||
## [Unreleased]
|
||||
|
||||
### Added
|
||||
|
||||
### Changed
|
||||
|
||||
### Fixed
|
||||
|
||||
## [0.1.8] — 2026-05-17
|
||||
|
||||
### Added — Alpha Zoo (450+ pre-built quant alphas)
|
||||
- `agent/src/factors/` — base operators (`rank`, `scale`, `ts_*`, `delta`,
|
||||
`decay_linear`, `signed_power`, `safe_div`, market-aware `vwap`) and a
|
||||
registry that AST-extracts metadata from each alpha module without
|
||||
importing it. Lookahead is enforced at the operator level
|
||||
(`delta(d>=1)`), and registry sanity checks reject `+/-inf` and
|
||||
outputs that are more than 95 % NaN.
|
||||
- 4 zoos shipping 452 alphas total:
|
||||
- **qlib158** (154 alphas) — port of Microsoft Qlib's `Alpha158`
|
||||
feature handler under Apache-2.0, with pinned commit SHA per file.
|
||||
- **alpha101** (101 alphas) — implementation of Kakushadze (2015)
|
||||
*"101 Formulaic Alphas"* (arXiv:1601.00991), written from the paper
|
||||
appendix; the relevant trademarked string is intentionally absent.
|
||||
- **gtja191** (191 alphas) — implementation of Guotai Junan's 2014
|
||||
*"191 Short-period Trading Alpha Factors"* research report.
|
||||
- **academic** (6 factors) — Fama-French 5 + Carhart momentum, shipped
|
||||
as honest price-based proxies (not the canonical FF series).
|
||||
- `vibe-trading alpha {list,show,bench,compare,export-manifest}` CLI
|
||||
subcommand. `show` and `export-manifest` enforce path-traversal guards.
|
||||
- New agent tools: `AlphaZooTool` (browse) and `AlphaBenchTool`
|
||||
(orchestrator with Jinja2 autoescape + strict CSP HTML report).
|
||||
- `ZooSignalEngine.from_zoo(...)` — composite multi-factor signal engine
|
||||
with cross-sectional standardisation, weighting, and optional top-N /
|
||||
bottom-N long-short conversion.
|
||||
- `wiki/scripts/build_alpha_library.py` — Alpha Library renderer.
|
||||
Reads `manifest.json` produced by `vibe-trading alpha export-manifest`
|
||||
and emits 452 per-alpha HTML pages plus 4 per-zoo overviews, each with
|
||||
`script-src 'none'` CSP. The landing page hydrates per-zoo counts
|
||||
from `content/index.json`.
|
||||
- New blog post: *"Which of the 191 GTJA alphas still work in 2026?"*
|
||||
with aggregate IC statistics, theme breakdown, and the top alphas
|
||||
that survive eight years of out-of-sample data.
|
||||
|
||||
### Added — Web UI for Alpha Zoo
|
||||
- New page at `/alpha-zoo` in the Vite + React frontend with three
|
||||
views: browse (4 zoo cards + filter bar + paginated table), detail
|
||||
(formula, metadata, collapsible source code), and bench-runner
|
||||
(form → SSE-streamed progress + Alive/Reversed/Dead stat cards +
|
||||
Top-5-by-IR table + by-theme breakdown chart). "Alpha Zoo" nav
|
||||
entry added to the layout.
|
||||
- Four new REST routes in the FastAPI server:
|
||||
- `GET /alpha/list` — filterable alpha catalogue
|
||||
- `GET /alpha/{alpha_id}` — meta + source code
|
||||
- `POST /alpha/bench` — kicks off a background bench job and
|
||||
returns a `job_id`
|
||||
- `GET /alpha/bench/{job_id}/stream` — Server-Sent Events with
|
||||
`progress`, `result`, `done`, and `error` event types. In-memory
|
||||
job state with a 1-hour TTL; no Redis/Celery dependency.
|
||||
- Bench math is refactored into `agent/src/factors/bench_runner.py`
|
||||
so the CLI driver (`agent/scripts/w4a_run_benches.py`) and the new
|
||||
API worker share a single implementation.
|
||||
|
||||
### Added — Safety floor
|
||||
- `agent/tests/factors/test_alpha_purity.py` — AST allowlist scan over
|
||||
every `zoo/**/*.py` module (whitelist: pandas, numpy, scipy.\*,
|
||||
`src.factors.base`, `__future__`, `typing`, `math`, `dataclasses`;
|
||||
banned: `os`, `sys`, `subprocess`, `socket`, `urllib`, `requests`,
|
||||
`httpx`, `pathlib`, `Path`, `open`, `eval`, `exec`, `compile`,
|
||||
`__import__`, and `getattr(_, "__*")`).
|
||||
- `agent/tests/factors/test_lookahead.py` — sentinel future-row
|
||||
injection on a 300-row synthetic panel; corrupting rows after the
|
||||
probe must leave the probe value unchanged within 1e-9.
|
||||
- `tools/ci_grep_gates.sh` — CI gate that rejects `yaml.load(` without
|
||||
`safe_load`, any trademarked-name leak in shipped artifacts, and any
|
||||
per-stock-code data leak in `wiki/**/*.{json,csv,html}`.
|
||||
- `agent/tests/factors/conftest.py` — opt-in `pytest-socket` integration
|
||||
that hard-fails any test attempting outbound network during the
|
||||
factors test suite.
|
||||
|
||||
### Added — Community governance
|
||||
- `CONTRIBUTING.md` — Developer Certificate of Origin sign-off
|
||||
requirement and a contributor checklist for new alpha PRs (purity,
|
||||
lookahead, `__alpha_meta__` shape, LaTeX-matches-code, per-zoo
|
||||
LICENSE.md, DCO).
|
||||
- `NOTICE` (repo root) — Apache-2.0 attribution for Qlib and a
|
||||
declaration that the bundled formulas from Kakushadze, GTJA, and the
|
||||
academic baselines are mathematical content (paper prose, tables, and
|
||||
figures are not reproduced here).
|
||||
- Per-zoo `LICENSE.md` for each of `qlib158/`, `alpha101/`, `gtja191/`,
|
||||
and `academic/`, plus an upstream `NOTICE` for `qlib158/`.
|
||||
|
||||
### Changed
|
||||
- `agent/src/tools/factor_analysis_tool.py` extracted its IC/IR and
|
||||
layered-backtest helpers to `agent/src/factors/factor_analysis_core.py`
|
||||
so the new `alpha_bench_tool` reuses the same maths. Public tool
|
||||
signature is unchanged; `_compute_ic_series` and `_compute_group_equity`
|
||||
remain importable as backward-compatible aliases.
|
||||
- `agent/cli.py` grew by 7 lines to register the `alpha` subcommand;
|
||||
all handler logic lives in `agent/src/factors/cli_handlers.py`.
|
||||
- Packaging: `pyproject.toml` now ships `zoo/**/*.yaml`, `zoo/**/*.md`,
|
||||
and `zoo/**/NOTICE` as package data; `MANIFEST.in` recursively
|
||||
includes `agent/src/factors`.
|
||||
|
||||
### Known limitations
|
||||
- The `btc-usdt` universe is single-asset; cross-sectional IC requires
|
||||
≥2 instruments, so the bundled `alpha101_btc` bench run returns
|
||||
alive/reversed/dead = 0/0/0 by construction. Use a multi-symbol crypto
|
||||
basket (e.g. BTC + ETH + SOL + the top-N perpetuals) for meaningful
|
||||
cross-sectional results; a curated `crypto-majors` universe is planned
|
||||
for 0.2.
|
||||
|
||||
### Internal
|
||||
- `wiki/alpha-library/manifest.json` and `wiki/alpha-library/content/`
|
||||
are generated artifacts and gitignored. Run
|
||||
`vibe-trading alpha export-manifest --out wiki/alpha-library/manifest.json
|
||||
--force` followed by `python wiki/scripts/build_alpha_library.py` to
|
||||
regenerate the static site.
|
||||
@@ -0,0 +1,128 @@
|
||||
# Contributor Covenant Code of Conduct
|
||||
|
||||
## Our Pledge
|
||||
|
||||
We as members, contributors, and leaders pledge to make participation in our
|
||||
community a harassment-free experience for everyone, regardless of age, body
|
||||
size, visible or invisible disability, ethnicity, sex characteristics, gender
|
||||
identity and expression, level of experience, education, socioeconomic status,
|
||||
nationality, personal appearance, race, religion, or sexual identity
|
||||
and orientation.
|
||||
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming,
|
||||
diverse, inclusive, and healthy community.
|
||||
|
||||
## Our Standards
|
||||
|
||||
Examples of behavior that contributes to a positive environment for our
|
||||
community include:
|
||||
|
||||
- Demonstrating empathy and kindness toward other people
|
||||
- Being respectful of differing opinions, viewpoints, and experiences
|
||||
- Giving and gracefully accepting constructive feedback
|
||||
- Accepting responsibility and apologizing to those affected by our mistakes,
|
||||
and learning from the experience
|
||||
- Focusing on what is best not just for us as individuals, but for the
|
||||
overall community
|
||||
|
||||
Examples of unacceptable behavior include:
|
||||
|
||||
- The use of sexualized language or imagery, and sexual attention or
|
||||
advances of any kind
|
||||
- Trolling, insulting or derogatory comments, and personal or political attacks
|
||||
- Public or private harassment
|
||||
- Publishing others' private information, such as a physical or email
|
||||
address, without their explicit permission
|
||||
- Other conduct which could reasonably be considered inappropriate in a
|
||||
professional setting
|
||||
|
||||
## Enforcement Responsibilities
|
||||
|
||||
Community leaders are responsible for clarifying and enforcing our standards of
|
||||
acceptable behavior and will take appropriate and fair corrective action in
|
||||
response to any behavior that they deem inappropriate, threatening, offensive,
|
||||
or harmful.
|
||||
|
||||
Community leaders have the right and responsibility to remove, edit, or reject
|
||||
comments, commits, code, wiki edits, issues, and other contributions that are
|
||||
not aligned to this Code of Conduct, and will communicate reasons for moderation
|
||||
decisions when appropriate.
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all community spaces, and also applies when
|
||||
an individual is officially representing the community in public spaces.
|
||||
Examples of representing our community include using an official e-mail address,
|
||||
posting via an official social media account, or acting as an appointed
|
||||
representative at an online or offline event.
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be
|
||||
reported to the community leaders responsible for enforcement via
|
||||
[GitHub Issues](https://github.com/HKUDS/Vibe-Trading/issues).
|
||||
All complaints will be reviewed and investigated promptly and fairly.
|
||||
|
||||
All community leaders are obligated to respect the privacy and security of the
|
||||
reporter of any incident.
|
||||
|
||||
## Enforcement Guidelines
|
||||
|
||||
Community leaders will follow these Community Impact Guidelines in determining
|
||||
the consequences for any action they deem in violation of this Code of Conduct:
|
||||
|
||||
### 1. Correction
|
||||
|
||||
**Community Impact**: Use of inappropriate language or other behavior deemed
|
||||
unprofessional or unwelcome in the community.
|
||||
|
||||
**Consequence**: A private, written warning from community leaders, providing
|
||||
clarity around the nature of the violation and an explanation of why the
|
||||
behavior was inappropriate. A public apology may be requested.
|
||||
|
||||
### 2. Warning
|
||||
|
||||
**Community Impact**: A violation through a single incident or series
|
||||
of actions.
|
||||
|
||||
**Consequence**: A warning with consequences for continued behavior. No
|
||||
interaction with the people involved, including unsolicited interaction with
|
||||
those enforcing the Code of Conduct, for a specified period of time. This
|
||||
includes avoiding interactions in community spaces as well as external channels
|
||||
like social media. Violating these terms may lead to a temporary or
|
||||
permanent ban.
|
||||
|
||||
### 3. Temporary Ban
|
||||
|
||||
**Community Impact**: A serious violation of community standards, including
|
||||
sustained inappropriate behavior.
|
||||
|
||||
**Consequence**: A temporary ban from any sort of interaction or public
|
||||
communication with the community for a specified period of time. No public or
|
||||
private interaction with the people involved, including unsolicited interaction
|
||||
with those enforcing the Code of Conduct, is allowed during this period.
|
||||
Violating these terms may lead to a permanent ban.
|
||||
|
||||
### 4. Permanent Ban
|
||||
|
||||
**Community Impact**: Demonstrating a pattern of violation of community
|
||||
standards, including sustained inappropriate behavior, harassment of an
|
||||
individual, or aggression toward or disparagement of classes of individuals.
|
||||
|
||||
**Consequence**: A permanent ban from any sort of public interaction within
|
||||
the community.
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage],
|
||||
version 2.1, available at
|
||||
https://www.contributor-covenant.org/version/2/1/code_of_conduct.html.
|
||||
|
||||
Community Impact Guidelines were inspired by [Mozilla's code of conduct
|
||||
enforcement ladder](https://github.com/mozilla/diversity).
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
|
||||
For answers to common questions about this code of conduct, see the FAQ at
|
||||
https://www.contributor-covenant.org/faq. Translations are available at
|
||||
https://www.contributor-covenant.org/translations.
|
||||
+123
-140
@@ -1,169 +1,152 @@
|
||||
# Contributing to Vibe-Trading
|
||||
|
||||
Thanks for your interest in contributing! This guide will help you get started.
|
||||
Vibe-Trading is a natural-language finance research AI agent (FastAPI + ReAct
|
||||
agent backend, Vite+React frontend, vectorized daily and options backtesting).
|
||||
This guide covers contribution governance: the Developer Certificate of Origin
|
||||
(DCO) sign-off requirement, the reviewer checklist for Alpha Zoo factor
|
||||
contributions, and the quickstart for adding a new alpha.
|
||||
|
||||
## Quick Links
|
||||
For general project setup (`pip install -e ".[dev]"`, dev servers,
|
||||
`pytest --ignore=agent/tests/e2e_backtest`), see the README. For bug reports
|
||||
and feature requests, use the GitHub issue templates.
|
||||
|
||||
- [Discord](https://discord.gg/2vDYc2w5) — ask questions, discuss ideas
|
||||
- [Issues](https://github.com/HKUDS/Vibe-Trading/issues) — bug reports & feature requests
|
||||
- [Good First Issues](https://github.com/HKUDS/Vibe-Trading/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22) — great starting points
|
||||
## Developer Certificate of Origin (DCO)
|
||||
|
||||
## Development Setup
|
||||
Every commit in a community pull request MUST carry a `Signed-off-by:`
|
||||
trailer. We do not require a CLA — the DCO is a lightweight per-commit
|
||||
attestation that you wrote the code or have the right to submit it under
|
||||
the project's MIT license. Maintainer-direct commits to `main` are not
|
||||
subject to the trailer requirement (the maintainer's authorship is
|
||||
already attested by the commit's author field), but community PRs are.
|
||||
|
||||
Sign your commits with `-s`:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/HKUDS/Vibe-Trading.git
|
||||
cd Vibe-Trading
|
||||
python -m venv .venv
|
||||
source .venv/bin/activate # Linux/macOS
|
||||
# .venv\Scripts\Activate.ps1 # Windows
|
||||
|
||||
pip install -e ".[dev]"
|
||||
cp agent/.env.example agent/.env
|
||||
# Edit agent/.env — set your LLM provider
|
||||
git commit -s -m "feat(factors): add gtja191 alpha 042"
|
||||
```
|
||||
|
||||
### Run tests
|
||||
This appends a trailer like:
|
||||
|
||||
```bash
|
||||
pytest --ignore=agent/tests/e2e_backtest --tb=short -q
|
||||
```
|
||||
Signed-off-by: Your Name <you@example.com>
|
||||
```
|
||||
|
||||
### Start dev servers
|
||||
PRs without a `Signed-off-by:` on every commit will be asked to rebase and
|
||||
resign. To fix an unsigned series, run
|
||||
`git rebase --signoff <base-branch>` and force-push the branch.
|
||||
|
||||
```bash
|
||||
# Terminal 1: API server
|
||||
vibe-trading serve --port 8899
|
||||
### DCO 1.1 (full text)
|
||||
|
||||
# Terminal 2: Frontend
|
||||
cd frontend && npm install && npm run dev
|
||||
```
|
||||
Developer Certificate of Origin
|
||||
Version 1.1
|
||||
|
||||
Copyright (C) 2004, 2006 The Linux Foundation and its contributors.
|
||||
1 Letterman Drive
|
||||
Suite D4700
|
||||
San Francisco, CA, 94129
|
||||
|
||||
Everyone is permitted to copy and distribute verbatim copies of this
|
||||
license document, but changing it is not allowed.
|
||||
|
||||
|
||||
Developer's Certificate of Origin 1.1
|
||||
|
||||
By making a contribution to this project, I certify that:
|
||||
|
||||
(a) The contribution was created in whole or in part by me and I
|
||||
have the right to submit it under the open source license
|
||||
indicated in the file; or
|
||||
|
||||
(b) The contribution is based upon previous work that, to the best
|
||||
of my knowledge, is covered under an appropriate open source
|
||||
license and I have the right under that license to submit that
|
||||
work with modifications, whether created in whole or in part
|
||||
by me, under the same open source license (unless I am
|
||||
permitted to submit under a different license), as indicated
|
||||
in the file; or
|
||||
|
||||
(c) The contribution was provided directly to me by some other
|
||||
person who certified (a), (b) or (c) and I have not modified
|
||||
it.
|
||||
|
||||
(d) I understand and agree that this project and the contribution
|
||||
are public and that a record of the contribution (including all
|
||||
personal information I submit with it, including my sign-off) is
|
||||
maintained indefinitely and may be redistributed consistent with
|
||||
this project or the open source license(s) involved.
|
||||
```
|
||||
|
||||
## Project Structure
|
||||
## Alpha PR Reviewer Checklist
|
||||
|
||||
| Directory | What lives here | Open to contribute? |
|
||||
|-----------|----------------|:-------------------:|
|
||||
| `agent/src/skills/` | 68 finance skill definitions (SKILL.md) | Yes |
|
||||
| `agent/src/tools/` | 21 agent tools | Yes |
|
||||
| `agent/backtest/` | Backtest engines, loaders, optimizers | Yes |
|
||||
| `agent/config/swarm/` | 29 swarm preset YAMLs | Yes |
|
||||
| `frontend/` | React 19 + Vite web UI | Yes |
|
||||
| `agent/src/agent/` | ReAct agent core (loop, context, skills) | Ask first |
|
||||
| `agent/src/session/` | Session management | Ask first |
|
||||
| `agent/src/providers/` | LLM provider abstraction | Ask first |
|
||||
This checklist applies to any PR adding or modifying files under
|
||||
`agent/src/factors/zoo/**/*.py`. Reviewers MUST verify every box before
|
||||
merging. Authors are strongly encouraged to self-check first.
|
||||
|
||||
> **Core modules** (`agent/`, `session/`, `providers/`) are protected — please open an issue to discuss before modifying.
|
||||
- [ ] **Purity gate**: file passes `pytest agent/tests/factors/test_alpha_purity.py`.
|
||||
The AST scan rejects any imports outside the allowlist
|
||||
(`pandas`, `numpy`, `scipy.*`, `src.factors.base`, `__future__`, `typing`,
|
||||
`math`, `dataclasses`) and any reference to forbidden names: `os`,
|
||||
`subprocess`, `socket`, `urllib`, `requests`, `httpx`, `pathlib`, `Path`,
|
||||
`eval`, `exec`, `compile`, `__import__`, bare `open`, or `getattr` with a
|
||||
second argument beginning with `"__"`.
|
||||
- [ ] **Lookahead gate**: file passes `pytest agent/tests/factors/test_lookahead.py`.
|
||||
No negative shifts, no forward leakage. `delta(df, d)` must have `d >= 1`.
|
||||
- [ ] **`__alpha_meta__` present** with all required pydantic-validated fields:
|
||||
`id`, `theme`, `formula_latex`, `columns_required`, `universe`, `frequency`,
|
||||
`decay_horizon`, `min_warmup_bars`. Optional: `nickname`, `extras_required`,
|
||||
`requires_sector`, `notes`.
|
||||
- [ ] **`compute(panel)` contract**: returns a DataFrame with the same shape
|
||||
as `panel["close"]`, NaN preserved at warmup / missing-data positions,
|
||||
no `+/-inf` values.
|
||||
- [ ] **LaTeX matches code**: the `formula_latex` in `__alpha_meta__` and the
|
||||
formula in the module docstring describe what `compute()` actually does.
|
||||
- [ ] **Per-zoo `LICENSE.md` updated** to cite the source paper / report and
|
||||
to state that formulas are mathematical facts, not subject to copyright,
|
||||
and that prose / tables / figures from papers and reports are not
|
||||
reproduced in this repo. Do NOT frame the bundled formulas using US
|
||||
affirmative-defense terminology — that is a litigation posture, not a
|
||||
license grant. State the mathematical-facts rationale instead.
|
||||
- [ ] **Apache-2 attribution**: if the alpha is adapted from an Apache-2.0
|
||||
upstream (e.g. Microsoft Qlib), the file MUST carry a header of the form
|
||||
`# Adapted from <repo>@<commit-sha>:<path> (Apache-2.0). Copyright (c) <holder>.`
|
||||
- [ ] **DCO**: every commit in the PR carries `Signed-off-by:`.
|
||||
|
||||
## How to Contribute
|
||||
## Adding a New Alpha (Quickstart)
|
||||
|
||||
### Reporting Bugs
|
||||
|
||||
Use the [Bug Report](https://github.com/HKUDS/Vibe-Trading/issues/new?template=bug_report.yml) template. Include:
|
||||
|
||||
- Steps to reproduce
|
||||
- Expected vs actual behavior
|
||||
- Your environment (OS, Python version, provider)
|
||||
- Error logs if available
|
||||
|
||||
### Suggesting Features
|
||||
|
||||
Use the [Feature Request](https://github.com/HKUDS/Vibe-Trading/issues/new?template=feature_request.yml) template.
|
||||
|
||||
### Submitting Code
|
||||
|
||||
1. **Fork & branch** — create a feature branch from `main`
|
||||
1. Pick the target zoo directory under `agent/src/factors/zoo/` (e.g.
|
||||
`gtja191/`, `alpha101/`, `qlib158/`, `academic/`).
|
||||
2. Create `<alpha_id_short>.py` in that directory. Define `__alpha_meta__`
|
||||
(must satisfy the pydantic `AlphaMeta` schema in
|
||||
`agent/src/factors/registry.py`) and a pure `compute(panel)` function
|
||||
that imports only from `src.factors.base` plus the allowlisted stdlib /
|
||||
numpy / pandas / scipy.
|
||||
3. Run the purity and lookahead gates locally:
|
||||
```bash
|
||||
git checkout -b feat/my-feature
|
||||
pytest agent/tests/factors/test_alpha_purity.py agent/tests/factors/test_lookahead.py -q
|
||||
```
|
||||
|
||||
2. **Make changes** — follow the code standards below
|
||||
|
||||
3. **Test** — add or update tests, ensure `pytest` passes
|
||||
4. (Optional but recommended) Run a quick bench:
|
||||
```bash
|
||||
pytest --ignore=agent/tests/e2e_backtest --tb=short -q
|
||||
vibe-trading alpha bench --zoo <zoo_id> --universe csi300 --period 2020-2025
|
||||
```
|
||||
5. Open a PR. Every commit must include `Signed-off-by:` (use
|
||||
`git commit -s`). Reviewers will walk the checklist above.
|
||||
|
||||
4. **Commit** — use [Conventional Commits](https://www.conventionalcommits.org/)
|
||||
```
|
||||
feat: add RSI divergence skill
|
||||
fix: handle empty DataFrame in backtest loader
|
||||
docs: update CLI reference table
|
||||
test: add crypto engine edge cases
|
||||
```
|
||||
## Code Style
|
||||
|
||||
5. **Pull Request** — open a PR against `main` with:
|
||||
- Summary of changes
|
||||
- Related issue number (e.g., `Closes #42`)
|
||||
- Test plan
|
||||
- Format with `black`; lint with `ruff` (config in `pyproject.toml`).
|
||||
- Type-annotate all public function and method signatures.
|
||||
- Google-style docstrings (`Args:` / `Returns:` / `Raises:`).
|
||||
- Keep files under 400 lines where practical, 800 hard cap.
|
||||
- No hardcoded paths, secrets, or URLs — config via `.env`, YAML, or
|
||||
module-level constants.
|
||||
- Delete unused code rather than commenting it out.
|
||||
|
||||
## Code Standards
|
||||
## Attribution
|
||||
|
||||
- **Python**: Google-style docstrings, type hints encouraged
|
||||
- **No hardcoding**: config via `.env`, YAML, or constants
|
||||
- **Delete unused code** — don't comment-preserve
|
||||
- **OKX pairs**: use `BTC-USDT` format (hyphen, uppercase)
|
||||
- **UI text**: English. LLM output follows user language
|
||||
- **File size**: aim for < 400 lines, max 800
|
||||
Do NOT add `Co-Authored-By:` trailers or AI-assistant attribution lines to
|
||||
commit messages or PR descriptions. The DCO sign-off is the only required
|
||||
trailer; keep commit metadata clean.
|
||||
|
||||
## Contribution Roadmap
|
||||
|
||||
### Easy: New Skill
|
||||
|
||||
Each skill is a single `SKILL.md` file in `agent/src/skills/<category>/<skill-name>/`. Categories: `data-source`, `strategy`, `analysis`, `asset-class`, `crypto`, `flow`, `tool`. Look at existing skills for the format.
|
||||
|
||||
### Easy: New Swarm Preset
|
||||
|
||||
A YAML file in `agent/config/swarm/` defining agents, roles, and DAG workflow. See existing presets.
|
||||
|
||||
### Medium: New Data Source Loader
|
||||
|
||||
1. Create `agent/backtest/loaders/<source>.py`
|
||||
2. Implement the `DataLoader` Protocol (see `agent/backtest/loaders/base.py`)
|
||||
3. Register in `agent/backtest/loaders/registry.py`
|
||||
4. Add tests in `agent/tests/`
|
||||
|
||||
### Medium: Portfolio Optimizer Constraints
|
||||
|
||||
Current optimizers (`agent/backtest/optimizers/`) support basic weight optimization. We need:
|
||||
- **Leverage constraints** — max gross exposure limits
|
||||
- **Sector/group caps** — weight limits per sector or asset group
|
||||
- **Turnover penalties** — transaction cost-aware rebalancing
|
||||
- Extend `BaseOptimizer` interface, keep backward compatibility
|
||||
|
||||
### Medium: Correlation Heatmap Dashboard
|
||||
|
||||
Add a cross-asset correlation matrix component to the frontend:
|
||||
- Time-window slider (30d / 60d / 90d / 1Y)
|
||||
- Hierarchical clustering for sector grouping
|
||||
- ECharts heatmap or custom canvas renderer
|
||||
- Wire to a new API endpoint that computes rolling correlations
|
||||
|
||||
### Hard: Intraday Backtest Engine
|
||||
|
||||
Current engines run on daily bars. We need sub-daily execution:
|
||||
- Support 1m / 5m / 15m / 30m / 1H / 4H intervals
|
||||
- Handle market session boundaries (pre-market, after-hours, overnight gaps)
|
||||
- Intraday margin / buying power tracking
|
||||
- Integrate with minute-level data loaders (OKX klines, yfinance intraday)
|
||||
- Start from `BaseEngine` — see `agent/backtest/engines/base.py` for the abstract interface
|
||||
|
||||
### Hard: Options Volatility Surface & Greeks Visualization
|
||||
|
||||
Build 3D implied-vol surface and Greeks charts in the frontend:
|
||||
- **Vol surface**: strike vs. expiry vs. implied vol (3D mesh or contour)
|
||||
- **Greeks dashboard**: delta, gamma, theta, vega curves across strikes
|
||||
- **Skew chart**: 25-delta risk reversal over time
|
||||
- Backend: extend `options_pricing_tool.py` to return surface data
|
||||
- Frontend: ECharts GL for 3D, or custom WebGL renderer
|
||||
|
||||
### Hard: Monte Carlo & Stress Testing
|
||||
|
||||
Add scenario simulation and tail-risk analysis:
|
||||
- **Monte Carlo**: generate N return paths from fitted distribution, compute VaR/CVaR confidence intervals
|
||||
- **Historical stress tests**: replay specific crisis periods (2008, 2020 COVID, 2022 crypto winter)
|
||||
- **Regime switching**: HMM-based regime detection (bull/bear/sideways), conditional risk metrics
|
||||
- Output: distribution plots, drawdown probability curves, worst-case tables
|
||||
- Can be a new tool in `agent/src/tools/` or an extension to the backtest engine
|
||||
|
||||
## License
|
||||
|
||||
By contributing, you agree that your contributions will be licensed under the [MIT License](LICENSE).
|
||||
By contributing, you agree that your contributions are licensed under the
|
||||
project's MIT license (see `LICENSE`).
|
||||
+13
@@ -14,6 +14,12 @@ RUN npm run build
|
||||
# ============================================================================
|
||||
FROM python:3.11-slim AS runtime
|
||||
|
||||
LABEL org.opencontainers.image.title="Vibe-Trading" \
|
||||
org.opencontainers.image.description="Natural-language finance research AI agent with backtesting" \
|
||||
org.opencontainers.image.version="0.1.7" \
|
||||
org.opencontainers.image.source="https://github.com/HKUDS/Vibe-Trading" \
|
||||
org.opencontainers.image.licenses="MIT"
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
# System deps
|
||||
@@ -35,6 +41,13 @@ COPY --from=frontend-build /app/frontend/dist frontend/dist
|
||||
# Install CLI entrypoint
|
||||
RUN pip install --no-cache-dir -e .
|
||||
|
||||
# Runtime should not run as root. Keep writable app data directories owned by
|
||||
# the service user so named Docker volumes inherit usable permissions.
|
||||
RUN useradd --create-home --shell /usr/sbin/nologin vibe \
|
||||
&& mkdir -p agent/runs agent/sessions agent/uploads agent/.swarm/runs \
|
||||
&& chown -R vibe:vibe /app
|
||||
USER vibe
|
||||
|
||||
# Default port
|
||||
EXPOSE 8899
|
||||
|
||||
|
||||
+30
@@ -0,0 +1,30 @@
|
||||
include LICENSE
|
||||
include NOTICE
|
||||
include README.md
|
||||
include README_zh.md
|
||||
include README_ja.md
|
||||
include README_ko.md
|
||||
include README_ar.md
|
||||
include pyproject.toml
|
||||
include Dockerfile
|
||||
include docker-compose.yml
|
||||
|
||||
# Developer entry-point template
|
||||
include agent/.env.example
|
||||
|
||||
# Alpha Zoo factor metadata and per-zoo LICENSE / NOTICE files
|
||||
recursive-include agent/src/factors *.yaml *.md
|
||||
|
||||
# Tests shipped so dev installs can run `pytest` against the package.
|
||||
# Files prefixed with `_` are local debug scripts kept untracked — keep
|
||||
# them out of the sdist even if present in the working tree.
|
||||
recursive-include agent/tests *.py
|
||||
recursive-exclude agent/tests _*.py
|
||||
|
||||
# Strip generated / VCS / editor noise
|
||||
global-exclude __pycache__
|
||||
global-exclude *.py[cod]
|
||||
global-exclude *.so
|
||||
global-exclude .DS_Store
|
||||
global-exclude .pytest_cache
|
||||
global-exclude *.egg-info
|
||||
@@ -0,0 +1,22 @@
|
||||
Vibe-Trading
|
||||
Copyright 2026 HKUDS contributors.
|
||||
|
||||
This product includes software developed at HKUDS (https://github.com/HKUDS).
|
||||
|
||||
This product bundles Microsoft Qlib feature definitions under the Apache 2.0
|
||||
license. See agent/src/factors/zoo/qlib158/NOTICE and LICENSE.md for the
|
||||
upstream NOTICE and attribution.
|
||||
|
||||
Mathematical formulas from the following sources are reimplemented in this
|
||||
repository as factual mathematical content (formulas are not copyrightable):
|
||||
|
||||
- Kakushadze, Z. (2015) "101 Formulaic Alphas" (arXiv:1601.00991)
|
||||
See agent/src/factors/zoo/alpha101/LICENSE.md
|
||||
- Guotai Junan Securities (2014) "191 Short-period Trading Alpha Factors"
|
||||
See agent/src/factors/zoo/gtja191/LICENSE.md
|
||||
- Fama-French five-factor model, Carhart momentum, Hou-Xue-Zhang q-factor
|
||||
See agent/src/factors/zoo/academic/LICENSE.md
|
||||
|
||||
Prose, tables, and figures from the source papers and reports are NOT
|
||||
reproduced in this repository. Only the mathematical formulas — which are
|
||||
factual content and not subject to copyright — are reimplemented here.
|
||||
@@ -1,5 +1,5 @@
|
||||
<p align="center">
|
||||
<b>English</b> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a>
|
||||
<b>English</b> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a> | <a href="README_ar.md">العربية</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -19,127 +19,226 @@
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="License"></a>
|
||||
<br>
|
||||
<img src="https://img.shields.io/badge/Skills-68-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Swarm_Presets-29-7C3AED" alt="Swarm">
|
||||
<img src="https://img.shields.io/badge/Tools-21-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-5-2563EB" alt="Data Sources">
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
<a href="https://discord.gg/2vDYc2w5"><img src="https://img.shields.io/badge/Discord-Join-7289DA?style=flat-square&logo=discord&logoColor=white" alt="Discord"></a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://vibetrading.wiki/">Website</a> ·
|
||||
<a href="https://vibetrading.wiki/docs/">Docs</a> ·
|
||||
<a href="#-news">News</a> ·
|
||||
<a href="#-key-features">Features</a> ·
|
||||
<a href="#-shadow-account">Shadow Account</a> ·
|
||||
<a href="#-demo">Demo</a> ·
|
||||
<a href="#-what-is-vibe-trading">What Is It</a> ·
|
||||
<a href="#-get-started">Get Started</a> ·
|
||||
<a href="#-cli-reference">CLI</a> ·
|
||||
<a href="#-api-server">API</a> ·
|
||||
<a href="#-mcp-plugin">MCP</a> ·
|
||||
<a href="#-project-structure">Structure</a> ·
|
||||
<a href="#-quick-start">Quick Start</a> ·
|
||||
<a href="#-examples">Examples</a> ·
|
||||
<a href="#-api-server">API / MCP</a> ·
|
||||
<a href="#-roadmap">Roadmap</a> ·
|
||||
<a href="#-contributing">Contributing</a> ·
|
||||
<a href="#contributors">Contributors</a>
|
||||
<a href="#-contributing">Contributing</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="#-get-started"><img src="assets/pip-install.svg" height="45" alt="pip install vibe-trading-ai"></a>
|
||||
<a href="#-quick-start"><img src="assets/pip-install.svg" height="45" alt="pip install vibe-trading-ai"></a>
|
||||
</p>
|
||||
|
||||
---
|
||||
|
||||
## 📰 News
|
||||
|
||||
- **2026-04-10** 📦 **v0.1.4**: Fix Docker build ([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)), add `web_search` MCP tool (17 total), `akshare`/`ccxt` in deps & MCP. 11 LLM providers (DeepSeek, Groq, Gemini, Ollama, etc.), all tuning params via `.env`. Hardened `ml-strategy` skill. Published to PyPI and ClawHub.
|
||||
- **2026-04-09** 📊 **Backtest Wave 2 — multi-asset engines**: added ChinaFutures (CFFEX/SHFE/DCE/ZCE, 50+ contracts), GlobalFutures (CME/ICE/Eurex, 30+ contracts), Forex (24 pairs, spread + swap), Options v2 (American exercise, IV smile). Statistical validation: Monte Carlo permutation test, Bootstrap Sharpe CI, Walk-Forward analysis.
|
||||
- **2026-04-08** 🔧 **Multi-market backtest** with per-market rules; **Pine Script v6 export** for TradingView. **Data source expansion**: 5 sources with auto-fallback, `web_search` tool, skill categorization (7 categories).
|
||||
- **2026-04-01** 🚀 **v0.1.0** — Initial release: ReAct agent, 64 skills, 29 swarm presets, cross-market backtest, CLI + Web UI + MCP server.
|
||||
- **2026-05-17** 🧬 **Alpha Zoo v1 (0.1.8)**: 452 pre-built quant alphas across 4 zoos — `qlib158` (Microsoft Qlib, Apache-2 attribution), `alpha101` (Kakushadze 101 Formulaic Alphas, paper rewrite from arXiv:1601.00991), `gtja191` (Guotai Junan 2014 short-horizon factor report), and `academic` (Fama-French 5 + Carhart price-based proxies). One-line CLI to bench any zoo on your universe: `vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025`. Ships with AST purity gate, lookahead-guard test, `pytest-socket` network kill-switch, per-zoo LICENSE.md, and a Developer Certificate of Origin (DCO) workflow for community PRs. Auto-rendered Alpha Library at [vibetrading.wiki/alpha-library/](https://vibetrading.wiki/alpha-library/) + research-lab post [Which of the 191 GTJA alphas still work in 2026?](https://vibetrading.wiki/research-lab/posts/alpha-191-in-2026.html).
|
||||
- **2026-05-16** 🧪 **Research spine update**: Added a backend Hypothesis Registry with `create_hypothesis`, `update_hypothesis`, `link_backtest`, and `search_hypotheses`; external-content readers now attach warning-only `security_warnings`; and Shadow Account scanning now uses deterministic OHLCV feature evaluation instead of the old calendar-phase stub.
|
||||
- **2026-05-15** 🪪 The run detail page now surfaces the Trust Layer run card alongside metrics and artifacts, completing the UI side of the `run_card.json` work landed on 2026-05-12. `PersistentMemory.add()` was also hardened on length, empty/whitespace-only names, and C0/C1 control bytes from the #108/#109/#110 triage ([#112](https://github.com/HKUDS/Vibe-Trading/pull/112), thanks @Teerapat-Vatpitak).
|
||||
|
||||
---
|
||||
<details>
|
||||
<summary>Earlier news</summary>
|
||||
|
||||
## 💡 What Is Vibe-Trading?
|
||||
- **2026-05-14** 🌐 the public wiki is now live at [vibetrading.wiki](https://vibetrading.wiki/) with docs, tutorials, Research Lab, and Alpha Library sections deployed through Cloudflare Pages. Persistent memory is also inspectable from the CLI via `vibe-trading memory list/show/search/forget` ([#102](https://github.com/HKUDS/Vibe-Trading/pull/102), thanks @Teerapat-Vatpitak), and memory tokenization/slugs now support Thai, Arabic, Hebrew, and Cyrillic text ([#104](https://github.com/HKUDS/Vibe-Trading/pull/104)).
|
||||
- **2026-05-13** 🧭 Swarm runs now ground workers with fetched market data and cleaner persisted reports ([#93](https://github.com/HKUDS/Vibe-Trading/pull/93), [#84](https://github.com/HKUDS/Vibe-Trading/pull/84)).
|
||||
- **2026-05-12** 🧾 Backtests now emit `run_card.json` and `run_card.md` alongside artifacts for reproducible research runs.
|
||||
- **2026-05-11** 🧭 **Memory slugs, swarm accounting, and CLI preflight**: Persistent memory now preserves CJK characters when generating file slugs, preventing silent filename collisions for Chinese/Japanese/Korean notes ([#95](https://github.com/HKUDS/Vibe-Trading/pull/95), thanks @voidborne-d). Swarm run totals now prefer provider-reported token usage with the existing estimate fallback ([#94](https://github.com/HKUDS/Vibe-Trading/pull/94), thanks @Teerapat-Vatpitak), and the CLI run UI gained a startup preflight check for common environment issues ([#96](https://github.com/HKUDS/Vibe-Trading/pull/96), thanks @ykykj).
|
||||
- **2026-05-10** 🧱 **Regression guardrails + run metadata**: Memory recall now treats underscores as token boundaries, so snake_case saved memories such as `mcp_wiring_test` match natural-language queries like "mcp wiring" ([#87](https://github.com/HKUDS/Vibe-Trading/pull/87), thanks @hp083625). The MCP server has a subprocess smoke test covering initialize → `tools/list` → `tools/call` to guard the first-call deadlock path ([#86](https://github.com/HKUDS/Vibe-Trading/pull/86)), while low-risk hardening landed for Windows path-sensitive tests, API best-effort exception handling, backtest `run_dir` allowed-root validation, and SwarmRun provider/model metadata ([#88](https://github.com/HKUDS/Vibe-Trading/pull/88), [#90](https://github.com/HKUDS/Vibe-Trading/pull/90), [#91](https://github.com/HKUDS/Vibe-Trading/pull/91), [#92](https://github.com/HKUDS/Vibe-Trading/pull/92), thanks @Teerapat-Vatpitak).
|
||||
- **2026-05-09** 🛡️ **API path hardening + MCP server stability**: API run/session routes now validate path IDs before lookup, rejecting malformed newline-containing parameters and pinning the behavior in the auth/security regression suite ([#80](https://github.com/HKUDS/Vibe-Trading/pull/80), thanks @SJoon99). The MCP server now pre-warms the tool registry on the main thread before serving `tools/call`, avoiding a first-call deadlock in lazy tool discovery ([#85](https://github.com/HKUDS/Vibe-Trading/pull/85), thanks @Teerapat-Vatpitak). The Vite dev proxy also honors `VITE_API_URL` for non-default backend targets ([#82](https://github.com/HKUDS/Vibe-Trading/pull/82), thanks @voidborne-d).
|
||||
- **2026-05-08** 🧾 **Tushare statement fields in filters**: A-share daily backtests can now request PIT-safe financial statement fields through `fundamental_fields`, so signal engines can screen on `income_total_revenue`, `income_n_income`, `balancesheet_total_hldr_eqy_exc_min_int`, `fina_indicator_roe`, and similar table-prefixed columns after their announcement/disclosure dates ([#76](https://github.com/HKUDS/Vibe-Trading/pull/76), thanks @mrbob-git). Follow-up hardening makes explicit statement-field requests fail fast if Tushare enrichment cannot run, instead of silently falling back to raw price bars ([#77](https://github.com/HKUDS/Vibe-Trading/pull/77)).
|
||||
- **2026-05-07** 📈 **Tushare fundamentals + community triage**: Added a point-in-time `TushareFundamentalProvider` contract for fundamental research workflows, with regression coverage for the project `TUSHARE_TOKEN` environment path ([#74](https://github.com/HKUDS/Vibe-Trading/pull/74)). Community triage also clarified that Vibe-Trading keeps rapid iteration focused on one UI language for now, avoids adding redundant search dependencies while DuckDuckGo-backed `web_search` is already bundled, and treats unofficial hosted deployments as untrusted places for API keys or data-source tokens.
|
||||
- **2026-05-06** 🚀 **v0.1.7 released** ([Release notes](https://github.com/HKUDS/Vibe-Trading/releases/tag/v0.1.7), `pip install -U vibe-trading-ai`): Security-boundary hardening is now published on PyPI and ClawHub, covering safer API/read/upload/file/URL/generated-code/shell-tool/Docker defaults while keeping localhost CLI/Web UI workflows low-friction. This cycle also includes Web UI Settings, correlation heatmap, OpenAI Codex OAuth, A-share pre-ST filtering, interactive CLI UX, swarm preset inspection, dividend analysis, dev workflow polish, and audited frontend build-dependency floors. Thanks to the 0.1.7 contributors and to lemi9090 (S2W) for coordinated security validation.
|
||||
- **2026-05-05** 🛡️ **Security boundary follow-up**: Completes the remaining security-boundary hardening around explicit CORS origins, Settings credential indicators, web URL reading, and Shadow Account code generation, with regression tests added for each path. Normal localhost CLI/Web UI workflows stay the same; remote deployments should continue using `API_AUTH_KEY` and explicit trusted origins.
|
||||
- **2026-05-04** 🖥️ **Interactive CLI UX + CI cleanup**: Interactive mode now has a live bottom status bar showing provider/model, session duration, last-run latency, and cumulative tool-call stats, plus prompt history navigation and cursor editing with arrow keys via `prompt_toolkit` ([#69](https://github.com/HKUDS/Vibe-Trading/pull/69)). The CLI still falls back to Rich prompts when `prompt_toolkit` or a TTY is unavailable. CI path expectations were also aligned with the hardened file-import sandbox and cross-platform `/tmp` resolution, returning main to green ([`bb67dc7`](https://github.com/HKUDS/Vibe-Trading/commit/bb67dc7cfcc11553c57d8962bee56381dca43758)).
|
||||
- **2026-05-03** 🛡️ **Security hardening patch**: Tightens default API authentication for non-local deployments, protects sensitive run/session/swarm reads, restricts upload and local file-reading boundaries, gates shell-capable tools by entry point, validates generated strategy loading before import, and runs the Docker image as a non-root user with a localhost-only published port by default. Local CLI and localhost Web UI workflows remain low-friction; remote API/Web deployments should set `API_AUTH_KEY`.
|
||||
- **2026-05-02** 🧭 **Dividend analysis + sharper roadmap**: Added the `dividend-analysis` skill for income stocks, payout sustainability, dividend growth, shareholder yield, ex-dividend mechanics, and yield-trap checks, pinned by bundled-skill regression tests. The public roadmap now focuses on upcoming work: Research Autopilot, Data Bridge, Options Lab, Portfolio Studio, Alpha Zoo, Research Delivery, Trust Layer, and Community sharing.
|
||||
- **2026-05-01** 🔥 **Correlation heatmap + OpenAI Codex OAuth + A-share pre-ST filter**: New correlation dashboard/API computes rolling return correlations and renders an ECharts heatmap for portfolio and symbol analysis ([#64](https://github.com/HKUDS/Vibe-Trading/pull/64)). OpenAI Codex provider support now uses ChatGPT OAuth via `vibe-trading provider login openai-codex`, with Settings metadata and adapter regression tests ([#65](https://github.com/HKUDS/Vibe-Trading/pull/65)). Added and hardened the `ashare-pre-st-filter` skill for A-share ST/*ST risk screening, including Sina penalty relevance filtering so securities-account mentions do not inflate E2 counts ([#63](https://github.com/HKUDS/Vibe-Trading/pull/63)).
|
||||
- **2026-04-30** ⚙️ **Web UI Settings + validation CLI hardening**: New Settings page for LLM provider/model, base URL, reasoning effort, and data source credentials, backed by local/auth-protected settings APIs and data-driven provider metadata ([#57](https://github.com/HKUDS/Vibe-Trading/pull/57)). Also hardens `python -m backtest.validation <run_dir>` so missing, blank, malformed, non-existent, and non-directory inputs fail with clear operator-facing messages before validation starts ([#60](https://github.com/HKUDS/Vibe-Trading/pull/60)).
|
||||
- **2026-04-28** 🚀 **v0.1.6 released** (`pip install -U vibe-trading-ai`): Fixes `vibe-trading --swarm-presets` returning empty after `pip install` / `uv tool install` ([#55](https://github.com/HKUDS/Vibe-Trading/issues/55)) — preset YAMLs now bundled inside the `src.swarm` package and pinned by a 6-test regression suite. Plus AKShare loader correctly routes ETFs (`510300.SH`) and forex (`USDCNH`) to the right endpoints with hardened registry fallback. Rolls up everything since v0.1.5: benchmark comparison panel, `/upload` streaming + size limits, Futu loader (HK + A-share), vnpy export skill, security hardening, frontend lazy loading (688KB → 262KB).
|
||||
- **2026-04-27** 📊 **Benchmark panel + upload safety**: Backtest output now ships a benchmark comparison panel (ticker / benchmark return / excess return / information ratio) with yfinance-backed resolution for SPY, CSI 300, etc. ([#48](https://github.com/HKUDS/Vibe-Trading/issues/48)). Plus `/upload` streams the request body in 1 MB chunks and aborts past `MAX_UPLOAD_SIZE`, bounding memory under oversized/malformed clients ([#53](https://github.com/HKUDS/Vibe-Trading/pull/53)) — pinned by a 4-case regression suite.
|
||||
- **2026-04-22** 🛡️ **Hardening + new integrations**: Path containment enforced in `safe_path` + journal/shadow tool sandbox, `MANIFEST.in` ships `.env.example` / tests / Docker files in sdist, route-level lazy loading shrinks frontend initial bundle 688KB → 262KB. Plus Futu data loader for HK & A-share equities ([#47](https://github.com/HKUDS/Vibe-Trading/pull/47)) and vnpy CtaTemplate export skill ([#46](https://github.com/HKUDS/Vibe-Trading/pull/46)).
|
||||
- **2026-04-21** 🛡️ **Workspace + docs**: Relative `run_dir` normalized to active run dir ([#43](https://github.com/HKUDS/Vibe-Trading/pull/43)). README usage examples ([#45](https://github.com/HKUDS/Vibe-Trading/pull/45)).
|
||||
- **2026-04-20** 🔌 **Reasoning + Swarm**: `reasoning_content` preserved across all `ChatOpenAI` paths — Kimi / DeepSeek / Qwen thinking work end-to-end ([#39](https://github.com/HKUDS/Vibe-Trading/issues/39)). Swarm streaming + clean Ctrl+C ([#42](https://github.com/HKUDS/Vibe-Trading/issues/42)).
|
||||
- **2026-04-19** 📦 **v0.1.5**: Published to PyPI & ClawHub. `python-multipart` CVE floor bump, 5 new MCP tools wired (`analyze_trade_journal` + 4 shadow-account tools), `pattern_recognition` → `pattern` registry fix, Docker dep parity, SKILL manifest synced (22 MCP tools / 71 skills).
|
||||
- **2026-04-18** 👥 **Shadow Account**: Extract your strategy rules from a broker journal → backtest the shadow across markets → 8-section HTML/PDF report showing exactly how much you leave on the table (rule violations, early exits, missed signals, counterfactual trades). 4 new tools, 1 skill, 32 tools total. Trade Journal + Shadow Account samples now live in the web UI welcome screen.
|
||||
- **2026-04-17** 📊 **Trade Journal Analyzer + Universal File Reader**: Upload broker exports (同花顺/东财/富途/generic CSV) → auto trading profile (holding days, win rate, PnL ratio, drawdown) + 4 bias diagnostics (disposition effect, overtrading, chasing momentum, anchoring). `read_document` now dispatches PDF, Word, Excel, PowerPoint, images (OCR), and 40+ text formats behind one unified call.
|
||||
- **2026-04-16** 🧠 **Agent Harness**: Persistent cross-session memory, FTS5 session search, self-evolving skills (full CRUD), 5-layer context compression, read/write tool batching. 27 tools, 107 new tests.
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**: Z.ai provider ([#35](https://github.com/HKUDS/Vibe-Trading/pull/35)), MiniMax temperature fix + model update ([#33](https://github.com/HKUDS/Vibe-Trading/pull/33)). 13 providers.
|
||||
- **2026-04-14** 🔧 **MCP Stability**: Fixed backtest tool `Connection closed` error on stdio transport ([#32](https://github.com/HKUDS/Vibe-Trading/pull/32)).
|
||||
- **2026-04-13** 🌐 **Cross-Market Composite Backtest**: New `CompositeEngine` backtests mixed-market portfolios (e.g. A-shares + crypto) with shared capital pool and per-market rules. Also fixed swarm template variable fallback and frontend timeout.
|
||||
- **2026-04-12** 🌍 **Multi-Platform Export**: `/pine` exports strategies to TradingView (Pine Script v6), TDX (通达信/同花顺/东方财富), and MetaTrader 5 (MQL5) in one command.
|
||||
- **2026-04-11** 🛡️ **Reliability & DX**: `vibe-trading init` .env bootstrap ([#19](https://github.com/HKUDS/Vibe-Trading/pull/19)), preflight checks, runtime data-source fallback, hardened backtest engine. Multi-language README ([#21](https://github.com/HKUDS/Vibe-Trading/pull/21)).
|
||||
- **2026-04-10** 📦 **v0.1.4**: Docker fix ([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)), `web_search` MCP tool, 12 LLM providers, `akshare`/`ccxt` deps. Published to PyPI and ClawHub.
|
||||
- **2026-04-09** 📊 **Backtest Wave 2**: ChinaFutures, GlobalFutures, Forex, Options v2 engines. Monte Carlo, Bootstrap CI, Walk-Forward validation.
|
||||
- **2026-04-08** 🔧 **Multi-market backtest** with per-market rules, Pine Script v6 export, 5 data sources with auto-fallback.
|
||||
|
||||
Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural language requests into executable trading strategies, research insights, and portfolio analysis across global markets.
|
||||
|
||||
### Key Capabilities:
|
||||
• **Strategy Generation** — Automatically writes trading code from your ideas<br>
|
||||
• **Smart Data Access** — 5 data sources with automatic fallback; zero-config for all markets<br>
|
||||
• **Performance Testing** — Tests your strategies against historical market data<br>
|
||||
• **TradingView Export** — One-click convert strategies to Pine Script v6 for TradingView<br>
|
||||
• **Expert Teams** — Deploys specialized AI agents for complex research tasks<br>
|
||||
• **Live Updates** — Watch the entire analysis process in real-time
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## ✨ Key Features
|
||||
|
||||
<table width="100%">
|
||||
<div align="center">
|
||||
<table align="center" width="94%" style="width:94%; margin-left:auto; margin-right:auto;">
|
||||
<tr>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-research.png" height="150" alt="Research"/><br>
|
||||
<h3>🔍 DeepResearch for Trading</h3>
|
||||
<img src="https://img.shields.io/badge/68_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<div align="left" style="font-size: 4px;">
|
||||
• Multi-domain analysis coverage across markets<br>
|
||||
• Auto strategy and signal generation<br>
|
||||
• Macro economic research and insights<br>
|
||||
• Natural-language task routing via chat
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-self-improving-trading-agent.png" height="130" alt="Self-improving trading agent"/><br>
|
||||
<h3>🔍 Self-Improving Trading Agent</h3>
|
||||
<div align="left">
|
||||
• Natural-language market research<br>
|
||||
• Strategy drafts and file/web analysis<br>
|
||||
• Memory-backed workflows
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-swarm.png" height="150" alt="Swarm"/><br>
|
||||
<h3>🐝 Swarm Intelligence</h3>
|
||||
<img src="https://img.shields.io/badge/29_Trading_Teams-4ECDC4?style=for-the-badge&logo=hive&logoColor=white" alt="Swarm" /><br><br>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-multi-agent-trading-teams.png" height="130" alt="Multi-agent trading teams"/><br>
|
||||
<h3>🐝 Multi-Agent Trading Teams</h3>
|
||||
<div align="left">
|
||||
• 29 out-of-the-box trading team presets<br>
|
||||
• DAG-based multi-agent orchestration<br>
|
||||
• Real-time decision streaming dashboard<br>
|
||||
• Custom team building through YAML
|
||||
• Investment, quant, crypto, and risk teams<br>
|
||||
• Streaming progress and persisted reports<br>
|
||||
• Workers grounded with fetched market data
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-backtest.png" height="150" alt="Backtest"/><br>
|
||||
<h3>📊 Cross-Market Backtest</h3>
|
||||
<img src="https://img.shields.io/badge/5_Data_Sources-FFD93D?style=for-the-badge&logo=bitcoin&logoColor=black" alt="Backtest" /><br><br>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-cross-market-data-backtesting.png" height="130" alt="Cross-market data and backtesting"/><br>
|
||||
<h3>📊 Cross-Market Data & Backtesting</h3>
|
||||
<div align="left">
|
||||
• A-shares, HK/US equities, crypto, futures & forex<br>
|
||||
• 7 market engines: A-share, US/HK equity, crypto, China futures, global futures, forex<br>
|
||||
• Statistical validation: Monte Carlo, Bootstrap CI, Walk-Forward<br>
|
||||
• 15+ performance metrics & 4 optimizers
|
||||
• A/HK/US equities, crypto, futures, and forex<br>
|
||||
• Data fallback and composite backtests<br>
|
||||
• PIT data, validation, and run cards
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-quant.png" height="150" alt="Quant"/><br>
|
||||
<h3>🧮 Quant Analysis Toolkit</h3>
|
||||
<img src="https://img.shields.io/badge/Quant_Tools-C77DFF?style=for-the-badge&logo=wolfram&logoColor=white" alt="Quant" /><br><br>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-shadow-account.png" height="130" alt="Shadow Account"/><br>
|
||||
<h3>👥 Shadow Account</h3>
|
||||
<div align="left">
|
||||
• Factor IC/IR analysis & quantile backtesting<br>
|
||||
• Black-Scholes pricing & full Greeks calculation<br>
|
||||
• Technical pattern recognition & detection<br>
|
||||
• Portfolio optimization via MVO/Risk Parity/BL
|
||||
• Broker-journal behavior diagnostics<br>
|
||||
• Rule-based Shadow Account comparisons<br>
|
||||
• Exportable audit reports and strategy code
|
||||
</div>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
## 68 Skills across 7 Categories
|
||||
## 💡 What Is Vibe-Trading?
|
||||
|
||||
- 📊 68 specialized finance skills organized into 7 categories
|
||||
Vibe-Trading is an open-source research workspace for turning finance questions into runnable analysis. It connects natural-language prompts to market-data loaders, strategy generation, backtest engines, reports, exports, and persistent research memory.
|
||||
|
||||
It is designed for research, simulation, and backtesting. It does not execute live trades.
|
||||
|
||||
---
|
||||
|
||||
## ✨ What You Can Do
|
||||
|
||||
| Task | Output |
|
||||
|------|--------|
|
||||
| **Ask a trading question** | Market research with tools, data, documents, and reusable session context. |
|
||||
| **Backtest a strategy idea** | Strategy code, metrics, benchmark context, validation artifacts, and run cards. |
|
||||
| **Review your own trades** | Broker-journal parsing, behavior diagnostics, rule extraction, and Shadow Account comparisons. |
|
||||
| **Improve repeated research** | Persistent memory and editable skills turn useful routines into reusable workflows. |
|
||||
| **Run analyst teams** | Multi-agent research reviews for investment, quant, crypto, macro, and risk workflows. |
|
||||
| **Ship usable artifacts** | Reports, TradingView Pine Script, TDX, MetaTrader 5, MCP tools, and later research sessions. |
|
||||
| **Bench a pre-built alpha zoo** | One-line IC + alive/reversed/dead categorisation across 452 alphas (Qlib 158 + Kakushadze 101 + GTJA 191 + FF5 + Carhart) on your universe. |
|
||||
|
||||
---
|
||||
|
||||
## ⚡ Quick Example
|
||||
|
||||
```bash
|
||||
pip install vibe-trading-ai
|
||||
|
||||
# Natural-language research
|
||||
vibe-trading run -p "Backtest a BTC-USDT 20/50 moving-average strategy for 2024, summarize return and drawdown, then export the report"
|
||||
|
||||
# Bench a pre-built alpha zoo (one line)
|
||||
vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025 --top 20
|
||||
```
|
||||
|
||||
```bash
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Analyze my trading behavior, extract my shadow strategy, and compare it with my actual trades"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 👥 Shadow Account
|
||||
|
||||
Shadow Account starts from your own trading records instead of a generic strategy template.
|
||||
|
||||
Upload a broker export, let the agent summarize your behavior, then compare the actual trading path with a rule-based shadow strategy.
|
||||
|
||||
| Step | Agent output |
|
||||
|------|--------------|
|
||||
| **1. Read your journal** | Parses broker exports from 同花顺, 东方财富, 富途, and generic CSV formats. |
|
||||
| **2. Profile your behavior** | Holding days, win rate, PnL ratio, drawdown, disposition effect, overtrading, momentum chasing, and anchoring checks. |
|
||||
| **3. Extract your rules** | Turns recurring entries/exits into an explicit strategy profile instead of a hand-wavy summary. |
|
||||
| **4. Run the shadow** | Backtests the extracted rules and highlights rule breaks, early exits, missed signals, and alternative trade paths. |
|
||||
| **5. Deliver the report** | Produces an HTML/PDF report that can be inspected, archived, or refined in a later session. |
|
||||
|
||||
```bash
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Analyze my trading behavior, extract my shadow strategy, and compare it with my actual trades"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 🧪 Research Workflow
|
||||
|
||||
Most runs follow the same evidence path: route the request, load the right market context, execute tools, validate outputs, and keep the artifacts inspectable.
|
||||
|
||||
| Layer | What happens |
|
||||
|-------|--------------|
|
||||
| **Plan** | Selects the relevant finance skills, tools, data sources, and swarm preset when useful. |
|
||||
| **Ground** | Pulls A-shares, HK/US equities, crypto, futures, forex, documents, or web context through the available loaders. |
|
||||
| **Execute** | Generates testable strategy code, runs tools, and uses the matching backtest engine or analysis workflow. |
|
||||
| **Validate** | Adds metrics, benchmark comparison, Monte Carlo, Bootstrap, Walk-Forward, run cards, and warnings where applicable. |
|
||||
| **Deliver** | Returns reports, artifacts, tool traces, and exports for TradingView, TDX, MetaTrader 5, MCP clients, or later sessions. |
|
||||
|
||||
---
|
||||
|
||||
## 🔩 Detailed Capabilities
|
||||
|
||||
Detailed inventories are folded below to keep the main README scannable. Open them when you want to inspect the available building blocks.
|
||||
|
||||
<details>
|
||||
<summary><b>Finance Skill Library</b> <sub>75 skills across 8 categories</sub></summary>
|
||||
|
||||
- 📊 75 specialized finance skills organized into 8 categories
|
||||
- 🌐 Complete coverage from traditional markets to crypto & DeFi
|
||||
- 🔬 Comprehensive capabilities spanning data sourcing to quantitative research
|
||||
|
||||
| Category | Skills | Examples |
|
||||
|----------|--------|----------|
|
||||
| Data Source | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| Strategy | 16 | `strategy-generate`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 15 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis` |
|
||||
| Strategy | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 17 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis`, `dividend-analysis` |
|
||||
| Asset Class | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| Crypto | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
| Flow | 7 | `hk-connect-flow`, `us-etf-flow`, `edgar-sec-filings`, `financial-statement`, `adr-hshare` |
|
||||
| Tool | 8 | `backtest-diagnose`, `report-generate`, `pine-script`, `doc-reader`, `web-reader` |
|
||||
| Tool | 11 | `backtest-diagnose`, `report-generate`, `pine-script`, `doc-reader`, `web-reader`, `vnpy-export`, `alpha-zoo` |
|
||||
| Risk Analysis | 1 | `ashare-pre-st-filter` |
|
||||
|
||||
## 29 Agent Swarm Team Presets
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Preset Trading Teams</b> <sub>29 swarm presets</sub></summary>
|
||||
|
||||
- 🏢 29 ready-to-use agent teams
|
||||
- ⚡ Pre-configured finance workflows
|
||||
@@ -161,7 +260,29 @@ Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural l
|
||||
|
||||
</sub>
|
||||
|
||||
### 🎬 Demo
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Alpha Zoo</b> <sub>452 pre-built quant alphas across 4 zoos</sub></summary>
|
||||
|
||||
- 🧬 452 cross-sectional alphas, lookahead-banned at the operator layer
|
||||
- 📈 IC + IR + alive/reversed/dead categorisation in one CLI command
|
||||
- 🔬 AST purity gate + 300-row lookahead sentinel test + `pytest-socket` network kill-switch
|
||||
- 📦 Apache-2 attribution for Qlib; per-zoo `LICENSE.md` declaring formulas as mathematical content
|
||||
- 🤝 Developer Certificate of Origin (DCO) sign-off workflow for community PRs
|
||||
|
||||
| Zoo | Count | Source | License |
|
||||
|-----|-------|--------|---------|
|
||||
| **qlib158** | 154 | Microsoft Qlib `Alpha158` (Apache-2.0, commit-pinned) | Apache-2.0 |
|
||||
| **alpha101** | 101 | Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991 | Formulas are mathematical content |
|
||||
| **gtja191** | 191 | Guotai Junan (2014), "191 Short-period Trading Alpha Factors" | Formulas are mathematical content |
|
||||
| **academic** | 6 | Fama-French 5 + Carhart momentum (price-based proxies) | Public academic literature |
|
||||
|
||||
Run `vibe-trading alpha list` to browse, `vibe-trading alpha show <id>` for formulas + source, `vibe-trading alpha bench --zoo X --universe Y --period Z` to score a whole zoo.
|
||||
|
||||
</details>
|
||||
|
||||
## 🎬 Demo
|
||||
|
||||
<div align="center">
|
||||
<table>
|
||||
@@ -185,7 +306,7 @@ https://github.com/user-attachments/assets/3754a414-c3ee-464f-b1e8-78e1a74fbd30
|
||||
|
||||
---
|
||||
|
||||
## 🚀 Quick Started
|
||||
## 🚀 Quick Start
|
||||
|
||||
### One-line install (PyPI)
|
||||
|
||||
@@ -193,6 +314,13 @@ https://github.com/user-attachments/assets/3754a414-c3ee-464f-b1e8-78e1a74fbd30
|
||||
pip install vibe-trading-ai
|
||||
```
|
||||
|
||||
Then run a first research task:
|
||||
|
||||
```bash
|
||||
vibe-trading init
|
||||
vibe-trading run -p "Backtest a BTC-USDT 20/50 moving-average strategy for 2024 and summarize return and drawdown"
|
||||
```
|
||||
|
||||
> **Package name vs commands:** The PyPI package is `vibe-trading-ai`. Once installed, you get three commands:
|
||||
>
|
||||
> | Command | Purpose |
|
||||
@@ -222,8 +350,9 @@ vibe-trading-mcp # start MCP server (stdio)
|
||||
- An **LLM API key** from any supported provider — or run locally with **Ollama** (no key needed)
|
||||
- **Python 3.11+** for Path B
|
||||
- **Docker** for Path A
|
||||
- OpenAI Codex can also be used with ChatGPT OAuth: set `LANGCHAIN_PROVIDER=openai-codex`, then run `vibe-trading provider login openai-codex`. This does not use `OPENAI_API_KEY`.
|
||||
|
||||
> **Supported LLM providers:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Ollama (local). See `.env.example` for config.
|
||||
> **Supported LLM providers:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Z.ai, Ollama (local). See `.env.example` for config.
|
||||
|
||||
> **Tip:** All markets work without any API keys thanks to automatic fallback. yfinance (HK/US), OKX (crypto), and AKShare (A-shares, US, HK, futures, forex) are all free. Tushare token is optional — AKShare covers A-shares as a free fallback.
|
||||
|
||||
@@ -239,6 +368,8 @@ docker compose up --build
|
||||
|
||||
Open `http://localhost:8899`. Backend + frontend in one container.
|
||||
|
||||
Docker publishes the backend on `127.0.0.1:8899` by default and runs the app as a non-root container user. If you intentionally expose the API beyond your own machine, set a strong `API_AUTH_KEY` and send `Authorization: Bearer <key>` from clients.
|
||||
|
||||
### Path B: Local install
|
||||
|
||||
```bash
|
||||
@@ -300,14 +431,30 @@ Copy `agent/.env.example` to `agent/.env` and uncomment the provider block you w
|
||||
| `LANGCHAIN_PROVIDER` | Yes | Provider name (`openrouter`, `deepseek`, `groq`, `ollama`, etc.) |
|
||||
| `<PROVIDER>_API_KEY` | Yes* | API key (`OPENROUTER_API_KEY`, `DEEPSEEK_API_KEY`, etc.) |
|
||||
| `<PROVIDER>_BASE_URL` | Yes | API endpoint URL |
|
||||
| `LANGCHAIN_MODEL_NAME` | Yes | Model name (e.g. `deepseek/deepseek-v3.2`) |
|
||||
| `LANGCHAIN_MODEL_NAME` | Yes | Model name (e.g. `deepseek-v4-pro`) |
|
||||
| `TUSHARE_TOKEN` | No | Tushare Pro token for A-share data (falls back to AKShare) |
|
||||
| `TIMEOUT_SECONDS` | No | LLM call timeout, default 120s |
|
||||
| `API_AUTH_KEY` | Recommended for network deployments | Bearer token required when the API is reachable from non-local clients |
|
||||
| `VIBE_TRADING_ENABLE_SHELL_TOOLS` | No | Explicit opt-in for shell-capable tools in remote API/MCP-SSE style deployments |
|
||||
| `VIBE_TRADING_ALLOWED_FILE_ROOTS` | No | Extra comma-separated roots for document and broker-journal imports |
|
||||
| `VIBE_TRADING_ALLOWED_RUN_ROOTS` | No | Extra comma-separated roots for generated-code run directories |
|
||||
|
||||
<sub>* Ollama does not require an API key.</sub>
|
||||
<sub>* Ollama does not require an API key. OpenAI Codex uses ChatGPT OAuth and stores tokens via `oauth-cli-kit`, not in `agent/.env`.</sub>
|
||||
|
||||
**Free data (no key needed):** A-shares via AKShare, HK/US equities via yfinance, crypto via OKX, 100+ crypto exchanges via CCXT. The system automatically selects the best available source for each market.
|
||||
|
||||
### 🎯 Recommended Models
|
||||
|
||||
Vibe-Trading is a tool-heavy agent — skills, backtests, memory, and swarms all flow through tool calls. Model choice directly decides whether the agent *uses* its tools or fabricates answers from training data.
|
||||
|
||||
| Tier | Examples | When to use |
|
||||
|------|----------|-------------|
|
||||
| **Best** | `anthropic/claude-opus-4.7`, `anthropic/claude-sonnet-4.6`, `openai/gpt-5.4`, `google/gemini-3.1-pro-preview` | Complex swarms (3+ agents), long research sessions, paper-grade analysis |
|
||||
| **Sweet spot** (default) | `deepseek-v4-pro`, `deepseek/deepseek-v4-pro`, `x-ai/grok-4.20`, `z-ai/glm-5.1`, `moonshotai/kimi-k2.5`, `qwen/qwen3-max-thinking` | Daily driver — reliable tool-calling at ~1/10 the cost |
|
||||
| **Avoid for agent use** | `*-nano`, `*-flash-lite`, `*-coder-next`, small / distilled variants | Tool-calling is unreliable — the agent will appear to "answer from memory" instead of loading skills or running backtests |
|
||||
|
||||
The default `agent/.env.example` ships with DeepSeek official API + `deepseek-v4-pro`; OpenRouter users can use `deepseek/deepseek-v4-pro`.
|
||||
|
||||
---
|
||||
|
||||
## 🖥 CLI Reference
|
||||
@@ -316,6 +463,7 @@ Copy `agent/.env.example` to `agent/.env` and uncomment the provider block you w
|
||||
vibe-trading # interactive TUI
|
||||
vibe-trading run -p "..." # single run
|
||||
vibe-trading serve # API server
|
||||
vibe-trading alpha list # browse 452 pre-built alphas; show / bench / compare / export-manifest sub-commands available
|
||||
```
|
||||
|
||||
<details>
|
||||
@@ -324,7 +472,7 @@ vibe-trading serve # API server
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/help` | Show all commands |
|
||||
| `/skills` | List all 68 finance skills |
|
||||
| `/skills` | List all 75 finance skills |
|
||||
| `/swarm` | List 29 swarm team presets |
|
||||
| `/swarm run <preset> [vars_json]` | Run a swarm team with live streaming |
|
||||
| `/swarm list` | Swarm run history |
|
||||
@@ -333,7 +481,7 @@ vibe-trading serve # API server
|
||||
| `/list` | Recent runs |
|
||||
| `/show <run_id>` | Run details + metrics |
|
||||
| `/code <run_id>` | Generated strategy code |
|
||||
| `/pine <run_id>` | Pine Script for TradingView |
|
||||
| `/pine <run_id>` | Export indicators (TradingView + TDX + MT5) |
|
||||
| `/trace <run_id>` | Full execution replay |
|
||||
| `/continue <run_id> <prompt>` | Continue a run with new instructions |
|
||||
| `/sessions` | List chat sessions |
|
||||
@@ -361,16 +509,111 @@ vibe-trading --swarm-run investment_committee '{"topic":"BTC outlook"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # Pine Script for TradingView
|
||||
vibe-trading --pine <run_id> # Export indicators (TradingView + TDX + MT5)
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "refine the strategy"
|
||||
vibe-trading --upload report.pdf
|
||||
```
|
||||
|
||||
```bash
|
||||
vibe-trading alpha list --zoo gtja191 --limit 10
|
||||
vibe-trading alpha show gtja191_171
|
||||
vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025 --top 20
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 💡 Examples
|
||||
|
||||
### Strategy & Backtesting
|
||||
|
||||
```bash
|
||||
# Moving average crossover on US equities
|
||||
vibe-trading run -p "Backtest a 20/50-day moving average crossover on AAPL for the past year, show Sharpe ratio and max drawdown"
|
||||
|
||||
# RSI mean-reversion on crypto
|
||||
vibe-trading run -p "Test RSI(14) mean-reversion on BTC-USDT: buy below 30, sell above 70, last 6 months"
|
||||
|
||||
# Multi-factor strategy on A-shares
|
||||
vibe-trading run -p "Backtest a momentum + value + quality multi-factor strategy on CSI 300 constituents over 2 years"
|
||||
|
||||
# After backtesting, export to TradingView / TDX / MetaTrader 5
|
||||
vibe-trading --pine <run_id>
|
||||
```
|
||||
|
||||
**Bench a pre-built alpha zoo** (one line):
|
||||
```bash
|
||||
vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025 --top 20
|
||||
```
|
||||
|
||||
**Browse the catalogue** and inspect a single alpha:
|
||||
```bash
|
||||
vibe-trading alpha list --zoo gtja191 --theme reversal --limit 10
|
||||
vibe-trading alpha show gtja191_171
|
||||
```
|
||||
|
||||
**Compose a multi-factor signal** from the zoo (Python):
|
||||
```python
|
||||
from src.skills.multi_factor.zoo_signal_engine import ZooSignalEngine
|
||||
engine = ZooSignalEngine.from_zoo(["gtja191_171", "gtja191_111", "gtja191_163"])
|
||||
panel = ... # your wide OHLCV panel
|
||||
signal = engine.compute_signal(panel)
|
||||
```
|
||||
|
||||
### Market Research
|
||||
|
||||
```bash
|
||||
# Equity deep-dive
|
||||
vibe-trading run -p "Research NVDA: earnings trend, analyst consensus, option flow, and key risks for next quarter"
|
||||
|
||||
# Macro analysis
|
||||
vibe-trading run -p "Analyze the current Fed rate path, USD strength, and impact on EM equities and gold"
|
||||
|
||||
# Crypto on-chain
|
||||
vibe-trading run -p "Deep dive BTC on-chain: whale flows, exchange balances, miner activity, and funding rates"
|
||||
```
|
||||
|
||||
### Swarm Workflows
|
||||
|
||||
```bash
|
||||
# Bull/bear debate on a stock
|
||||
vibe-trading --swarm-run investment_committee '{"topic": "Is TSLA a buy at current levels?"}'
|
||||
|
||||
# Quant strategy from screening to backtest
|
||||
vibe-trading --swarm-run quant_strategy_desk '{"universe": "S&P 500", "horizon": "3 months"}'
|
||||
|
||||
# Crypto desk: funding + liquidation + flow → risk manager
|
||||
vibe-trading --swarm-run crypto_trading_desk '{"asset": "ETH-USDT", "timeframe": "1w"}'
|
||||
|
||||
# Global macro portfolio allocation
|
||||
vibe-trading --swarm-run macro_rates_fx_desk '{"focus": "Fed pivot impact on EM bonds"}'
|
||||
```
|
||||
|
||||
### Cross-Session Memory
|
||||
|
||||
```bash
|
||||
# Save your preferences once
|
||||
vibe-trading run -p "Remember: I prefer RSI-based strategies, max 10% drawdown, hold period 5–20 days"
|
||||
|
||||
# The agent recalls them in future sessions automatically
|
||||
vibe-trading run -p "Build a crypto strategy that fits my risk profile"
|
||||
```
|
||||
|
||||
### Upload & Analyze Documents
|
||||
|
||||
```bash
|
||||
# Analyze a broker export or earnings report
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Profile my trading behavior and identify any biases"
|
||||
|
||||
vibe-trading --upload NVDA_Q1_earnings.pdf
|
||||
vibe-trading run -p "Summarize the key risks and beats/misses from this earnings report"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 🌐 API Server
|
||||
|
||||
```bash
|
||||
@@ -381,7 +624,7 @@ vibe-trading serve --port 8899
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | List runs |
|
||||
| `GET` | `/runs/{run_id}` | Run details |
|
||||
| `GET` | `/runs/{run_id}/pine` | Pine Script export |
|
||||
| `GET` | `/runs/{run_id}/pine` | Multi-platform indicator export |
|
||||
| `POST` | `/sessions` | Create session |
|
||||
| `POST` | `/sessions/{id}/messages` | Send message |
|
||||
| `GET` | `/sessions/{id}/events` | SSE event stream |
|
||||
@@ -389,14 +632,34 @@ vibe-trading serve --port 8899
|
||||
| `GET` | `/swarm/presets` | List swarm presets |
|
||||
| `POST` | `/swarm/runs` | Start swarm run |
|
||||
| `GET` | `/swarm/runs/{id}/events` | Swarm SSE stream |
|
||||
| `GET` | `/alpha/list` | List alphas (filter by zoo/theme/universe) |
|
||||
| `GET` | `/alpha/{alpha_id}` | Alpha metadata + source code |
|
||||
| `POST` | `/alpha/bench` | Start a bench job (returns `job_id`) |
|
||||
| `GET` | `/alpha/bench/{job_id}/stream` | SSE progress stream |
|
||||
| `GET` | `/settings/llm` | Read Web UI LLM settings |
|
||||
| `PUT` | `/settings/llm` | Update local LLM settings |
|
||||
| `GET` | `/settings/data-sources` | Read local data source settings |
|
||||
| `PUT` | `/settings/data-sources` | Update local data source settings |
|
||||
|
||||
Interactive docs: `http://localhost:8899/docs`
|
||||
|
||||
### Security defaults
|
||||
|
||||
For localhost development, `vibe-trading serve` keeps the browser workflow simple. For any non-local client, sensitive API endpoints require `API_AUTH_KEY`; use `Authorization: Bearer <key>` for JSON/upload requests. Browser EventSource streams are handled by the Web UI after you enter the same key once in Settings.
|
||||
|
||||
Shell-capable tools are available to local CLI and trusted localhost workflows, but are not exposed to remote API sessions unless you explicitly set `VIBE_TRADING_ENABLE_SHELL_TOOLS=1`. Document and journal readers are limited to upload/import roots by default; place files under `agent/uploads`, `agent/runs`, `./uploads`, `./data`, `~/.vibe-trading/uploads`, or `~/.vibe-trading/imports`, or add a dedicated directory through `VIBE_TRADING_ALLOWED_FILE_ROOTS`.
|
||||
|
||||
### Web UI Settings
|
||||
|
||||
The Web UI Settings page lets local users update the LLM provider/model, base URL, generation parameters, reasoning effort, and optional market data credentials such as the Tushare token. Settings are persisted to `agent/.env`; provider defaults are loaded from `agent/src/providers/llm_providers.json`.
|
||||
|
||||
Settings reads are side-effect free: `GET /settings/llm` and `GET /settings/data-sources` never create `agent/.env`, and they only return project-relative paths. Settings reads and writes can expose credential state or update credentials/runtime environment, so they require `API_AUTH_KEY` when configured. If `API_AUTH_KEY` is unset for dev mode, settings access is accepted only from loopback clients.
|
||||
|
||||
---
|
||||
|
||||
## 🔌 MCP Plugin
|
||||
|
||||
Vibe-Trading exposes 17 MCP tools for any MCP-compatible client. Runs as a stdio subprocess — no server setup needed. **16 of 17 tools work with zero API keys** (HK/US/crypto). Only `run_swarm` needs an LLM key.
|
||||
Vibe-Trading exposes 22 MCP tools for any MCP-compatible client. Runs as a stdio subprocess — no server setup needed. **21 of 22 tools work with zero API keys** (HK/US/crypto). Only `run_swarm` needs an LLM key.
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
@@ -438,7 +701,7 @@ vibe-trading-mcp --transport sse # SSE for web clients
|
||||
|
||||
</details>
|
||||
|
||||
**MCP tools exposed (17):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
**MCP tools exposed (22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
|
||||
<details>
|
||||
<summary><b>Install from ClawHub (one command)</b></summary>
|
||||
@@ -458,7 +721,7 @@ Browse on ClawHub: [clawhub.ai/skills/vibe-trading](https://clawhub.ai/skills/vi
|
||||
<details>
|
||||
<summary><b>OpenSpace — self-evolving skills</b></summary>
|
||||
|
||||
All 68 finance skills are published on [open-space.cloud](https://open-space.cloud) and evolve autonomously through OpenSpace's self-evolution engine.
|
||||
All 75 finance skills are published on [open-space.cloud](https://open-space.cloud) and evolve autonomously through OpenSpace's self-evolution engine.
|
||||
|
||||
To use with OpenSpace, add both MCP servers to your agent config:
|
||||
|
||||
@@ -480,12 +743,93 @@ To use with OpenSpace, add both MCP servers to your agent config:
|
||||
}
|
||||
```
|
||||
|
||||
OpenSpace will auto-discover all 68 skills, enabling auto-fix, auto-improve, and community sharing. Search for Vibe-Trading skills via `search_skills("finance backtest")` in any OpenSpace-connected agent.
|
||||
OpenSpace will auto-discover all 75 skills, enabling auto-fix, auto-improve, and community sharing. Search for Vibe-Trading skills via `search_skills("finance backtest")` in any OpenSpace-connected agent.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 🔌 Loading Tools from External MCP Servers (MCP Client Mode)
|
||||
|
||||
> **This is the opposite direction from the MCP Plugin above.**
|
||||
> The MCP Plugin lets *other* agents call Vibe-Trading tools.
|
||||
> This section lets the *built-in* Vibe-Trading agent call tools from *your* external MCP servers.
|
||||
|
||||
### Quick start
|
||||
|
||||
Create `~/.vibe-trading/agent.json`:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"my-server": {
|
||||
"command": "uvx",
|
||||
"args": ["my-mcp-server"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Run any CLI command — tools from `my-server` are automatically injected into the agent's registry after local tools:
|
||||
|
||||
```bash
|
||||
vibe-trading run "use my-server to do X"
|
||||
```
|
||||
|
||||
### Config reference
|
||||
|
||||
| Field | Type | Default | Description |
|
||||
|-------|------|---------|-------------|
|
||||
| `command` | string | required | Executable to spawn |
|
||||
| `args` | array | `[]` | Command-line arguments |
|
||||
| `env` | object | `{}` | Extra environment variables merged into the subprocess env |
|
||||
| `toolTimeout` | number | `30` | Per-tool call timeout in seconds |
|
||||
| `enabledTools` | array | `["*"]` | Tool allowlist. Use `["*"]` to expose all tools from the server |
|
||||
|
||||
Config file location: `~/.vibe-trading/agent.json` (JSON or YAML).
|
||||
|
||||
### Per-session overrides (API)
|
||||
|
||||
When creating a session via the API you can pass `mcpServers` inside `session.config` to extend or override the global config for that session only:
|
||||
|
||||
```json
|
||||
{
|
||||
"config": {
|
||||
"mcpServers": {
|
||||
"research-server": {
|
||||
"command": "uvx",
|
||||
"args": ["research-mcp"],
|
||||
"enabledTools": ["search", "fetch"]
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Tool naming
|
||||
|
||||
Remote tools are exposed with stable names: `mcp_<server>_<tool>`.
|
||||
|
||||
If two server names produce the same ASCII-safe local prefix (e.g. `foo-bar` and `foo_bar` both become `foo_bar`), a deterministic hash suffix is appended at the server-segment level so names remain unique. The operator receives a warning:
|
||||
|
||||
```
|
||||
WARNING: Configured MCP server 'foo-bar' collides with another server after local name
|
||||
normalization. Using local tool prefix 'mcp_foo_bar_<hash>_<tool>' to keep generated
|
||||
tool names unique. Rename the server in agent config if you want a different prefix.
|
||||
```
|
||||
|
||||
### v1 limits
|
||||
|
||||
| Limit | Detail |
|
||||
|-------|--------|
|
||||
| Transport | stdio only (SSE / streamable HTTP excluded in v1) |
|
||||
| Execution | serial only — MCP tools never enter the parallel readonly path |
|
||||
| Surfaces | tools only (resources and prompts excluded in v1) |
|
||||
| Hot reload | not supported — restart the process to pick up config changes |
|
||||
| Swarm path | MCP tools are not available inside Swarm worker registries in v1 |
|
||||
|
||||
---
|
||||
|
||||
## 📁 Project Structure
|
||||
|
||||
<details>
|
||||
@@ -496,51 +840,63 @@ Vibe-Trading/
|
||||
├── agent/ # Backend (Python)
|
||||
│ ├── cli.py # CLI entrypoint — interactive TUI + subcommands
|
||||
│ ├── api_server.py # FastAPI server — runs, sessions, upload, swarm, SSE
|
||||
│ ├── mcp_server.py # MCP server — 17 tools for OpenClaw / Claude Desktop
|
||||
│ ├── mcp_server.py # MCP server — 22 tools for OpenClaw / Claude Desktop
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # ReAct agent core
|
||||
│ │ │ ├── loop.py # main reasoning loop
|
||||
│ │ │ ├── skills.py # skill loader (68 SKILL.md files, 7 categories)
|
||||
│ │ │ ├── tools.py # tool orchestration
|
||||
│ │ │ ├── context.py # system prompt builder
|
||||
│ │ │ ├── memory.py # run memory / artifact store
|
||||
│ │ │ ├── loop.py # 5-layer compression + read/write tool batching
|
||||
│ │ │ ├── context.py # system prompt + auto-recall from persistent memory
|
||||
│ │ │ ├── skills.py # skill loader (75 bundled + user-created via CRUD)
|
||||
│ │ │ ├── tools.py # tool base class + registry
|
||||
│ │ │ ├── memory.py # lightweight workspace state per run
|
||||
│ │ │ ├── frontmatter.py # shared YAML frontmatter parser
|
||||
│ │ │ └── trace.py # execution trace writer
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 21 agent tools
|
||||
│ │ │ ├── backtest_tool.py # run backtests
|
||||
│ │ │ ├── factor_analysis_tool.py
|
||||
│ │ │ ├── options_pricing_tool.py
|
||||
│ │ │ ├── pattern_tool.py # chart pattern detection
|
||||
│ │ │ ├── doc_reader_tool.py # PDF reader (OCR fallback)
|
||||
│ │ │ ├── web_reader_tool.py # web page reader (Jina)
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo web search
|
||||
│ │ │ ├── swarm_tool.py # launch swarm teams
|
||||
│ │ │ └── ... # file I/O, bash, tasks, etc.
|
||||
│ │ ├── memory/ # Cross-session persistent memory
|
||||
│ │ │ └── persistent.py # file-based memory (~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 68 finance skills in 7 categories (SKILL.md each)
|
||||
│ │ ├── tools/ # 31 auto-discovered agent tools
|
||||
│ │ │ ├── backtest_tool.py # run backtests
|
||||
│ │ │ ├── remember_tool.py # cross-session memory (save/recall/forget)
|
||||
│ │ │ ├── skill_writer_tool.py # skill CRUD (save/patch/delete/file)
|
||||
│ │ │ ├── session_search_tool.py # FTS5 cross-session search
|
||||
│ │ │ ├── swarm_tool.py # launch swarm teams
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo web search
|
||||
│ │ │ └── ... # bash, file I/O, factor analysis, options, alpha browser + bench, etc.
|
||||
│ │ │
|
||||
│ │ ├── factors/ # Alpha Zoo — 452 alphas across 4 zoos
|
||||
│ │ │ ├── base.py # 19 operators (rank/scale/ts_*/delta/decay_linear/safe_div/vwap)
|
||||
│ │ │ ├── registry.py # AST-only metadata load + lazy compute + sanity gates
|
||||
│ │ │ ├── bench_runner.py # IC + alive/reversed/dead categorisation
|
||||
│ │ │ └── zoo/ # qlib158 (154) + alpha101 (101) + gtja191 (191) + academic (6)
|
||||
│ │ │
|
||||
│ │ ├── api/ # FastAPI route modules
|
||||
│ │ │ └── alpha_routes.py # /alpha/list, /alpha/{id}, /alpha/bench, SSE stream
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 75 finance skills in 8 categories (SKILL.md each)
|
||||
│ │ ├── swarm/ # Swarm DAG execution engine
|
||||
│ │ ├── session/ # Multi-turn chat session management
|
||||
│ │ │ └── presets/ # 29 swarm preset YAML definitions
|
||||
│ │ ├── session/ # Multi-turn chat + FTS5 session search
|
||||
│ │ └── providers/ # LLM provider abstraction
|
||||
│ │
|
||||
│ ├── backtest/ # Backtest engines
|
||||
│ │ ├── engines/ # 7 engines: china_a, global_equity, crypto, china_futures, global_futures, forex + options_portfolio
|
||||
│ │ ├── loaders/ # 5 sources: tushare, okx, yfinance, akshare, ccxt
|
||||
│ │ │ ├── base.py # DataLoader Protocol
|
||||
│ │ │ └── registry.py # Registry + auto-fallback chains
|
||||
│ │ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│ │
|
||||
│ └── config/swarm/ # 29 swarm preset YAML definitions
|
||||
│ └── backtest/ # Backtest engines
|
||||
│ ├── engines/ # 7 engines + composite cross-market engine + options_portfolio
|
||||
│ ├── loaders/ # 6 sources: tushare, okx, yfinance, akshare, ccxt, futu
|
||||
│ │ ├── base.py # DataLoader Protocol
|
||||
│ │ └── registry.py # Registry + auto-fallback chains
|
||||
│ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│
|
||||
├── frontend/ # Web UI (React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
│ ├── pages/ # Home, Agent, RunDetail, Compare
|
||||
│ ├── pages/ # Home, Agent, AlphaZoo, RunDetail, Compare, Correlation, Settings
|
||||
│ ├── components/ # chat, charts, layout
|
||||
│ └── stores/ # Zustand state management
|
||||
│
|
||||
├── Dockerfile # Multi-stage build
|
||||
├── docker-compose.yml # One-command deploy
|
||||
├── pyproject.toml # Package config + CLI entrypoint
|
||||
├── tools/ # Repo-level CI helpers
|
||||
│ └── ci_grep_gates.sh # rejects yaml.load / trademark / per-stock-data leaks
|
||||
└── LICENSE # MIT
|
||||
```
|
||||
|
||||
@@ -581,17 +937,15 @@ Vibe-Trading is part of the **[HKUDS](https://github.com/HKUDS)** agent ecosyste
|
||||
|
||||
| Phase | Feature | Status |
|
||||
|-------|---------|--------|
|
||||
| **Analysis & Viz** | Options volatility surface & Greeks 3D visualization | Planned |
|
||||
| | Cross-asset correlation heatmap with rolling window & clustering | Planned |
|
||||
| | Benchmark comparison in CLI backtest output | Planned |
|
||||
| | Calmar Ratio & Omega Ratio in backtest metrics | Planned |
|
||||
| **Skills & Presets** | Dividend Analysis skill | Planned |
|
||||
| | ESG / Sustainable Investing swarm preset | Planned |
|
||||
| | Emerging Markets Research Desk swarm preset | Planned |
|
||||
| **Portfolio & Optimization** | Advanced portfolio optimizer: leverage, sector caps, turnover constraints | Planned |
|
||||
| **Future** | Beginner tutorial: "5-minute natural language backtest" | Planned |
|
||||
| | Live data streaming via WebSocket | Exploring |
|
||||
| | Strategy marketplace (share & discover) | Exploring |
|
||||
| **Trust Layer** | Reproducible run cards are emitted and shown in Run Detail; v1 adds tool traces and citations | v0 Shipped |
|
||||
| **Hypothesis Registry** | Durable research hypotheses with lifecycle status, data sources, skills, run-card links, and invalidation notes | Backend MVP Shipped |
|
||||
| **Research Autopilot** | Manual-first research loop: hypothesis → deterministic backtest → evidence report | Next |
|
||||
| **Data Bridge** | Bring-your-own data: local CSV/Parquet/SQL connectors with schema mapping | Planned |
|
||||
| **Options Lab** | Vol surface, Greeks dashboard, payoff/scenario explorer | Planned |
|
||||
| **Portfolio Studio** | Risk x-ray, constraints, turnover-aware optimizer, rebalance notes | Planned |
|
||||
| **Alpha Zoo** | 452 pre-built alphas (Qlib 158 + Kakushadze 101 + GTJA 191 + FF5 + Carhart) with one-line bench, agent integration, and Web UI | **Shipped 0.1.8** |
|
||||
| **Research Delivery** | Scheduled briefs to Slack / Telegram / email-style channels | Planned |
|
||||
| **Community** | Shareable skills, presets, and strategy cards | Exploring |
|
||||
|
||||
---
|
||||
|
||||
@@ -609,6 +963,18 @@ Want to contribute something bigger? Check the [Roadmap](#-roadmap) above and op
|
||||
|
||||
Thanks to everyone who has contributed to Vibe-Trading!
|
||||
|
||||
Recent v0.1.7 cycle contributors and credits:
|
||||
|
||||
- @GTC2080 / TaoMu — Web UI Settings and provider/data-source configuration APIs (#57)
|
||||
- @BigNounce90 — validation CLI hardening for backtest `run_dir` input (#60)
|
||||
- @shadowinlife — A-share pre-ST filter skill (#63)
|
||||
- @MB-Ndhlovu — correlation heatmap dashboard and review fixes (#64, #66)
|
||||
- @ykykj — OpenAI Codex OAuth provider option (#65)
|
||||
- @RuifengFu — interactive CLI live status bar and prompt editing (#69)
|
||||
- @SiMinus — swarm preset inspection command (#73)
|
||||
- @warren618 / Haozhe Wu — security hardening, release integration, docs, Docker, packaging, and local dev workflow
|
||||
- lemi9090 (S2W) — coordinated security research, validation, and disclosure support
|
||||
|
||||
<a href="https://github.com/HKUDS/Vibe-Trading/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=HKUDS/Vibe-Trading" />
|
||||
</a>
|
||||
@@ -625,6 +991,12 @@ MIT License — see [LICENSE](LICENSE)
|
||||
|
||||
---
|
||||
|
||||
## Star History
|
||||
|
||||
[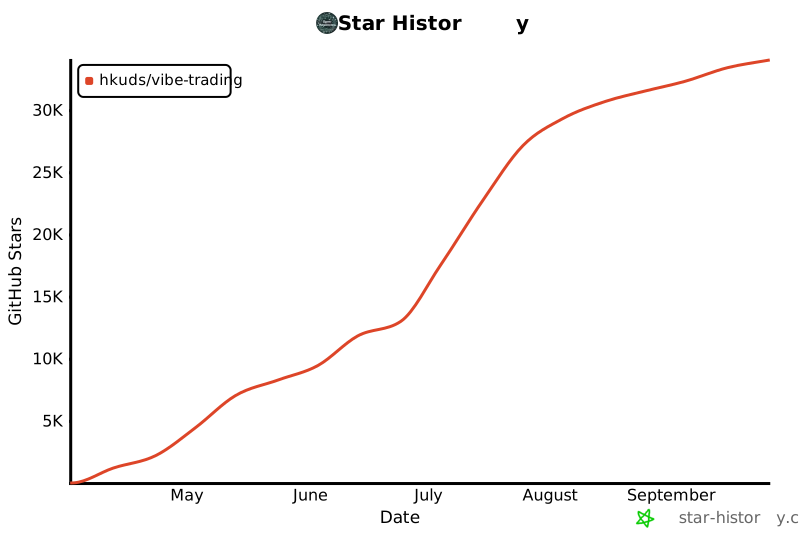](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
Thanks for visiting <b>Vibe-Trading</b> ✨
|
||||
</p>
|
||||
|
||||
+925
@@ -0,0 +1,925 @@
|
||||
<p align="center">
|
||||
<a href="README.md">English</a> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a> | <b>العربية</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<img src="assets/icon.png" width="120" alt="شعار Vibe-Trading"/>
|
||||
</p>
|
||||
|
||||
<h1 align="center">Vibe-Trading: وكيل التداول الشخصي الخاص بك</h1>
|
||||
|
||||
<p align="center">
|
||||
<b>أمر واحد يمنح وكيلك قدرات تداول شاملة</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<img src="https://img.shields.io/badge/Python-3.11%2B-3776AB?style=flat&logo=python&logoColor=white" alt="Python">
|
||||
<img src="https://img.shields.io/badge/Backend-FastAPI-009688?style=flat" alt="FastAPI">
|
||||
<img src="https://img.shields.io/badge/Frontend-React%2019-61DAFB?style=flat&logo=react&logoColor=white" alt="React">
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="License"></a>
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
<a href="https://discord.gg/2vDYc2w5"><img src="https://img.shields.io/badge/Discord-Join-7289DA?style=flat-square&logo=discord&logoColor=white" alt="Discord"></a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://vibetrading.wiki/">الموقع</a> ·
|
||||
<a href="https://vibetrading.wiki/docs/">الوثائق</a> ·
|
||||
<a href="#-الأخبار">الأخبار</a> ·
|
||||
<a href="#-الميزات-الرئيسية">الميزات</a> ·
|
||||
<a href="#-حساب-الظل">حساب الظل</a> ·
|
||||
<a href="#-العرض-التوضيحي">العرض التوضيحي</a> ·
|
||||
<a href="#-البدء-السريع">البدء السريع</a> ·
|
||||
<a href="#-أمثلة">أمثلة</a> ·
|
||||
<a href="#-خادم-api">API / MCP</a> ·
|
||||
<a href="#-خارطة-الطريق">خارطة الطريق</a> ·
|
||||
<a href="#المساهمة">المساهمة</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="#-البدء-السريع"><img src="assets/pip-install.svg" height="45" alt="pip install vibe-trading-ai"></a>
|
||||
</p>
|
||||
|
||||
---
|
||||
|
||||
## 📰 الأخبار
|
||||
|
||||
- **2026-05-17** 🧬 **Alpha Zoo v1 (0.1.8)**: 452 ألفا كمّي جاهز عبر 4 zoos — `qlib158` (ميزات Alpha158 من Microsoft Qlib، إسناد Apache-2.0)، `alpha101` (إعادة تنفيذ "101 Formulaic Alphas" من Kakushadze بناءً على ورقة arXiv:1601.00991)، `gtja191` (تقرير بحث Guotai Junan 2014 لعوامل تداول قصيرة الأجل)، `academic` (Fama-French 5 + Carhart momentum كـ proxy قائم على الأسعار). سطر أوامر واحد للـ bench على أي universe: `vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025`. تتضمن بوابة AST للنقاء، اختبار حماية lookahead، عزل الشبكة عبر `pytest-socket`، LICENSE.md لكل zoo، وسير عمل توقيع DCO لمساهمات المجتمع. تقديم Alpha Library تلقائياً على [vibetrading.wiki/alpha-library/](https://vibetrading.wiki/alpha-library/)، مع منشور Research Lab [Which of the 191 GTJA alphas still work in 2026?](https://vibetrading.wiki/research-lab/posts/alpha-191-in-2026.html).
|
||||
- **2026-05-16** 🧪 **تحديث عمود البحث**: أضيف backend Hypothesis Registry مع `create_hypothesis` و`update_hypothesis` و`link_backtest` و`search_hypotheses`. تضيف قارئات المحتوى الخارجي الآن `security_warnings` تحذيرية فقط، وانتقل ماسح Shadow Account من calendar-phase stub القديم إلى تقييم حتمي لميزات OHLCV.
|
||||
- **2026-05-15** 🪪 تعرض صفحة تفاصيل الـ run الآن بطاقة Trust Layer run card إلى جانب المقاييس والمخرجات، لتكمل الجانب الواجهي من عمل `run_card.json` الذي هبط في 2026-05-12. كما تم تعزيز `PersistentMemory.add()` على مسارات الطول والأسماء الفارغة أو التي تحتوي على فراغات فقط وبايتات التحكم C0/C1 ضمن فرز #108/#109/#110 ([#112](https://github.com/HKUDS/Vibe-Trading/pull/112)، شكراً @Teerapat-Vatpitak).
|
||||
|
||||
<details>
|
||||
<summary>أخبار سابقة</summary>
|
||||
|
||||
- **2026-05-14** 🌐 أصبح الويكي العام متاحاً على [vibetrading.wiki](https://vibetrading.wiki/) مع أقسام docs وtutorials وResearch Lab وAlpha Library، ويُنشر عبر Cloudflare Pages. أصبحت الذاكرة الدائمة أيضاً قابلة للفحص من سطر الأوامر عبر `vibe-trading memory list/show/search/forget` ([#102](https://github.com/HKUDS/Vibe-Trading/pull/102)، شكراً @Teerapat-Vatpitak)، كما يدعم توليد الرموز وslugs للذاكرة الآن التايلاندية والعربية والعبرية والنص السيريلي ([#104](https://github.com/HKUDS/Vibe-Trading/pull/104)).
|
||||
|
||||
- **2026-05-13** 🧭 أصبحت تشغيلات السرب تؤسس عمل الوكلاء على بيانات سوق مجلوبة مسبقاً، مع تقارير محفوظة أنظف ([#93](https://github.com/HKUDS/Vibe-Trading/pull/93)، [#84](https://github.com/HKUDS/Vibe-Trading/pull/84)).
|
||||
- **2026-05-12** 🧾 أصبحت الاختبارات الرجعية تنتج `run_card.json` و`run_card.md` إلى جانب المخرجات لدعم تشغيلات بحثية قابلة لإعادة الإنتاج.
|
||||
- **2026-05-11** 🧭 **Memory slugs، ومحاسبة السرب، وفحص CLI المسبق**: أصبحت الذاكرة الدائمة تحفظ أحرف CJK عند توليد slugs للملفات، مما يمنع اصطدامات أسماء صامتة لملاحظات الصينية/اليابانية/الكورية ([#95](https://github.com/HKUDS/Vibe-Trading/pull/95)، شكراً @voidborne-d). تفضل مجاميع تشغيل السرب الآن استخدام استهلاك الرموز المبلغ من المزود مع الإبقاء على التقدير الاحتياطي الحالي ([#94](https://github.com/HKUDS/Vibe-Trading/pull/94)، شكراً @Teerapat-Vatpitak)، كما حصلت واجهة تشغيل CLI على فحص بدء مبكر للمشكلات البيئية الشائعة ([#96](https://github.com/HKUDS/Vibe-Trading/pull/96)، شكراً @ykykj).
|
||||
- **2026-05-10** 🧱 **حواجز انحدار وبيانات تشغيل وصفية**: أصبح استدعاء الذاكرة يتعامل مع الشرطات السفلية كحدود رموز، لذلك تطابق ذكريات `snake_case` مثل `mcp_wiring_test` استعلامات طبيعية مثل "mcp wiring" ([#87](https://github.com/HKUDS/Vibe-Trading/pull/87)، شكراً @hp083625). يملك خادم MCP الآن اختبار smoke عبر subprocess يغطي initialize → `tools/list` → `tools/call` لحماية مسار التعطل في أول استدعاء ([#86](https://github.com/HKUDS/Vibe-Trading/pull/86))، كما وصلت تحسينات منخفضة المخاطر لاختبارات مسارات Windows، ومعالجة استثناءات API best-effort، والتحقق من allowed-root في `run_dir` للاختبار الرجعي، وبيانات provider/model في SwarmRun ([#88](https://github.com/HKUDS/Vibe-Trading/pull/88)، [#90](https://github.com/HKUDS/Vibe-Trading/pull/90)، [#91](https://github.com/HKUDS/Vibe-Trading/pull/91)، [#92](https://github.com/HKUDS/Vibe-Trading/pull/92)، شكراً @Teerapat-Vatpitak).
|
||||
- **2026-05-09** 🛡️ **تعزيز مسارات API واستقرار خادم MCP**: تتحقق مسارات run/session في API الآن من معرفات المسار قبل البحث، وترفض المعاملات المشوهة التي تحتوي على أسطر جديدة مع تثبيت السلوك في مجموعة اختبارات auth/security ([#80](https://github.com/HKUDS/Vibe-Trading/pull/80)، شكراً @SJoon99). يسخن خادم MCP سجل الأدوات على الخيط الرئيسي قبل خدمة `tools/call` لتجنب تعطل أول استدعاء في اكتشاف الأدوات الكسول ([#85](https://github.com/HKUDS/Vibe-Trading/pull/85)، شكراً @Teerapat-Vatpitak). كما يحترم Vite dev proxy المتغير `VITE_API_URL` لأهداف الخلفية غير الافتراضية ([#82](https://github.com/HKUDS/Vibe-Trading/pull/82)، شكراً @voidborne-d).
|
||||
- **2026-05-08** 🧾 **حقول قوائم Tushare داخل المرشحات**: تستطيع اختبارات أسهم A اليومية الآن طلب حقول قوائم مالية آمنة زمنياً عبر `fundamental_fields`، بحيث يمكن لمحركات الإشارات الفرز على أعمدة مثل `income_total_revenue` و`income_n_income` و`balancesheet_total_hldr_eqy_exc_min_int` و`fina_indicator_roe` بعد تواريخ الإعلان/الإفصاح ([#76](https://github.com/HKUDS/Vibe-Trading/pull/76)، شكراً @mrbob-git). ويجعل التعزيز اللاحق طلب حقول القوائم الصريح يفشل سريعاً إذا تعذر تشغيل إثراء Tushare، بدلاً من الرجوع بصمت إلى أشرطة الأسعار الخام ([#77](https://github.com/HKUDS/Vibe-Trading/pull/77)).
|
||||
- **2026-05-07** 📈 **أساسيات Tushare وفرز المجتمع**: أضيف عقد `TushareFundamentalProvider` بنمط point-in-time لتدفقات البحث الأساسي، مع تغطية انحدار لمسار متغير البيئة `TUSHARE_TOKEN` في المشروع ([#74](https://github.com/HKUDS/Vibe-Trading/pull/74)). كما أوضح فرز المجتمع أن Vibe-Trading يركز حالياً على لغة واجهة واحدة لتسريع التكرار، ويتجنب تبعيات بحث زائدة ما دام `web_search` المدعوم من DuckDuckGo مضمناً، ويتعامل مع النشر المستضاف غير الرسمي كمكان غير موثوق لمفاتيح API أو رموز مصادر البيانات.
|
||||
- **2026-05-06** 🚀 **إصدار v0.1.7** ([Release notes](https://github.com/HKUDS/Vibe-Trading/releases/tag/v0.1.7)، `pip install -U vibe-trading-ai`): نُشر تعزيز حدود الأمان على PyPI وClawHub، ويغطي افتراضات أكثر أماناً للـ API/القراءة/الرفع/الملفات/URL/الكود المولد/أدوات shell/Docker مع إبقاء تدفقات CLI/Web UI المحلية سهلة. تشمل الدورة أيضاً Web UI Settings، وخريطة ارتباط حرارية، وOpenAI Codex OAuth، ومرشح A-share pre-ST، وتحسين CLI التفاعلي، وفحص swarm presets، وتحليل التوزيعات، وصقل سير التطوير، ورفع حدود أمان تبعيات بناء الواجهة. شكراً لمساهمي 0.1.7 وlemi9090 (S2W) على التحقق الأمني المنسق.
|
||||
- **2026-05-05** 🛡️ **متابعة حدود الأمان**: استكمال تعزيز الأمان حول CORS origins الصريحة، ومؤشرات بيانات الاعتماد في Settings، وقراءة عناوين الويب، وتوليد كود Shadow Account، مع اختبارات انحدار لكل مسار. تبقى تدفقات CLI/Web UI على localhost كما هي؛ وعلى عمليات النشر البعيدة استخدام `API_AUTH_KEY` وorigins موثوقة صريحة.
|
||||
- **2026-05-04** 🖥️ **تجربة CLI تفاعلية وتنظيف CI**: يعرض الوضع التفاعلي الآن شريط حالة سفلياً مباشراً يبين provider/model ومدة الجلسة وكمون آخر تشغيل وإحصاءات استدعاءات الأدوات، مع تصفح سجل الأوامر وتحرير المؤشر بمفاتيح الأسهم عبر `prompt_toolkit` ([#69](https://github.com/HKUDS/Vibe-Trading/pull/69)). يعود CLI إلى Rich prompts عند غياب `prompt_toolkit` أو TTY. كما وُئمت توقعات مسارات CI مع صندوق استيراد الملفات المعزز وحل `/tmp` عبر المنصات، فعاد main إلى الأخضر ([`bb67dc7`](https://github.com/HKUDS/Vibe-Trading/commit/bb67dc7cfcc11553c57d8962bee56381dca43758)).
|
||||
- **2026-05-03** 🛡️ **تصحيح تعزيز الأمان**: يشدد مصادقة API الافتراضية للنشر غير المحلي، ويحمي قراءات run/session/swarm الحساسة، ويقيد حدود الرفع وقراءة الملفات المحلية، ويقيد أدوات shell بحسب نقطة الدخول، ويتحقق من تحميل الاستراتيجيات المولدة قبل الاستيراد، ويشغل صورة Docker كمستخدم غير root مع منفذ localhost فقط افتراضياً. تبقى تدفقات CLI وWeb UI المحلية سهلة؛ وعلى نشر API/Web البعيد ضبط `API_AUTH_KEY`.
|
||||
- **2026-05-02** 🧭 **تحليل التوزيعات وخارطة طريق أوضح**: أضيفت مهارة `dividend-analysis` لأسهم الدخل، واستدامة التوزيعات، ونموها، وعائد المساهمين، وآليات ex-dividend، وفحص مصائد العائد، مع تثبيتها باختبارات انحدار للمهارات المضمنة. تركز خارطة الطريق العامة الآن على Research Autopilot وData Bridge وOptions Lab وPortfolio Studio وAlpha Zoo وResearch Delivery وTrust Layer ومشاركة Community.
|
||||
- **2026-05-01** 🔥 **خريطة ارتباط حرارية وOpenAI Codex OAuth ومرشح A-share pre-ST**: لوحة/API ارتباط جديدة تحسب ارتباطات العوائد المتحركة وتعرض خريطة حرارية ECharts لتحليل المحافظ والرموز ([#64](https://github.com/HKUDS/Vibe-Trading/pull/64)). يدعم مزود OpenAI Codex الآن ChatGPT OAuth عبر `vibe-trading provider login openai-codex` مع بيانات Settings واختبارات انحدار للمحول ([#65](https://github.com/HKUDS/Vibe-Trading/pull/65)). أضيفت وعُززت مهارة `ashare-pre-st-filter` لفحص مخاطر ST/*ST في أسهم A، مع فلترة صلة عقوبات Sina حتى لا تضخم إشارات حسابات الأوراق المالية عدادات E2 ([#63](https://github.com/HKUDS/Vibe-Trading/pull/63)).
|
||||
- **2026-04-30** ⚙️ **Web UI Settings وتعزيز validation CLI**: صفحة Settings جديدة لمزود/نموذج LLM، وbase URL، وreasoning effort، وبيانات اعتماد مصادر البيانات، مدعومة بواجهات settings API محلية/محمية وببيانات مزودين قابلة للتكوين ([#57](https://github.com/HKUDS/Vibe-Trading/pull/57)). كما تعزز `python -m backtest.validation <run_dir>` حتى تفشل المدخلات الناقصة أو الفارغة أو المشوهة أو غير الموجودة أو غير الدليل برسائل واضحة قبل بدء التحقق ([#60](https://github.com/HKUDS/Vibe-Trading/pull/60)).
|
||||
- **2026-04-28** 🚀 **إصدار v0.1.6** (`pip install -U vibe-trading-ai`): إصلاح إرجاع `vibe-trading --swarm-presets` فارغاً بعد `pip install` / `uv tool install` ([#55](https://github.com/HKUDS/Vibe-Trading/issues/55))، حيث أصبحت ملفات preset YAML مضمنة داخل حزمة `src.swarm` ومثبتة بستة اختبارات انحدار. كما أصبح محمل AKShare يوجه ETFs مثل `510300.SH` والفوركس مثل `USDCNH` إلى النقاط الصحيحة مع fallback registry معزز. يجمع الإصدار كل ما بعد v0.1.5: لوحة مقارنة معيارية، بث `/upload` وحدود الحجم، محمل Futu (HK + A-share)، مهارة تصدير vnpy، تعزيز أمني، وتحميل واجهة كسول من 688KB إلى 262KB.
|
||||
- **2026-04-27** 📊 **لوحة مقارنة معيارية وأمان الرفع**: مخرجات الاختبار الرجعي تتضمن الآن لوحة مقارنة معيارية (ticker / benchmark return / excess return / information ratio) مع حل عبر yfinance لـ SPY وCSI 300 وغيرها ([#48](https://github.com/HKUDS/Vibe-Trading/issues/48)). كما تبث `/upload` جسم الطلب في أجزاء 1 MB وتتوقف بعد `MAX_UPLOAD_SIZE`، مما يحد الذاكرة تحت العملاء الضخمين/المشوهين ([#53](https://github.com/HKUDS/Vibe-Trading/pull/53))، ومثبتة بأربعة اختبارات انحدار.
|
||||
- **2026-04-22** 🛡️ **تعزيز وتكاملات جديدة**: فرض احتواء المسارات في `safe_path` وصندوق أدوات journal/shadow، وإرسال `.env.example` / الاختبارات / ملفات Docker في sdist عبر `MANIFEST.in`، وتصغير الحزمة الأولية للواجهة من 688KB إلى 262KB عبر التحميل الكسول على مستوى المسارات. إضافة محمل Futu لأسهم HK وA-share ([#47](https://github.com/HKUDS/Vibe-Trading/pull/47)) ومهارة تصدير vnpy CtaTemplate ([#46](https://github.com/HKUDS/Vibe-Trading/pull/46)).
|
||||
- **2026-04-21** 🛡️ **مساحة العمل والوثائق**: تطبيع `run_dir` النسبي إلى دليل التشغيل النشط ([#43](https://github.com/HKUDS/Vibe-Trading/pull/43)). أمثلة استخدام README ([#45](https://github.com/HKUDS/Vibe-Trading/pull/45)).
|
||||
- **2026-04-20** 🔌 **Reasoning وSwarm**: الحفاظ على `reasoning_content` عبر جميع مسارات `ChatOpenAI`، لتعمل أفكار Kimi / DeepSeek / Qwen من البداية للنهاية ([#39](https://github.com/HKUDS/Vibe-Trading/issues/39)). بث Swarm وإيقاف Ctrl+C نظيف ([#42](https://github.com/HKUDS/Vibe-Trading/issues/42)).
|
||||
- **2026-04-19** 📦 **v0.1.5**: النشر إلى PyPI وClawHub. رفع حد `python-multipart` لسد CVE، وربط 5 أدوات MCP جديدة (`analyze_trade_journal` + 4 أدوات shadow-account)، وإصلاح سجل `pattern_recognition` → `pattern`، ومطابقة تبعيات Docker، ومزامنة بيان SKILL (22 أداة MCP / 71 مهارة).
|
||||
- **2026-04-18** 👥 **Shadow Account**: استخرج قواعد استراتيجيتك من سجل وسيط → اختبر الظل عبر الأسواق → تقرير HTML/PDF من 8 أقسام يوضح ما تتركه على الطاولة (خرق القواعد، الخروج المبكر، الإشارات الفائتة، الصفقات المضادة). 4 أدوات جديدة، ومهارة واحدة، و32 أداة إجمالاً. أمثلة Trade Journal + Shadow Account موجودة الآن في شاشة ترحيب Web UI.
|
||||
- **2026-04-17** 📊 **محلل سجل التداول وقارئ ملفات شامل**: ارفع صادرات الوسطاء (同花顺/东财/富途/generic CSV) → ملف تداول تلقائي (أيام الاحتفاظ، معدل الربح، نسبة PnL، التراجع) + 4 تشخيصات سلوكية (disposition effect، الإفراط في التداول، مطاردة الزخم، anchoring). أصبح `read_document` يوجه PDF وWord وExcel وPowerPoint والصور (OCR) و40+ صيغة نصية خلف استدعاء موحد.
|
||||
- **2026-04-16** 🧠 **Agent Harness**: ذاكرة دائمة عبر الجلسات، بحث جلسات FTS5، مهارات ذاتية التطور (CRUD كامل)، ضغط سياق بخمس طبقات، وتجميع أدوات القراءة/الكتابة. 27 أداة، و107 اختبارات جديدة.
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**: مزود Z.ai ([#35](https://github.com/HKUDS/Vibe-Trading/pull/35))، وإصلاح temperature في MiniMax وتحديث النموذج ([#33](https://github.com/HKUDS/Vibe-Trading/pull/33)). 13 مزوداً.
|
||||
- **2026-04-14** 🔧 **استقرار MCP**: إصلاح خطأ `Connection closed` في أداة الاختبار الرجعي على نقل stdio ([#32](https://github.com/HKUDS/Vibe-Trading/pull/32)).
|
||||
- **2026-04-13** 🌐 **اختبار رجعي مركب عبر الأسواق**: محرك `CompositeEngine` جديد يختبر محافظ مختلطة الأسواق (مثل أسهم A + crypto) بمجمع رأس مال مشترك وقواعد لكل سوق. كما أصلح fallback لمتغيرات قالب السرب ومهلة الواجهة.
|
||||
- **2026-04-12** 🌍 **تصدير متعدد المنصات**: يصدر `/pine` الاستراتيجيات إلى TradingView (Pine Script v6)، وTDX (通达信/同花顺/东方财富)، وMetaTrader 5 (MQL5) بأمر واحد.
|
||||
- **2026-04-11** 🛡️ **الموثوقية وتجربة المطور**: إعداد `.env` عبر `vibe-trading init` ([#19](https://github.com/HKUDS/Vibe-Trading/pull/19))، وفحوصات مسبقة، وfallback لمصادر البيانات وقت التشغيل، ومحرك اختبار رجعي معزز. README متعدد اللغات ([#21](https://github.com/HKUDS/Vibe-Trading/pull/21)).
|
||||
- **2026-04-10** 📦 **v0.1.4**: إصلاح Docker ([#8](https://github.com/HKUDS/Vibe-Trading/issues/8))، وأداة MCP `web_search`، و12 مزود LLM، وتبعيات `akshare`/`ccxt`. النشر إلى PyPI وClawHub.
|
||||
- **2026-04-09** 📊 **الموجة الثانية للاختبار الرجعي**: محركات ChinaFutures وGlobalFutures وForex وOptions v2. تحقق Monte Carlo وBootstrap CI وWalk-Forward.
|
||||
- **2026-04-08** 🔧 **اختبار رجعي متعدد الأسواق** مع قواعد لكل سوق، وتصدير Pine Script v6، و5 مصادر بيانات مع fallback تلقائي.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## ✨ الميزات الرئيسية
|
||||
|
||||
<div align="center">
|
||||
<table align="center" width="94%" style="width:94%; margin-left:auto; margin-right:auto;">
|
||||
<tr>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-self-improving-trading-agent.png" height="130" alt="وكيل تداول ذاتي التحسن"/><br>
|
||||
<h3>🔍 وكيل تداول ذاتي التحسن</h3>
|
||||
<div align="left">
|
||||
• بحث سوقي باللغة الطبيعية<br>
|
||||
• مسودات استراتيجيات وتحليل ملفات/ويب<br>
|
||||
• تدفقات عمل مدعومة بالذاكرة
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-multi-agent-trading-teams.png" height="130" alt="فرق تداول متعددة الوكلاء"/><br>
|
||||
<h3>🐝 فرق تداول متعددة الوكلاء</h3>
|
||||
<div align="left">
|
||||
• فرق استثمار وكمّ وكريبتو ومخاطر<br>
|
||||
• تقدم مباشر وتقارير محفوظة<br>
|
||||
• وكلاء مؤسسون على بيانات سوق مجلوبة
|
||||
</div>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-cross-market-data-backtesting.png" height="130" alt="بيانات واختبارات رجعية عبر الأسواق"/><br>
|
||||
<h3>📊 بيانات واختبارات رجعية عبر الأسواق</h3>
|
||||
<div align="left">
|
||||
• أسهم A/HK/US، وكريبتو، وعقود آجلة، وفوركس<br>
|
||||
• fallback للبيانات واختبارات مركبة<br>
|
||||
• بيانات PIT، وتحقيق، وبطاقات تشغيل
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="50%" valign="top">
|
||||
<img src="assets/feature-shadow-account.png" height="130" alt="Shadow Account"/><br>
|
||||
<h3>👥 Shadow Account</h3>
|
||||
<div align="left">
|
||||
• تشخيص سلوكي لسجلات الوسطاء<br>
|
||||
• مقارنات Shadow Account قائمة على القواعد<br>
|
||||
• تقارير تدقيق وكود استراتيجية قابلان للتصدير
|
||||
</div>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
## 💡 ما هو Vibe-Trading؟
|
||||
|
||||
Vibe-Trading مساحة عمل بحثية مفتوحة المصدر تحول الأسئلة المالية إلى تحليل قابل للتشغيل. يربط المطالبات باللغة الطبيعية بمحملات بيانات السوق، وتوليد الاستراتيجيات، ومحركات الاختبار الرجعي، والتقارير، والتصدير، وذاكرة البحث الدائمة.
|
||||
|
||||
صُمم للبحث والمحاكاة والاختبار الرجعي. لا ينفذ صفقات حية.
|
||||
|
||||
---
|
||||
|
||||
## ✨ ما الذي يمكنك فعله؟
|
||||
|
||||
| المهمة | الناتج |
|
||||
|------|--------|
|
||||
| **طرح سؤال تداول** | بحث سوقي باستخدام الأدوات والبيانات والمستندات وسياق جلسة قابل لإعادة الاستخدام. |
|
||||
| **اختبار فكرة استراتيجية رجعياً** | كود استراتيجية، ومقاييس، وسياق معياري، ومخرجات تحقق، وبطاقات تشغيل. |
|
||||
| **مراجعة صفقاتك الخاصة** | قراءة سجلات الوسطاء، وتشخيص السلوك، واستخراج القواعد، ومقارنات Shadow Account. |
|
||||
| **تحسين الأبحاث المتكررة** | الذاكرة الدائمة والمهارات القابلة للتحرير تحول الروتينات المفيدة إلى تدفقات قابلة لإعادة الاستخدام. |
|
||||
| **تشغيل فرق محللين** | مراجعات بحث متعددة الوكلاء لتدفقات الاستثمار والكم والكريبتو والماكرو والمخاطر. |
|
||||
| **إنتاج مخرجات قابلة للاستخدام** | تقارير، وTradingView Pine Script، وTDX، وMetaTrader 5، وأدوات MCP، وجلسات بحث لاحقة. |
|
||||
| **bench ألفا zoo جاهزة** | تشغيل IC + IR + تصنيف alive/reversed/dead عبر 452 ألفا (Qlib 158 + Kakushadze 101 + GTJA 191 + FF5 + Carhart) بسطر أوامر واحد على universe الخاص بك. |
|
||||
|
||||
---
|
||||
|
||||
## ⚡ مثال سريع
|
||||
|
||||
```bash
|
||||
pip install vibe-trading-ai
|
||||
|
||||
# بحث بلغة طبيعية
|
||||
vibe-trading run -p "Backtest a BTC-USDT 20/50 moving-average strategy for 2024, summarize return and drawdown, then export the report"
|
||||
|
||||
# bench لـ alpha zoo جاهز بسطر واحد
|
||||
vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025 --top 20
|
||||
```
|
||||
|
||||
```bash
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Analyze my trading behavior, extract my shadow strategy, and compare it with my actual trades"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 👥 حساب الظل
|
||||
|
||||
ينطلق Shadow Account من سجلات تداولك أنت، لا من قالب استراتيجية عام.
|
||||
|
||||
ارفع تصديراً من وسيطك، ودع الوكيل يلخص سلوكك، ثم قارن مسار التداول الحقيقي باستراتيجية ظل قائمة على قواعد.
|
||||
|
||||
| الخطوة | ناتج الوكيل |
|
||||
|------|--------------|
|
||||
| **1. قراءة سجلك** | يقرأ صادرات الوسطاء من 同花顺 و东方财富 و富途 وصيغ CSV العامة. |
|
||||
| **2. بناء ملف سلوكك** | أيام الاحتفاظ، ومعدل الربح، ونسبة PnL، والتراجع، وdisposition effect، والإفراط في التداول، ومطاردة الزخم، وفحوصات anchoring. |
|
||||
| **3. استخراج قواعدك** | يحول أنماط الدخول/الخروج المتكررة إلى ملف استراتيجية صريح بدلاً من ملخص ضبابي. |
|
||||
| **4. تشغيل الظل** | يختبر القواعد المستخرجة رجعياً ويبرز خرق القواعد، والخروج المبكر، والإشارات الفائتة، ومسارات التداول البديلة. |
|
||||
| **5. تسليم التقرير** | ينتج تقرير HTML/PDF يمكن فحصه أو أرشفته أو تحسينه في جلسة لاحقة. |
|
||||
|
||||
```bash
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Analyze my trading behavior, extract my shadow strategy, and compare it with my actual trades"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 🧪 سير البحث
|
||||
|
||||
تتبع أغلب التشغيلات مسار أدلة واحداً: توجيه الطلب، تحميل سياق السوق المناسب، تنفيذ الأدوات، التحقق من المخرجات، وإبقاء المخرجات قابلة للفحص.
|
||||
|
||||
| الطبقة | ما يحدث |
|
||||
|-------|--------------|
|
||||
| **Plan** | يختار المهارات المالية والأدوات ومصادر البيانات وإعداد السرب الملائمة عند الحاجة. |
|
||||
| **Ground** | يجلب أسهم A، وأسهم HK/US، والكريبتو، والعقود الآجلة، والفوركس، والمستندات، أو سياق الويب عبر المحملات المتاحة. |
|
||||
| **Execute** | يولد كود استراتيجية قابل للاختبار، ويشغل الأدوات، ويستخدم محرك الاختبار الرجعي أو سير التحليل المناسب. |
|
||||
| **Validate** | يضيف المقاييس، والمقارنة المعيارية، وMonte Carlo، وBootstrap، وWalk-Forward، وبطاقات التشغيل، والتحذيرات عند اللزوم. |
|
||||
| **Deliver** | يعيد التقارير والمخرجات وآثار الأدوات والتصديرات إلى TradingView وTDX وMetaTrader 5 وعملاء MCP أو جلسات لاحقة. |
|
||||
|
||||
---
|
||||
|
||||
## 🔩 القدرات التفصيلية
|
||||
|
||||
القوائم التفصيلية مطوية أدناه حتى يبقى README سهل القراءة. افتحها عندما تريد فحص اللبنات المتاحة.
|
||||
|
||||
<details>
|
||||
<summary><b>مكتبة المهارات المالية</b> <sub>75 مهارة عبر 8 فئات</sub></summary>
|
||||
|
||||
- 📊 75 مهارة مالية متخصصة منظمة في 8 فئات
|
||||
- 🌐 تغطية كاملة من الأسواق التقليدية إلى الكريبتو وDeFi
|
||||
- 🔬 قدرات شاملة من مصادر البيانات إلى البحث الكمي
|
||||
|
||||
| الفئة | المهارات | أمثلة |
|
||||
|----------|--------|----------|
|
||||
| Data Source | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| Strategy | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 17 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis`, `dividend-analysis` |
|
||||
| Asset Class | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| Crypto | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
| Flow | 7 | `hk-connect-flow`, `us-etf-flow`, `edgar-sec-filings`, `financial-statement`, `adr-hshare` |
|
||||
| Tool | 11 | `backtest-diagnose`, `report-generate`, `pine-script`, `doc-reader`, `web-reader`, `vnpy-export`, `alpha-zoo` |
|
||||
| Risk Analysis | 1 | `ashare-pre-st-filter` |
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>فرق تداول جاهزة</b> <sub>29 إعداد سرب مسبق</sub></summary>
|
||||
|
||||
- 🏢 29 فريق وكلاء جاهزاً للاستخدام
|
||||
- ⚡ تدفقات مالية مهيأة مسبقاً
|
||||
- 🎯 إعدادات للاستثمار والتداول وإدارة المخاطر
|
||||
|
||||
| الإعداد | سير العمل |
|
||||
|--------|----------|
|
||||
| `investment_committee` | مناظرة صعود/هبوط → مراجعة مخاطر → قرار مدير المحفظة النهائي |
|
||||
| `global_equities_desk` | باحث أسهم A + HK/US + كريبتو → استراتيجي عالمي |
|
||||
| `crypto_trading_desk` | تمويل/أساس + تصفية + تدفق → مدير مخاطر |
|
||||
| `earnings_research_desk` | أساسيات + مراجعات + خيارات → استراتيجي أرباح |
|
||||
| `macro_rates_fx_desk` | أسعار فائدة + FX + سلع → مدير محفظة ماكرو |
|
||||
| `quant_strategy_desk` | فرز + بحث عوامل → اختبار رجعي → تدقيق مخاطر |
|
||||
| `technical_analysis_panel` | TA كلاسيكي + Ichimoku + harmonic + Elliott + SMC → إجماع |
|
||||
| `risk_committee` | تراجع + مخاطر ذيل + مراجعة نظام → اعتماد |
|
||||
| `global_allocation_committee` | أسهم A + كريبتو + HK/US → تخصيص عبر الأسواق |
|
||||
|
||||
<sub>بالإضافة إلى أكثر من 20 إعداداً متخصصاً آخر — شغل vibe-trading --swarm-presets لاستكشافها كلها.
|
||||
|
||||
</sub>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Alpha Zoo</b> <sub>452 ألفا كمّي جاهز عبر 4 zoos</sub></summary>
|
||||
|
||||
- 🧬 452 ألفا cross-sectional، مع منع lookahead على طبقة العوامل (operators)
|
||||
- 📈 IC + IR + تصنيف alive/reversed/dead بأمر CLI واحد
|
||||
- 🔬 بوابة نقاء AST + اختبار حماية lookahead بـ 300 صف + قاطع شبكة عبر `pytest-socket`
|
||||
- 📦 إسناد Apache-2 لـ Qlib؛ ملف `LICENSE.md` لكل zoo يصرّح بأن الصيغ محتوى رياضي
|
||||
- 🤝 سير عمل توقيع Developer Certificate of Origin (DCO) لمساهمات المجتمع
|
||||
|
||||
| Zoo | العدد | المصدر | الرخصة |
|
||||
|-----|-------|--------|--------|
|
||||
| **qlib158** | 154 | Microsoft Qlib `Alpha158` (Apache-2.0، مثبّت على commit) | Apache-2.0 |
|
||||
| **alpha101** | 101 | Kakushadze (2015)، "101 Formulaic Alphas"، arXiv:1601.00991 | الصيغ محتوى رياضي |
|
||||
| **gtja191** | 191 | Guotai Junan (2014)، "191 Short-period Trading Alpha Factors" | الصيغ محتوى رياضي |
|
||||
| **academic** | 6 | Fama-French 5 + Carhart momentum (proxy قائم على الأسعار) | أدبيات أكاديمية عامة |
|
||||
|
||||
شغّل `vibe-trading alpha list` للتصفح، و`vibe-trading alpha show <id>` للحصول على الصيغ + المصدر، و`vibe-trading alpha bench --zoo X --universe Y --period Z` لتقييم zoo كاملة.
|
||||
|
||||
</details>
|
||||
|
||||
## 🎬 العرض التوضيحي
|
||||
|
||||
<div align="center">
|
||||
<table>
|
||||
<tr>
|
||||
<td width="50%">
|
||||
|
||||
https://github.com/user-attachments/assets/4e4dcb80-7358-4b9a-92f0-1e29612e6e86
|
||||
|
||||
</td>
|
||||
<td width="50%">
|
||||
|
||||
https://github.com/user-attachments/assets/3754a414-c3ee-464f-b1e8-78e1a74fbd30
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td colspan="2" align="center"><sub>☝️ اختبار رجعي باللغة الطبيعية ومناظرة سرب متعدد الوكلاء — Web UI + CLI</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 🚀 البدء السريع
|
||||
|
||||
### تثبيت بسطر واحد (PyPI)
|
||||
|
||||
```bash
|
||||
pip install vibe-trading-ai
|
||||
```
|
||||
|
||||
ثم شغل أول مهمة بحثية:
|
||||
|
||||
```bash
|
||||
vibe-trading init
|
||||
vibe-trading run -p "Backtest a BTC-USDT 20/50 moving-average strategy for 2024 and summarize return and drawdown"
|
||||
```
|
||||
|
||||
> **اسم الحزمة مقابل الأوامر:** حزمة PyPI هي `vibe-trading-ai`. بعد التثبيت تحصل على ثلاثة أوامر:
|
||||
>
|
||||
> | الأمر | الغرض |
|
||||
> |---------|---------|
|
||||
> | `vibe-trading` | CLI / TUI تفاعلي |
|
||||
> | `vibe-trading serve` | تشغيل خادم ويب FastAPI |
|
||||
> | `vibe-trading-mcp` | بدء خادم MCP (لـ Claude Desktop وOpenClaw وCursor وغيرها) |
|
||||
|
||||
```bash
|
||||
vibe-trading init # interactive .env setup
|
||||
vibe-trading # launch CLI
|
||||
vibe-trading serve --port 8899 # launch web UI
|
||||
vibe-trading-mcp # start MCP server (stdio)
|
||||
```
|
||||
|
||||
### أو اختر مساراً
|
||||
|
||||
| المسار | الأنسب لـ | الوقت |
|
||||
|------|----------|------|
|
||||
| **A. Docker** | التجربة الآن، دون إعداد محلي | دقيقتان |
|
||||
| **B. تثبيت محلي** | التطوير والوصول الكامل إلى CLI | 5 دقائق |
|
||||
| **C. MCP plugin** | وصله بوكيلك الحالي | 3 دقائق |
|
||||
| **D. ClawHub** | أمر واحد دون استنساخ | دقيقة واحدة |
|
||||
|
||||
### المتطلبات المسبقة
|
||||
|
||||
- **مفتاح API لنموذج LLM** من أي مزود مدعوم — أو التشغيل محلياً عبر **Ollama** (لا يحتاج مفتاحاً)
|
||||
- **Python 3.11+** للمسار B
|
||||
- **Docker** للمسار A
|
||||
- يمكن استخدام OpenAI Codex أيضاً عبر ChatGPT OAuth: اضبط `LANGCHAIN_PROVIDER=openai-codex`، ثم شغل `vibe-trading provider login openai-codex`. هذا لا يستخدم `OPENAI_API_KEY`.
|
||||
|
||||
> **مزودو LLM المدعومون:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Z.ai, Ollama (local). راجع `.env.example` للإعداد.
|
||||
|
||||
> **نصيحة:** تعمل كل الأسواق دون مفاتيح API بفضل fallback التلقائي. yfinance (HK/US)، وOKX (crypto)، وAKShare (A-shares, US, HK, futures, forex) مجانية. رمز Tushare اختياري، إذ يغطي AKShare أسهم A كبديل مجاني.
|
||||
|
||||
### المسار A: Docker (دون إعداد)
|
||||
|
||||
```bash
|
||||
git clone https://github.com/HKUDS/Vibe-Trading.git
|
||||
cd Vibe-Trading
|
||||
cp agent/.env.example agent/.env
|
||||
# Edit agent/.env — uncomment your LLM provider and set API key
|
||||
docker compose up --build
|
||||
```
|
||||
|
||||
افتح `http://localhost:8899`. الخلفية والواجهة الأمامية داخل حاوية واحدة.
|
||||
|
||||
ينشر Docker الخلفية على `127.0.0.1:8899` افتراضياً ويشغل التطبيق كمستخدم حاوية غير root. إذا كنت تقصد تعريض API خارج جهازك، فاضبط `API_AUTH_KEY` قوياً وأرسل `Authorization: Bearer <key>` من العملاء.
|
||||
|
||||
### المسار B: التثبيت المحلي
|
||||
|
||||
```bash
|
||||
git clone https://github.com/HKUDS/Vibe-Trading.git
|
||||
cd Vibe-Trading
|
||||
python -m venv .venv
|
||||
|
||||
# Activate
|
||||
source .venv/bin/activate # Linux / macOS
|
||||
# .venv\Scripts\Activate.ps1 # Windows PowerShell
|
||||
|
||||
pip install -e .
|
||||
cp agent/.env.example agent/.env # Edit — set your LLM provider API key
|
||||
vibe-trading # Launch interactive TUI
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary><b>تشغيل واجهة الويب (اختياري)</b></summary>
|
||||
|
||||
```bash
|
||||
# Terminal 1: API server
|
||||
vibe-trading serve --port 8899
|
||||
|
||||
# Terminal 2: Frontend dev server
|
||||
cd frontend && npm install && npm run dev
|
||||
```
|
||||
|
||||
افتح `http://localhost:5899`. تمرر الواجهة الأمامية استدعاءات API إلى `localhost:8899`.
|
||||
|
||||
**وضع الإنتاج (خادم واحد):**
|
||||
|
||||
```bash
|
||||
cd frontend && npm run build && cd ..
|
||||
vibe-trading serve --port 8899 # FastAPI serves dist/ as static files
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### المسار C: MCP plugin
|
||||
|
||||
راجع قسم [MCP Plugin](#-mcp-plugin) أدناه.
|
||||
|
||||
### المسار D: ClawHub (أمر واحد)
|
||||
|
||||
```bash
|
||||
npx clawhub@latest install vibe-trading --force
|
||||
```
|
||||
|
||||
تُنزل المهارة وإعداد MCP إلى مجلد مهارات وكيلك. راجع [تثبيت ClawHub](#-mcp-plugin) للتفاصيل.
|
||||
|
||||
---
|
||||
|
||||
## 🧠 متغيرات البيئة
|
||||
|
||||
انسخ `agent/.env.example` إلى `agent/.env` وأزل التعليق عن كتلة المزود التي تريدها. يحتاج كل مزود إلى 3-4 متغيرات:
|
||||
|
||||
| المتغير | مطلوب | الوصف |
|
||||
|----------|:--------:|-------------|
|
||||
| `LANGCHAIN_PROVIDER` | نعم | اسم المزود (`openrouter`, `deepseek`, `groq`, `ollama`, إلخ) |
|
||||
| `<PROVIDER>_API_KEY` | نعم* | مفتاح API (`OPENROUTER_API_KEY`, `DEEPSEEK_API_KEY`, إلخ) |
|
||||
| `<PROVIDER>_BASE_URL` | نعم | عنوان URL لنقطة نهاية API |
|
||||
| `LANGCHAIN_MODEL_NAME` | نعم | اسم النموذج (مثل `deepseek-v4-pro`) |
|
||||
| `TUSHARE_TOKEN` | لا | رمز Tushare Pro لبيانات أسهم A (يرجع إلى AKShare عند الحاجة) |
|
||||
| `TIMEOUT_SECONDS` | لا | مهلة استدعاء LLM، الافتراضي 120s |
|
||||
| `API_AUTH_KEY` | موصى به للنشر الشبكي | Bearer token مطلوب عندما يكون API قابلاً للوصول من عملاء غير محليين |
|
||||
| `VIBE_TRADING_ENABLE_SHELL_TOOLS` | لا | تفعيل صريح للأدوات القادرة على shell في نشر API/MCP-SSE البعيد |
|
||||
| `VIBE_TRADING_ALLOWED_FILE_ROOTS` | لا | جذور إضافية مفصولة بفواصل لاستيراد المستندات وسجلات الوسطاء |
|
||||
| `VIBE_TRADING_ALLOWED_RUN_ROOTS` | لا | جذور إضافية مفصولة بفواصل لأدلة تشغيل الكود المولد |
|
||||
|
||||
<sub>* لا يحتاج Ollama إلى مفتاح API. يستخدم OpenAI Codex ChatGPT OAuth ويخزن الرموز عبر `oauth-cli-kit`، لا داخل `agent/.env`.</sub>
|
||||
|
||||
**بيانات مجانية (دون مفتاح):** أسهم A عبر AKShare، وأسهم HK/US عبر yfinance، والكريبتو عبر OKX، وأكثر من 100 بورصة كريبتو عبر CCXT. يختار النظام تلقائياً أفضل مصدر متاح لكل سوق.
|
||||
|
||||
### 🎯 النماذج الموصى بها
|
||||
|
||||
Vibe-Trading وكيل كثيف الأدوات؛ المهارات والاختبارات الرجعية والذاكرة والأسراب كلها تمر عبر استدعاءات أدوات. اختيار النموذج يحدد مباشرة هل سيستخدم الوكيل أدواته أم سيصطنع إجابات من بيانات التدريب.
|
||||
|
||||
| المستوى | أمثلة | متى تستخدمه |
|
||||
|------|----------|-------------|
|
||||
| **الأفضل** | `anthropic/claude-opus-4.7`, `anthropic/claude-sonnet-4.6`, `openai/gpt-5.4`, `google/gemini-3.1-pro-preview` | أسراب معقدة (3+ وكلاء)، جلسات بحث طويلة، تحليل بمستوى ورقة علمية |
|
||||
| **النقطة المثلى** (افتراضي) | `deepseek-v4-pro`, `deepseek/deepseek-v4-pro`, `x-ai/grok-4.20`, `z-ai/glm-5.1`, `moonshotai/kimi-k2.5`, `qwen/qwen3-max-thinking` | الاستخدام اليومي، tool-calling موثوق بنحو عُشر التكلفة |
|
||||
| **تجنبها لاستخدام الوكيل** | `*-nano`, `*-flash-lite`, `*-coder-next`, small / distilled variants | tool-calling غير موثوق؛ سيبدو الوكيل وكأنه "يجيب من الذاكرة" بدلاً من تحميل المهارات أو تشغيل الاختبارات الرجعية |
|
||||
|
||||
يأتي `agent/.env.example` افتراضياً مع DeepSeek official API + `deepseek-v4-pro`; ويمكن لمستخدمي OpenRouter استخدام `deepseek/deepseek-v4-pro`.
|
||||
|
||||
---
|
||||
|
||||
## 🖥 مرجع CLI
|
||||
|
||||
```bash
|
||||
vibe-trading # interactive TUI
|
||||
vibe-trading run -p "..." # single run
|
||||
vibe-trading serve # API server
|
||||
vibe-trading alpha list # استعرض 452 ألفا جاهز؛ متاح show / bench / compare / export-manifest
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary><b>أوامر الشرطة المائلة داخل TUI</b></summary>
|
||||
|
||||
| الأمر | الوصف |
|
||||
|---------|-------------|
|
||||
| `/help` | عرض كل الأوامر |
|
||||
| `/skills` | عرض كل المهارات المالية الـ 75 |
|
||||
| `/swarm` | عرض إعدادات فرق السرب الـ 29 |
|
||||
| `/swarm run <preset> [vars_json]` | تشغيل فريق سرب مع بث مباشر |
|
||||
| `/swarm list` | سجل تشغيلات السرب |
|
||||
| `/swarm show <run_id>` | تفاصيل تشغيل السرب |
|
||||
| `/swarm cancel <run_id>` | إلغاء سرب قيد التشغيل |
|
||||
| `/list` | التشغيلات الأخيرة |
|
||||
| `/show <run_id>` | تفاصيل التشغيل + المقاييس |
|
||||
| `/code <run_id>` | كود الاستراتيجية المولدة |
|
||||
| `/pine <run_id>` | تصدير المؤشرات (TradingView + TDX + MT5) |
|
||||
| `/trace <run_id>` | إعادة تشغيل التنفيذ كاملة |
|
||||
| `/continue <run_id> <prompt>` | متابعة تشغيل بتعليمات جديدة |
|
||||
| `/sessions` | عرض جلسات الدردشة |
|
||||
| `/settings` | عرض إعدادات التشغيل |
|
||||
| `/clear` | مسح الشاشة |
|
||||
| `/quit` | خروج |
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>تشغيل واحد والخيارات</b></summary>
|
||||
|
||||
```bash
|
||||
vibe-trading run -p "Backtest BTC-USDT MACD strategy, last 30 days"
|
||||
vibe-trading run -p "Analyze AAPL momentum" --json
|
||||
vibe-trading run -f strategy.txt
|
||||
echo "Backtest 000001.SZ RSI" | vibe-trading run
|
||||
```
|
||||
|
||||
```bash
|
||||
vibe-trading -p "your prompt"
|
||||
vibe-trading --skills
|
||||
vibe-trading --swarm-presets
|
||||
vibe-trading --swarm-run investment_committee '{"topic":"BTC outlook"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # Export indicators (TradingView + TDX + MT5)
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "refine the strategy"
|
||||
vibe-trading --upload report.pdf
|
||||
```
|
||||
|
||||
```bash
|
||||
vibe-trading alpha list --zoo gtja191 --limit 10
|
||||
vibe-trading alpha show gtja191_171
|
||||
vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025 --top 20
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 💡 أمثلة
|
||||
|
||||
### الاستراتيجيات والاختبار الرجعي
|
||||
|
||||
```bash
|
||||
# Moving average crossover on US equities
|
||||
vibe-trading run -p "Backtest a 20/50-day moving average crossover on AAPL for the past year, show Sharpe ratio and max drawdown"
|
||||
|
||||
# RSI mean-reversion on crypto
|
||||
vibe-trading run -p "Test RSI(14) mean-reversion on BTC-USDT: buy below 30, sell above 70, last 6 months"
|
||||
|
||||
# Multi-factor strategy on A-shares
|
||||
vibe-trading run -p "Backtest a momentum + value + quality multi-factor strategy on CSI 300 constituents over 2 years"
|
||||
|
||||
# After backtesting, export to TradingView / TDX / MetaTrader 5
|
||||
vibe-trading --pine <run_id>
|
||||
```
|
||||
|
||||
**bench ألفا zoo جاهز بسطر واحد**:
|
||||
```bash
|
||||
vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025 --top 20
|
||||
```
|
||||
|
||||
**استعرض الكتالوج** وافحص ألفا مفردة:
|
||||
```bash
|
||||
vibe-trading alpha list --zoo gtja191 --theme reversal --limit 10
|
||||
vibe-trading alpha show gtja191_171
|
||||
```
|
||||
|
||||
**ركّب إشارة متعدد العوامل** من ألفات zoo (Python):
|
||||
```python
|
||||
from src.skills.multi_factor.zoo_signal_engine import ZooSignalEngine
|
||||
engine = ZooSignalEngine.from_zoo(["gtja191_171", "gtja191_111", "gtja191_163"])
|
||||
panel = ... # your wide OHLCV panel
|
||||
signal = engine.compute_signal(panel)
|
||||
```
|
||||
|
||||
### بحث السوق
|
||||
|
||||
```bash
|
||||
# Equity deep-dive
|
||||
vibe-trading run -p "Research NVDA: earnings trend, analyst consensus, option flow, and key risks for next quarter"
|
||||
|
||||
# Macro analysis
|
||||
vibe-trading run -p "Analyze the current Fed rate path, USD strength, and impact on EM equities and gold"
|
||||
|
||||
# Crypto on-chain
|
||||
vibe-trading run -p "Deep dive BTC on-chain: whale flows, exchange balances, miner activity, and funding rates"
|
||||
```
|
||||
|
||||
### تدفقات السرب
|
||||
|
||||
```bash
|
||||
# Bull/bear debate on a stock
|
||||
vibe-trading --swarm-run investment_committee '{"topic": "Is TSLA a buy at current levels?"}'
|
||||
|
||||
# Quant strategy from screening to backtest
|
||||
vibe-trading --swarm-run quant_strategy_desk '{"universe": "S&P 500", "horizon": "3 months"}'
|
||||
|
||||
# Crypto desk: funding + liquidation + flow → risk manager
|
||||
vibe-trading --swarm-run crypto_trading_desk '{"asset": "ETH-USDT", "timeframe": "1w"}'
|
||||
|
||||
# Global macro portfolio allocation
|
||||
vibe-trading --swarm-run macro_rates_fx_desk '{"focus": "Fed pivot impact on EM bonds"}'
|
||||
```
|
||||
|
||||
### ذاكرة عبر الجلسات
|
||||
|
||||
```bash
|
||||
# Save your preferences once
|
||||
vibe-trading run -p "Remember: I prefer RSI-based strategies, max 10% drawdown, hold period 5–20 days"
|
||||
|
||||
# The agent recalls them in future sessions automatically
|
||||
vibe-trading run -p "Build a crypto strategy that fits my risk profile"
|
||||
```
|
||||
|
||||
### رفع المستندات وتحليلها
|
||||
|
||||
```bash
|
||||
# Analyze a broker export or earnings report
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Profile my trading behavior and identify any biases"
|
||||
|
||||
vibe-trading --upload NVDA_Q1_earnings.pdf
|
||||
vibe-trading run -p "Summarize the key risks and beats/misses from this earnings report"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 🌐 خادم API
|
||||
|
||||
```bash
|
||||
vibe-trading serve --port 8899
|
||||
```
|
||||
|
||||
| الطريقة | نقطة النهاية | الوصف |
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | عرض التشغيلات |
|
||||
| `GET` | `/runs/{run_id}` | تفاصيل التشغيل |
|
||||
| `GET` | `/runs/{run_id}/pine` | تصدير مؤشرات متعدد المنصات |
|
||||
| `POST` | `/sessions` | إنشاء جلسة |
|
||||
| `POST` | `/sessions/{id}/messages` | إرسال رسالة |
|
||||
| `GET` | `/sessions/{id}/events` | بث أحداث SSE |
|
||||
| `POST` | `/upload` | رفع PDF/ملف |
|
||||
| `GET` | `/swarm/presets` | عرض إعدادات السرب |
|
||||
| `POST` | `/swarm/runs` | بدء تشغيل سرب |
|
||||
| `GET` | `/swarm/runs/{id}/events` | بث SSE للسرب |
|
||||
| `GET` | `/alpha/list` | قائمة ألفات مع تصفية حسب zoo/theme/universe |
|
||||
| `GET` | `/alpha/{alpha_id}` | بيانات وصفية + الكود المصدري للألفا |
|
||||
| `POST` | `/alpha/bench` | بدء مهمة bench (يعيد `job_id`) |
|
||||
| `GET` | `/alpha/bench/{job_id}/stream` | تدفق تقدّم SSE |
|
||||
| `GET` | `/settings/llm` | قراءة إعدادات LLM في Web UI |
|
||||
| `PUT` | `/settings/llm` | تحديث إعدادات LLM المحلية |
|
||||
| `GET` | `/settings/data-sources` | قراءة إعدادات مصادر البيانات المحلية |
|
||||
| `PUT` | `/settings/data-sources` | تحديث إعدادات مصادر البيانات المحلية |
|
||||
|
||||
توثيق تفاعلي: `http://localhost:8899/docs`
|
||||
|
||||
### الإعدادات الأمنية الافتراضية
|
||||
|
||||
للتطوير على localhost، يبقي `vibe-trading serve` سير المتصفح بسيطاً. لأي عميل غير محلي، تتطلب نقاط API الحساسة `API_AUTH_KEY`؛ استخدم `Authorization: Bearer <key>` لطلبات JSON/الرفع. تتعامل Web UI مع تدفقات Browser EventSource بعد إدخال المفتاح نفسه مرة واحدة في Settings.
|
||||
|
||||
تتوفر الأدوات القادرة على shell للـ CLI المحلي وتدفقات localhost الموثوقة، لكنها لا تُعرض لجلسات API البعيدة ما لم تضبط صراحة `VIBE_TRADING_ENABLE_SHELL_TOOLS=1`. قارئات المستندات والسجلات محدودة افتراضياً بجذور الرفع/الاستيراد؛ ضع الملفات تحت `agent/uploads` أو `agent/runs` أو `./uploads` أو `./data` أو `~/.vibe-trading/uploads` أو `~/.vibe-trading/imports`، أو أضف دليلاً مخصصاً عبر `VIBE_TRADING_ALLOWED_FILE_ROOTS`.
|
||||
|
||||
### إعدادات Web UI
|
||||
|
||||
تتيح صفحة Settings في Web UI للمستخدمين المحليين تحديث مزود/نموذج LLM، وbase URL، ومعلمات التوليد، وreasoning effort، وبيانات اعتماد السوق الاختيارية مثل رمز Tushare. تُحفظ الإعدادات في `agent/.env`؛ وتُحمّل قيم المزودين الافتراضية من `agent/src/providers/llm_providers.json`.
|
||||
|
||||
قراءات Settings بلا آثار جانبية: لا تنشئ `GET /settings/llm` ولا `GET /settings/data-sources` ملف `agent/.env`، ولا تعيدان إلا مسارات نسبية للمشروع. قد تكشف قراءات وكتابات Settings حالة بيانات الاعتماد أو تحدث بيانات الاعتماد/بيئة التشغيل، لذلك تتطلب `API_AUTH_KEY` عند ضبطه. إذا كان `API_AUTH_KEY` غير مضبوط في وضع التطوير، فلا يقبل الوصول إلى Settings إلا من عملاء loopback.
|
||||
|
||||
---
|
||||
|
||||
## 🔌 MCP Plugin
|
||||
|
||||
يعرض Vibe-Trading 22 أداة MCP لأي عميل متوافق مع MCP. يعمل كعملية stdio فرعية، دون إعداد خادم. **21 من أصل 22 أداة تعمل دون أي مفاتيح API** (HK/US/crypto). يحتاج `run_swarm` وحده إلى مفتاح LLM.
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
|
||||
أضف إلى `claude_desktop_config.json`:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"vibe-trading": {
|
||||
"command": "vibe-trading-mcp"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>OpenClaw</b></summary>
|
||||
|
||||
أضف إلى `~/.openclaw/config.yaml`:
|
||||
|
||||
```yaml
|
||||
skills:
|
||||
- name: vibe-trading
|
||||
command: vibe-trading-mcp
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Cursor / Windsurf / عملاء MCP آخرون</b></summary>
|
||||
|
||||
```bash
|
||||
vibe-trading-mcp # stdio (default)
|
||||
vibe-trading-mcp --transport sse # SSE for web clients
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
**أدوات MCP المعروضة (22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
|
||||
<details>
|
||||
<summary><b>التثبيت من ClawHub (أمر واحد)</b></summary>
|
||||
|
||||
```bash
|
||||
npx clawhub@latest install vibe-trading --force
|
||||
```
|
||||
|
||||
> `--force` مطلوب لأن المهارة تشير إلى واجهات API خارجية، مما يطلق فحص VirusTotal الآلي. الكود مفتوح المصدر بالكامل وآمن للفحص.
|
||||
|
||||
ينزل هذا المهارة وإعداد MCP إلى مجلد مهارات وكيلك. لا حاجة للاستنساخ.
|
||||
|
||||
تصفح على ClawHub: [clawhub.ai/skills/vibe-trading](https://clawhub.ai/skills/vibe-trading)
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>OpenSpace — مهارات ذاتية التطور</b></summary>
|
||||
|
||||
كل المهارات المالية الـ 75 منشورة على [open-space.cloud](https://open-space.cloud) وتتطور ذاتياً عبر محرك التطور الذاتي في OpenSpace.
|
||||
|
||||
للاستخدام مع OpenSpace، أضف خادمي MCP إلى إعداد وكيلك:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"openspace": {
|
||||
"command": "openspace-mcp",
|
||||
"toolTimeout": 600,
|
||||
"env": {
|
||||
"OPENSPACE_HOST_SKILL_DIRS": "/path/to/vibe-trading/agent/src/skills",
|
||||
"OPENSPACE_WORKSPACE": "/path/to/OpenSpace"
|
||||
}
|
||||
},
|
||||
"vibe-trading": {
|
||||
"command": "vibe-trading-mcp"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
سيكتشف OpenSpace كل المهارات الـ 75 تلقائياً، مما يتيح auto-fix وauto-improve والمشاركة المجتمعية. ابحث عن مهارات Vibe-Trading عبر `search_skills("finance backtest")` في أي وكيل متصل بـ OpenSpace.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 📁 هيكل المشروع
|
||||
|
||||
<details>
|
||||
<summary><b>انقر للتوسيع</b></summary>
|
||||
|
||||
```
|
||||
Vibe-Trading/
|
||||
├── agent/ # Backend (Python)
|
||||
│ ├── cli.py # CLI entrypoint — interactive TUI + subcommands
|
||||
│ ├── api_server.py # FastAPI server — runs, sessions, upload, swarm, SSE
|
||||
│ ├── mcp_server.py # MCP server — 22 tools for OpenClaw / Claude Desktop
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # ReAct agent core
|
||||
│ │ │ ├── loop.py # 5-layer compression + read/write tool batching
|
||||
│ │ │ ├── context.py # system prompt + auto-recall from persistent memory
|
||||
│ │ │ ├── skills.py # skill loader (75 bundled + user-created via CRUD)
|
||||
│ │ │ ├── tools.py # tool base class + registry
|
||||
│ │ │ ├── memory.py # lightweight workspace state per run
|
||||
│ │ │ ├── frontmatter.py # shared YAML frontmatter parser
|
||||
│ │ │ └── trace.py # execution trace writer
|
||||
│ │ │
|
||||
│ │ ├── memory/ # Cross-session persistent memory
|
||||
│ │ │ └── persistent.py # file-based memory (~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 31 auto-discovered agent tools
|
||||
│ │ │ ├── backtest_tool.py # run backtests
|
||||
│ │ │ ├── remember_tool.py # cross-session memory (save/recall/forget)
|
||||
│ │ │ ├── skill_writer_tool.py # skill CRUD (save/patch/delete/file)
|
||||
│ │ │ ├── session_search_tool.py # FTS5 cross-session search
|
||||
│ │ │ ├── swarm_tool.py # launch swarm teams
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo web search
|
||||
│ │ │ └── ... # bash, file I/O, factor analysis, options, alpha browser + bench, etc.
|
||||
│ │ │
|
||||
│ │ ├── factors/ # Alpha Zoo — 452 ألفا عبر 4 zoos
|
||||
│ │ │ ├── base.py # 19 عاملاً (rank/scale/ts_*/delta/decay_linear/safe_div/vwap)
|
||||
│ │ │ ├── registry.py # تحميل بيانات وصفية AST فقط + حساب كسول + بوابات سلامة
|
||||
│ │ │ ├── bench_runner.py # IC + تصنيف alive/reversed/dead
|
||||
│ │ │ └── zoo/ # qlib158 (154) + alpha101 (101) + gtja191 (191) + academic (6)
|
||||
│ │ │
|
||||
│ │ ├── api/ # وحدات مسارات FastAPI
|
||||
│ │ │ └── alpha_routes.py # /alpha/list, /alpha/{id}, /alpha/bench, SSE stream
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 75 finance skills in 8 categories (SKILL.md each)
|
||||
│ │ ├── swarm/ # Swarm DAG execution engine
|
||||
│ │ │ └── presets/ # 29 swarm preset YAML definitions
|
||||
│ │ ├── session/ # Multi-turn chat + FTS5 session search
|
||||
│ │ └── providers/ # LLM provider abstraction
|
||||
│ │
|
||||
│ └── backtest/ # Backtest engines
|
||||
│ ├── engines/ # 7 engines + composite cross-market engine + options_portfolio
|
||||
│ ├── loaders/ # 6 sources: tushare, okx, yfinance, akshare, ccxt, futu
|
||||
│ │ ├── base.py # DataLoader Protocol
|
||||
│ │ └── registry.py # Registry + auto-fallback chains
|
||||
│ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│
|
||||
├── frontend/ # Web UI (React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
│ ├── pages/ # Home, Agent, AlphaZoo, RunDetail, Compare, Correlation, Settings
|
||||
│ ├── components/ # chat, charts, layout
|
||||
│ └── stores/ # Zustand state management
|
||||
│
|
||||
├── Dockerfile # Multi-stage build
|
||||
├── docker-compose.yml # One-command deploy
|
||||
├── pyproject.toml # Package config + CLI entrypoint
|
||||
├── tools/ # Repo-level CI helpers
|
||||
│ └── ci_grep_gates.sh # rejects yaml.load / trademark / per-stock-data leaks
|
||||
└── LICENSE # MIT
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 🏛 النظام البيئي
|
||||
|
||||
Vibe-Trading جزء من نظام وكلاء **[HKUDS](https://github.com/HKUDS)**:
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/ClawTeam"><b>ClawTeam</b></a><br>
|
||||
<sub>Agent Swarm Intelligence</sub>
|
||||
</td>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/nanobot"><b>NanoBot</b></a><br>
|
||||
<sub>Ultra-Lightweight Personal AI Assistant</sub>
|
||||
</td>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/CLI-Anything"><b>CLI-Anything</b></a><br>
|
||||
<sub>Making All Software Agent-Native</sub>
|
||||
</td>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/OpenSpace"><b>OpenSpace</b></a><br>
|
||||
<sub>Self-Evolving AI Agent Skills</sub>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
---
|
||||
|
||||
## 🗺 خارطة الطريق
|
||||
|
||||
> نشحن على مراحل. تنتقل العناصر إلى [Issues](https://github.com/HKUDS/Vibe-Trading/issues) عندما يبدأ العمل.
|
||||
|
||||
| المرحلة | الميزة | الحالة |
|
||||
|-------|---------|--------|
|
||||
| **Trust Layer** | بطاقات تشغيل قابلة لإعادة الإنتاج تُنتج وتظهر في Run Detail؛ يضيف v1 آثار الأدوات والاستشهادات | v0 شُحن |
|
||||
| **Hypothesis Registry** | فرضيات بحثية دائمة مع حالة lifecycle ومصادر بيانات ومهارات وروابط run-card وملاحظات إبطال | Backend MVP شُحن |
|
||||
| **Research Autopilot** | حلقة بحث يدوية أولاً: فرضية → اختبار رجعي حتمي → تقرير أدلة | التالي |
|
||||
| **Data Bridge** | أحضر بياناتك: موصلات CSV/Parquet/SQL محلية مع schema mapping | مخطط |
|
||||
| **Options Lab** | سطح تقلب، ولوحة Greeks، ومستكشف payoff/scenario | مخطط |
|
||||
| **Portfolio Studio** | أشعة مخاطر، وقيود، ومحسن يراعي الدوران، وملاحظات إعادة توازن | مخطط |
|
||||
| **Alpha Zoo** | 452 ألفا كمّي جاهز عبر 4 zoos (Qlib 158 + Kakushadze 101 + GTJA 191 + FF5 + Carhart)، سطر أوامر واحد للـ bench، تكامل agent، وواجهة Web | **تم الإطلاق 0.1.8** |
|
||||
| **Research Delivery** | موجزات مجدولة إلى Slack / Telegram / قنوات شبيهة بالبريد | مخطط |
|
||||
| **Community** | مهارات وإعدادات مسبقة وبطاقات استراتيجية قابلة للمشاركة | قيد الاستكشاف |
|
||||
|
||||
---
|
||||
|
||||
## المساهمة
|
||||
|
||||
نرحب بالمساهمات! راجع [CONTRIBUTING.md](CONTRIBUTING.md) للإرشادات.
|
||||
|
||||
**المشكلات الجيدة للمبتدئين** موسومة بـ [`good first issue`](https://github.com/HKUDS/Vibe-Trading/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22) — اختر واحدة وابدأ.
|
||||
|
||||
هل تريد المساهمة بشيء أكبر؟ راجع [خارطة الطريق](#-خارطة-الطريق) أعلاه وافتح issue للنقاش قبل البدء.
|
||||
|
||||
---
|
||||
|
||||
## المساهمون
|
||||
|
||||
شكراً لكل من ساهم في Vibe-Trading!
|
||||
|
||||
مساهمو واعتمادات دورة v0.1.7 الأخيرة:
|
||||
|
||||
- @GTC2080 / TaoMu — Web UI Settings وواجهات إعداد provider/data-source (#57)
|
||||
- @BigNounce90 — تعزيز validation CLI لمدخل `run_dir` في الاختبار الرجعي (#60)
|
||||
- @shadowinlife — مهارة A-share pre-ST filter (#63)
|
||||
- @MB-Ndhlovu — لوحة خريطة الارتباط الحرارية وإصلاحات المراجعة (#64, #66)
|
||||
- @ykykj — خيار مزود OpenAI Codex OAuth (#65)
|
||||
- @RuifengFu — شريط حالة CLI التفاعلي وتحرير prompt (#69)
|
||||
- @SiMinus — أمر فحص swarm preset (#73)
|
||||
- @warren618 / Haozhe Wu — تعزيز الأمان، وتكامل الإصدار، والوثائق، وDocker، والتغليف، وسير التطوير المحلي
|
||||
- lemi9090 (S2W) — بحث أمني منسق، وتحقق، ودعم الإفصاح
|
||||
|
||||
<a href="https://github.com/HKUDS/Vibe-Trading/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=HKUDS/Vibe-Trading" />
|
||||
</a>
|
||||
|
||||
---
|
||||
|
||||
## إخلاء المسؤولية
|
||||
|
||||
Vibe-Trading مخصص للبحث والمحاكاة والاختبار الرجعي فقط. ليس نصيحة استثمارية ولا ينفذ صفقات حية. الأداء السابق لا يضمن النتائج المستقبلية.
|
||||
|
||||
## الرخصة
|
||||
|
||||
رخصة MIT — راجع [LICENSE](LICENSE)
|
||||
|
||||
---
|
||||
|
||||
## تاريخ النجوم
|
||||
|
||||
[](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
شكراً لزيارة <b>Vibe-Trading</b> ✨
|
||||
</p>
|
||||
<p align="center">
|
||||
<img src="https://visitor-badge.laobi.icu/badge?page_id=HKUDS.Vibe-Trading&style=flat" alt="visitors"/>
|
||||
</p>
|
||||
+536
-244
File diff suppressed because it is too large.
Load diff
+521
-227
File diff suppressed because it is too large.
Load diff
+549
-258
File diff suppressed because it is too large.
Load diff
+26
@@ -0,0 +1,26 @@
|
||||
# Security Policy
|
||||
|
||||
## Supported Versions
|
||||
|
||||
| Version | Supported |
|
||||
|---------|:---------:|
|
||||
| latest | ✅ |
|
||||
|
||||
## Reporting a Vulnerability
|
||||
|
||||
If you discover a security vulnerability, please report it responsibly:
|
||||
|
||||
1. **Do NOT open a public issue.**
|
||||
2. Use the [GitHub Security Advisory](https://github.com/HKUDS/Vibe-Trading/security/advisories/new) to report privately.
|
||||
3. Include steps to reproduce, potential impact, and any suggested fixes.
|
||||
|
||||
We will acknowledge your report within **5 business days** and work with you to resolve the issue.
|
||||
|
||||
## Scope
|
||||
|
||||
This policy applies to the [HKUDS/Vibe-Trading](https://github.com/HKUDS/Vibe-Trading) repository.
|
||||
|
||||
## Disclosure
|
||||
|
||||
- Please do not publicly disclose the vulnerability until we have released a fix.
|
||||
- We will credit reporters in the release notes (unless you prefer anonymity).
|
||||
+79
-32
@@ -1,89 +1,136 @@
|
||||
# ============================================================================
|
||||
# LLM Provider — uncomment ONE block below
|
||||
# LLM Provider — uncomment ONE provider block below
|
||||
# ============================================================================
|
||||
LANGCHAIN_TEMPERATURE=0.0
|
||||
|
||||
# --- OpenRouter ---
|
||||
# --- OpenRouter (recommended, multi-model gateway) ---
|
||||
LANGCHAIN_PROVIDER=openrouter
|
||||
LANGCHAIN_MODEL_NAME=deepseek/deepseek-v3.2
|
||||
OPENROUTER_API_KEY=sk-or-v1-your-key-here
|
||||
OPENROUTER_BASE_URL=https://openrouter.ai/api/v1
|
||||
LANGCHAIN_MODEL_NAME=deepseek/deepseek-v3.2
|
||||
|
||||
# --- DeepSeek ---
|
||||
# LANGCHAIN_PROVIDER=deepseek
|
||||
# DEEPSEEK_API_KEY=sk-xxx
|
||||
# DEEPSEEK_BASE_URL=https://api.deepseek.com/v1
|
||||
# LANGCHAIN_MODEL_NAME=deepseek-chat
|
||||
|
||||
# --- OpenAI ---
|
||||
# LANGCHAIN_PROVIDER=openai
|
||||
# LANGCHAIN_MODEL_NAME=gpt-4o
|
||||
# OPENAI_API_KEY=sk-xxx
|
||||
# OPENAI_BASE_URL=https://api.openai.com/v1
|
||||
# LANGCHAIN_MODEL_NAME=gpt-4o
|
||||
|
||||
# --- OpenAI Codex (ChatGPT OAuth; not the OpenAI API key path) ---
|
||||
# Login first: vibe-trading provider login openai-codex
|
||||
# Requires a ChatGPT account with Codex access. OAuth tokens are stored by oauth-cli-kit.
|
||||
# LANGCHAIN_PROVIDER=openai-codex
|
||||
# LANGCHAIN_MODEL_NAME=openai-codex/gpt-5.3-codex
|
||||
# OPENAI_CODEX_BASE_URL=https://chatgpt.com/backend-api/codex/responses
|
||||
|
||||
# --- DeepSeek ---
|
||||
# LANGCHAIN_PROVIDER=deepseek
|
||||
# LANGCHAIN_MODEL_NAME=deepseek-chat
|
||||
# DEEPSEEK_API_KEY=sk-xxx
|
||||
# DEEPSEEK_BASE_URL=https://api.deepseek.com/v1
|
||||
|
||||
# --- Gemini ---
|
||||
# LANGCHAIN_PROVIDER=gemini
|
||||
# LANGCHAIN_MODEL_NAME=gemini-2.5-flash
|
||||
# GEMINI_API_KEY=xxx
|
||||
# GEMINI_BASE_URL=https://generativelanguage.googleapis.com/v1beta/openai/
|
||||
# LANGCHAIN_MODEL_NAME=gemini-2.5-flash
|
||||
|
||||
# --- Groq ---
|
||||
# LANGCHAIN_PROVIDER=groq
|
||||
# LANGCHAIN_MODEL_NAME=llama-3.3-70b-versatile
|
||||
# GROQ_API_KEY=gsk_xxx
|
||||
# GROQ_BASE_URL=https://api.groq.com/openai/v1
|
||||
# LANGCHAIN_MODEL_NAME=llama-3.3-70b-versatile
|
||||
|
||||
# --- DashScope / Qwen ---
|
||||
# LANGCHAIN_PROVIDER=dashscope
|
||||
# LANGCHAIN_MODEL_NAME=qwen-plus
|
||||
# DASHSCOPE_API_KEY=sk-xxx
|
||||
# DASHSCOPE_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
|
||||
# LANGCHAIN_MODEL_NAME=qwen-plus
|
||||
|
||||
# --- Zhipu ---
|
||||
# LANGCHAIN_PROVIDER=zhipu
|
||||
# LANGCHAIN_MODEL_NAME=glm-4-plus
|
||||
# ZHIPU_API_KEY=xxx
|
||||
# ZHIPU_BASE_URL=https://open.bigmodel.cn/api/paas/v4
|
||||
# LANGCHAIN_MODEL_NAME=glm-4-plus
|
||||
|
||||
# --- Moonshot / Kimi ---
|
||||
# LANGCHAIN_PROVIDER=moonshot
|
||||
# LANGCHAIN_MODEL_NAME=kimi-k2.5
|
||||
# MOONSHOT_API_KEY=sk-xxx
|
||||
# MOONSHOT_BASE_URL=https://api.moonshot.ai/v1
|
||||
# LANGCHAIN_MODEL_NAME=kimi-k2.5
|
||||
|
||||
# --- MiniMax ---
|
||||
# LANGCHAIN_PROVIDER=minimax
|
||||
# LANGCHAIN_MODEL_NAME=MiniMax-M2.7 # or MiniMax-M2.7-highspeed (faster)
|
||||
# MINIMAX_API_KEY=xxx
|
||||
# MINIMAX_BASE_URL=https://api.minimax.io/v1
|
||||
# LANGCHAIN_MODEL_NAME=MiniMax-Text-01
|
||||
# Note: MiniMax requires temperature > 0. Set LANGCHAIN_TEMPERATURE=1.0 (default when using MiniMax)
|
||||
|
||||
# --- Xiaomi MIMO ---
|
||||
# LANGCHAIN_PROVIDER=mimo
|
||||
# LANGCHAIN_MODEL_NAME=MiMo-72B-A27B
|
||||
# MIMO_API_KEY=xxx
|
||||
# MIMO_BASE_URL=https://api.xiaomimimo.com/v1
|
||||
# LANGCHAIN_MODEL_NAME=MiMo-72B-A27B
|
||||
|
||||
# --- Ollama ---
|
||||
# --- Z.ai (for Coding Plan) ---
|
||||
# LANGCHAIN_PROVIDER=zai
|
||||
# LANGCHAIN_MODEL_NAME=glm-5.1
|
||||
# ZAI_API_KEY=xxx
|
||||
# ZAI_BASE_URL=https://api.z.ai/api/coding/paas/v4
|
||||
|
||||
# --- Ollama (local) ---
|
||||
# LANGCHAIN_PROVIDER=ollama
|
||||
# OLLAMA_BASE_URL=http://localhost:11434/v1
|
||||
# LANGCHAIN_MODEL_NAME=qwen2.5:32b
|
||||
# OLLAMA_BASE_URL=http://localhost:11434/v1
|
||||
|
||||
# ============================================================================
|
||||
# Data Providers
|
||||
# ============================================================================
|
||||
# A-shares: Tushare Pro (requires token, https://tushare.pro)
|
||||
TUSHARE_TOKEN=your-tushare-token
|
||||
# HK/US equities: yfinance (free, no key needed)
|
||||
# Crypto: OKX public API (free, no key needed)
|
||||
|
||||
# ============================================================================
|
||||
# Runtime
|
||||
# ============================================================================
|
||||
# LLM parameters
|
||||
LANGCHAIN_TEMPERATURE=0.0
|
||||
TIMEOUT_SECONDS=120
|
||||
MAX_RETRIES=2
|
||||
|
||||
# Enable reasoning on relays that require opt-in (e.g. OpenRouter thinking models).
|
||||
# Forwarded as extra_body.reasoning.effort = low / medium / high / max.
|
||||
# Leave unset for Moonshot / DeepSeek official APIs — they return reasoning_content by default.
|
||||
# LANGCHAIN_REASONING_EFFORT=medium
|
||||
|
||||
# ============================================================================
|
||||
# Swarm / Subagent tuning (optional, defaults are sensible)
|
||||
# Data Sources
|
||||
# ============================================================================
|
||||
# A-shares: Tushare Pro token (https://tushare.pro)
|
||||
TUSHARE_TOKEN=your-tushare-token
|
||||
# HK/US equities: yfinance (free, no config needed)
|
||||
# Crypto: OKX public API (free, no config needed)
|
||||
# Crypto fallback exchange (default: binance). Change if OKX is blocked:
|
||||
# CCXT_EXCHANGE=binance
|
||||
# HK / A-share equities via Futu OpenAPI (optional, requires FutuOpenD running locally)
|
||||
# Download FutuOpenD: https://www.futunn.com/download/openAPI
|
||||
# FUTU_HOST=127.0.0.1
|
||||
# FUTU_PORT=11111
|
||||
|
||||
# ============================================================================
|
||||
# API Server (optional)
|
||||
# ============================================================================
|
||||
# Bearer token for API auth.
|
||||
# Empty dev mode is loopback-only. Set this before exposing port 8899 beyond localhost.
|
||||
# API_AUTH_KEY=
|
||||
# CORS allowed origins (comma-separated)
|
||||
# CORS_ORIGINS=http://localhost:3000,http://localhost:5173,http://localhost:8000
|
||||
# Enable session runtime
|
||||
# ENABLE_SESSION_RUNTIME=true
|
||||
# Docker compose sets this together with a 127.0.0.1 port bind so browser
|
||||
# requests from the host machine still count as local dev-mode access.
|
||||
# Do not enable this when publishing port 8899 on 0.0.0.0 without API_AUTH_KEY.
|
||||
# VIBE_TRADING_TRUST_DOCKER_LOOPBACK=0
|
||||
# Advanced local-only opt-in: expose shell execution tools to the agent.
|
||||
# VIBE_TRADING_ENABLE_SHELL_TOOLS=0
|
||||
# Optional import roots for read_document/analyze_trade_journal.
|
||||
# Use comma-separated absolute paths. Defaults include agent/uploads, agent/runs,
|
||||
# ./uploads, ./data, ~/.vibe-trading/uploads, and ~/.vibe-trading/imports.
|
||||
# VIBE_TRADING_ALLOWED_FILE_ROOTS=
|
||||
# Optional run roots for generated-code tools such as write_file/backtest.
|
||||
# Defaults include agent/runs, ./runs, and ~/.vibe-trading/shadow_runs.
|
||||
# VIBE_TRADING_ALLOWED_RUN_ROOTS=
|
||||
|
||||
# ============================================================================
|
||||
# Agent Tuning (optional, defaults are sensible)
|
||||
# ============================================================================
|
||||
# SWARM_WORKER_TIMEOUT=300
|
||||
# SWARM_WORKER_MAX_ITER=50
|
||||
|
||||
+126
-15
@@ -1,7 +1,7 @@
|
||||
---
|
||||
name: vibe-trading
|
||||
version: 0.1.4
|
||||
description: Professional finance research toolkit — backtesting (6 engines), factor analysis, options pricing, 68 finance skills, and 29 multi-agent swarm teams across 5 data sources (tushare, yfinance, okx, akshare, ccxt).
|
||||
version: 0.1.8
|
||||
description: Professional finance research toolkit — backtesting (7 engines + benchmark comparison panel), factor analysis, Alpha Zoo (452 pre-built alphas across qlib158/alpha101/gtja191/academic), options pricing, 75 finance skills, 29 multi-agent swarm teams, Trade Journal analyzer, and Shadow Account (extract → backtest → render) across 6 data sources (tushare, yfinance, okx, akshare, ccxt, futu).
|
||||
dependencies:
|
||||
python: ">=3.11"
|
||||
pip:
|
||||
@@ -11,7 +11,7 @@ env:
|
||||
description: "Tushare API token for China A-share data (optional — HK/US/crypto work without any key)"
|
||||
required: false
|
||||
- name: OPENAI_API_KEY
|
||||
description: "OpenAI-compatible API key — only needed for run_swarm (multi-agent teams). All other 16 tools work without it."
|
||||
description: "OpenAI-compatible API key — only needed for run_swarm (multi-agent teams). All other tools work without it."
|
||||
required: false
|
||||
- name: LANGCHAIN_MODEL_NAME
|
||||
description: "LLM model name for run_swarm (e.g. deepseek/deepseek-v3.2). Only needed if using run_swarm."
|
||||
@@ -23,7 +23,7 @@ mcp:
|
||||
|
||||
# Vibe-Trading
|
||||
|
||||
Professional finance research toolkit with AI-powered backtesting (6 engines), multi-agent teams, and 68 specialized skills.
|
||||
Professional finance research toolkit with AI-powered backtesting (7 engines), multi-agent teams, 75 specialized skills, the **Alpha Zoo** (452 pre-built quantitative alphas across qlib158 / alpha101 / gtja191 / academic with one-line CLI benchmarking), and the Shadow Account loop — extract your implicit trading rules from a journal, backtest them across A股/港股/美股/crypto, then see where they would have served you better.
|
||||
|
||||
## Setup
|
||||
|
||||
@@ -53,7 +53,7 @@ Add to your agent's MCP config:
|
||||
|
||||
### API Key Requirements
|
||||
|
||||
**16 of 17 MCP tools work with zero API keys.** After `pip install`, backtesting, market data, factor analysis, options pricing, chart patterns, web search, and all 68 skills are ready to use for HK/US equities and crypto.
|
||||
**21 of 22 MCP tools work with zero API keys.** After `pip install`, backtesting, market data, factor analysis, options pricing, chart patterns, web search, document reading, trade journal analysis, shadow-account extraction/backtest/report, the Alpha Zoo (452 pre-built alphas), and all 75 skills are ready to use for HK/US equities and crypto.
|
||||
|
||||
| Feature | Key needed | When |
|
||||
|---------|-----------|------|
|
||||
@@ -63,12 +63,22 @@ Add to your agent's MCP config:
|
||||
|
||||
## What You Can Do
|
||||
|
||||
### Shadow Account — flagship loop
|
||||
|
||||
Feed a CSV broker export (同花顺 / 东财 / 富途 / generic), and the agent will:
|
||||
1. `analyze_trade_journal` — profile your behavior (holding period, win rate, disposition effect, chasing, overtrading, anchoring).
|
||||
2. `extract_shadow_strategy` — distill 3-5 if-then rules that describe your profitable roundtrips.
|
||||
3. `run_shadow_backtest` — backtest those rules across A/HK/US/crypto and compute delta-PnL vs your realized trades.
|
||||
4. `render_shadow_report` — produce an HTML/PDF report (8 sections + charts) with today's matching signals.
|
||||
5. `scan_shadow_signals` — list today's symbols that match your shadow's entry cadence (research only).
|
||||
|
||||
### Backtesting
|
||||
Create and run quantitative strategies across 6 engines (ChinaA, GlobalEquity, Crypto, ChinaFutures, GlobalFutures, Forex + options) with 5 data sources:
|
||||
Create and run quantitative strategies across 7 engines (ChinaA, GlobalEquity, Crypto, ChinaFutures, GlobalFutures, Forex + options) with 6 data sources:
|
||||
- **HK/US equities** via yfinance (free, no API key)
|
||||
- **Cryptocurrency** via OKX or CCXT/100+ exchanges (free, no API key)
|
||||
- **China A-shares** via Tushare (token) or AKShare (free fallback)
|
||||
- **Futures, forex, macro** via AKShare (free, no API key)
|
||||
- **HK & A-share equities** via Futu (broker login required, optional)
|
||||
|
||||
Example workflow:
|
||||
1. Use `list_skills()` to discover strategy patterns
|
||||
@@ -89,34 +99,49 @@ Example workflow:
|
||||
|
||||
Use `list_swarm_presets()` to see all teams, then `run_swarm()` to execute.
|
||||
|
||||
### Finance Skills (68)
|
||||
### Alpha Zoo (452 pre-built alphas)
|
||||
One-line cross-sectional IC / IR / alive-reversed-dead categorisation across four bundled zoos:
|
||||
- **qlib158** (154 alphas) — Microsoft Qlib's `Alpha158` feature handler, Apache-2.0 with pinned commit SHA.
|
||||
- **alpha101** (101 alphas) — Kakushadze (2015) "101 Formulaic Alphas" (arXiv:1601.00991), written from the paper appendix.
|
||||
- **gtja191** (191 alphas) — Guotai Junan 2014 "191 Short-period Trading Alpha Factors" research report.
|
||||
- **academic** (6 factors) — Fama-French 5 + Carhart momentum (honest price-based proxies).
|
||||
|
||||
Each alpha ships with `__alpha_meta__` (formula LaTeX + theme + universe + warmup + columns required), guarded by an AST purity gate + 300-row lookahead sentinel test. Use the `vibe-trading alpha {list,show,bench,compare,export-manifest}` CLI, the `/alpha/*` REST routes (browser at `/alpha-zoo`), or compose multi-factor signals via `ZooSignalEngine.from_zoo(...)`.
|
||||
|
||||
### Finance Skills (75)
|
||||
Comprehensive knowledge base covering:
|
||||
- Technical analysis (candlestick, Elliott wave, Ichimoku, SMC)
|
||||
- Quantitative methods (factor research, ML strategy, pair trading)
|
||||
- Technical analysis (candlestick, Elliott wave, Ichimoku, SMC, harmonic, chanlun)
|
||||
- Quantitative methods (factor research, ML strategy, pair trading, multi-factor)
|
||||
- Risk management (VaR/CVaR, stress testing, hedging)
|
||||
- Options (Black-Scholes, Greeks, multi-leg strategies)
|
||||
- Options (Black-Scholes, Greeks, multi-leg strategies, payoff diagrams)
|
||||
- HK/US equities (SEC filings, earnings revisions, ETF flows, ADR/H-share arbitrage)
|
||||
- Crypto trading desk (funding rates, liquidation heatmaps, stablecoin flows, token unlocks, DeFi yields)
|
||||
- Behavioral finance, trade journal diagnostics, shadow account
|
||||
- Macro analysis, credit research, sector rotation, and more
|
||||
|
||||
Use `load_skill(name)` to access full methodology docs with code templates.
|
||||
|
||||
## Available MCP Tools (17)
|
||||
## Available MCP Tools (22)
|
||||
|
||||
| Tool | Description | API Key |
|
||||
|------|-------------|---------|
|
||||
| `list_skills` | List all 68 finance skills | None |
|
||||
| `list_skills` | List all 75 finance skills | None |
|
||||
| `load_skill` | Load full skill documentation | None |
|
||||
| `backtest` | Run vectorized backtest engine | None* |
|
||||
| `factor_analysis` | IC/IR analysis + layered backtest | None* |
|
||||
| `analyze_options` | Black-Scholes price + Greeks | None |
|
||||
| `pattern_recognition` | Detect chart patterns (H&S, double top, etc.) | None |
|
||||
| `get_market_data` | Fetch OHLCV data across 5 sources (auto-detect + fallback) | None* |
|
||||
| `get_market_data` | Fetch OHLCV data across 6 sources (auto-detect + fallback) | None* |
|
||||
| `web_search` | Search the web via DuckDuckGo | None |
|
||||
| `read_url` | Fetch web page as Markdown | None |
|
||||
| `read_document` | Extract text from PDF (with OCR) | None |
|
||||
| `read_document` | Extract text from PDF/DOCX/XLSX/PPTX/images | None |
|
||||
| `write_file` | Write files (config, strategy code) | None |
|
||||
| `read_file` | Read file contents | None |
|
||||
| `analyze_trade_journal` | Parse broker CSV → profile + behavior diagnostics | None |
|
||||
| `extract_shadow_strategy` | Distill 3-5 if-then rules from profitable roundtrips | None |
|
||||
| `run_shadow_backtest` | Multi-market backtest + delta-PnL attribution | None* |
|
||||
| `render_shadow_report` | HTML/PDF shadow report (8 sections + charts) | None |
|
||||
| `scan_shadow_signals` | Today's symbols matching the shadow's cadence | None |
|
||||
| `list_swarm_presets` | List multi-agent team presets | None |
|
||||
| `run_swarm` | Execute a multi-agent research team | LLM key |
|
||||
| `get_swarm_status` | Poll swarm run status without blocking | None |
|
||||
@@ -131,13 +156,99 @@ Use `load_skill(name)` to access full methodology docs with code templates.
|
||||
pip install vibe-trading-ai
|
||||
```
|
||||
|
||||
That's it — no API keys needed for HK/US/crypto markets. Start using `backtest`, `get_market_data`, `analyze_options`, `web_search`, and all 68 skills immediately.
|
||||
That's it — no API keys needed for HK/US/crypto markets. Start using `backtest`, `get_market_data`, `analyze_options`, `analyze_trade_journal`, `extract_shadow_strategy`, `web_search`, the **Alpha Zoo** (`vibe-trading alpha bench --zoo gtja191 --universe csi300 --period 2018-2025`), and all 75 skills immediately.
|
||||
|
||||
## Loading Tools from External MCP Servers
|
||||
|
||||
The built-in agent can load tools from your own external MCP servers in addition to its local toolset.
|
||||
|
||||
> **Note:** This is the *MCP client* path — the opposite of the MCP plugin listed above. The plugin above makes Vibe-Trading's tools available to your agents. This section lets Vibe-Trading's own agent call tools from *your* servers.
|
||||
|
||||
### Setup
|
||||
|
||||
Create `~/.vibe-trading/agent.json`:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"my-server": {
|
||||
"command": "uvx",
|
||||
"args": ["my-mcp-server"],
|
||||
"toolTimeout": 30,
|
||||
"enabledTools": ["*"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Remote tools appear automatically in every `vibe-trading run` / `vibe-trading chat` call. They are injected after local tools under stable names: `mcp_<server>_<tool>`.
|
||||
|
||||
### Config fields
|
||||
|
||||
| Field | Required | Default | Description |
|
||||
|-------|----------|---------|-------------|
|
||||
| `command` | yes | — | Executable to launch |
|
||||
| `args` | no | `[]` | Command arguments |
|
||||
| `env` | no | `{}` | Extra env vars for the subprocess |
|
||||
| `toolTimeout` | no | `30` | Seconds before a tool call is cancelled |
|
||||
| `enabledTools` | no | `["*"]` | Allowlist of remote tool names. `["*"]` enables all |
|
||||
|
||||
### Per-session override (API)
|
||||
|
||||
> **Security — disabled by default.** `mcpServers` defines subprocess `command`/`args`/`env` and is therefore restricted to operator-level trust. API callers **cannot** inject MCP server definitions through `POST /sessions` unless the server operator explicitly opts in.
|
||||
|
||||
To enable session-level MCP injection, set the environment variable on the server before starting the agent:
|
||||
|
||||
```bash
|
||||
export ALLOW_SESSION_MCP_SERVERS=1
|
||||
```
|
||||
|
||||
With the opt-in active, pass `mcpServers` inside `session.config` to extend or replace the global config for that session only:
|
||||
|
||||
```json
|
||||
{
|
||||
"config": {
|
||||
"mcpServers": {
|
||||
"research": {
|
||||
"command": "uvx",
|
||||
"args": ["research-mcp"],
|
||||
"enabledTools": ["search"]
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Without `ALLOW_SESSION_MCP_SERVERS=1`, any `mcpServers` key in `session.config` is silently stripped before config loading. The global operator config on disk (`~/.vibe-trading/agent.json`) is always respected regardless of this flag.
|
||||
|
||||
### v1 limits
|
||||
|
||||
- **Transport:** stdio only. SSE and HTTP transports are rejected.
|
||||
- **Execution:** serial only. MCP tools never enter the parallel readonly path.
|
||||
- **Surfaces:** tools only. Resources and prompts are not exposed.
|
||||
- **Swarm:** MCP tools are excluded from Swarm worker registries in v1.
|
||||
- **Hot reload:** not supported. Restart the process to pick up config changes.
|
||||
|
||||
### Failure handling
|
||||
|
||||
| Case | Behavior |
|
||||
|------|----------|
|
||||
| Missing config file | falls back to empty config — no MCP servers loaded |
|
||||
| Invalid config file | logs a warning and falls back to empty config |
|
||||
| Server fails to start | that server is skipped; local tools and other servers still load |
|
||||
| Tool call times out | returns a normalized error payload instead of raising |
|
||||
| Two server names collide after sanitization | deterministic hash suffix appended; operator warning emitted |
|
||||
|
||||
|
||||
|
||||
## Examples
|
||||
|
||||
**Backtest a MACD strategy on Apple:**
|
||||
> Backtest AAPL with MACD crossover strategy (fast=12, slow=26, signal=9) for 2024
|
||||
|
||||
**Analyze my trade journal and build a Shadow Account:**
|
||||
> Call analyze_trade_journal on ~/Downloads/tonghuashun.csv, then extract_shadow_strategy with min_support=3, then run_shadow_backtest for the last year, then render_shadow_report.
|
||||
|
||||
**Run an investment committee review:**
|
||||
> Use run_swarm with investment_committee preset to evaluate NVDA. Variables: target=NVDA.US, market=US
|
||||
|
||||
|
||||
+817
-47
File diff suppressed because it is too large.
Load diff
@@ -0,0 +1,152 @@
|
||||
"""Benchmark ticker resolution and fetch for backtest comparison.
|
||||
|
||||
Provides a lightweight, zero-dependency way to fetch benchmark reference
|
||||
data given a set of strategy codes and a data source.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.yfinance_loader import DataLoader as YfinanceLoader
|
||||
|
||||
|
||||
# -------------------------------------------------------------------
|
||||
# Benchmark map: market type → default ticker
|
||||
# -------------------------------------------------------------------
|
||||
|
||||
MARKET_BENCHMARKS: dict[str, Optional[str]] = {
|
||||
"us_equity": "SPY",
|
||||
"hk_equity": "HK.03100", # Hang Seng China Enterprises ETF
|
||||
"a_share": "000300.SH", # CSI 300 (China A-share core index)
|
||||
"crypto": "BTC-USDT",
|
||||
"futures": "ES.CME", # E-mini S&P 500 futures
|
||||
"forex": None, # no universal benchmark
|
||||
}
|
||||
|
||||
|
||||
@dataclass
|
||||
class BenchmarkResult:
|
||||
ticker: str
|
||||
ret_series: pd.Series # per-bar returns, index = timestamps
|
||||
total_ret: float # total return over the period
|
||||
|
||||
|
||||
def resolve_benchmark(
|
||||
strategy_codes: list[str],
|
||||
source: str,
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
interval: str = "1D",
|
||||
explicit: Optional[str] = None,
|
||||
) -> Optional[BenchmarkResult]:
|
||||
"""Resolve the appropriate benchmark ticker and fetch its return series.
|
||||
|
||||
Args:
|
||||
strategy_codes: Instruments being backtested (used for market inference).
|
||||
source: Data source name (tushare / yfinance / okx / akshare / ccxt).
|
||||
start_date: Backtest start date.
|
||||
end_date: Backtest end date.
|
||||
interval: Bar interval (1m / 5m / 15m / 30m / 1H / 4H / 1D).
|
||||
explicit: Override ticker (e.g. "SPY" passed via config).
|
||||
|
||||
Returns:
|
||||
BenchmarkResult with return series and total return, or None if no
|
||||
benchmark applies (forex, or fetch failure).
|
||||
"""
|
||||
ticker = _resolve_ticker(strategy_codes, source, explicit)
|
||||
if ticker is None:
|
||||
return None
|
||||
|
||||
try:
|
||||
bench_df = _fetch_benchmark(ticker, start_date, end_date, interval)
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
if bench_df.empty or "close" not in bench_df.columns:
|
||||
return None
|
||||
|
||||
close = bench_df["close"].dropna()
|
||||
if len(close) < 2:
|
||||
return None
|
||||
|
||||
ret_series = close.pct_change().fillna(0.0)
|
||||
total_ret = float((1 + ret_series).prod() - 1)
|
||||
|
||||
return BenchmarkResult(ticker=ticker, ret_series=ret_series, total_ret=total_ret)
|
||||
|
||||
|
||||
# -------------------------------------------------------------------
|
||||
# Internal helpers
|
||||
# -------------------------------------------------------------------
|
||||
|
||||
def _resolve_ticker(
|
||||
codes: list[str],
|
||||
source: str,
|
||||
explicit: Optional[str],
|
||||
) -> Optional[str]:
|
||||
"""Pick the benchmark ticker to use."""
|
||||
|
||||
if explicit:
|
||||
return explicit
|
||||
|
||||
# Infer market from source + first code pattern
|
||||
market = _infer_market(codes, source)
|
||||
ticker = MARKET_BENCHMARKS.get(market)
|
||||
|
||||
# yfinance is the universal fallback for benchmark fetch
|
||||
# but it only works for us_equity / hk_equity market types
|
||||
if ticker and market not in {"us_equity", "hk_equity"}:
|
||||
# Only use benchmark if we can actually fetch it
|
||||
pass
|
||||
|
||||
return ticker
|
||||
|
||||
|
||||
def _infer_market(codes: list[str], source: str) -> str:
|
||||
"""Rough market inference from symbol patterns and source."""
|
||||
if not codes:
|
||||
return "us_equity"
|
||||
|
||||
first = codes[0].upper()
|
||||
|
||||
if source in ("okx", "ccxt") or "-" in first or "/" in first:
|
||||
return "crypto"
|
||||
if first.endswith(".US"):
|
||||
return "us_equity"
|
||||
if first.endswith(".HK"):
|
||||
return "hk_equity"
|
||||
if source in ("tushare", "akshare"):
|
||||
if first.isdigit() and len(first) == 6:
|
||||
return "a_share"
|
||||
if first.startswith(("IF", "IC", "IH", "IM", "T", "TF")):
|
||||
return "futures"
|
||||
return "a_share"
|
||||
|
||||
return "us_equity"
|
||||
|
||||
|
||||
def _fetch_benchmark(
|
||||
ticker: str,
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
interval: str,
|
||||
) -> pd.DataFrame:
|
||||
"""Fetch benchmark OHLCV data via yfinance (single symbol, no auth)."""
|
||||
loader = YfinanceLoader()
|
||||
result = loader.fetch([ticker], start_date, end_date, interval=interval)
|
||||
|
||||
if isinstance(result, dict):
|
||||
df = result.get(ticker)
|
||||
elif isinstance(result, pd.DataFrame):
|
||||
df = result
|
||||
else:
|
||||
return pd.DataFrame()
|
||||
|
||||
if df is None or (isinstance(df, pd.DataFrame) and df.empty):
|
||||
return pd.DataFrame()
|
||||
|
||||
return df
|
||||
@@ -0,0 +1,175 @@
|
||||
"""Cross-asset correlation matrix computation.
|
||||
|
||||
Computes pairwise Pearson or Spearman correlation of daily returns
|
||||
over a configurable lookback window. Used by the /correlation API endpoint.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Dict, Literal
|
||||
|
||||
import pandas as pd
|
||||
import numpy as np
|
||||
from scipy.stats import spearmanr
|
||||
|
||||
|
||||
def infer_market(code: str) -> str:
|
||||
"""Infer market key from a ticker symbol."""
|
||||
code_upper = code.upper()
|
||||
crypto_suffixes = ("USDT", "BTC", "ETH", "BNB", "SOL", "ADA", "DOGE")
|
||||
if any(code_upper.endswith(s) for s in crypto_suffixes) or "/" in code:
|
||||
return "crypto"
|
||||
# Check .HK suffix FIRST so leading-zero tickers like 0700.HK / 0005.HK
|
||||
# are correctly classified before the A-share prefix checks
|
||||
if code_upper.endswith(".HK"):
|
||||
return "hk_equity"
|
||||
if code_upper.startswith(("6", "000", "001", "002")):
|
||||
return "a_share"
|
||||
if code_upper.startswith(("0", "399")):
|
||||
return "a_share"
|
||||
if code_upper.startswith(("0", "1", "2", "3", "4")):
|
||||
return "hk_equity"
|
||||
return "us_equity"
|
||||
|
||||
|
||||
def _rolling_correlation_matrix(
|
||||
price_series: Dict[str, pd.DataFrame],
|
||||
window: int,
|
||||
method: Literal["pearson", "spearman"],
|
||||
) -> tuple[list[str], list[list[float]]]:
|
||||
"""Compute correlation matrix for multiple price series.
|
||||
|
||||
Args:
|
||||
price_series: Mapping of asset code -> DataFrame with a ``close`` column.
|
||||
window: Rolling window size in days.
|
||||
method: "pearson" or "spearman".
|
||||
|
||||
Returns:
|
||||
(labels, matrix) where labels is the sorted list of codes and matrix
|
||||
is a symmetric NxN matrix of correlation coefficients.
|
||||
"""
|
||||
if not price_series:
|
||||
return [], []
|
||||
|
||||
codes = sorted(price_series.keys())
|
||||
|
||||
# Build a aligned returns DataFrame (row index = date)
|
||||
returns_frames = []
|
||||
closes = {}
|
||||
for code, df in price_series.items():
|
||||
if df.empty:
|
||||
raise ValueError(f"Price series for '{code}' is empty")
|
||||
if "close" not in df.columns and "close" not in df.index.names:
|
||||
raise ValueError(f"No 'close' column in price series for '{code}'")
|
||||
# Support both column-based and index-based trade_date
|
||||
if "trade_date" in df.index.names and "trade_date" not in df.columns:
|
||||
ts = df["close"]
|
||||
else:
|
||||
ts = df.set_index("trade_date")["close"]
|
||||
closes[code] = ts.sort_index()
|
||||
|
||||
for code in codes:
|
||||
ts = closes[code]
|
||||
rets = ts.pct_change().dropna()
|
||||
rets.name = code
|
||||
returns_frames.append(rets)
|
||||
|
||||
# Align all series to a common index (inner join)
|
||||
aligned = pd.concat(returns_frames, axis=1).dropna()
|
||||
if aligned.empty:
|
||||
raise ValueError("No overlapping return data between assets")
|
||||
|
||||
# Apply the trailing window — only use the last `window` rows of aligned data
|
||||
if len(aligned) > window:
|
||||
aligned = aligned.iloc[-window:]
|
||||
|
||||
n = len(aligned)
|
||||
if n < 2:
|
||||
raise ValueError("Not enough data points to compute correlation")
|
||||
|
||||
labels = codes
|
||||
n_assets = len(labels)
|
||||
matrix = [[1.0] * n_assets for _ in range(n_assets)]
|
||||
|
||||
for i in range(n_assets):
|
||||
for j in range(i + 1, n_assets):
|
||||
xi = aligned.iloc[:, i].values
|
||||
xj = aligned.iloc[:, j].values
|
||||
if method == "spearman":
|
||||
corr, _ = spearmanr(xi, xj)
|
||||
else:
|
||||
corr = np.corrcoef(xi, xj)[0, 1]
|
||||
if np.isnan(corr):
|
||||
corr = 0.0
|
||||
matrix[i][j] = round(corr, 4)
|
||||
matrix[j][i] = round(corr, 4)
|
||||
|
||||
return labels, matrix
|
||||
|
||||
|
||||
def compute_correlation_matrix(
|
||||
codes: list[str],
|
||||
days: int = 90,
|
||||
method: Literal["pearson", "spearman"] = "pearson",
|
||||
) -> Dict[str, object]:
|
||||
"""Fetch price data and compute correlation matrix for a list of assets.
|
||||
|
||||
Args:
|
||||
codes: List of asset codes (e.g. ["BTC-USDT", "ETH-USDT", "SPY"]).
|
||||
days: Lookback window in days (default 90).
|
||||
method: Correlation method.
|
||||
|
||||
Returns:
|
||||
Dict with keys: labels, matrix, window, method.
|
||||
"""
|
||||
from datetime import datetime, timedelta
|
||||
|
||||
end_date = datetime.now().strftime("%Y-%m-%d")
|
||||
start_date = (datetime.now() - timedelta(days=days + 60)).strftime("%Y-%m-%d")
|
||||
|
||||
# Import here to avoid circular
|
||||
from backtest.loaders.registry import resolve_loader
|
||||
|
||||
price_series: Dict[str, pd.DataFrame] = {}
|
||||
|
||||
for code in codes:
|
||||
market = infer_market(code)
|
||||
try:
|
||||
loader = resolve_loader(market)
|
||||
except Exception:
|
||||
# Fall back to yfinance for us_equity / hk_equity
|
||||
try:
|
||||
from backtest.loaders.registry import LOADER_REGISTRY
|
||||
if "yfinance" in LOADER_REGISTRY:
|
||||
loader = LOADER_REGISTRY["yfinance"]()
|
||||
else:
|
||||
continue
|
||||
except Exception:
|
||||
continue
|
||||
|
||||
try:
|
||||
result = loader.fetch(
|
||||
codes=[code],
|
||||
start_date=start_date,
|
||||
end_date=end_date,
|
||||
interval="1D",
|
||||
fields=["trade_date", "open", "high", "low", "close", "volume"],
|
||||
)
|
||||
if code in result and not result[code].empty:
|
||||
price_series[code] = result[code]
|
||||
except Exception:
|
||||
continue
|
||||
|
||||
if len(price_series) < 2:
|
||||
raise ValueError(
|
||||
f"Could not fetch price data for at least 2 assets. "
|
||||
f"Fetched: {list(price_series.keys())}"
|
||||
)
|
||||
|
||||
labels, matrix = _rolling_correlation_matrix(price_series, days, method)
|
||||
return {
|
||||
"labels": labels,
|
||||
"matrix": matrix,
|
||||
"window": days,
|
||||
"method": method,
|
||||
}
|
||||
@@ -13,12 +13,17 @@ Wave 2:
|
||||
- GlobalFuturesEngine: International futures (CME/ICE/Eurex)
|
||||
- ForexEngine: FX spot/CFD (spread, swap, high leverage)
|
||||
|
||||
Wave 3:
|
||||
- CompositeEngine: Cross-market engine with shared capital pool
|
||||
- _market_hooks: Extracted on_bar logic (funding, liquidation, swap)
|
||||
|
||||
Inheritance:
|
||||
BaseEngine
|
||||
├── ChinaAEngine
|
||||
├── GlobalEquityEngine
|
||||
├── CryptoEngine
|
||||
├── ForexEngine
|
||||
├── CompositeEngine (delegates to sub-engines as rule providers)
|
||||
└── FuturesBaseEngine
|
||||
├── ChinaFuturesEngine
|
||||
└── GlobalFuturesEngine
|
||||
|
||||
@@ -0,0 +1,180 @@
|
||||
"""Extracted per-bar market hooks as pure functions.
|
||||
|
||||
Both the original engines (CryptoEngine, ForexEngine) and CompositeEngine
|
||||
call these same functions. Zero duplication — one source of truth.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Dict
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.models import Position
|
||||
|
||||
# ── Crypto: OKX tiered maintenance margin table (simplified) ──
|
||||
|
||||
_TIER_TABLE = [
|
||||
(100_000, 0.004),
|
||||
(500_000, 0.006),
|
||||
(1_000_000, 0.01),
|
||||
(5_000_000, 0.02),
|
||||
(10_000_000, 0.05),
|
||||
(float("inf"), 0.10),
|
||||
]
|
||||
|
||||
FUNDING_HOURS = {0, 8, 16}
|
||||
|
||||
|
||||
def _maintenance_rate(notional_usd: float) -> float:
|
||||
"""Look up tiered maintenance margin rate."""
|
||||
for tier_max, rate in _TIER_TABLE:
|
||||
if notional_usd <= tier_max:
|
||||
return rate
|
||||
return _TIER_TABLE[-1][1]
|
||||
|
||||
|
||||
def calc_crypto_funding_fee(
|
||||
symbol: str,
|
||||
bar: pd.Series,
|
||||
timestamp: pd.Timestamp,
|
||||
positions: Dict[str, Position],
|
||||
funding_rate: float,
|
||||
applied_set: set,
|
||||
daily_done_set: set,
|
||||
) -> float:
|
||||
"""Calculate crypto funding fee for one symbol.
|
||||
|
||||
Args:
|
||||
symbol: Instrument code.
|
||||
bar: Current bar data.
|
||||
timestamp: Bar timestamp.
|
||||
positions: Shared positions dict.
|
||||
funding_rate: Fixed rate per settlement.
|
||||
applied_set: (symbol, date, hour) dedup set — mutated.
|
||||
daily_done_set: (symbol, date) dedup set — mutated.
|
||||
|
||||
Returns:
|
||||
Fee amount (positive = longs pay, negative = longs receive).
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return 0.0
|
||||
|
||||
current_date = timestamp.date()
|
||||
hour = timestamp.hour if hasattr(timestamp, "hour") else 0
|
||||
|
||||
if hour in FUNDING_HOURS:
|
||||
key = (symbol, current_date, hour)
|
||||
if key in applied_set:
|
||||
return 0.0
|
||||
applied_set.add(key)
|
||||
else:
|
||||
day_key = (symbol, current_date)
|
||||
if day_key in daily_done_set:
|
||||
return 0.0
|
||||
daily_done_set.add(day_key)
|
||||
|
||||
pos = positions.get(symbol)
|
||||
if pos is None:
|
||||
return 0.0
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
notional = pos.size * mark_price
|
||||
return notional * funding_rate * pos.direction
|
||||
|
||||
|
||||
def check_crypto_liquidation(
|
||||
symbol: str,
|
||||
bar: pd.Series,
|
||||
positions: Dict[str, Position],
|
||||
) -> bool:
|
||||
"""Check if a crypto position should be liquidated.
|
||||
|
||||
Args:
|
||||
symbol: Instrument code.
|
||||
bar: Current bar data.
|
||||
positions: Shared positions dict.
|
||||
|
||||
Returns:
|
||||
True if liquidation should be triggered.
|
||||
Does NOT execute the liquidation -- caller handles that.
|
||||
"""
|
||||
pos = positions.get(symbol)
|
||||
if pos is None or pos.leverage <= 1.0:
|
||||
return False
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
margin = pos.size * pos.entry_price / pos.leverage
|
||||
unrealized = pos.direction * pos.size * (mark_price - pos.entry_price)
|
||||
|
||||
notional = pos.size * mark_price
|
||||
maint_rate = _maintenance_rate(notional)
|
||||
maint_margin = notional * maint_rate
|
||||
|
||||
return (margin + unrealized) <= maint_margin
|
||||
|
||||
|
||||
# ── Forex: swap tables ──
|
||||
|
||||
_SWAP_LONG: dict[str, float] = {
|
||||
"EUR/USD": -6.5, "GBP/USD": -3.0, "USD/JPY": 8.0, "USD/CHF": 4.0,
|
||||
"AUD/USD": -2.0, "USD/CAD": 2.0, "NZD/USD": -1.5,
|
||||
}
|
||||
_SWAP_SHORT: dict[str, float] = {
|
||||
"EUR/USD": 3.5, "GBP/USD": -1.0, "USD/JPY": -12.0, "USD/CHF": -8.0,
|
||||
"AUD/USD": -1.0, "USD/CAD": -5.0, "NZD/USD": -2.0,
|
||||
}
|
||||
|
||||
|
||||
def _normalize_symbol(symbol: str) -> str:
|
||||
"""Normalize forex symbol to 'XXX/YYY' format."""
|
||||
s = symbol.replace(".FX", "").replace(".", "").strip()
|
||||
if "/" in s:
|
||||
return s.upper()
|
||||
if len(s) == 6:
|
||||
return f"{s[:3]}/{s[3:]}".upper()
|
||||
return s.upper()
|
||||
|
||||
|
||||
def calc_forex_swap(
|
||||
symbol: str,
|
||||
timestamp: pd.Timestamp,
|
||||
positions: Dict[str, Position],
|
||||
lot_size: float,
|
||||
last_swap_dates: dict,
|
||||
) -> float:
|
||||
"""Calculate forex swap for one symbol.
|
||||
|
||||
Args:
|
||||
symbol: Forex pair.
|
||||
timestamp: Bar timestamp.
|
||||
positions: Shared positions dict.
|
||||
lot_size: Standard lot size (e.g. 100_000).
|
||||
last_swap_dates: Per-symbol date tracking dict -- mutated.
|
||||
|
||||
Returns:
|
||||
Swap amount (positive = credit, negative = debit).
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return 0.0
|
||||
|
||||
current_date = timestamp.date()
|
||||
if last_swap_dates.get(symbol) == current_date:
|
||||
return 0.0
|
||||
last_swap_dates[symbol] = current_date
|
||||
|
||||
pos = positions.get(symbol)
|
||||
if pos is None:
|
||||
return 0.0
|
||||
|
||||
pair = _normalize_symbol(symbol)
|
||||
lots = pos.size / lot_size
|
||||
|
||||
if pos.direction == 1:
|
||||
swap_per_lot = _SWAP_LONG.get(pair, -1.0)
|
||||
else:
|
||||
swap_per_lot = _SWAP_SHORT.get(pair, -1.0)
|
||||
|
||||
# Wednesday = triple swap (covers Sat+Sun)
|
||||
multiplier = 3.0 if timestamp.weekday() == 2 else 1.0
|
||||
return lots * swap_per_lot * multiplier
|
||||
@@ -10,14 +10,20 @@ from __future__ import annotations
|
||||
|
||||
import importlib
|
||||
import json
|
||||
import logging
|
||||
import re as _re
|
||||
import sys
|
||||
from abc import ABC, abstractmethod
|
||||
from collections.abc import Iterable
|
||||
from pathlib import Path
|
||||
from typing import Any, Callable, Dict, List, Optional
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.tushare_fundamentals import (
|
||||
TushareFundamentalProvider,
|
||||
enrich_price_frames_with_fundamentals,
|
||||
)
|
||||
from backtest.metrics import (
|
||||
by_exit_reason_stats,
|
||||
by_symbol_stats,
|
||||
@@ -25,6 +31,39 @@ from backtest.metrics import (
|
||||
)
|
||||
from backtest.models import EquitySnapshot, Position, TradeRecord
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _run_card_data_sources(config: Dict[str, Any], loader: Any) -> List[str]:
|
||||
"""Return source names for run-card evidence."""
|
||||
configured = config.get("_run_card_effective_sources")
|
||||
if isinstance(configured, list):
|
||||
return [str(source) for source in configured if str(source).strip()]
|
||||
if isinstance(configured, str) and configured.strip():
|
||||
return [configured.strip()]
|
||||
|
||||
loader_name = getattr(loader, "name", None)
|
||||
if loader_name:
|
||||
return [str(loader_name)]
|
||||
|
||||
source = config.get("source")
|
||||
return [str(source)] if source else []
|
||||
|
||||
|
||||
# ─── Market detection (lightweight, for signal alignment only) ───
|
||||
|
||||
_CRYPTO_RE = _re.compile(r"^[A-Z]+-USDT$|^[A-Z]+/USDT$", _re.I)
|
||||
_FOREX_RE = _re.compile(r"^[A-Z]{3}/[A-Z]{3}$|^[A-Z]{6}\.FX$")
|
||||
|
||||
|
||||
def _detect_market_for_align(code: str) -> str:
|
||||
"""Lightweight market detection for ffill_limit calculation."""
|
||||
if _CRYPTO_RE.match(code):
|
||||
return "crypto"
|
||||
if _FOREX_RE.match(code):
|
||||
return "forex"
|
||||
return "equity"
|
||||
|
||||
|
||||
# ─── Signal alignment (reused from daily_portfolio logic) ───
|
||||
|
||||
@@ -57,12 +96,28 @@ def _align(
|
||||
close = pd.DataFrame(index=dates, columns=codes, dtype=float)
|
||||
for c in codes:
|
||||
close[c] = data_map[c]["close"].reindex(dates)
|
||||
close = close.ffill().bfill()
|
||||
|
||||
# ffill with limit to avoid masking long suspensions (e.g. 3-week halt)
|
||||
# Cross-market needs larger limit (Chinese New Year can be 9-10 bars)
|
||||
ffill_limit = 10 if len({_detect_market_for_align(c) for c in codes}) > 1 else 5
|
||||
close = close.ffill(limit=ffill_limit)
|
||||
|
||||
# Drop symbols that are entirely NaN (no data overlap with date range)
|
||||
all_nan_cols = [c for c in codes if close[c].isna().all()]
|
||||
if all_nan_cols:
|
||||
logger.warning("Symbols dropped (no usable price data): %s", all_nan_cols)
|
||||
codes = [c for c in codes if c not in all_nan_cols]
|
||||
if not codes:
|
||||
raise ValueError("All symbols have no data in the requested date range")
|
||||
close = close[codes]
|
||||
|
||||
pos = pd.DataFrame(0.0, index=dates, columns=codes)
|
||||
for c in codes:
|
||||
raw = signal_map[c].reindex(dates).fillna(0.0).clip(-1.0, 1.0)
|
||||
pos[c] = raw.shift(1).fillna(0.0)
|
||||
# Shift on each symbol's OWN trading calendar, then ffill to unified
|
||||
own_dates = data_map[c].index
|
||||
raw = signal_map[c].reindex(own_dates).fillna(0.0).clip(-1.0, 1.0)
|
||||
shifted = raw.shift(1).fillna(0.0)
|
||||
pos[c] = shifted.reindex(dates).ffill(limit=ffill_limit).fillna(0.0)
|
||||
|
||||
ret = close.pct_change().fillna(0.0)
|
||||
|
||||
@@ -96,6 +151,57 @@ def _load_optimizer(config: Dict[str, Any]) -> Optional[Callable]:
|
||||
return None
|
||||
|
||||
|
||||
def _normalise_fundamental_fields(config: Dict[str, Any]) -> dict[str, list[str]]:
|
||||
"""Read the optional statement-table field map from backtest config."""
|
||||
raw_fields = config.get("fundamental_fields")
|
||||
if raw_fields in (None, {}):
|
||||
return {}
|
||||
if not isinstance(raw_fields, dict):
|
||||
raise ValueError("fundamental_fields must map table names to field-name lists")
|
||||
|
||||
normalized: dict[str, list[str]] = {}
|
||||
for table, fields in raw_fields.items():
|
||||
if not isinstance(table, str) or not table.strip():
|
||||
raise ValueError("fundamental_fields table names must be non-empty strings")
|
||||
if fields is None:
|
||||
continue
|
||||
if isinstance(fields, str) or not isinstance(fields, Iterable):
|
||||
raise ValueError(f"fundamental_fields[{table!r}] must be a list of field names")
|
||||
|
||||
field_list = list(fields)
|
||||
if not field_list:
|
||||
continue
|
||||
invalid = [field for field in field_list if not isinstance(field, str) or not field.strip()]
|
||||
if invalid:
|
||||
raise ValueError(f"fundamental_fields[{table!r}] contains invalid field names")
|
||||
normalized[table.strip()] = field_list
|
||||
return normalized
|
||||
|
||||
|
||||
def _maybe_enrich_fundamentals(
|
||||
data_map: Dict[str, pd.DataFrame],
|
||||
config: Dict[str, Any],
|
||||
) -> Dict[str, pd.DataFrame]:
|
||||
"""Attach configured Tushare statement fields before signal generation."""
|
||||
fields_by_table = _normalise_fundamental_fields(config)
|
||||
if not fields_by_table:
|
||||
return data_map
|
||||
|
||||
try:
|
||||
provider = TushareFundamentalProvider()
|
||||
return enrich_price_frames_with_fundamentals(
|
||||
data_map,
|
||||
provider,
|
||||
fields_by_table,
|
||||
as_of=config.get("end_date", ""),
|
||||
periods=config.get("fundamental_periods"),
|
||||
)
|
||||
except Exception as exc:
|
||||
raise RuntimeError(
|
||||
f"fundamental_fields requested but Tushare enrichment failed: {exc}"
|
||||
) from exc
|
||||
|
||||
|
||||
# ─── Base Engine ───
|
||||
|
||||
|
||||
@@ -241,6 +347,7 @@ class BaseEngine(ABC):
|
||||
if not data_map:
|
||||
print(json.dumps({"error": "No data fetched"}))
|
||||
sys.exit(1)
|
||||
data_map = _maybe_enrich_fundamentals(data_map, config)
|
||||
|
||||
# 2. Generate signals
|
||||
signal_map = signal_engine.generate(data_map)
|
||||
@@ -255,6 +362,9 @@ class BaseEngine(ABC):
|
||||
data_map, signal_map, valid_codes, optimizer=opt_fn,
|
||||
)
|
||||
|
||||
# Sync codes after _align may have dropped all-NaN symbols
|
||||
valid_codes = [c for c in valid_codes if c in target_pos.columns]
|
||||
|
||||
# 4. Bar-by-bar execution
|
||||
self._execute_bars(dates, data_map, close_df, target_pos, valid_codes)
|
||||
|
||||
@@ -264,10 +374,33 @@ class BaseEngine(ABC):
|
||||
index=[s.timestamp for s in self.equity_snapshots],
|
||||
)
|
||||
bench_ret = ret_df.mean(axis=1) if ret_df.shape[1] > 0 else pd.Series(0.0, index=dates)
|
||||
benchmark_metadata = {}
|
||||
|
||||
# ── External benchmark fetch ──────────────────────────────────────────
|
||||
bench_ticker = config.get("benchmark")
|
||||
if bench_ticker and bench_ticker != "auto":
|
||||
from backtest.benchmark import resolve_benchmark
|
||||
bench_result = resolve_benchmark(
|
||||
strategy_codes=codes,
|
||||
source=config.get("source", "yfinance"),
|
||||
start_date=config.get("start_date", ""),
|
||||
end_date=config.get("end_date", ""),
|
||||
interval=interval,
|
||||
explicit=bench_ticker,
|
||||
)
|
||||
if bench_result is not None:
|
||||
bench_ret = bench_result.ret_series.reindex(dates).fillna(0.0)
|
||||
benchmark_metadata = {
|
||||
"benchmark_ticker": bench_result.ticker,
|
||||
"benchmark_return": bench_result.total_ret,
|
||||
}
|
||||
# ── External benchmark fetch ──────────────────────────────────────────
|
||||
|
||||
bench_equity = self.initial_capital * (1 + bench_ret).cumprod()
|
||||
|
||||
# 6. Metrics
|
||||
m = calc_metrics(equity_series, self.trades, self.initial_capital, bars_per_year, bench_ret)
|
||||
m.update(benchmark_metadata)
|
||||
m["by_symbol"] = by_symbol_stats(self.trades)
|
||||
m["by_exit_reason"] = by_exit_reason_stats(self.trades)
|
||||
|
||||
@@ -288,6 +421,16 @@ class BaseEngine(ABC):
|
||||
target_pos, m, valid_codes,
|
||||
)
|
||||
|
||||
# 9. Trust Layer run card
|
||||
from backtest.run_card import write_run_card
|
||||
write_run_card(
|
||||
run_dir,
|
||||
config,
|
||||
m,
|
||||
data_sources=_run_card_data_sources(config, loader),
|
||||
strategy_path=run_dir / "code" / "signal_engine.py",
|
||||
)
|
||||
|
||||
# Print scalar metrics (skip nested dicts for JSON compat)
|
||||
print(json.dumps({k: v for k, v in m.items() if not isinstance(v, dict)}, indent=2))
|
||||
return m
|
||||
@@ -314,8 +457,11 @@ class BaseEngine(ABC):
|
||||
# b. Rebalance each symbol to target weight
|
||||
equity = self._calc_equity(close_df, ts)
|
||||
for c in codes:
|
||||
target_w = float(target_pos.at[ts, c]) if ts in target_pos.index else 0.0
|
||||
self._rebalance(c, target_w, data_map.get(c), ts, equity)
|
||||
try:
|
||||
target_w = float(target_pos.at[ts, c]) if ts in target_pos.index else 0.0
|
||||
self._rebalance(c, target_w, data_map.get(c), ts, equity)
|
||||
except Exception as exc:
|
||||
logger.warning("Rebalance failed for %s at %s: %s", c, ts, exc)
|
||||
|
||||
# c. Record equity snapshot
|
||||
snap_equity = self._calc_equity(close_df, ts)
|
||||
|
||||
@@ -0,0 +1,217 @@
|
||||
"""Composite cross-market backtest engine.
|
||||
|
||||
Manages a shared capital pool across multiple market engines.
|
||||
Sub-engines are used as stateless "rule books" for market-specific
|
||||
calculations (commission, slippage, lot rounding, etc.).
|
||||
All state (capital, positions, trades) lives in CompositeEngine.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from typing import Dict, List
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.engines.base import BaseEngine
|
||||
from backtest.engines._market_hooks import (
|
||||
calc_crypto_funding_fee,
|
||||
check_crypto_liquidation,
|
||||
calc_forex_swap,
|
||||
)
|
||||
|
||||
|
||||
# ── Market detection (same patterns as runner.py) ──
|
||||
|
||||
_MARKET_PATTERNS = [
|
||||
(re.compile(r"^\d{6}\.(SZ|SH|BJ)$", re.I), "a_share"),
|
||||
(re.compile(r"^(51|15|56)\d{4}\.(SZ|SH)$", re.I), "a_share"),
|
||||
(re.compile(r"^[A-Z]+\.US$", re.I), "us_equity"),
|
||||
(re.compile(r"^\d{3,5}\.HK$", re.I), "hk_equity"),
|
||||
(re.compile(r"^[A-Z]+-USDT$", re.I), "crypto"),
|
||||
(re.compile(r"^[A-Z]+/USDT$", re.I), "crypto"),
|
||||
(re.compile(r"^[A-Za-z]{1,2}\d{3,4}\.(ZCE|DCE|SHFE|INE|CFFEX|GFEX)$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{2,4}[FGHJKMNQUVXZ]\d{1,2}$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{2,4}\d{4}$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{2,4}\.(CME|CBOT|NYMEX|COMEX|ICE|EUREX)$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{3}/[A-Z]{3}$"), "forex"),
|
||||
(re.compile(r"^[A-Z]{6}\.FX$"), "forex"),
|
||||
]
|
||||
|
||||
_CHINA_EXCHANGES = {"CFFEX", "SHFE", "DCE", "ZCE", "INE", "GFEX"}
|
||||
|
||||
|
||||
def _detect_market(code: str) -> str:
|
||||
"""Infer market type from symbol format."""
|
||||
for pattern, market in _MARKET_PATTERNS:
|
||||
if pattern.match(code):
|
||||
return market
|
||||
return "a_share"
|
||||
|
||||
|
||||
def _is_china_futures(code: str) -> bool:
|
||||
"""Check if futures code belongs to a Chinese exchange."""
|
||||
parts = code.upper().split(".")
|
||||
return len(parts) == 2 and parts[1] in _CHINA_EXCHANGES
|
||||
|
||||
|
||||
def _build_rule_engines(config: dict, codes: List[str]) -> Dict[str, BaseEngine]:
|
||||
"""Instantiate one sub-engine per market type detected in codes."""
|
||||
markets = {_detect_market(c) for c in codes}
|
||||
engines: Dict[str, BaseEngine] = {}
|
||||
|
||||
for market in markets:
|
||||
if market == "a_share":
|
||||
from backtest.engines.china_a import ChinaAEngine
|
||||
engines["a_share"] = ChinaAEngine(config)
|
||||
elif market == "us_equity":
|
||||
from backtest.engines.global_equity import GlobalEquityEngine
|
||||
engines["us_equity"] = GlobalEquityEngine(config, market="us")
|
||||
elif market == "hk_equity":
|
||||
from backtest.engines.global_equity import GlobalEquityEngine
|
||||
engines["hk_equity"] = GlobalEquityEngine(config, market="hk")
|
||||
elif market == "crypto":
|
||||
from backtest.engines.crypto import CryptoEngine
|
||||
engines["crypto"] = CryptoEngine(config)
|
||||
elif market == "forex":
|
||||
from backtest.engines.forex import ForexEngine
|
||||
engines["forex"] = ForexEngine(config)
|
||||
elif market == "futures":
|
||||
china = any(
|
||||
_is_china_futures(c) for c in codes if _detect_market(c) == "futures"
|
||||
)
|
||||
if china:
|
||||
from backtest.engines.china_futures import ChinaFuturesEngine
|
||||
engines["futures"] = ChinaFuturesEngine(config)
|
||||
else:
|
||||
from backtest.engines.global_futures import GlobalFuturesEngine
|
||||
engines["futures"] = GlobalFuturesEngine(config)
|
||||
|
||||
return engines
|
||||
|
||||
|
||||
class CompositeEngine(BaseEngine):
|
||||
"""Cross-market engine with shared capital pool.
|
||||
|
||||
Sub-engines are stateless rule providers. All positions, capital,
|
||||
and trades live here (inherited from BaseEngine).
|
||||
|
||||
Args:
|
||||
config: Backtest configuration dict.
|
||||
codes: List of instrument codes spanning multiple markets.
|
||||
"""
|
||||
|
||||
def __init__(self, config: dict, codes: List[str]):
|
||||
super().__init__(config)
|
||||
|
||||
# Build symbol -> market mapping
|
||||
self._symbol_market: Dict[str, str] = {c: _detect_market(c) for c in codes}
|
||||
|
||||
# Build sub-engines (one per market type)
|
||||
self._rule_engines = _build_rule_engines(config, codes)
|
||||
|
||||
# Crypto dedup state (owned by CompositeEngine, not sub-engine)
|
||||
self._funding_applied: set = set()
|
||||
self._funding_daily_done: set = set()
|
||||
|
||||
# Forex dedup state
|
||||
self._last_swap_dates: dict = {}
|
||||
|
||||
def _rule_for(self, symbol: str) -> BaseEngine:
|
||||
"""Get the sub-engine that provides rules for this symbol."""
|
||||
market = self._symbol_market.get(symbol, "a_share")
|
||||
return self._rule_engines[market]
|
||||
|
||||
# ── Stateless method dispatch ──
|
||||
|
||||
def can_execute(self, symbol: str, direction: int, bar: pd.Series) -> bool:
|
||||
"""Market-rule check with T+1 interceptor for A-shares."""
|
||||
market = self._symbol_market.get(symbol, "a_share")
|
||||
|
||||
# T+1: intercept here because sub-engine has no access to shared positions
|
||||
if market == "a_share" and direction == 0:
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is not None:
|
||||
bar_date = None
|
||||
if hasattr(bar, "name") and hasattr(bar.name, "date"):
|
||||
bar_date = bar.name.date()
|
||||
entry_date = (
|
||||
pos.entry_time.date()
|
||||
if hasattr(pos.entry_time, "date")
|
||||
else None
|
||||
)
|
||||
if bar_date and entry_date and bar_date == entry_date:
|
||||
return False
|
||||
|
||||
# Delegate remaining checks (price limits, short-sell block, etc.)
|
||||
return self._rule_for(symbol).can_execute(symbol, direction, bar)
|
||||
|
||||
def round_size(self, raw_size: float, price: float) -> float:
|
||||
"""Delegate to active symbol's sub-engine."""
|
||||
return self._rule_for(self._active_symbol).round_size(raw_size, price)
|
||||
|
||||
def calc_commission(
|
||||
self, size: float, price: float, direction: int, is_open: bool,
|
||||
) -> float:
|
||||
"""Delegate to active symbol's sub-engine."""
|
||||
return self._rule_for(self._active_symbol).calc_commission(
|
||||
size, price, direction, is_open,
|
||||
)
|
||||
|
||||
def apply_slippage(self, price: float, direction: int) -> float:
|
||||
"""Delegate to active symbol's sub-engine."""
|
||||
sub = self._rule_for(self._active_symbol)
|
||||
# ForexEngine needs _active_symbol set on the sub-engine
|
||||
sub._active_symbol = self._active_symbol
|
||||
return sub.apply_slippage(price, direction)
|
||||
|
||||
# ── PnL / margin dispatch (route by symbol, not _active_symbol) ──
|
||||
|
||||
def _calc_pnl(
|
||||
self, symbol: str, direction: int, size: float,
|
||||
entry_price: float, exit_price: float,
|
||||
) -> float:
|
||||
return self._rule_for(symbol)._calc_pnl(
|
||||
symbol, direction, size, entry_price, exit_price,
|
||||
)
|
||||
|
||||
def _calc_margin(
|
||||
self, symbol: str, size: float, price: float, leverage: float,
|
||||
) -> float:
|
||||
return self._rule_for(symbol)._calc_margin(symbol, size, price, leverage)
|
||||
|
||||
def _calc_raw_size(
|
||||
self, symbol: str, target_notional: float, price: float,
|
||||
) -> float:
|
||||
return self._rule_for(symbol)._calc_raw_size(symbol, target_notional, price)
|
||||
|
||||
# ── Stateful hooks (implemented directly, NO delegation) ──
|
||||
|
||||
def on_bar(self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp) -> None:
|
||||
"""Per-bar hooks dispatched by market type."""
|
||||
market = self._symbol_market.get(symbol)
|
||||
|
||||
if market == "crypto":
|
||||
crypto_sub = self._rule_engines["crypto"]
|
||||
fee = calc_crypto_funding_fee(
|
||||
symbol, bar, timestamp, self.positions,
|
||||
crypto_sub.funding_rate,
|
||||
self._funding_applied, self._funding_daily_done,
|
||||
)
|
||||
self.capital -= fee
|
||||
|
||||
if check_crypto_liquidation(symbol, bar, self.positions):
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is not None:
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
liq_price = crypto_sub.apply_slippage(mark_price, -pos.direction)
|
||||
self._close_position(symbol, liq_price, timestamp, "liquidation")
|
||||
|
||||
elif market == "forex":
|
||||
forex_sub = self._rule_engines["forex"]
|
||||
if forex_sub.swap_enabled:
|
||||
swap = calc_forex_swap(
|
||||
symbol, timestamp, self.positions,
|
||||
forex_sub.lot_size, self._last_swap_dates,
|
||||
)
|
||||
self.capital += swap
|
||||
@@ -13,21 +13,10 @@ from __future__ import annotations
|
||||
import pandas as pd
|
||||
|
||||
from backtest.engines.base import BaseEngine
|
||||
|
||||
|
||||
# OKX tiered maintenance margin table (simplified)
|
||||
# (max_notional_usd, maintenance_margin_rate)
|
||||
_TIER_TABLE = [
|
||||
(100_000, 0.004),
|
||||
(500_000, 0.006),
|
||||
(1_000_000, 0.01),
|
||||
(5_000_000, 0.02),
|
||||
(10_000_000, 0.05),
|
||||
(float("inf"), 0.10),
|
||||
]
|
||||
|
||||
# Funding fee settlement hours (UTC)
|
||||
_FUNDING_HOURS = {0, 8, 16}
|
||||
from backtest.engines._market_hooks import (
|
||||
calc_crypto_funding_fee,
|
||||
check_crypto_liquidation,
|
||||
)
|
||||
|
||||
|
||||
class CryptoEngine(BaseEngine):
|
||||
@@ -70,80 +59,15 @@ class CryptoEngine(BaseEngine):
|
||||
|
||||
def on_bar(self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp) -> None:
|
||||
"""Crypto per-bar hooks: funding fee + liquidation check."""
|
||||
self._apply_funding_fee(symbol, bar, timestamp)
|
||||
self._check_liquidation(symbol, bar, timestamp)
|
||||
|
||||
# ── Funding fee (exchange-enforced, every 8h) ──
|
||||
|
||||
def _apply_funding_fee(
|
||||
self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp,
|
||||
) -> None:
|
||||
"""Deduct/credit funding fee at settlement hours.
|
||||
|
||||
Positive rate: longs pay shorts. Negative rate: shorts pay longs.
|
||||
|
||||
For intraday bars: applies at each 8h settlement (0/8/16 UTC).
|
||||
For daily bars: applies once per calendar day regardless of hour.
|
||||
Dedup is per-(symbol, date, hour) so multi-symbol portfolios work.
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return
|
||||
|
||||
current_date = timestamp.date()
|
||||
hour = timestamp.hour if hasattr(timestamp, "hour") else 0
|
||||
|
||||
if hour in _FUNDING_HOURS:
|
||||
key = (symbol, current_date, hour)
|
||||
if key in self._funding_applied:
|
||||
return
|
||||
self._funding_applied.add(key)
|
||||
else:
|
||||
# Non-settlement hour (e.g. daily bar at 12:00 UTC)
|
||||
# Apply once per day as approximation
|
||||
day_key = (symbol, current_date)
|
||||
if day_key in self._funding_daily_done:
|
||||
return
|
||||
self._funding_daily_done.add(day_key)
|
||||
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is None:
|
||||
return
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
notional = pos.size * mark_price
|
||||
fee = notional * self.funding_rate * pos.direction
|
||||
fee = calc_crypto_funding_fee(
|
||||
symbol, bar, timestamp, self.positions,
|
||||
self.funding_rate, self._funding_applied, self._funding_daily_done,
|
||||
)
|
||||
self.capital -= fee
|
||||
|
||||
# ── Liquidation (exchange-enforced) ──
|
||||
|
||||
def _check_liquidation(
|
||||
self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp,
|
||||
) -> None:
|
||||
"""Force-close when maintenance margin ratio drops to / below 100%."""
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is None or pos.leverage <= 1.0:
|
||||
return # spot has no liquidation
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
margin = pos.size * pos.entry_price / pos.leverage
|
||||
unrealized = pos.direction * pos.size * (mark_price - pos.entry_price)
|
||||
|
||||
# Maintenance margin rate (tiered)
|
||||
notional = pos.size * mark_price
|
||||
maint_rate = self._maintenance_rate(notional)
|
||||
maint_margin = notional * maint_rate
|
||||
|
||||
# Margin ratio = (margin + unrealized) / maint_margin
|
||||
equity_in_pos = margin + unrealized
|
||||
if equity_in_pos <= maint_margin:
|
||||
# Liquidation: close at mark price with taker fee
|
||||
liq_price = self.apply_slippage(mark_price, -pos.direction)
|
||||
self._close_position(symbol, liq_price, timestamp, "liquidation")
|
||||
|
||||
@staticmethod
|
||||
def _maintenance_rate(notional_usd: float) -> float:
|
||||
"""Look up tiered maintenance margin rate."""
|
||||
for tier_max, rate in _TIER_TABLE:
|
||||
if notional_usd <= tier_max:
|
||||
return rate
|
||||
return _TIER_TABLE[-1][1]
|
||||
if check_crypto_liquidation(symbol, bar, self.positions):
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is not None:
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
liq_price = self.apply_slippage(mark_price, -pos.direction)
|
||||
self._close_position(symbol, liq_price, timestamp, "liquidation")
|
||||
@@ -15,6 +15,7 @@ from __future__ import annotations
|
||||
import pandas as pd
|
||||
|
||||
from backtest.engines.base import BaseEngine
|
||||
from backtest.engines._market_hooks import calc_forex_swap
|
||||
|
||||
|
||||
# ── Typical spreads in pips (1 pip = 0.0001 for most pairs, 0.01 for JPY) ──
|
||||
@@ -33,18 +34,6 @@ _SPREAD_PIPS: dict[str, float] = {
|
||||
}
|
||||
_DEFAULT_SPREAD_PIPS = 2.0
|
||||
|
||||
# ── Daily swap points (per standard lot, in account currency) ──
|
||||
# Positive = receive, negative = pay. Varies by broker/rates; simplified table.
|
||||
|
||||
_SWAP_LONG: dict[str, float] = {
|
||||
"EUR/USD": -6.5, "GBP/USD": -3.0, "USD/JPY": 8.0, "USD/CHF": 4.0,
|
||||
"AUD/USD": -2.0, "USD/CAD": 2.0, "NZD/USD": -1.5,
|
||||
}
|
||||
_SWAP_SHORT: dict[str, float] = {
|
||||
"EUR/USD": 3.5, "GBP/USD": -1.0, "USD/JPY": -12.0, "USD/CHF": -8.0,
|
||||
"AUD/USD": -1.0, "USD/CAD": -5.0, "NZD/USD": -2.0,
|
||||
}
|
||||
|
||||
# Standard lot size
|
||||
STANDARD_LOT = 100_000
|
||||
|
||||
@@ -149,41 +138,12 @@ class ForexEngine(BaseEngine):
|
||||
"""Apply daily swap/rollover at end of trading day."""
|
||||
if not self.swap_enabled:
|
||||
return
|
||||
self._apply_swap(symbol, timestamp)
|
||||
swap = calc_forex_swap(
|
||||
symbol, timestamp, self.positions,
|
||||
self.lot_size, self._last_swap_dates,
|
||||
)
|
||||
self.capital += swap
|
||||
|
||||
def get_contract_multiplier(self, symbol: str) -> float:
|
||||
"""Forex: multiplier is 1.0 (size is in currency units)."""
|
||||
return 1.0
|
||||
|
||||
# ── Swap (overnight rollover) ──
|
||||
|
||||
def _apply_swap(self, symbol: str, timestamp: pd.Timestamp) -> None:
|
||||
"""Deduct/credit swap at daily rollover (once per calendar day).
|
||||
|
||||
Triple swap on Wednesday (covers weekend).
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return
|
||||
|
||||
current_date = timestamp.date()
|
||||
if self._last_swap_dates.get(symbol) == current_date:
|
||||
return
|
||||
self._last_swap_dates[symbol] = current_date
|
||||
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is None:
|
||||
return
|
||||
|
||||
pair = _normalize_symbol(symbol)
|
||||
lots = pos.size / self.lot_size
|
||||
|
||||
if pos.direction == 1:
|
||||
swap_per_lot = _SWAP_LONG.get(pair, -1.0)
|
||||
else:
|
||||
swap_per_lot = _SWAP_SHORT.get(pair, -1.0)
|
||||
|
||||
# Wednesday = triple swap (covers Sat+Sun)
|
||||
multiplier = 3.0 if timestamp.weekday() == 2 else 1.0
|
||||
swap = lots * swap_per_lot * multiplier
|
||||
|
||||
self.capital += swap
|
||||
@@ -16,7 +16,6 @@ Artifacts: equity.csv, metrics.csv, trades.csv, greeks.csv.
|
||||
|
||||
import json
|
||||
import sys
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
@@ -290,7 +289,6 @@ def run_options_backtest(
|
||||
commission = config.get("commission", 0.001)
|
||||
options_cfg = config.get("options_config", {})
|
||||
risk_free_rate = options_cfg.get("risk_free_rate", 0.05)
|
||||
iv_source = options_cfg.get("iv_source", "historical")
|
||||
contract_multiplier = options_cfg.get("contract_multiplier", 1.0)
|
||||
exercise_style = options_cfg.get("exercise_style", "european") # v2: "european" or "american"
|
||||
iv_skew = options_cfg.get("iv_skew", 0.0) # v2: smile skew param (0 = flat)
|
||||
@@ -554,6 +552,15 @@ def run_options_backtest(
|
||||
pd.DataFrame(greeks_records).to_csv(out / "greeks.csv", index=False)
|
||||
pd.DataFrame([metrics]).to_csv(out / "metrics.csv", index=False)
|
||||
|
||||
from backtest.run_card import write_run_card
|
||||
write_run_card(
|
||||
run_dir,
|
||||
config,
|
||||
metrics,
|
||||
data_sources=[str(getattr(loader, "name", config.get("source", "")))],
|
||||
strategy_path=run_dir / "code" / "signal_engine.py",
|
||||
)
|
||||
|
||||
print(json.dumps(metrics, indent=2))
|
||||
return metrics
|
||||
|
||||
|
||||
@@ -11,6 +11,7 @@ from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -38,6 +39,38 @@ def _is_crypto(code: str) -> bool:
|
||||
return "-USDT" in code.upper() or "/USDT" in code.upper()
|
||||
|
||||
|
||||
# Exchange-listed ETF / LOF prefix codes:
|
||||
# SH: 50/51/52/56/58 (ETFs), SZ: 15/16 (ETFs + LOFs).
|
||||
# Issue #50 — these symbols look like A-shares (.SH / .SZ) but stock_zh_a_hist
|
||||
# can't price them; route through fund_etf_hist_sina instead.
|
||||
_ETF_PREFIXES = frozenset({"15", "16", "50", "51", "52", "56", "58"})
|
||||
|
||||
|
||||
def _is_etf_listed(code: str) -> bool:
|
||||
"""Detect exchange-listed ETF / LOF symbols (e.g. 518880.SH, 159915.SZ)."""
|
||||
upper = code.upper()
|
||||
if not upper.endswith((".SH", ".SZ")):
|
||||
return False
|
||||
digits = upper.split(".")[0]
|
||||
if len(digits) != 6 or not digits.isdigit():
|
||||
return False
|
||||
return digits[:2] in _ETF_PREFIXES
|
||||
|
||||
|
||||
def _is_forex(code: str) -> bool:
|
||||
"""Detect forex pairs by matching against AKShare's symbol_market_map.
|
||||
|
||||
Issue #54 — forex symbols (EURUSD, GBPUSD, etc.) have no exchange suffix
|
||||
and previously fell through to the A-share endpoint.
|
||||
"""
|
||||
upper = code.upper().removesuffix(".FX")
|
||||
try:
|
||||
from akshare.forex.cons import symbol_market_map
|
||||
except Exception:
|
||||
return False
|
||||
return upper in symbol_market_map
|
||||
|
||||
|
||||
@register
|
||||
class DataLoader:
|
||||
"""AKShare universal OHLCV loader (free, no auth)."""
|
||||
@@ -78,6 +111,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping symbol -> OHLCV DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
result: Dict[str, pd.DataFrame] = {}
|
||||
for code in codes:
|
||||
try:
|
||||
@@ -94,12 +129,17 @@ class DataLoader:
|
||||
"""Fetch a single symbol."""
|
||||
import akshare as ak
|
||||
|
||||
# ETF check must precede A-share — 518880.SH ends with .SH but is an ETF.
|
||||
if _is_etf_listed(code):
|
||||
return self._fetch_etf(ak, code, start_date, end_date)
|
||||
if _is_a_share(code):
|
||||
return self._fetch_a_share(ak, code, start_date, end_date, interval)
|
||||
if _is_us(code):
|
||||
return self._fetch_us(ak, code, start_date, end_date)
|
||||
if _is_hk(code):
|
||||
return self._fetch_hk(ak, code, start_date, end_date)
|
||||
if _is_forex(code):
|
||||
return self._fetch_forex(ak, code, start_date, end_date)
|
||||
# Default: try A-share
|
||||
return self._fetch_a_share(ak, code, start_date, end_date, interval)
|
||||
|
||||
@@ -142,6 +182,49 @@ class DataLoader:
|
||||
continue
|
||||
return None
|
||||
|
||||
def _fetch_etf(self, ak, code: str, start_date: str, end_date: str) -> Optional[pd.DataFrame]:
|
||||
"""Fetch exchange-listed ETF / LOF via fund_etf_hist_sina.
|
||||
|
||||
Sina symbol format is ``sh518880`` / ``sz159915``. The endpoint returns
|
||||
the full history; we filter to the requested window after fetching.
|
||||
"""
|
||||
digits, _, suffix = code.upper().partition(".")
|
||||
symbol = f"{suffix.lower()}{digits}"
|
||||
df = ak.fund_etf_hist_sina(symbol=symbol)
|
||||
if df is None or df.empty:
|
||||
return None
|
||||
df = self._normalize(df, date_col="date")
|
||||
# fund_etf_hist_sina returns full history — clip to window.
|
||||
return df.loc[start_date:end_date]
|
||||
|
||||
def _fetch_forex(self, ak, code: str, start_date: str, end_date: str) -> Optional[pd.DataFrame]:
|
||||
"""Fetch forex pair via forex_hist_em.
|
||||
|
||||
Columns returned are 日期 / 代码 / 名称 / 今开 / 最新价 / 最高 / 最低 / 振幅
|
||||
— note ``最新价`` (latest) plays the role of close. Volume isn't reported,
|
||||
so we synthesize a zero column to satisfy the OHLCV contract.
|
||||
"""
|
||||
symbol = code.upper().removesuffix(".FX")
|
||||
df = ak.forex_hist_em(symbol=symbol)
|
||||
if df is None or df.empty:
|
||||
return None
|
||||
df = df.rename(columns={
|
||||
"日期": "trade_date",
|
||||
"今开": "open",
|
||||
"最新价": "close",
|
||||
"最高": "high",
|
||||
"最低": "low",
|
||||
})
|
||||
df["trade_date"] = pd.to_datetime(df["trade_date"])
|
||||
df = df.set_index("trade_date").sort_index()
|
||||
df["volume"] = 0.0
|
||||
for col in ("open", "high", "low", "close"):
|
||||
df[col] = pd.to_numeric(df[col], errors="coerce")
|
||||
df = df[["open", "high", "low", "close", "volume"]].dropna(
|
||||
subset=["open", "high", "low", "close"]
|
||||
)
|
||||
return df.loc[start_date:end_date]
|
||||
|
||||
def _fetch_hk(self, ak, code: str, start_date: str, end_date: str) -> Optional[pd.DataFrame]:
|
||||
"""Fetch HK stock via stock_hk_hist."""
|
||||
symbol = code.replace(".HK", "").zfill(5)
|
||||
|
||||
@@ -1,8 +1,16 @@
|
||||
"""DataLoader Protocol and shared exceptions for all data source loaders."""
|
||||
"""DataLoader Protocol, shared exceptions, and bounded-retry helpers.
|
||||
|
||||
The retry/budget helpers are the canonical pattern for any loader that calls
|
||||
a flaky external API: a wall-clock deadline plus a small backoff schedule
|
||||
applied only to a declared transient exception class. New loaders should
|
||||
import :func:`check_budget` and :func:`retry_with_budget` rather than
|
||||
re-implementing the loop.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Protocol, runtime_checkable
|
||||
import time
|
||||
from typing import Callable, Protocol, TypeVar, runtime_checkable
|
||||
|
||||
import pandas as pd
|
||||
|
||||
@@ -11,6 +19,110 @@ class NoAvailableSourceError(Exception):
|
||||
"""Raised when no data source is available for a given market."""
|
||||
|
||||
|
||||
def validate_date_range(start_date: str, end_date: str) -> None:
|
||||
"""Validate that start_date <= end_date.
|
||||
|
||||
Args:
|
||||
start_date: Start date string (YYYY-MM-DD).
|
||||
end_date: End date string (YYYY-MM-DD).
|
||||
|
||||
Raises:
|
||||
ValueError: If dates are invalid or start > end.
|
||||
"""
|
||||
try:
|
||||
start = pd.Timestamp(start_date)
|
||||
end = pd.Timestamp(end_date)
|
||||
except Exception as exc:
|
||||
raise ValueError(f"Invalid date format: start={start_date!r}, end={end_date!r}") from exc
|
||||
if start > end:
|
||||
raise ValueError(f"start_date ({start_date}) > end_date ({end_date})")
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Bounded retry / budget helpers (shared by ccxt_loader, okx, and any future
|
||||
# loader calling a flaky external API).
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
DEFAULT_BACKOFF: tuple[float, ...] = (0.5, 1.5, 4.0)
|
||||
DEFAULT_MAX_RETRIES = 3
|
||||
|
||||
|
||||
def check_budget(deadline: float, label: str, budget_s: float | None = None) -> None:
|
||||
"""Raise :class:`TimeoutError` if the monotonic clock has crossed ``deadline``.
|
||||
|
||||
Use this between pages of a paginated fetch to fail fast instead of
|
||||
grinding through more requests once the wall-clock budget is gone.
|
||||
|
||||
Args:
|
||||
deadline: ``time.monotonic()`` instant past which we abort.
|
||||
label: Free-form label used in the exception message
|
||||
(e.g. ``"ccxt fetch for BTC/USDT"``).
|
||||
budget_s: Original budget in seconds, included verbatim in the
|
||||
message when present.
|
||||
"""
|
||||
if time.monotonic() > deadline:
|
||||
suffix = f" exceeded {budget_s:.0f}s budget" if budget_s is not None else " exceeded budget"
|
||||
raise TimeoutError(f"{label}{suffix}")
|
||||
|
||||
|
||||
_T = TypeVar("_T")
|
||||
|
||||
|
||||
def retry_with_budget(
|
||||
fn: Callable[[], _T],
|
||||
*,
|
||||
transient: type[BaseException] | tuple[type[BaseException], ...],
|
||||
deadline: float,
|
||||
label: str,
|
||||
max_retries: int = DEFAULT_MAX_RETRIES,
|
||||
backoff: tuple[float, ...] = DEFAULT_BACKOFF,
|
||||
) -> _T:
|
||||
"""Call ``fn`` with a bounded retry budget on declared transient errors.
|
||||
|
||||
Between attempts sleeps ``min(backoff[attempt], remaining_budget)`` so a
|
||||
short remaining budget never spends the full backoff. The terminal
|
||||
transient failure — whether ``max_retries`` is exhausted OR the deadline
|
||||
has passed — is wrapped in :class:`TimeoutError`, preserving the original
|
||||
exception as ``__cause__``. Anything not in ``transient`` propagates
|
||||
unchanged on the first occurrence (we never retry an exception class
|
||||
the caller didn't opt in to).
|
||||
|
||||
Args:
|
||||
fn: Zero-arg callable producing the result.
|
||||
transient: Exception class(es) considered transient and retryable.
|
||||
deadline: ``time.monotonic()`` instant past which retries are aborted.
|
||||
label: Free-form label used in the TimeoutError message
|
||||
(e.g. ``"OKX fetch for BTC-USDT"``).
|
||||
max_retries: Additional attempts after the first call. Total
|
||||
attempts = ``max_retries + 1``.
|
||||
backoff: Per-retry sleep seconds. Must have at least
|
||||
``max_retries`` entries.
|
||||
|
||||
Returns:
|
||||
Whatever ``fn`` returns.
|
||||
|
||||
Raises:
|
||||
ValueError: ``backoff`` is shorter than ``max_retries``.
|
||||
TimeoutError: All retries exhausted or the deadline crossed.
|
||||
Any non-transient exception: Propagated unchanged from ``fn``.
|
||||
"""
|
||||
if len(backoff) < max_retries:
|
||||
raise ValueError(
|
||||
f"backoff has {len(backoff)} entries; need >= max_retries ({max_retries})"
|
||||
)
|
||||
for attempt in range(max_retries + 1):
|
||||
try:
|
||||
return fn()
|
||||
except transient as exc:
|
||||
remaining = deadline - time.monotonic()
|
||||
if attempt == max_retries or remaining <= 0:
|
||||
raise TimeoutError(
|
||||
f"{label} failed after {attempt + 1} attempt(s): {exc}"
|
||||
) from exc
|
||||
time.sleep(min(backoff[attempt], max(0.0, remaining)))
|
||||
raise AssertionError("unreachable: retry loop must return or raise") # pragma: no cover
|
||||
|
||||
|
||||
@runtime_checkable
|
||||
class DataLoaderProtocol(Protocol):
|
||||
"""Interface that every data source loader must satisfy."""
|
||||
|
||||
@@ -9,10 +9,16 @@ from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import os
|
||||
import time
|
||||
from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import (
|
||||
check_budget,
|
||||
retry_with_budget,
|
||||
validate_date_range,
|
||||
)
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -22,6 +28,14 @@ _INTERVAL_MAP = {
|
||||
"1H": "1h", "4H": "4h", "1D": "1d",
|
||||
}
|
||||
|
||||
# P12-b: ccxt had no request timeout and an unbounded paginated fetch with
|
||||
# no retry budget, so a transient disconnect hung get_market_data for 10+
|
||||
# minutes. Cap each HTTP call, bound transient retries, and enforce a hard
|
||||
# wall-clock budget so the fetch fails fast instead of hanging. Retry
|
||||
# scheduling is delegated to :mod:`backtest.loaders.base`.
|
||||
_CCXT_TIMEOUT_MS = int(os.getenv("CCXT_TIMEOUT_MS", "15000"))
|
||||
_CCXT_FETCH_BUDGET_S = float(os.getenv("CCXT_FETCH_BUDGET_S", "60"))
|
||||
|
||||
|
||||
@register
|
||||
class DataLoader:
|
||||
@@ -50,7 +64,7 @@ class DataLoader:
|
||||
if exchange_cls is None:
|
||||
logger.warning("Unknown CCXT exchange %s, falling back to binance", exchange_id)
|
||||
exchange_cls = ccxt.binance
|
||||
return exchange_cls({"enableRateLimit": True})
|
||||
return exchange_cls({"enableRateLimit": True, "timeout": _CCXT_TIMEOUT_MS})
|
||||
|
||||
def fetch(
|
||||
self,
|
||||
@@ -73,6 +87,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping symbol -> OHLCV DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
exchange = self._get_exchange()
|
||||
timeframe = _INTERVAL_MAP.get(interval, "1d")
|
||||
since_ms = int(pd.Timestamp(start_date).timestamp() * 1000)
|
||||
@@ -94,12 +110,25 @@ class DataLoader:
|
||||
exchange, symbol: str, timeframe: str, since_ms: int, end_ms: int,
|
||||
) -> Optional[pd.DataFrame]:
|
||||
"""Paginated OHLCV fetch for one symbol."""
|
||||
import ccxt
|
||||
|
||||
all_rows: list = []
|
||||
cursor = since_ms
|
||||
limit = 1000
|
||||
deadline = time.monotonic() + _CCXT_FETCH_BUDGET_S
|
||||
label = f"ccxt fetch for {symbol}"
|
||||
|
||||
for _ in range(200):
|
||||
ohlcv = exchange.fetch_ohlcv(symbol, timeframe, since=cursor, limit=limit)
|
||||
check_budget(deadline, label, budget_s=_CCXT_FETCH_BUDGET_S)
|
||||
# ``ccxt.NetworkError`` covers RequestTimeout / DDoSProtection /
|
||||
# ExchangeNotAvailable — the transient family. Anything else
|
||||
# (e.g. ``ExchangeError`` for a bad symbol) is not retried.
|
||||
ohlcv = retry_with_budget(
|
||||
lambda: exchange.fetch_ohlcv(symbol, timeframe, since=cursor, limit=limit),
|
||||
transient=ccxt.NetworkError,
|
||||
deadline=deadline,
|
||||
label=label,
|
||||
)
|
||||
if not ohlcv:
|
||||
break
|
||||
all_rows.extend(ohlcv)
|
||||
|
||||
@@ -0,0 +1,163 @@
|
||||
"""Futu OpenAPI-backed loader for HK and China A-share OHLCV data."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import os
|
||||
from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import NoAvailableSourceError, validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_OHLCV_COLUMNS = ["open", "high", "low", "close", "volume"]
|
||||
|
||||
_INTERVAL_MAP: dict[str, str] = {
|
||||
"1D": "K_DAY",
|
||||
"1H": "K_60M",
|
||||
"4H": "K_240M",
|
||||
"1W": "K_WEEK",
|
||||
"1M": "K_MON",
|
||||
}
|
||||
|
||||
|
||||
def _to_futu_symbol(code: str) -> str:
|
||||
"""Convert project symbol to Futu OpenAPI format.
|
||||
|
||||
Examples:
|
||||
700.HK -> HK.00700
|
||||
5.HK -> HK.00005
|
||||
000001.SZ -> SZ.000001
|
||||
600519.SH -> SH.600519
|
||||
"""
|
||||
upper = code.strip().upper()
|
||||
if upper.endswith(".HK"):
|
||||
return f"HK.{upper[:-3].zfill(5)}"
|
||||
if upper.endswith(".SZ"):
|
||||
return f"SZ.{upper[:-3].zfill(6)}"
|
||||
if upper.endswith(".SH"):
|
||||
return f"SH.{upper[:-3].zfill(6)}"
|
||||
return upper
|
||||
|
||||
|
||||
def _to_futu_ktype(interval: str):
|
||||
"""Map project interval string to a futu KLType enum value.
|
||||
|
||||
Lazy-imports futu so the module can be imported without futu installed.
|
||||
Unknown intervals fall back to K_DAY.
|
||||
"""
|
||||
from futu import KLType # noqa: PLC0415
|
||||
return getattr(KLType, _INTERVAL_MAP.get(interval.strip(), "K_DAY"))
|
||||
|
||||
|
||||
def _normalize_frame(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Normalise a Futu kline DataFrame to the standard OHLCV schema.
|
||||
|
||||
Args:
|
||||
df: Raw DataFrame returned by ``request_history_kline()``.
|
||||
|
||||
Returns:
|
||||
DataFrame with columns [open, high, low, close, volume] indexed
|
||||
by ``trade_date`` (timezone-naive DatetimeIndex), sorted ascending.
|
||||
"""
|
||||
if df.empty:
|
||||
return pd.DataFrame(columns=_OHLCV_COLUMNS)
|
||||
|
||||
result = df.copy()
|
||||
result.index = pd.to_datetime(result["time_key"])
|
||||
result.index.name = "trade_date"
|
||||
result = result[_OHLCV_COLUMNS].copy()
|
||||
result = result.apply(pd.to_numeric, errors="coerce")
|
||||
result["volume"] = result["volume"].fillna(0.0)
|
||||
result = result.dropna(subset=["open", "high", "low", "close"])
|
||||
return result.sort_index()
|
||||
|
||||
|
||||
@register
|
||||
class FutuLoader:
|
||||
"""Fetch HK and China A-share bars from Futu OpenAPI.
|
||||
|
||||
Requires FutuOpenD running locally (https://www.futunn.com/download/openAPI)
|
||||
and the environment variables ``FUTU_HOST`` / ``FUTU_PORT`` to be set.
|
||||
"""
|
||||
|
||||
name = "futu"
|
||||
markets = {"hk_equity", "a_share"}
|
||||
requires_auth = True
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._host = os.environ.get("FUTU_HOST", "127.0.0.1")
|
||||
self._port = int(os.environ.get("FUTU_PORT", "11111"))
|
||||
|
||||
def is_available(self) -> bool:
|
||||
"""Return True if env vars are set and FutuOpenD is reachable."""
|
||||
if not os.environ.get("FUTU_HOST") or not os.environ.get("FUTU_PORT"):
|
||||
return False
|
||||
try:
|
||||
import futu # noqa: PLC0415
|
||||
ctx = futu.OpenQuoteContext(host=self._host, port=self._port)
|
||||
ctx.close()
|
||||
return True
|
||||
except Exception:
|
||||
return False
|
||||
|
||||
def fetch(
|
||||
self,
|
||||
codes: List[str],
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
*,
|
||||
interval: str = "1D",
|
||||
fields: Optional[List[str]] = None,
|
||||
) -> Dict[str, pd.DataFrame]:
|
||||
"""Fetch OHLCV history from Futu OpenAPI.
|
||||
|
||||
Args:
|
||||
codes: Project symbols such as ``700.HK`` or ``000001.SZ``.
|
||||
start_date: Start date in ``YYYY-MM-DD`` format.
|
||||
end_date: End date in ``YYYY-MM-DD`` format.
|
||||
interval: Backtest interval — ``1D``, ``1H``, or ``4H``.
|
||||
fields: Ignored; included for interface compatibility.
|
||||
|
||||
Returns:
|
||||
Mapping of input symbol to normalised OHLCV dataframe.
|
||||
|
||||
Raises:
|
||||
NoAvailableSourceError: If FutuOpenD connection fails.
|
||||
"""
|
||||
del fields
|
||||
if not codes:
|
||||
return {}
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
try:
|
||||
import futu # noqa: PLC0415
|
||||
ktype = _to_futu_ktype(interval)
|
||||
ctx = futu.OpenQuoteContext(host=self._host, port=self._port)
|
||||
except Exception as exc:
|
||||
raise NoAvailableSourceError(
|
||||
f"Cannot connect to FutuOpenD at {self._host}:{self._port}: {exc}"
|
||||
) from exc
|
||||
|
||||
results: Dict[str, pd.DataFrame] = {}
|
||||
try:
|
||||
for code in codes:
|
||||
futu_code = _to_futu_symbol(code)
|
||||
ret, data = ctx.request_history_kline(
|
||||
futu_code,
|
||||
start=start_date,
|
||||
end=end_date,
|
||||
ktype=ktype,
|
||||
max_count=10_000,
|
||||
)
|
||||
if ret != futu.RET_OK:
|
||||
logger.warning("Futu returned error for %s: %s", futu_code, data)
|
||||
continue
|
||||
results[code] = _normalize_frame(data)
|
||||
finally:
|
||||
ctx.close()
|
||||
|
||||
return results
|
||||
@@ -5,15 +5,28 @@ Supports 1m/5m/15m/30m/1H/4H/1D.
|
||||
Up to 300 bars per request; paginates with ``after`` for longer history.
|
||||
"""
|
||||
|
||||
import os
|
||||
import time
|
||||
from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
import requests
|
||||
|
||||
from backtest.loaders.base import (
|
||||
check_budget,
|
||||
retry_with_budget,
|
||||
validate_date_range,
|
||||
)
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
BASE_URL = "https://www.okx.com/api/v5"
|
||||
_MAX_PER_PAGE = 300
|
||||
# P12-b parity: OKX already sets a per-request timeout but had no retry
|
||||
# budget, so a transient blip dropped the whole symbol and a slow tier
|
||||
# could stall ~max_pages*timeout. Bound it like the ccxt loader; retry
|
||||
# scheduling is delegated to :mod:`backtest.loaders.base`.
|
||||
_OKX_TIMEOUT = int(os.getenv("OKX_TIMEOUT_S", "15"))
|
||||
_OKX_FETCH_BUDGET_S = float(os.getenv("OKX_FETCH_BUDGET_S", "60"))
|
||||
|
||||
|
||||
@register
|
||||
@@ -52,6 +65,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping symbol -> DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
if fields:
|
||||
print(f"[WARN] OKX ignores extra fields: {fields}")
|
||||
|
||||
@@ -95,16 +110,32 @@ class DataLoader:
|
||||
"""
|
||||
all_rows: list = []
|
||||
after = str(end_ts)
|
||||
deadline = time.monotonic() + _OKX_FETCH_BUDGET_S
|
||||
label = f"OKX fetch for {inst_id}"
|
||||
|
||||
for _ in range(max_pages):
|
||||
check_budget(deadline, label, budget_s=_OKX_FETCH_BUDGET_S)
|
||||
params = {
|
||||
"instId": inst_id,
|
||||
"bar": bar,
|
||||
"limit": str(_MAX_PER_PAGE),
|
||||
"after": after,
|
||||
}
|
||||
resp = requests.get(f"{BASE_URL}/market/candles", params=params, timeout=15)
|
||||
data = resp.json()
|
||||
|
||||
def _do_request() -> dict:
|
||||
resp = requests.get(
|
||||
f"{BASE_URL}/market/candles",
|
||||
params=params,
|
||||
timeout=_OKX_TIMEOUT,
|
||||
)
|
||||
return resp.json()
|
||||
|
||||
data = retry_with_budget(
|
||||
_do_request,
|
||||
transient=requests.RequestException,
|
||||
deadline=deadline,
|
||||
label=label,
|
||||
)
|
||||
if data.get("code") != "0" or not data.get("data"):
|
||||
break
|
||||
|
||||
|
||||
@@ -52,6 +52,7 @@ def _ensure_registered() -> None:
|
||||
"backtest.loaders.yfinance_loader",
|
||||
"backtest.loaders.akshare_loader",
|
||||
"backtest.loaders.ccxt_loader",
|
||||
"backtest.loaders.futu",
|
||||
]
|
||||
import importlib
|
||||
for mod in _loader_modules:
|
||||
@@ -68,7 +69,7 @@ def _ensure_registered() -> None:
|
||||
FALLBACK_CHAINS: dict[str, list[str]] = {
|
||||
"a_share": ["tushare", "akshare"],
|
||||
"us_equity": ["yfinance", "akshare"],
|
||||
"hk_equity": ["yfinance", "akshare"],
|
||||
"hk_equity": ["yfinance", "futu", "akshare"],
|
||||
"crypto": ["okx", "ccxt"],
|
||||
"futures": ["tushare", "akshare"],
|
||||
"fund": ["tushare", "akshare"],
|
||||
@@ -98,8 +99,15 @@ def resolve_loader(market: str) -> Any:
|
||||
for name in chain:
|
||||
if name not in LOADER_REGISTRY:
|
||||
continue
|
||||
loader = LOADER_REGISTRY[name]()
|
||||
tried.append(name)
|
||||
# Issue #50 — some loaders (e.g. Tushare) call into the SDK during
|
||||
# __init__ and raise on missing credentials. Treat that the same as
|
||||
# is_available()=False so the fallback chain keeps walking.
|
||||
try:
|
||||
loader = LOADER_REGISTRY[name]()
|
||||
except Exception as exc:
|
||||
logger.debug("loader %s failed to construct: %s", name, exc)
|
||||
continue
|
||||
if loader.is_available():
|
||||
return loader
|
||||
raise NoAvailableSourceError(
|
||||
@@ -125,8 +133,12 @@ def get_loader_cls_with_fallback(source: str) -> Type[Any]:
|
||||
raise NoAvailableSourceError(f"Unknown data source: {source}")
|
||||
|
||||
loader_cls = LOADER_REGISTRY[source]
|
||||
instance = loader_cls()
|
||||
if instance.is_available():
|
||||
try:
|
||||
instance = loader_cls()
|
||||
except Exception as exc:
|
||||
logger.debug("loader %s failed to construct: %s", source, exc)
|
||||
instance = None
|
||||
if instance is not None and instance.is_available():
|
||||
return loader_cls
|
||||
|
||||
# Source unavailable — try same-market fallback
|
||||
|
||||
@@ -9,9 +9,13 @@ from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
|
||||
TUSHARE_TOKEN_PLACEHOLDERS = {"", "your-tushare-token"}
|
||||
|
||||
|
||||
@register
|
||||
class DataLoader:
|
||||
"""Tushare-backed OHLCV loader."""
|
||||
@@ -22,7 +26,7 @@ class DataLoader:
|
||||
|
||||
def is_available(self) -> bool:
|
||||
"""Available when TUSHARE_TOKEN is set."""
|
||||
return bool(os.getenv("TUSHARE_TOKEN", ""))
|
||||
return os.getenv("TUSHARE_TOKEN", "").strip() not in TUSHARE_TOKEN_PLACEHOLDERS
|
||||
|
||||
def __init__(self) -> None:
|
||||
"""Initialize Tushare pro API."""
|
||||
@@ -51,6 +55,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping code -> OHLCV DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
if interval != "1D":
|
||||
return self._fetch_minutes(codes, start_date, end_date, interval)
|
||||
|
||||
|
||||
@@ -0,0 +1,286 @@
|
||||
"""Tushare fundamental data provider with point-in-time safeguards."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Iterable
|
||||
|
||||
import pandas as pd
|
||||
|
||||
TUSHARE_TOKEN_PLACEHOLDERS = {"", "your-tushare-token"}
|
||||
|
||||
|
||||
class DataProviderError(Exception):
|
||||
"""Base error for fundamental provider failures."""
|
||||
|
||||
|
||||
class UnknownTableError(DataProviderError):
|
||||
"""Raised when a requested fundamental table is not supported."""
|
||||
|
||||
|
||||
class SchemaValidationError(DataProviderError):
|
||||
"""Raised when provider output is missing required columns."""
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ColumnSchema:
|
||||
"""Machine-readable column metadata for a provider table."""
|
||||
|
||||
name: str
|
||||
dtype: str
|
||||
required: bool = False
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class TableSchema:
|
||||
"""Machine-readable metadata for a Tushare fundamental table."""
|
||||
|
||||
name: str
|
||||
api_name: str
|
||||
point_in_time_column: str
|
||||
columns: tuple[ColumnSchema, ...]
|
||||
|
||||
@property
|
||||
def required_columns(self) -> tuple[str, ...]:
|
||||
return tuple(column.name for column in self.columns if column.required)
|
||||
|
||||
|
||||
_SCHEMAS: dict[str, TableSchema] = {
|
||||
"balancesheet": TableSchema(
|
||||
name="balancesheet",
|
||||
api_name="balancesheet",
|
||||
point_in_time_column="f_ann_date",
|
||||
columns=(
|
||||
ColumnSchema("ts_code", "str", required=True),
|
||||
ColumnSchema("ann_date", "date", required=True),
|
||||
ColumnSchema("f_ann_date", "date", required=False),
|
||||
ColumnSchema("end_date", "date", required=True),
|
||||
ColumnSchema("total_assets", "float"),
|
||||
ColumnSchema("total_liab", "float"),
|
||||
ColumnSchema("total_hldr_eqy_exc_min_int", "float"),
|
||||
),
|
||||
),
|
||||
"cashflow": TableSchema(
|
||||
name="cashflow",
|
||||
api_name="cashflow",
|
||||
point_in_time_column="f_ann_date",
|
||||
columns=(
|
||||
ColumnSchema("ts_code", "str", required=True),
|
||||
ColumnSchema("ann_date", "date", required=True),
|
||||
ColumnSchema("f_ann_date", "date", required=False),
|
||||
ColumnSchema("end_date", "date", required=True),
|
||||
ColumnSchema("net_profit", "float"),
|
||||
ColumnSchema("n_cashflow_act", "float"),
|
||||
ColumnSchema("c_cash_equ_end_period", "float"),
|
||||
),
|
||||
),
|
||||
"fina_indicator": TableSchema(
|
||||
name="fina_indicator",
|
||||
api_name="fina_indicator",
|
||||
point_in_time_column="ann_date",
|
||||
columns=(
|
||||
ColumnSchema("ts_code", "str", required=True),
|
||||
ColumnSchema("ann_date", "date", required=True),
|
||||
ColumnSchema("end_date", "date", required=True),
|
||||
ColumnSchema("eps", "float"),
|
||||
ColumnSchema("grossprofit_margin", "float"),
|
||||
ColumnSchema("netprofit_margin", "float"),
|
||||
ColumnSchema("roe", "float"),
|
||||
ColumnSchema("debt_to_assets", "float"),
|
||||
),
|
||||
),
|
||||
"income": TableSchema(
|
||||
name="income",
|
||||
api_name="income",
|
||||
point_in_time_column="f_ann_date",
|
||||
columns=(
|
||||
ColumnSchema("ts_code", "str", required=True),
|
||||
ColumnSchema("ann_date", "date", required=True),
|
||||
ColumnSchema("f_ann_date", "date", required=False),
|
||||
ColumnSchema("end_date", "date", required=True),
|
||||
ColumnSchema("total_revenue", "float"),
|
||||
ColumnSchema("revenue", "float"),
|
||||
ColumnSchema("operate_profit", "float"),
|
||||
ColumnSchema("n_income", "float"),
|
||||
),
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
class TushareFundamentalProvider:
|
||||
"""Small DataProvider contract for Tushare financial statement tables."""
|
||||
|
||||
def __init__(self, api: Any | None = None) -> None:
|
||||
if api is None:
|
||||
import tushare as ts
|
||||
|
||||
token = os.getenv("TUSHARE_TOKEN", "").strip()
|
||||
if token in TUSHARE_TOKEN_PLACEHOLDERS:
|
||||
token = ""
|
||||
api = ts.pro_api(token)
|
||||
self.api = api
|
||||
|
||||
def list_tables(self) -> list[str]:
|
||||
"""Return supported fundamental tables in stable order."""
|
||||
return sorted(_SCHEMAS)
|
||||
|
||||
def describe_table(self, table: str) -> TableSchema:
|
||||
"""Return schema metadata for a supported table."""
|
||||
try:
|
||||
return _SCHEMAS[table]
|
||||
except KeyError as exc:
|
||||
raise UnknownTableError(f"Unsupported Tushare fundamental table: {table}") from exc
|
||||
|
||||
def query_fundamentals(
|
||||
self,
|
||||
table: str,
|
||||
codes: Iterable[str],
|
||||
*,
|
||||
as_of: str | pd.Timestamp,
|
||||
periods: Iterable[str] | None = None,
|
||||
fields: Iterable[str] | None = None,
|
||||
) -> pd.DataFrame:
|
||||
"""Query a fundamental table and filter out rows unpublished by ``as_of``."""
|
||||
schema = self.describe_table(table)
|
||||
requested_periods = set(periods or [])
|
||||
frames: list[pd.DataFrame] = []
|
||||
|
||||
api_method = getattr(self.api, schema.api_name, None)
|
||||
if api_method is None:
|
||||
raise DataProviderError(f"Tushare API object has no method: {schema.api_name}")
|
||||
|
||||
for code in codes:
|
||||
frame = api_method(ts_code=code, period=None)
|
||||
if frame is not None and not frame.empty:
|
||||
frames.append(frame.copy())
|
||||
|
||||
if not frames:
|
||||
return self._empty_frame(schema, fields)
|
||||
|
||||
result = pd.concat(frames, ignore_index=True)
|
||||
self._validate_schema(schema, result)
|
||||
|
||||
if requested_periods:
|
||||
result = result[result["end_date"].astype(str).isin(requested_periods)]
|
||||
|
||||
pit_column = schema.point_in_time_column
|
||||
if pit_column not in result.columns or result[pit_column].isna().all():
|
||||
pit_column = "ann_date"
|
||||
as_of_date = _parse_tushare_date(as_of)
|
||||
pit_values = result[pit_column]
|
||||
if pit_column != "ann_date" and "ann_date" in result.columns:
|
||||
pit_values = pit_values.where(pit_values.notna(), result["ann_date"])
|
||||
pit_dates = pit_values.map(_parse_tushare_date)
|
||||
result = result[pit_dates <= as_of_date]
|
||||
|
||||
output_columns = self._output_columns(schema, result, fields)
|
||||
result = result.loc[:, output_columns].sort_values(["ts_code", "end_date"]).reset_index(drop=True)
|
||||
return result
|
||||
|
||||
def _validate_schema(self, schema: TableSchema, frame: pd.DataFrame) -> None:
|
||||
missing = [column for column in schema.required_columns if column not in frame.columns]
|
||||
if missing:
|
||||
raise SchemaValidationError(f"{schema.name} missing required columns: {', '.join(missing)}")
|
||||
|
||||
def _output_columns(
|
||||
self,
|
||||
schema: TableSchema,
|
||||
frame: pd.DataFrame,
|
||||
fields: Iterable[str] | None,
|
||||
) -> list[str]:
|
||||
identity = ["ts_code", "end_date", "ann_date"]
|
||||
if schema.point_in_time_column in frame.columns and schema.point_in_time_column not in identity:
|
||||
identity.append(schema.point_in_time_column)
|
||||
wanted = identity + list(fields or [])
|
||||
return [column for column in dict.fromkeys(wanted) if column in frame.columns]
|
||||
|
||||
def _empty_frame(self, schema: TableSchema, fields: Iterable[str] | None) -> pd.DataFrame:
|
||||
columns = self._output_columns(schema, pd.DataFrame(columns=[c.name for c in schema.columns]), fields)
|
||||
return pd.DataFrame(columns=columns)
|
||||
|
||||
|
||||
def _parse_tushare_date(value: str | pd.Timestamp) -> pd.Timestamp:
|
||||
"""Parse Tushare YYYYMMDD strings and common timestamp/date strings."""
|
||||
if isinstance(value, pd.Timestamp):
|
||||
return value.normalize()
|
||||
text = str(value)
|
||||
if len(text) == 8 and text.isdigit():
|
||||
return pd.to_datetime(text, format="%Y%m%d")
|
||||
return pd.to_datetime(text).normalize()
|
||||
|
||||
|
||||
def enrich_price_frames_with_fundamentals(
|
||||
data_map: dict[str, pd.DataFrame],
|
||||
provider: TushareFundamentalProvider,
|
||||
fields_by_table: dict[str, Iterable[str]],
|
||||
*,
|
||||
as_of: str | pd.Timestamp,
|
||||
periods: Iterable[str] | None = None,
|
||||
) -> dict[str, pd.DataFrame]:
|
||||
"""Attach PIT-safe fundamental snapshots to daily price frames.
|
||||
|
||||
Fundamental columns are prefixed with their table name, for example
|
||||
``income_total_revenue`` and ``fina_indicator_roe``. Each row becomes
|
||||
visible only on or after its announcement/disclosure date.
|
||||
"""
|
||||
if not data_map or not fields_by_table:
|
||||
return data_map
|
||||
|
||||
enriched = {code: frame.copy() for code, frame in data_map.items()}
|
||||
codes = list(enriched)
|
||||
|
||||
for table, fields in fields_by_table.items():
|
||||
field_list = list(fields or [])
|
||||
fundamentals = provider.query_fundamentals(
|
||||
table,
|
||||
codes,
|
||||
as_of=as_of,
|
||||
periods=periods,
|
||||
fields=field_list,
|
||||
)
|
||||
if fundamentals.empty:
|
||||
continue
|
||||
|
||||
schema = provider.describe_table(table)
|
||||
pit_column = schema.point_in_time_column
|
||||
if pit_column not in fundamentals.columns or fundamentals[pit_column].isna().all():
|
||||
pit_column = "ann_date"
|
||||
|
||||
for code, frame in enriched.items():
|
||||
rows = fundamentals[fundamentals["ts_code"] == code].copy()
|
||||
if rows.empty or frame.empty:
|
||||
continue
|
||||
|
||||
pit_values = rows[pit_column]
|
||||
if pit_column != "ann_date" and "ann_date" in rows.columns:
|
||||
pit_values = pit_values.where(pit_values.notna(), rows["ann_date"])
|
||||
rows["_pit_date"] = pit_values.map(_parse_tushare_date)
|
||||
rows = rows.dropna(subset=["_pit_date"]).sort_values("_pit_date")
|
||||
if rows.empty:
|
||||
continue
|
||||
|
||||
value_columns = [column for column in rows.columns if column not in {"ts_code", "_pit_date"}]
|
||||
right = rows[["_pit_date", *value_columns]].rename(
|
||||
columns={column: f"{table}_{column}" for column in value_columns}
|
||||
)
|
||||
|
||||
left = frame.copy()
|
||||
original_index = left.index
|
||||
left["_trade_date"] = pd.to_datetime(left.index).normalize()
|
||||
left["_original_order"] = range(len(left))
|
||||
|
||||
merged = pd.merge_asof(
|
||||
left.sort_values("_trade_date"),
|
||||
right.sort_values("_pit_date"),
|
||||
left_on="_trade_date",
|
||||
right_on="_pit_date",
|
||||
direction="backward",
|
||||
)
|
||||
merged = merged.sort_values("_original_order").drop(
|
||||
columns=["_trade_date", "_original_order", "_pit_date"]
|
||||
)
|
||||
merged.index = original_index
|
||||
enriched[code] = merged
|
||||
|
||||
return enriched
|
||||
@@ -8,6 +8,7 @@ from typing import Dict, List, Optional, Union
|
||||
import pandas as pd
|
||||
import yfinance as yf
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
_OHLCV_COLUMNS = ["open", "high", "low", "close", "volume"]
|
||||
@@ -230,6 +231,7 @@ class DataLoader:
|
||||
del fields
|
||||
if not codes:
|
||||
return {}
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
requested_interval = str(interval or "1D").strip()
|
||||
yf_interval = _to_yfinance_interval(requested_interval)
|
||||
|
||||
@@ -147,7 +147,7 @@ def calc_metrics(
|
||||
equity_curve: pd.Series,
|
||||
trades: List[TradeRecord],
|
||||
initial_cash: float,
|
||||
bars_per_year: int = 252,
|
||||
bars_per_year: Optional[int] = 252,
|
||||
bench_ret: Optional[pd.Series] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""Full set of performance metrics.
|
||||
@@ -156,7 +156,8 @@ def calc_metrics(
|
||||
equity_curve: Equity time series (index=timestamp, values=equity).
|
||||
trades: Completed round-trip trades.
|
||||
initial_cash: Starting capital.
|
||||
bars_per_year: Bars per year for annualisation.
|
||||
bars_per_year: Bars per year for annualisation. None = auto-detect
|
||||
from equity curve dates (calendar-day method, for cross-market).
|
||||
bench_ret: Benchmark per-bar return series (optional).
|
||||
|
||||
Returns:
|
||||
@@ -166,7 +167,15 @@ def calc_metrics(
|
||||
return _empty_metrics(initial_cash)
|
||||
|
||||
n = len(equity_curve)
|
||||
bpy = bars_per_year
|
||||
|
||||
# Calendar-day annualization for cross-market (bars_per_year=None)
|
||||
if bars_per_year is None:
|
||||
first, last = equity_curve.index[0], equity_curve.index[-1]
|
||||
calendar_days = (last - first).days
|
||||
years = calendar_days / 365.25 if calendar_days > 0 else 1.0
|
||||
bpy = int(n / years) if years > 0 else 252
|
||||
else:
|
||||
bpy = bars_per_year
|
||||
|
||||
port_ret = equity_curve.pct_change().fillna(0.0)
|
||||
|
||||
|
||||
@@ -0,0 +1,200 @@
|
||||
"""Trust Layer run card generator for backtest runs."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import json
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from typing import Any, Mapping, Sequence
|
||||
|
||||
|
||||
SCHEMA_VERSION = "0.1"
|
||||
BACKTEST_SUMMARY_KEYS = (
|
||||
"codes",
|
||||
"start_date",
|
||||
"end_date",
|
||||
"interval",
|
||||
"engine",
|
||||
"initial_cash",
|
||||
"source",
|
||||
)
|
||||
|
||||
|
||||
def write_run_card(
|
||||
run_dir: Path,
|
||||
config: Mapping[str, Any],
|
||||
metrics: Mapping[str, Any],
|
||||
*,
|
||||
data_sources: Sequence[str] | None = None,
|
||||
strategy_path: Path | None = None,
|
||||
warnings: Sequence[str] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
"""Write JSON and Markdown run cards for a backtest run.
|
||||
|
||||
Args:
|
||||
run_dir: Directory where run_card.json and run_card.md are written.
|
||||
config: Full backtest configuration. Only a summary and hash are stored.
|
||||
metrics: Backtest metrics. Scalar values are stored; ``validation`` is
|
||||
stored separately when present.
|
||||
data_sources: Data sources used by the run.
|
||||
strategy_path: Optional strategy source file to hash for reproducibility.
|
||||
warnings: Optional warnings to include in the card.
|
||||
|
||||
Returns:
|
||||
The run card payload written to ``run_card.json``.
|
||||
"""
|
||||
run_dir = Path(run_dir)
|
||||
run_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
config_file = run_dir / "config.json"
|
||||
reproducibility: dict[str, Any] = {
|
||||
"config_hash": _file_hash(config_file) if config_file.exists() else _json_hash(config),
|
||||
}
|
||||
if strategy_path is not None:
|
||||
strategy_file = Path(strategy_path)
|
||||
if strategy_file.exists() and strategy_file.is_file():
|
||||
reproducibility["strategy_hash"] = _file_hash(strategy_file)
|
||||
|
||||
card: dict[str, Any] = {
|
||||
"schema_version": SCHEMA_VERSION,
|
||||
"generated_at": _utc_now(),
|
||||
"run_dir": str(run_dir),
|
||||
"backtest": _backtest_summary(config),
|
||||
"reproducibility": reproducibility,
|
||||
"data_sources": list(data_sources or []),
|
||||
"metrics": _scalar_metrics(metrics),
|
||||
"warnings": list(warnings or []),
|
||||
"artifacts": _list_artifacts(run_dir),
|
||||
}
|
||||
if "validation" in metrics:
|
||||
card["validation"] = metrics["validation"]
|
||||
|
||||
json_path = run_dir / "run_card.json"
|
||||
md_path = run_dir / "run_card.md"
|
||||
json_path.write_text(
|
||||
json.dumps(card, ensure_ascii=False, indent=2, sort_keys=True, default=str) + "\n",
|
||||
encoding="utf-8",
|
||||
)
|
||||
md_path.write_text(_render_markdown(card), encoding="utf-8")
|
||||
return card
|
||||
|
||||
|
||||
def _utc_now() -> str:
|
||||
return datetime.now(timezone.utc).isoformat().replace("+00:00", "Z")
|
||||
|
||||
|
||||
def _json_hash(value: Mapping[str, Any]) -> str:
|
||||
payload = json.dumps(
|
||||
{key: val for key, val in value.items() if not str(key).startswith("_")},
|
||||
sort_keys=True,
|
||||
default=str,
|
||||
separators=(",", ":"),
|
||||
ensure_ascii=False,
|
||||
)
|
||||
return hashlib.sha256(payload.encode("utf-8")).hexdigest()
|
||||
|
||||
|
||||
def _file_hash(path: Path) -> str:
|
||||
digest = hashlib.sha256()
|
||||
with path.open("rb") as handle:
|
||||
for chunk in iter(lambda: handle.read(1024 * 1024), b""):
|
||||
digest.update(chunk)
|
||||
return digest.hexdigest()
|
||||
|
||||
|
||||
def _backtest_summary(config: Mapping[str, Any]) -> dict[str, Any]:
|
||||
return {key: config.get(key) for key in BACKTEST_SUMMARY_KEYS if key in config}
|
||||
|
||||
|
||||
def _scalar_metrics(metrics: Mapping[str, Any]) -> dict[str, Any]:
|
||||
return {
|
||||
key: value
|
||||
for key, value in metrics.items()
|
||||
if key != "validation" and _is_scalar(value)
|
||||
}
|
||||
|
||||
|
||||
def _is_scalar(value: Any) -> bool:
|
||||
return value is None or isinstance(value, (str, int, float, bool))
|
||||
|
||||
|
||||
def _list_artifacts(run_dir: Path) -> list[dict[str, Any]]:
|
||||
candidates: list[Path] = []
|
||||
for relative in (Path("config.json"), Path("code/signal_engine.py")):
|
||||
path = run_dir / relative
|
||||
if path.exists() and path.is_file():
|
||||
candidates.append(path)
|
||||
|
||||
artifacts_dir = run_dir / "artifacts"
|
||||
if artifacts_dir.exists() and artifacts_dir.is_dir():
|
||||
candidates.extend(path for path in artifacts_dir.rglob("*") if path.is_file())
|
||||
|
||||
artifacts = []
|
||||
for path in sorted(candidates, key=lambda item: item.relative_to(run_dir).as_posix()):
|
||||
artifacts.append(
|
||||
{
|
||||
"path": path.relative_to(run_dir).as_posix(),
|
||||
"size_bytes": path.stat().st_size,
|
||||
"sha256": _file_hash(path),
|
||||
}
|
||||
)
|
||||
return artifacts
|
||||
|
||||
|
||||
def _render_markdown(card: Mapping[str, Any]) -> str:
|
||||
lines = [
|
||||
"# Backtest Run Card",
|
||||
"",
|
||||
f"Generated: {card['generated_at']}",
|
||||
f"Run directory: `{card['run_dir']}`",
|
||||
"",
|
||||
"## Backtest Summary",
|
||||
]
|
||||
|
||||
backtest = card.get("backtest", {})
|
||||
if backtest:
|
||||
lines.extend(f"- {key}: {value}" for key, value in backtest.items())
|
||||
else:
|
||||
lines.append("- No backtest summary fields provided.")
|
||||
|
||||
lines.extend(["", "## Reproducibility"])
|
||||
reproducibility = card.get("reproducibility", {})
|
||||
lines.append(f"- config_hash: `{reproducibility.get('config_hash', '')}`")
|
||||
if "strategy_hash" in reproducibility:
|
||||
lines.append(f"- strategy_hash: `{reproducibility['strategy_hash']}`")
|
||||
|
||||
lines.extend(["", "## Data Sources"])
|
||||
data_sources = card.get("data_sources", [])
|
||||
lines.extend(f"- {source}" for source in data_sources) if data_sources else lines.append("- None recorded.")
|
||||
|
||||
lines.extend(["", "## Metrics"])
|
||||
metric_values = card.get("metrics", {})
|
||||
lines.extend(f"- {key}: {value}" for key, value in metric_values.items()) if metric_values else lines.append("- No scalar metrics recorded.")
|
||||
|
||||
lines.extend(["", "## Validation"])
|
||||
if "validation" in card:
|
||||
validation = card["validation"]
|
||||
if isinstance(validation, Mapping):
|
||||
lines.extend(f"- {key}: {value}" for key, value in validation.items())
|
||||
else:
|
||||
lines.append(f"- {validation}")
|
||||
else:
|
||||
lines.append("- Not present.")
|
||||
|
||||
warnings = card.get("warnings", [])
|
||||
if warnings:
|
||||
lines.extend(["", "## Warnings"])
|
||||
lines.extend(f"- {warning}" for warning in warnings)
|
||||
|
||||
lines.extend(["", "## Artifacts"])
|
||||
artifacts = card.get("artifacts", [])
|
||||
if artifacts:
|
||||
lines.extend(
|
||||
f"- `{artifact['path']}` ({artifact['size_bytes']} bytes, sha256 `{artifact['sha256']}`)"
|
||||
for artifact in artifacts
|
||||
)
|
||||
else:
|
||||
lines.append("- None found.")
|
||||
|
||||
return "\n".join(lines) + "\n"
|
||||
+271
-4
@@ -7,13 +7,17 @@ Supports ``engine`` for backtest engine (daily/options, default daily).
|
||||
Usage: ``python -m backtest.runner <run_dir>``
|
||||
"""
|
||||
|
||||
import ast
|
||||
import importlib.util
|
||||
import json
|
||||
import logging
|
||||
import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Dict, List
|
||||
from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
from pydantic import BaseModel, ConfigDict, model_validator, field_validator
|
||||
|
||||
try:
|
||||
from dotenv import load_dotenv
|
||||
@@ -22,6 +26,7 @@ except ImportError:
|
||||
pass
|
||||
|
||||
from backtest.loaders.registry import (
|
||||
FALLBACK_CHAINS,
|
||||
LOADER_REGISTRY,
|
||||
get_loader_cls_with_fallback,
|
||||
resolve_loader,
|
||||
@@ -30,6 +35,86 @@ from backtest.loaders.base import NoAvailableSourceError
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_VALID_INTERVALS = {"1m", "5m", "15m", "30m", "1H", "4H", "1D"}
|
||||
_VALID_ENGINES = {"daily", "options"}
|
||||
_VALID_SOURCES = {"tushare", "okx", "yfinance", "akshare", "ccxt", "auto"}
|
||||
|
||||
|
||||
class BacktestConfigSchema(BaseModel):
|
||||
"""Validates backtest config.json before execution."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
codes: List[str]
|
||||
start_date: str
|
||||
end_date: str
|
||||
source: str = "tushare"
|
||||
interval: str = "1D"
|
||||
engine: str = "daily"
|
||||
fundamental_fields: Optional[Dict[str, List[str]]] = None
|
||||
|
||||
@field_validator("codes")
|
||||
@classmethod
|
||||
def codes_not_empty(cls, v: List[str]) -> List[str]:
|
||||
if not v:
|
||||
raise ValueError("codes must be a non-empty list")
|
||||
if any(not c.strip() for c in v):
|
||||
raise ValueError("codes must not contain empty strings")
|
||||
return v
|
||||
|
||||
@field_validator("start_date", "end_date")
|
||||
@classmethod
|
||||
def valid_date(cls, v: str) -> str:
|
||||
try:
|
||||
pd.Timestamp(v)
|
||||
except Exception:
|
||||
raise ValueError(f"invalid date format: {v!r} (expected YYYY-MM-DD)")
|
||||
return v
|
||||
|
||||
@field_validator("interval")
|
||||
@classmethod
|
||||
def valid_interval(cls, v: str) -> str:
|
||||
if v not in _VALID_INTERVALS:
|
||||
raise ValueError(f"unsupported interval {v!r}, must be one of {_VALID_INTERVALS}")
|
||||
return v
|
||||
|
||||
@field_validator("engine")
|
||||
@classmethod
|
||||
def valid_engine(cls, v: str) -> str:
|
||||
if v not in _VALID_ENGINES:
|
||||
raise ValueError(f"unsupported engine {v!r}, must be one of {_VALID_ENGINES}")
|
||||
return v
|
||||
|
||||
@field_validator("source")
|
||||
@classmethod
|
||||
def valid_source(cls, v: str) -> str:
|
||||
if v not in _VALID_SOURCES:
|
||||
raise ValueError(f"unsupported source {v!r}, must be one of {_VALID_SOURCES}")
|
||||
return v
|
||||
|
||||
@field_validator("fundamental_fields")
|
||||
@classmethod
|
||||
def valid_fundamental_fields(
|
||||
cls,
|
||||
v: Optional[Dict[str, List[str]]],
|
||||
) -> Optional[Dict[str, List[str]]]:
|
||||
if v is None:
|
||||
return v
|
||||
for table, fields in v.items():
|
||||
if not table.strip():
|
||||
raise ValueError("fundamental_fields table names must be non-empty strings")
|
||||
if any(not field.strip() for field in fields):
|
||||
raise ValueError("fundamental_fields field names must be non-empty strings")
|
||||
return v
|
||||
|
||||
@model_validator(mode="after")
|
||||
def start_before_end(self) -> "BacktestConfigSchema":
|
||||
if pd.Timestamp(self.start_date) > pd.Timestamp(self.end_date):
|
||||
raise ValueError(
|
||||
f"start_date ({self.start_date}) must be <= end_date ({self.end_date})"
|
||||
)
|
||||
return self
|
||||
|
||||
|
||||
def _load_module_from_file(file_path: Path, module_name: str):
|
||||
"""Load a Python module from a file path via importlib.
|
||||
@@ -41,6 +126,7 @@ def _load_module_from_file(file_path: Path, module_name: str):
|
||||
Returns:
|
||||
Loaded module object.
|
||||
"""
|
||||
_validate_signal_engine_source(file_path)
|
||||
spec = importlib.util.spec_from_file_location(module_name, file_path)
|
||||
module = importlib.util.module_from_spec(spec)
|
||||
sys.modules[module_name] = module
|
||||
@@ -48,6 +134,111 @@ def _load_module_from_file(file_path: Path, module_name: str):
|
||||
return module
|
||||
|
||||
|
||||
def _is_literal_node(node: ast.AST) -> bool:
|
||||
"""Return whether an AST node is made only from literal values."""
|
||||
if isinstance(node, ast.Constant):
|
||||
return True
|
||||
if isinstance(node, (ast.Tuple, ast.List, ast.Set)):
|
||||
return all(_is_literal_node(item) for item in node.elts)
|
||||
if isinstance(node, ast.Dict):
|
||||
return all(
|
||||
(key is None or _is_literal_node(key)) and _is_literal_node(value)
|
||||
for key, value in zip(node.keys, node.values)
|
||||
)
|
||||
return False
|
||||
|
||||
|
||||
def _is_safe_constant_assignment(node: ast.AST) -> bool:
|
||||
"""Return whether a top-level assignment is literal-only."""
|
||||
if isinstance(node, ast.Assign):
|
||||
return _is_literal_node(node.value)
|
||||
if isinstance(node, ast.AnnAssign):
|
||||
return node.value is None or _is_literal_node(node.value)
|
||||
return False
|
||||
|
||||
|
||||
def _is_safe_reference(node: ast.AST | None) -> bool:
|
||||
"""Return whether an annotation/base expression cannot call code."""
|
||||
if node is None:
|
||||
return True
|
||||
if isinstance(node, (ast.Name, ast.Attribute, ast.Constant)):
|
||||
return True
|
||||
if isinstance(node, ast.Subscript):
|
||||
return _is_safe_reference(node.value) and _is_safe_reference(node.slice)
|
||||
if isinstance(node, ast.Tuple):
|
||||
return all(_is_safe_reference(item) for item in node.elts)
|
||||
if isinstance(node, ast.BinOp) and isinstance(node.op, ast.BitOr):
|
||||
return _is_safe_reference(node.left) and _is_safe_reference(node.right)
|
||||
return False
|
||||
|
||||
|
||||
def _validate_function_def(node: ast.FunctionDef | ast.AsyncFunctionDef) -> None:
|
||||
"""Reject import-time execution in function definitions."""
|
||||
if node.decorator_list:
|
||||
raise ValueError(f"Decorators are not allowed on function {node.name!r}")
|
||||
for default in [*node.args.defaults, *[d for d in node.args.kw_defaults if d]]:
|
||||
if not _is_literal_node(default):
|
||||
raise ValueError(f"Non-literal default is not allowed on function {node.name!r}")
|
||||
annotations = [node.returns]
|
||||
annotations.extend(arg.annotation for arg in node.args.posonlyargs)
|
||||
annotations.extend(arg.annotation for arg in node.args.args)
|
||||
annotations.extend(arg.annotation for arg in node.args.kwonlyargs)
|
||||
annotations.append(node.args.vararg.annotation if node.args.vararg else None)
|
||||
annotations.append(node.args.kwarg.annotation if node.args.kwarg else None)
|
||||
for annotation in annotations:
|
||||
if not _is_safe_reference(annotation):
|
||||
raise ValueError(f"Unsafe annotation is not allowed on function {node.name!r}")
|
||||
|
||||
|
||||
def _validate_class_body(node: ast.ClassDef) -> None:
|
||||
"""Reject import-time execution inside class bodies."""
|
||||
if node.decorator_list:
|
||||
raise ValueError(f"Decorators are not allowed on class {node.name!r}")
|
||||
for base in node.bases:
|
||||
if not _is_safe_reference(base):
|
||||
raise ValueError(f"Unsafe base class is not allowed on class {node.name!r}")
|
||||
if node.keywords:
|
||||
raise ValueError(f"Class keywords are not allowed on class {node.name!r}")
|
||||
for child in node.body:
|
||||
if isinstance(child, ast.Expr) and isinstance(child.value, ast.Constant):
|
||||
continue
|
||||
if isinstance(child, (ast.FunctionDef, ast.AsyncFunctionDef)):
|
||||
_validate_function_def(child)
|
||||
continue
|
||||
if _is_safe_constant_assignment(child):
|
||||
continue
|
||||
if isinstance(child, ast.Pass):
|
||||
continue
|
||||
raise ValueError(
|
||||
f"Executable class-level statement {type(child).__name__} is not allowed"
|
||||
)
|
||||
|
||||
|
||||
def _validate_signal_engine_source(file_path: Path) -> None:
|
||||
"""Reject import-time executable statements before loading signal_engine.py."""
|
||||
try:
|
||||
tree = ast.parse(file_path.read_text(encoding="utf-8"), filename=str(file_path))
|
||||
except SyntaxError as exc:
|
||||
raise ValueError(f"Invalid signal_engine.py syntax: {exc}") from exc
|
||||
|
||||
for node in tree.body:
|
||||
if isinstance(node, ast.Expr) and isinstance(node.value, ast.Constant):
|
||||
continue
|
||||
if isinstance(node, (ast.Import, ast.ImportFrom)):
|
||||
continue
|
||||
if isinstance(node, (ast.FunctionDef, ast.AsyncFunctionDef)):
|
||||
_validate_function_def(node)
|
||||
continue
|
||||
if isinstance(node, ast.ClassDef):
|
||||
_validate_class_body(node)
|
||||
continue
|
||||
if _is_safe_constant_assignment(node):
|
||||
continue
|
||||
raise ValueError(
|
||||
f"Executable top-level statement {type(node).__name__} is not allowed"
|
||||
)
|
||||
|
||||
|
||||
# --- Market detection (returns market type, NOT source name) ---
|
||||
|
||||
_MARKET_PATTERNS = [
|
||||
@@ -186,13 +377,40 @@ def main(run_dir: Path) -> None:
|
||||
|
||||
Args:
|
||||
run_dir: Run directory containing ``config.json`` and ``code/signal_engine.py``.
|
||||
The path is validated against the allowed run roots
|
||||
(``VIBE_TRADING_ALLOWED_RUN_ROOTS`` plus the defaults) before any
|
||||
file is read so an arbitrary filesystem location cannot be used
|
||||
to source ``code/signal_engine.py``.
|
||||
"""
|
||||
# Guard the CLI entry point with the same root whitelist the MCP
|
||||
# ``backtest`` tool already uses (src/tools/backtest_tool.py:23). Without
|
||||
# this, ``python -m backtest.runner /tmp/attacker_path`` would happily
|
||||
# import ``signal_engine.py`` from anywhere on disk; the AST scrubber
|
||||
# below blocks executable top-level statements but a method body still
|
||||
# runs on instantiation. See ``safe_run_dir`` for the policy.
|
||||
from src.tools.path_utils import safe_run_dir
|
||||
try:
|
||||
run_dir = safe_run_dir(str(run_dir))
|
||||
except ValueError as exc:
|
||||
print(json.dumps({"error": str(exc)}))
|
||||
sys.exit(1)
|
||||
|
||||
config_path = run_dir / "config.json"
|
||||
if not config_path.exists():
|
||||
print(json.dumps({"error": "config.json not found"}))
|
||||
sys.exit(1)
|
||||
|
||||
config = json.loads(config_path.read_text(encoding="utf-8"))
|
||||
raw_config = json.loads(config_path.read_text(encoding="utf-8"))
|
||||
|
||||
# Validate config schema
|
||||
try:
|
||||
BacktestConfigSchema(**raw_config)
|
||||
except Exception as exc:
|
||||
errors = str(exc)
|
||||
print(json.dumps({"error": f"Invalid config: {errors}"}))
|
||||
sys.exit(1)
|
||||
|
||||
config = raw_config
|
||||
source = config.get("source", "tushare")
|
||||
codes = config.get("codes", [])
|
||||
|
||||
@@ -225,10 +443,34 @@ def main(run_dir: Path) -> None:
|
||||
fields=config.get("extra_fields") or None,
|
||||
interval=interval,
|
||||
)
|
||||
# Runtime fallback: try next sources in chain when primary returns empty
|
||||
if not data_map and codes:
|
||||
market = _detect_market(codes[0])
|
||||
for fb_name in FALLBACK_CHAINS.get(market, []):
|
||||
if fb_name == source or fb_name not in LOADER_REGISTRY:
|
||||
continue
|
||||
fb_loader = LOADER_REGISTRY[fb_name]()
|
||||
if not fb_loader.is_available():
|
||||
continue
|
||||
fb_codes = _normalize_codes(codes, fb_name)
|
||||
data_map = fb_loader.fetch(
|
||||
fb_codes, config.get("start_date", ""),
|
||||
config.get("end_date", ""), interval=interval,
|
||||
)
|
||||
if data_map:
|
||||
logger.info("Runtime fallback: %s -> %s", source, fb_name)
|
||||
source = fb_name
|
||||
loader = fb_loader
|
||||
break
|
||||
if not data_map:
|
||||
print(json.dumps({"error": "No data fetched"}))
|
||||
sys.exit(1)
|
||||
|
||||
if source == "auto":
|
||||
config["_run_card_effective_sources"] = sorted(_group_codes_by_source(codes))
|
||||
else:
|
||||
config["_run_card_effective_sources"] = [source]
|
||||
|
||||
# Engine
|
||||
engine_type = config.get("engine", "daily")
|
||||
signal_engine = engine_cls()
|
||||
@@ -236,7 +478,12 @@ def main(run_dir: Path) -> None:
|
||||
# Annualization bars
|
||||
effective_source = _detect_primary_source(codes, source)
|
||||
from backtest.metrics import calc_bars_per_year
|
||||
bars_per_year = calc_bars_per_year(interval, effective_source)
|
||||
# Cross-market: use calendar-day annualization (bars_per_year=None)
|
||||
market_types = {_detect_market(c) for c in codes}
|
||||
if len(market_types) > 1:
|
||||
bars_per_year = None
|
||||
else:
|
||||
bars_per_year = calc_bars_per_year(interval, effective_source)
|
||||
|
||||
# Auto mode: wrap preloaded data in a dummy loader
|
||||
if source == "auto":
|
||||
@@ -268,6 +515,11 @@ def _create_market_engine(source: str, config: dict, codes: List[str]):
|
||||
# Detect dominant market type from codes
|
||||
markets = {_detect_market(c) for c in codes} if codes else set()
|
||||
|
||||
# Cross-market -> CompositeEngine
|
||||
if len(markets) > 1:
|
||||
from backtest.engines.composite import CompositeEngine
|
||||
return CompositeEngine(config, codes)
|
||||
|
||||
# Futures routing (Wave 2)
|
||||
if "futures" in markets:
|
||||
# Distinguish China vs global futures by exchange suffix
|
||||
@@ -399,6 +651,21 @@ def _fetch_auto(codes: List[str], config: dict, interval: str = "1D") -> dict:
|
||||
normalized_codes = _normalize_codes(market_codes, src_name)
|
||||
fields = config.get("extra_fields") if src_name == "tushare" else None
|
||||
result = loader.fetch(normalized_codes, start_date, end_date, fields=fields, interval=interval)
|
||||
|
||||
# Runtime fallback: try remaining sources when primary returns empty
|
||||
if not result:
|
||||
for fb_name in FALLBACK_CHAINS.get(market, []):
|
||||
if fb_name == src_name or fb_name not in LOADER_REGISTRY:
|
||||
continue
|
||||
fb_loader = LOADER_REGISTRY[fb_name]()
|
||||
if not fb_loader.is_available():
|
||||
continue
|
||||
fb_codes = _normalize_codes(market_codes, fb_name)
|
||||
result = fb_loader.fetch(fb_codes, start_date, end_date, interval=interval)
|
||||
if result:
|
||||
logger.info("Runtime fallback: %s -> %s for %s", src_name, fb_name, market)
|
||||
break
|
||||
|
||||
merged.update(result)
|
||||
|
||||
return merged
|
||||
@@ -417,6 +684,6 @@ class _AutoLoader:
|
||||
|
||||
if __name__ == "__main__":
|
||||
if len(sys.argv) < 2:
|
||||
print(f"Usage: python -m backtest.runner <run_dir>")
|
||||
print("Usage: python -m backtest.runner <run_dir>")
|
||||
sys.exit(1)
|
||||
main(Path(sys.argv[1]))
|
||||
@@ -5,7 +5,7 @@ Three independent tools:
|
||||
- Bootstrap Sharpe CI: how stable is the risk-adjusted return?
|
||||
- Walk-Forward analysis: is performance consistent across time windows?
|
||||
|
||||
Usage: called automatically by BaseEngine.run_backtest when config["validation"]
|
||||
Usage: called automatically by BaseEngine.run_backtest when config[\"validation\"]
|
||||
is present, or invoked directly on backtest outputs.
|
||||
"""
|
||||
|
||||
@@ -330,6 +330,31 @@ def _load_trades(run_dir: Path) -> List[TradeRecord]:
|
||||
return trades
|
||||
|
||||
|
||||
def _parse_run_dir(argv: List[str]) -> Path:
|
||||
"""Validate CLI input and return a usable run directory path."""
|
||||
if len(argv) < 2:
|
||||
raise SystemExit("Usage: python -m backtest.validation <run_dir>")
|
||||
|
||||
raw_run_dir = argv[1]
|
||||
if not raw_run_dir.strip():
|
||||
raise SystemExit("run_dir must be a non-empty path")
|
||||
if "\0" in raw_run_dir:
|
||||
raise SystemExit("Invalid run_dir path: embedded NUL byte")
|
||||
|
||||
try:
|
||||
run_dir = Path(raw_run_dir).expanduser()
|
||||
exists = run_dir.exists()
|
||||
is_dir = run_dir.is_dir() if exists else False
|
||||
except (OSError, RuntimeError, ValueError) as exc:
|
||||
raise SystemExit(f"Invalid run_dir path: {exc}") from exc
|
||||
|
||||
if not exists:
|
||||
raise SystemExit(f"run_dir does not exist: {run_dir}")
|
||||
if not is_dir:
|
||||
raise SystemExit(f"run_dir is not a directory: {run_dir}")
|
||||
return run_dir
|
||||
|
||||
|
||||
def main(run_dir: Path) -> Dict[str, Any]:
|
||||
"""Run all three validations on existing backtest artifacts.
|
||||
|
||||
@@ -370,9 +395,5 @@ def main(run_dir: Path) -> Dict[str, Any]:
|
||||
|
||||
if __name__ == "__main__":
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
if len(sys.argv) < 2:
|
||||
print("Usage: python -m backtest.validation <run_dir>")
|
||||
sys.exit(1)
|
||||
main(Path(sys.argv[1]))
|
||||
main(_parse_run_dir(sys.argv))
|
||||
+1252
-105
File diff suppressed because it is too large.
Load diff
+320
-58
@@ -1,5 +1,5 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Vibe-Trading MCP Server — expose 17 finance research tools to any MCP client.
|
||||
"""Vibe-Trading MCP Server — expose 22 finance research tools to any MCP client.
|
||||
|
||||
Works with OpenClaw, Claude Desktop, Cursor, and any MCP-compatible client.
|
||||
Zero API key required for HK/US/crypto markets (yfinance, OKX, AKShare are free).
|
||||
@@ -27,6 +27,8 @@ Claude Desktop config:
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import re
|
||||
import sys
|
||||
@@ -42,6 +44,8 @@ from fastmcp import FastMCP
|
||||
|
||||
mcp = FastMCP("Vibe-Trading")
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Lazy-loaded singletons
|
||||
@@ -49,12 +53,19 @@ mcp = FastMCP("Vibe-Trading")
|
||||
|
||||
_skills_loader = None
|
||||
_registry = None
|
||||
_include_shell_tools = True
|
||||
|
||||
|
||||
def _env_shell_tools_enabled() -> bool:
|
||||
"""Return whether shell tools were explicitly enabled for network MCP."""
|
||||
return os.getenv("VIBE_TRADING_ENABLE_SHELL_TOOLS", "").strip().lower() in {"1", "true", "yes", "on"}
|
||||
|
||||
|
||||
def _get_skills_loader():
|
||||
global _skills_loader
|
||||
if _skills_loader is None:
|
||||
from src.agent.skills import SkillsLoader
|
||||
|
||||
_skills_loader = SkillsLoader()
|
||||
return _skills_loader
|
||||
|
||||
@@ -63,7 +74,8 @@ def _get_registry():
|
||||
global _registry
|
||||
if _registry is None:
|
||||
from src.tools import build_registry
|
||||
_registry = build_registry()
|
||||
|
||||
_registry = build_registry(include_shell_tools=_include_shell_tools)
|
||||
return _registry
|
||||
|
||||
|
||||
@@ -71,11 +83,12 @@ def _get_registry():
|
||||
# Skill tools
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def list_skills() -> str:
|
||||
"""List all available finance skills with names and descriptions.
|
||||
|
||||
Returns a JSON array of {name, description} for all 68 skills.
|
||||
Returns a JSON array of {name, description} for all loaded skills.
|
||||
Use load_skill(name) to get the full documentation for any skill.
|
||||
"""
|
||||
loader = _get_skills_loader()
|
||||
@@ -105,6 +118,7 @@ def load_skill(name: str) -> str:
|
||||
# Backtest tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def backtest(run_dir: str) -> str:
|
||||
"""Run a vectorized backtest using config.json and code/signal_engine.py.
|
||||
@@ -127,6 +141,7 @@ def backtest(run_dir: str) -> str:
|
||||
run_dir: Path to the run directory containing config.json and code/.
|
||||
"""
|
||||
from src.tools.backtest_tool import run_backtest
|
||||
|
||||
return run_backtest(run_dir)
|
||||
|
||||
|
||||
@@ -134,6 +149,7 @@ def backtest(run_dir: str) -> str:
|
||||
# Factor analysis tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def factor_analysis(
|
||||
codes: list[str],
|
||||
@@ -159,17 +175,25 @@ def factor_analysis(
|
||||
bottom_n: Number of bottom-ranked stocks per period.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("factor_analysis", {
|
||||
"codes": codes, "factor_name": factor_name,
|
||||
"start_date": start_date, "end_date": end_date,
|
||||
"source": source, "top_n": top_n, "bottom_n": bottom_n,
|
||||
})
|
||||
return registry.execute(
|
||||
"factor_analysis",
|
||||
{
|
||||
"codes": codes,
|
||||
"factor_name": factor_name,
|
||||
"start_date": start_date,
|
||||
"end_date": end_date,
|
||||
"source": source,
|
||||
"top_n": top_n,
|
||||
"bottom_n": bottom_n,
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Options pricing tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def analyze_options(
|
||||
spot: float,
|
||||
@@ -190,17 +214,24 @@ def analyze_options(
|
||||
option_type: "call" or "put".
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("options_pricing", {
|
||||
"spot": spot, "strike": strike, "expiry_days": expiry_days,
|
||||
"risk_free_rate": risk_free_rate, "volatility": volatility,
|
||||
"option_type": option_type,
|
||||
})
|
||||
return registry.execute(
|
||||
"options_pricing",
|
||||
{
|
||||
"spot": spot,
|
||||
"strike": strike,
|
||||
"expiry_days": expiry_days,
|
||||
"risk_free_rate": risk_free_rate,
|
||||
"volatility": volatility,
|
||||
"option_type": option_type,
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Pattern recognition tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def pattern_recognition(run_dir: str) -> str:
|
||||
"""Detect technical chart patterns (head-and-shoulders, double top/bottom,
|
||||
@@ -213,13 +244,14 @@ def pattern_recognition(run_dir: str) -> str:
|
||||
run_dir: Path to run directory containing artifacts/ohlcv_*.csv.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("pattern_recognition", {"run_dir": run_dir})
|
||||
return registry.execute("pattern", {"run_dir": run_dir})
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Web & document reading tools
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def read_url(url: str) -> str:
|
||||
"""Fetch a web page and convert it to clean Markdown text.
|
||||
@@ -231,6 +263,7 @@ def read_url(url: str) -> str:
|
||||
url: Target URL to read.
|
||||
"""
|
||||
from src.tools.web_reader_tool import read_url as _read_url
|
||||
|
||||
return _read_url(url)
|
||||
|
||||
|
||||
@@ -252,6 +285,7 @@ def read_document(file_path: str) -> str:
|
||||
# Web search tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def web_search(query: str, max_results: int = 5) -> str:
|
||||
"""Search the web via DuckDuckGo and return top results.
|
||||
@@ -264,15 +298,20 @@ def web_search(query: str, max_results: int = 5) -> str:
|
||||
max_results: Maximum results to return (default 5, max 10).
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("web_search", {
|
||||
"query": query, "max_results": min(max_results, 10),
|
||||
})
|
||||
return registry.execute(
|
||||
"web_search",
|
||||
{
|
||||
"query": query,
|
||||
"max_results": min(max_results, 10),
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# File I/O tools (sandboxed to workspace)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def write_file(path: str, content: str) -> str:
|
||||
"""Write content to a file. Used to create config.json and signal_engine.py
|
||||
@@ -301,6 +340,7 @@ def read_file(path: str) -> str:
|
||||
# Swarm team tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def list_swarm_presets() -> str:
|
||||
"""List available swarm multi-agent team presets.
|
||||
@@ -310,6 +350,7 @@ def list_swarm_presets() -> str:
|
||||
Returns preset names, descriptions, agent counts, and required variables.
|
||||
"""
|
||||
from src.swarm.presets import list_presets
|
||||
|
||||
presets = list_presets()
|
||||
return json.dumps(presets, ensure_ascii=False, indent=2)
|
||||
|
||||
@@ -330,15 +371,17 @@ def run_swarm(preset_name: str, variables: dict[str, str]) -> str:
|
||||
"""
|
||||
import time
|
||||
from src.swarm.runtime import SwarmRuntime
|
||||
from src.swarm.store import SwarmStore
|
||||
from src.swarm.store import SwarmStore, swarm_runs_root
|
||||
from src.swarm.models import RunStatus
|
||||
|
||||
swarm_dir = AGENT_DIR / ".swarm" / "runs"
|
||||
swarm_dir = swarm_runs_root()
|
||||
store = SwarmStore(base_dir=swarm_dir)
|
||||
runtime = SwarmRuntime(store=store)
|
||||
|
||||
try:
|
||||
run = runtime.start_run(preset_name, variables)
|
||||
run = runtime.start_run(
|
||||
preset_name, variables, include_shell_tools=_include_shell_tools
|
||||
)
|
||||
except FileNotFoundError as exc:
|
||||
return json.dumps({"status": "error", "error": str(exc)}, ensure_ascii=False)
|
||||
except ValueError as exc:
|
||||
@@ -351,19 +394,23 @@ def run_swarm(preset_name: str, variables: dict[str, str]) -> str:
|
||||
if current is None:
|
||||
return json.dumps({"status": "error", "error": "Run record lost"}, ensure_ascii=False)
|
||||
if current.status in (RunStatus.completed, RunStatus.failed, RunStatus.cancelled):
|
||||
tasks = [
|
||||
{"id": t.id, "agent_id": t.agent_id, "status": t.status.value, "summary": t.summary}
|
||||
for t in current.tasks
|
||||
]
|
||||
return json.dumps({
|
||||
"status": current.status.value,
|
||||
"preset": preset_name,
|
||||
"run_id": current.id,
|
||||
"final_report": current.final_report,
|
||||
"tasks": tasks,
|
||||
"total_input_tokens": current.total_input_tokens,
|
||||
"total_output_tokens": current.total_output_tokens,
|
||||
}, ensure_ascii=False, indent=2)
|
||||
from src.swarm.serialization import run_level_error, serialize_task
|
||||
|
||||
tasks = [serialize_task(t) for t in current.tasks]
|
||||
return json.dumps(
|
||||
{
|
||||
"status": current.status.value,
|
||||
"preset": preset_name,
|
||||
"run_id": current.id,
|
||||
"final_report": current.final_report,
|
||||
"error": run_level_error(current),
|
||||
"tasks": tasks,
|
||||
"total_input_tokens": current.total_input_tokens,
|
||||
"total_output_tokens": current.total_output_tokens,
|
||||
},
|
||||
ensure_ascii=False,
|
||||
indent=2,
|
||||
)
|
||||
|
||||
return json.dumps({"status": "error", "error": "Swarm timed out after 30 minutes"}, ensure_ascii=False)
|
||||
|
||||
@@ -372,6 +419,8 @@ def run_swarm(preset_name: str, variables: dict[str, str]) -> str:
|
||||
# Market data tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
DEFAULT_MAX_ROWS = 250
|
||||
|
||||
_SOURCE_PATTERNS = [
|
||||
(re.compile(r"^\d{6}\.(SZ|SH|BJ)$", re.I), "tushare"),
|
||||
(re.compile(r"^[A-Z]+\.US$", re.I), "yfinance"),
|
||||
@@ -391,9 +440,40 @@ def _detect_source(code: str) -> str:
|
||||
def _get_loader(source: str):
|
||||
"""Get loader class via registry with fallback support."""
|
||||
from backtest.loaders.registry import get_loader_cls_with_fallback
|
||||
|
||||
return get_loader_cls_with_fallback(source)
|
||||
|
||||
|
||||
def _cap_rows(records: list, max_rows: int) -> list | dict[str, object]:
|
||||
"""Bound a per-symbol row list to keep the MCP payload within budget.
|
||||
|
||||
max_rows==0 disables the cap (full list, unchanged shape). A negative
|
||||
max_rows is invalid and enforces the default cap (never unbounded).
|
||||
Otherwise an oversized symbol is *evenly strided* — every step-th bar,
|
||||
with the last bar pinned — so the returned series spans the full range
|
||||
(no head+tail gap, no synthetic ``_gap`` sentinel). Symbols within the
|
||||
cap are returned unchanged (plain list) — small queries are
|
||||
byte-identical.
|
||||
"""
|
||||
n = len(records)
|
||||
if max_rows < 0:
|
||||
max_rows = DEFAULT_MAX_ROWS # negative invalid -> enforce cap, never unbounded
|
||||
if max_rows == 0 or n <= max_rows:
|
||||
return records
|
||||
step = math.ceil(n / max_rows)
|
||||
sampled = records[::step]
|
||||
if sampled[-1] is not records[-1]:
|
||||
sampled = sampled + [records[-1]]
|
||||
return {
|
||||
"rows": n,
|
||||
"returned": len(sampled),
|
||||
"truncated": True,
|
||||
"policy": f"every-{step}th-row (even stride; last bar pinned)",
|
||||
"hint": "narrow the date range, coarsen interval, or set max_rows=0 for all rows",
|
||||
"data": sampled,
|
||||
}
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def get_market_data(
|
||||
codes: list[str],
|
||||
@@ -401,6 +481,7 @@ def get_market_data(
|
||||
end_date: str,
|
||||
source: str = "auto",
|
||||
interval: str = "1D",
|
||||
max_rows: int = DEFAULT_MAX_ROWS,
|
||||
) -> str:
|
||||
"""Fetch OHLCV market data for stocks, crypto, or mixed symbols.
|
||||
|
||||
@@ -418,6 +499,11 @@ def get_market_data(
|
||||
end_date: End date (YYYY-MM-DD).
|
||||
source: Data source ("auto", "yfinance", "okx", "tushare", "akshare", "ccxt").
|
||||
interval: Bar size (1m/5m/15m/30m/1H/4H/1D, default "1D").
|
||||
max_rows: Per-symbol row cap (default 250) so the response stays
|
||||
within the MCP token budget. A symbol exceeding it returns an
|
||||
even-stride downsample (every step-th bar, last bar pinned)
|
||||
plus truncation metadata. Set max_rows=0 for all rows
|
||||
(unbounded, legacy behavior).
|
||||
"""
|
||||
results = {}
|
||||
|
||||
@@ -432,7 +518,14 @@ def get_market_data(
|
||||
for src, src_codes in groups.items():
|
||||
loader_cls = _get_loader(src)
|
||||
loader = loader_cls()
|
||||
data_map = loader.fetch(src_codes, start_date, end_date, interval=interval)
|
||||
try:
|
||||
data_map = loader.fetch(src_codes, start_date, end_date, interval=interval)
|
||||
except Exception:
|
||||
# A loader blow-up for one group must not lose already-resolved
|
||||
# symbols or surface as an opaque MCP error; those codes fall
|
||||
# through to _unresolved below (P05).
|
||||
logger.exception("market-data loader %r failed for %s; codes fall through to _unresolved", src, src_codes)
|
||||
data_map = {}
|
||||
for symbol, df in data_map.items():
|
||||
records = df.reset_index().to_dict(orient="records")
|
||||
for r in records:
|
||||
@@ -441,7 +534,16 @@ def get_market_data(
|
||||
r[k] = v.isoformat()
|
||||
elif hasattr(v, "item"):
|
||||
r[k] = v.item()
|
||||
results[symbol] = records
|
||||
results[symbol] = _cap_rows(records, max_rows)
|
||||
|
||||
# P05: a typo / wrong-suffix / delisted / no-data symbol used to vanish
|
||||
# silently (the dict only held winners), indistinguishable from "no data".
|
||||
# Surface every requested code that produced nothing under a reserved key.
|
||||
# Additive: omitted entirely when all codes resolved, so the happy-path
|
||||
# payload is byte-identical to before.
|
||||
unresolved = [c for c in codes if c not in results]
|
||||
if unresolved:
|
||||
results["_unresolved"] = unresolved
|
||||
|
||||
return json.dumps(results, ensure_ascii=False, indent=2)
|
||||
|
||||
@@ -450,28 +552,25 @@ def get_market_data(
|
||||
# Swarm status & history tools
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
def _get_swarm_store():
|
||||
swarm_dir = AGENT_DIR / ".swarm" / "runs"
|
||||
from src.swarm.store import SwarmStore, swarm_runs_root
|
||||
|
||||
swarm_dir = swarm_runs_root()
|
||||
swarm_dir.mkdir(parents=True, exist_ok=True)
|
||||
from src.swarm.store import SwarmStore
|
||||
return SwarmStore(base_dir=swarm_dir)
|
||||
|
||||
|
||||
def _run_to_dict(run) -> dict:
|
||||
from src.swarm.serialization import run_level_error, serialize_task
|
||||
|
||||
return {
|
||||
"run_id": run.id,
|
||||
"status": run.status.value,
|
||||
"preset": run.preset_name,
|
||||
"created_at": run.created_at,
|
||||
"tasks": [
|
||||
{
|
||||
"id": t.id,
|
||||
"agent_id": t.agent_id,
|
||||
"status": t.status.value,
|
||||
"summary": t.summary,
|
||||
}
|
||||
for t in run.tasks
|
||||
],
|
||||
"error": run_level_error(run),
|
||||
"tasks": [serialize_task(t) for t in run.tasks],
|
||||
"final_report": run.final_report,
|
||||
"total_input_tokens": run.total_input_tokens,
|
||||
"total_output_tokens": run.total_output_tokens,
|
||||
@@ -526,31 +625,194 @@ def list_runs(limit: int = 20) -> str:
|
||||
runs = store.list_runs(limit=limit)
|
||||
items = []
|
||||
for run in runs:
|
||||
items.append({
|
||||
"run_id": run.id,
|
||||
"preset": run.preset_name,
|
||||
"status": run.status.value,
|
||||
"created_at": run.created_at,
|
||||
"total_input_tokens": run.total_input_tokens,
|
||||
"total_output_tokens": run.total_output_tokens,
|
||||
})
|
||||
items.append(
|
||||
{
|
||||
"run_id": run.id,
|
||||
"preset": run.preset_name,
|
||||
"status": run.status.value,
|
||||
"created_at": run.created_at,
|
||||
"total_input_tokens": run.total_input_tokens,
|
||||
"total_output_tokens": run.total_output_tokens,
|
||||
}
|
||||
)
|
||||
return json.dumps(items, ensure_ascii=False, indent=2)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Trade journal tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def analyze_trade_journal(
|
||||
file_path: str,
|
||||
analysis_type: str = "full",
|
||||
filter_expr: str = "",
|
||||
) -> str:
|
||||
"""Analyze a user's trade journal (CSV/Excel broker export) and return
|
||||
a trading profile plus behavior diagnostics.
|
||||
|
||||
Parses 同花顺 / 东方财富 / 富途 / generic formats (encoding auto-detected).
|
||||
Output (JSON):
|
||||
- profile: holding days, frequency, win rate, PnL ratio, top symbols,
|
||||
market distribution, hourly distribution
|
||||
- behaviors: disposition effect, overtrading, chasing momentum,
|
||||
anchoring (each with severity + numeric evidence)
|
||||
|
||||
Args:
|
||||
file_path: Absolute path to the uploaded CSV/Excel file.
|
||||
analysis_type: "full" | "profile" | "behavior" | "strategy".
|
||||
filter_expr: Optional filter (e.g. "2026-01 to 2026-03",
|
||||
"symbol=600519.SH", "market=china_a").
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute(
|
||||
"analyze_trade_journal",
|
||||
{
|
||||
"file_path": file_path,
|
||||
"analysis_type": analysis_type,
|
||||
"filter_expr": filter_expr,
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Shadow Account tools (4)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def extract_shadow_strategy(
|
||||
journal_path: str,
|
||||
min_support: int = 3,
|
||||
max_rules: int = 5,
|
||||
) -> str:
|
||||
"""Extract a Shadow Account profile (3-5 human-readable if-then rules)
|
||||
from the user's profitable roundtrips in a trade journal.
|
||||
|
||||
Run `analyze_trade_journal` first if the journal hasn't been parsed.
|
||||
Returns shadow_id + rules preview. Profile persists to
|
||||
~/.vibe-trading/shadow_accounts/.
|
||||
|
||||
Args:
|
||||
journal_path: Path to the CSV/Excel broker export.
|
||||
min_support: Minimum profitable roundtrips required to back one rule.
|
||||
max_rules: Maximum rules to return (typically 3-5).
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute(
|
||||
"extract_shadow_strategy",
|
||||
{
|
||||
"journal_path": journal_path,
|
||||
"min_support": min_support,
|
||||
"max_rules": max_rules,
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def run_shadow_backtest(
|
||||
shadow_id: str,
|
||||
window_start: str = "",
|
||||
window_end: str = "",
|
||||
markets: list[str] | None = None,
|
||||
journal_path: str = "",
|
||||
) -> str:
|
||||
"""Run a multi-market backtest (A股/港股/美股/crypto) on a Shadow Account
|
||||
profile and compute delta-PnL attribution vs the user's realized trades.
|
||||
|
||||
Requires `extract_shadow_strategy` to have run first.
|
||||
|
||||
Args:
|
||||
shadow_id: ID returned by extract_shadow_strategy.
|
||||
window_start: ISO date, default today-1y.
|
||||
window_end: ISO date, default today.
|
||||
markets: Subset of ["china_a", "hk", "us", "crypto"], default all four.
|
||||
journal_path: Original journal path (enables attribution), optional.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
params: dict[str, Any] = {"shadow_id": shadow_id}
|
||||
if window_start:
|
||||
params["window_start"] = window_start
|
||||
if window_end:
|
||||
params["window_end"] = window_end
|
||||
if markets:
|
||||
params["markets"] = markets
|
||||
if journal_path:
|
||||
params["journal_path"] = journal_path
|
||||
return registry.execute("run_shadow_backtest", params)
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def render_shadow_report(
|
||||
shadow_id: str,
|
||||
include_today_signals: bool = True,
|
||||
window_start: str = "",
|
||||
window_end: str = "",
|
||||
journal_path: str = "",
|
||||
) -> str:
|
||||
"""Render the Shadow Account HTML/PDF report (8 sections + charts) for
|
||||
a shadow_id. If no cached backtest, one is run automatically.
|
||||
|
||||
Args:
|
||||
shadow_id: Shadow Account ID.
|
||||
include_today_signals: Include today's market scan section.
|
||||
window_start: Optional backtest window override.
|
||||
window_end: Optional backtest window override.
|
||||
journal_path: Original journal path (for attribution), optional.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
params: dict[str, Any] = {
|
||||
"shadow_id": shadow_id,
|
||||
"include_today_signals": include_today_signals,
|
||||
}
|
||||
if window_start:
|
||||
params["window_start"] = window_start
|
||||
if window_end:
|
||||
params["window_end"] = window_end
|
||||
if journal_path:
|
||||
params["journal_path"] = journal_path
|
||||
return registry.execute("render_shadow_report", params)
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def scan_shadow_signals(
|
||||
shadow_id: str,
|
||||
date: str = "",
|
||||
per_market: int = 3,
|
||||
) -> str:
|
||||
"""List today's symbols that match the Shadow Account's entry cadence
|
||||
(research use only — not a trade recommendation).
|
||||
|
||||
Args:
|
||||
shadow_id: Shadow Account ID.
|
||||
date: ISO YYYY-MM-DD target date, default today.
|
||||
per_market: Max signals per market.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
params: dict[str, Any] = {"shadow_id": shadow_id, "per_market": per_market}
|
||||
if date:
|
||||
params["date"] = date
|
||||
return registry.execute("scan_shadow_signals", params)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Entry point
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
def main():
|
||||
"""Entry point for `vibe-trading-mcp` CLI command."""
|
||||
global _include_shell_tools, _registry
|
||||
import argparse
|
||||
|
||||
parser = argparse.ArgumentParser(description="Vibe-Trading MCP Server")
|
||||
parser.add_argument("--transport", choices=["stdio", "sse"], default="stdio",
|
||||
help="MCP transport (default: stdio)")
|
||||
parser.add_argument("--port", type=int, default=8900,
|
||||
help="SSE port (only used with --transport sse)")
|
||||
parser.add_argument("--transport", choices=["stdio", "sse"], default="stdio", help="MCP transport (default: stdio)")
|
||||
parser.add_argument("--port", type=int, default=8900, help="SSE port (only used with --transport sse)")
|
||||
args = parser.parse_args()
|
||||
_include_shell_tools = True if args.transport == "stdio" else _env_shell_tools_enabled()
|
||||
_registry = None
|
||||
_get_registry() # pre-warm: avoids deadlock when first tools/call lazy-inits inside FastMCP worker thread
|
||||
|
||||
if args.transport == "sse":
|
||||
mcp.run(transport="sse", port=args.port)
|
||||
|
||||
+18
-1
@@ -7,6 +7,8 @@ langchain-openai>=0.0.5
|
||||
langgraph>=0.2.50,<0.3
|
||||
langgraph-checkpoint>=2.0.0
|
||||
python-dotenv>=1.0.0
|
||||
httpx>=0.28.0
|
||||
oauth-cli-kit>=0.1.3
|
||||
|
||||
# Data & Computation
|
||||
pandas>=2.0.0
|
||||
@@ -14,6 +16,13 @@ numpy>=1.24.0
|
||||
scipy>=1.10.0
|
||||
duckdb>=1.2.0
|
||||
|
||||
# Document Readers (doc_reader_tool)
|
||||
openpyxl>=3.1.0
|
||||
python-docx>=1.1.0
|
||||
python-pptx>=0.6.23
|
||||
pypdfium2>=4.0.0
|
||||
Pillow>=10.0.0
|
||||
|
||||
# ML Strategy
|
||||
scikit-learn>=1.3.0
|
||||
joblib>=1.3.0
|
||||
@@ -33,8 +42,16 @@ ccxt>=4.0.0
|
||||
fastapi>=0.104.0
|
||||
uvicorn[standard]>=0.24.0
|
||||
pydantic>=2.0.0
|
||||
python-multipart>=0.0.6
|
||||
python-multipart>=0.0.18
|
||||
sse-starlette>=1.6.0
|
||||
|
||||
# MCP Server
|
||||
fastmcp>=2.0.0
|
||||
|
||||
# Web Search
|
||||
ddgs>=6.0.0
|
||||
|
||||
# Shadow Account HTML/PDF Report
|
||||
jinja2>=3.1.0
|
||||
matplotlib>=3.7.0
|
||||
weasyprint>=60.0
|
||||
@@ -0,0 +1,250 @@
|
||||
"""W4.a blog patcher: fill TBD placeholders in alpha-191-in-2026.html.
|
||||
|
||||
Reads ~/.vibe-trading/reports/bench_summary.json (produced by w4a_run_benches.py)
|
||||
and patches the HTML in place.
|
||||
|
||||
Substitutions performed:
|
||||
- num-alive / num-reversed / num-dead spans in the two stat blocks
|
||||
- Theme survival table rows (count + survival rate per theme)
|
||||
- Top 5 alphas (id + formula + IC mean)
|
||||
- 3 famously-dead alphas (replace invented IDs with worst-IC from gtja191)
|
||||
- Section-level "bench failed" callouts where the corresponding bench errored
|
||||
|
||||
The patcher never fabricates a number: if the gtja191 bench is missing, every
|
||||
TBD that depends on it becomes a "bench failed" note instead. The script is
|
||||
idempotent — re-running with the same summary produces the same HTML.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import html
|
||||
import json
|
||||
import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
REPO = Path(__file__).resolve().parents[2]
|
||||
HTML_PATH = REPO / "wiki" / "research-lab" / "posts" / "alpha-191-in-2026.html"
|
||||
SUMMARY_PATH = Path.home() / ".vibe-trading" / "reports" / "bench_summary.json"
|
||||
|
||||
GTJA_KEY = "gtja191_csi300"
|
||||
|
||||
# Themes shown in the table — these are the human labels in the HTML, mapped
|
||||
# to the canonical theme tags in registry meta. "Volume-price interaction"
|
||||
# requires *both* volume and reversal-or-momentum, so it gets a custom probe.
|
||||
THEME_LABEL_TO_TAGS: dict[str, list[str]] = {
|
||||
"Volume-price interaction": ["volume"],
|
||||
"Short-horizon volatility": ["volatility"],
|
||||
"Reversal": ["reversal"],
|
||||
"Momentum": ["momentum"],
|
||||
"Turnover / liquidity": ["liquidity"],
|
||||
"Microstructure / range": ["microstructure"],
|
||||
}
|
||||
|
||||
|
||||
def _load_summary() -> dict[str, Any]:
|
||||
if not SUMMARY_PATH.is_file():
|
||||
raise SystemExit(f"summary not found: {SUMMARY_PATH}")
|
||||
return json.loads(SUMMARY_PATH.read_text(encoding="utf-8"))
|
||||
|
||||
|
||||
def _gtja_entry(summary: dict[str, Any]) -> dict[str, Any] | None:
|
||||
entry = summary.get("zoos", {}).get(GTJA_KEY)
|
||||
if not entry or entry.get("status") != "ok":
|
||||
return None
|
||||
return entry
|
||||
|
||||
|
||||
def _patch_stats(text: str, entry: dict[str, Any]) -> str:
|
||||
for span_class, key in (
|
||||
("num-alive", "alive"),
|
||||
("num-reversed", "reversed"),
|
||||
("num-dead", "dead"),
|
||||
):
|
||||
value = entry.get(key)
|
||||
if value is None:
|
||||
continue
|
||||
pattern = re.compile(
|
||||
rf'(<span class="{span_class}">)\[TBD\](</span>)'
|
||||
)
|
||||
text = pattern.sub(rf"\g<1>{int(value)}\g<2>", text)
|
||||
return text
|
||||
|
||||
|
||||
def _theme_survival_rows(entry: dict[str, Any]) -> str:
|
||||
"""Build the inner <tr> rows for the theme-survival table."""
|
||||
by_theme = entry.get("by_theme", {})
|
||||
rows: list[str] = []
|
||||
definitions = {
|
||||
"Volume-price interaction": "Correlation / covariance of volume with close, high-low range",
|
||||
"Short-horizon volatility": "Rolling std / range over 5-20 day windows",
|
||||
"Reversal": "Negative-sign return signals over 1-5 day horizons",
|
||||
"Momentum": "Positive-sign return signals over 10-60 day horizons",
|
||||
"Turnover / liquidity": "Volume ratios, turnover-rate transforms",
|
||||
"Microstructure / range": "Open-close-high-low decompositions, intraday range proxies",
|
||||
}
|
||||
for label, tags in THEME_LABEL_TO_TAGS.items():
|
||||
# Aggregate across all listed tags (most themes are single-tag).
|
||||
alive = dead = reversed_ = count = 0
|
||||
for tag in tags:
|
||||
bucket = by_theme.get(tag)
|
||||
if bucket is None:
|
||||
continue
|
||||
alive += bucket.get("alive", 0)
|
||||
dead += bucket.get("dead", 0)
|
||||
reversed_ += bucket.get("reversed", 0)
|
||||
count += bucket.get("count", 0)
|
||||
if count == 0:
|
||||
count_cell = "n/a"
|
||||
rate_cell = "n/a"
|
||||
else:
|
||||
count_cell = str(count)
|
||||
rate_cell = f"{alive / count * 100:.0f}% ({alive}/{count})"
|
||||
rows.append(
|
||||
" <tr>\n"
|
||||
f" <td>{html.escape(label)}</td>\n"
|
||||
f" <td>{html.escape(definitions[label])}</td>\n"
|
||||
f" <td>{count_cell}</td>\n"
|
||||
f" <td>{rate_cell}</td>\n"
|
||||
" </tr>"
|
||||
)
|
||||
return "\n".join(rows)
|
||||
|
||||
|
||||
def _patch_theme_table(text: str, entry: dict[str, Any]) -> str:
|
||||
new_rows = _theme_survival_rows(entry)
|
||||
pattern = re.compile(
|
||||
r'(<tbody>)(.*?)(</tbody>)',
|
||||
re.DOTALL,
|
||||
)
|
||||
# The HTML has exactly one <tbody> inside the theme-table; surgical replace.
|
||||
def _swap(match: re.Match[str]) -> str:
|
||||
body = match.group(2)
|
||||
if "Volume-price interaction" not in body:
|
||||
return match.group(0) # not the theme table
|
||||
return f"{match.group(1)}\n{new_rows}\n {match.group(3)}"
|
||||
|
||||
return pattern.sub(_swap, text, count=1)
|
||||
|
||||
|
||||
def _formula_to_html(formula: str) -> str:
|
||||
return html.escape(formula)
|
||||
|
||||
|
||||
def _build_top5_cards(entry: dict[str, Any]) -> str:
|
||||
rows = entry.get("top5_by_ir", [])[:5]
|
||||
cards: list[str] = []
|
||||
for row in rows:
|
||||
aid = row["id"]
|
||||
formula = _formula_to_html(row.get("formula_latex", ""))
|
||||
ic = row.get("ic_mean", 0.0)
|
||||
ir = row.get("ir", 0.0)
|
||||
cards.append(
|
||||
" <article class=\"alpha-card\">\n"
|
||||
f" <span class=\"alpha-id\">{html.escape(aid)}</span>\n"
|
||||
f" <pre class=\"formula-block\"><code>{formula}</code></pre>\n"
|
||||
" <p class=\"alpha-note\">"
|
||||
f"Mean IC = {ic:.4f}, IR = {ir:.4f} over the CSI 300 / 2018–2025 window. "
|
||||
"Formula reproduced verbatim from the registry "
|
||||
f"(<code>__alpha_meta__[\"formula_latex\"]</code> of <code>{html.escape(aid)}</code>)."
|
||||
"</p>\n"
|
||||
" </article>"
|
||||
)
|
||||
return "\n".join(cards)
|
||||
|
||||
|
||||
def _build_dead_cards(entry: dict[str, Any]) -> str:
|
||||
rows = entry.get("dead_examples", [])[:3]
|
||||
cards: list[str] = []
|
||||
for row in rows:
|
||||
aid = row["id"]
|
||||
formula = _formula_to_html(row.get("formula_latex", ""))
|
||||
ic = row.get("ic_mean", 0.0)
|
||||
cat = row.get("category", "dead")
|
||||
ir = row.get("ir", 0.0)
|
||||
cards.append(
|
||||
" <article class=\"alpha-card\">\n"
|
||||
f" <span class=\"alpha-id\">{html.escape(aid)} ({html.escape(cat)})</span>\n"
|
||||
f" <pre class=\"formula-block\"><code>{formula}</code></pre>\n"
|
||||
" <p class=\"alpha-note\">"
|
||||
f"Mean IC = {ic:.4f}, IR = {ir:.4f}. Worst-performing slice of the gtja191 "
|
||||
"zoo on CSI 300 / 2018–2025 by raw IC."
|
||||
"</p>\n"
|
||||
" </article>"
|
||||
)
|
||||
return "\n".join(cards)
|
||||
|
||||
|
||||
def _patch_top5(text: str, entry: dict[str, Any]) -> str:
|
||||
cards = _build_top5_cards(entry)
|
||||
pattern = re.compile(
|
||||
r'(<h3>Top 5 surviving alphas</h3>.*?</p>\s*)' # heading + lead paragraph
|
||||
r'(?:<article class="alpha-card">.*?</article>\s*){5}',
|
||||
re.DOTALL,
|
||||
)
|
||||
return pattern.sub(rf"\g<1>{cards}\n\n ", text, count=1)
|
||||
|
||||
|
||||
def _patch_dead(text: str, entry: dict[str, Any]) -> str:
|
||||
cards = _build_dead_cards(entry)
|
||||
pattern = re.compile(
|
||||
r'(<h3>Three famously dead alphas</h3>.*?</p>\s*)'
|
||||
r'(?:<article class="alpha-card">.*?</article>\s*){3}',
|
||||
re.DOTALL,
|
||||
)
|
||||
return pattern.sub(rf"\g<1>{cards}\n\n ", text, count=1)
|
||||
|
||||
|
||||
def _patch_bench_failed_note(text: str) -> str:
|
||||
"""Replace the W4-roadmap placeholder callout with a real timestamp note."""
|
||||
return text.replace(
|
||||
"Numbers will be filled in once the full bench finishes (Vibe-Trading\n roadmap W4.a). "
|
||||
"This post is published as a methodology preview — the structure, definitions\n and caveats are final.",
|
||||
"Numbers below are the live W4.a bench output on the bundled gtja191 zoo "
|
||||
"(CSI 300, 2018–2025) — reproducible via the CLI snippet at the end of the post.",
|
||||
)
|
||||
|
||||
|
||||
def main() -> int:
|
||||
summary = _load_summary()
|
||||
entry = _gtja_entry(summary)
|
||||
|
||||
text = HTML_PATH.read_text(encoding="utf-8")
|
||||
|
||||
if entry is None:
|
||||
# Surface the failure once at the top; leave all TBDs intact so the
|
||||
# reader sees we have not invented numbers.
|
||||
zoo_blob = summary.get("zoos", {}).get(GTJA_KEY, {})
|
||||
reason = zoo_blob.get("error", "bench did not run")
|
||||
note = (
|
||||
'<p class="bench-failed"><strong>Note:</strong> the gtja191 / CSI 300 bench '
|
||||
f"failed during W4.a (reason: {html.escape(str(reason))}). All TBD numbers below "
|
||||
"remain to be filled in 0.1.9 once the bench is re-run.</p>"
|
||||
)
|
||||
text = text.replace(
|
||||
'roadmap W4.a). This post',
|
||||
f'roadmap W4.a). {note} This post'
|
||||
)
|
||||
HTML_PATH.write_text(text, encoding="utf-8")
|
||||
print(f"bench failed; left TBDs intact and added note. tbd count = "
|
||||
f"{text.count('[TBD]')}", file=sys.stderr)
|
||||
return 0
|
||||
|
||||
text = _patch_stats(text, entry)
|
||||
text = _patch_theme_table(text, entry)
|
||||
text = _patch_top5(text, entry)
|
||||
text = _patch_dead(text, entry)
|
||||
text = _patch_bench_failed_note(text)
|
||||
|
||||
# Mean IC ~ [TBD] placeholders inside the per-card paragraphs are no longer
|
||||
# needed (we rewrote the cards with real numbers). Sanity-check sweep.
|
||||
HTML_PATH.write_text(text, encoding="utf-8")
|
||||
|
||||
remaining = text.count("[TBD]")
|
||||
print(f"patched {HTML_PATH}; remaining [TBD] = {remaining}")
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
sys.exit(main())
|
||||
@@ -0,0 +1,170 @@
|
||||
"""W4.a bench driver: run 4 zoo×universe combinations and emit summary JSON.
|
||||
|
||||
Usage:
|
||||
cd agent && python scripts/w4a_run_benches.py
|
||||
|
||||
Output:
|
||||
~/.vibe-trading/reports/alpha_bench_*.html — per-run HTML reports
|
||||
~/.vibe-trading/reports/bench_<zoo>_<uni>.json — per-run raw results
|
||||
~/.vibe-trading/reports/bench_summary.json — aggregate summary
|
||||
|
||||
Safe to re-run; each bench result is cached by ``_load_universe_panel`` so the
|
||||
expensive Tushare/yfinance fetches only happen once per (universe, period).
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
|
||||
from dotenv import load_dotenv
|
||||
|
||||
# Repo-relative imports
|
||||
HERE = Path(__file__).resolve().parent
|
||||
AGENT_DIR = HERE.parent
|
||||
sys.path.insert(0, str(AGENT_DIR))
|
||||
|
||||
load_dotenv(AGENT_DIR / ".env")
|
||||
|
||||
# Configure logging early so universe loaders log their progress.
|
||||
logging.basicConfig(
|
||||
level=logging.INFO,
|
||||
format="%(asctime)s %(levelname)s %(name)s | %(message)s",
|
||||
)
|
||||
logger = logging.getLogger("w4a")
|
||||
|
||||
from src.factors.bench_runner import run_bench # noqa: E402
|
||||
from src.tools.alpha_bench_tool import run_alpha_bench # noqa: E402
|
||||
|
||||
|
||||
REPORTS_DIR = Path.home() / ".vibe-trading" / "reports"
|
||||
|
||||
BENCHES = [
|
||||
{"key": "gtja191_csi300", "zoo": "gtja191", "universe": "csi300", "period": "2018-2025"},
|
||||
{"key": "alpha101_sp500", "zoo": "alpha101", "universe": "sp500", "period": "2020-2025"},
|
||||
{"key": "qlib158_csi300", "zoo": "qlib158", "universe": "csi300", "period": "2020-2025"},
|
||||
{"key": "alpha101_btc", "zoo": "alpha101", "universe": "btc-usdt", "period": "2022-2025"},
|
||||
]
|
||||
|
||||
|
||||
def _run_one(bench: dict) -> dict:
|
||||
"""Run a single bench end-to-end. Returns a summary entry.
|
||||
|
||||
Delegates the math to ``src.factors.bench_runner.run_bench``; this wrapper
|
||||
just adds the HTML report (via ``run_alpha_bench``) and persists the raw
|
||||
per-alpha rows for downstream tooling, both of which the CLI driver wants
|
||||
but the API route does not.
|
||||
"""
|
||||
key = bench["key"]
|
||||
zoo = bench["zoo"]
|
||||
universe = bench["universe"]
|
||||
period = bench["period"]
|
||||
logger.info("=== bench %s: zoo=%s universe=%s period=%s ===", key, zoo, universe, period)
|
||||
start = time.monotonic()
|
||||
|
||||
entry: dict = {
|
||||
"key": key,
|
||||
"zoo": zoo,
|
||||
"universe": universe,
|
||||
"period": period,
|
||||
"status": "pending",
|
||||
}
|
||||
|
||||
# 1. HTML report (also exercises the universe loader so the panel is cached
|
||||
# on disk for the run_bench call below).
|
||||
try:
|
||||
envelope = run_alpha_bench(
|
||||
zoo=zoo, universe=universe, period=period, top=20
|
||||
)
|
||||
except Exception as exc: # noqa: BLE001 — never let one bench abort the suite
|
||||
logger.exception("bench %s crashed (run_alpha_bench)", key)
|
||||
entry["status"] = "error"
|
||||
entry["error"] = f"unexpected: {exc!s}"
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
if envelope.get("status") != "ok":
|
||||
entry["status"] = "error"
|
||||
entry["error"] = envelope.get("error", "unknown")
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
# 2. Full bench (per-alpha rows + categorisation).
|
||||
try:
|
||||
result = run_bench(zoo=zoo, universe=universe, period=period, top=20)
|
||||
except Exception as exc: # noqa: BLE001
|
||||
logger.exception("bench %s crashed (run_bench)", key)
|
||||
entry["status"] = "error"
|
||||
entry["error"] = f"unexpected: {exc!s}"
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
if result.get("status") != "ok":
|
||||
entry["status"] = "error"
|
||||
entry["error"] = result.get("error", "unknown")
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
rows = result.pop("rows", [])
|
||||
skipped = result.pop("skipped", [])
|
||||
|
||||
entry.update(result)
|
||||
entry["report_path"] = envelope.get("report_path")
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
|
||||
# Write per-bench raw rows for downstream tooling.
|
||||
raw_path = REPORTS_DIR / f"bench_{key}.json"
|
||||
raw_path.write_text(
|
||||
json.dumps(
|
||||
{"meta": {k: entry[k] for k in ("key", "zoo", "universe", "period", "status")},
|
||||
"rows": rows, "skipped": skipped},
|
||||
indent=2,
|
||||
default=str,
|
||||
),
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
logger.info(
|
||||
"bench %s done: tested=%d skipped=%d alive=%d reversed=%d dead=%d (%.1fs)",
|
||||
key, len(rows), len(skipped),
|
||||
entry["alive"], entry["reversed"], entry["dead"],
|
||||
entry["wall_seconds"],
|
||||
)
|
||||
return entry
|
||||
|
||||
|
||||
def main() -> int:
|
||||
REPORTS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
summary: dict = {
|
||||
"generated_at": datetime.now(timezone.utc).isoformat(timespec="seconds"),
|
||||
"zoos": {},
|
||||
}
|
||||
|
||||
tushare_ok = bool(os.getenv("TUSHARE_TOKEN", "").strip())
|
||||
if not tushare_ok:
|
||||
logger.warning("TUSHARE_TOKEN unset; csi300 benches will be skipped")
|
||||
|
||||
for bench in BENCHES:
|
||||
if bench["universe"] == "csi300" and not tushare_ok:
|
||||
summary["zoos"][bench["key"]] = {
|
||||
**{k: bench[k] for k in ("zoo", "universe", "period")},
|
||||
"status": "skipped",
|
||||
"error": "TUSHARE_TOKEN not set",
|
||||
}
|
||||
continue
|
||||
entry = _run_one(bench)
|
||||
summary["zoos"][bench["key"]] = entry
|
||||
|
||||
out = REPORTS_DIR / "bench_summary.json"
|
||||
out.write_text(json.dumps(summary, indent=2, default=str), encoding="utf-8")
|
||||
logger.info("wrote summary -> %s", out)
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
sys.exit(main())
|
||||
+92
-10
@@ -3,13 +3,20 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from typing import Any, Dict, List, Optional
|
||||
import logging
|
||||
from datetime import datetime
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Optional
|
||||
|
||||
from src.agent.memory import WorkspaceMemory
|
||||
from src.agent.skills import SkillsLoader
|
||||
from src.agent.tools import ToolRegistry
|
||||
|
||||
_SYSTEM_PROMPT = """You are a finance research agent with 68 specialist skills, 21 tools, 5 data sources (with auto-fallback), and 29 multi-agent swarm teams.
|
||||
if TYPE_CHECKING:
|
||||
from src.memory.persistent import PersistentMemory
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_SYSTEM_PROMPT = """You are a finance research agent with {skill_count} specialist skills, {tool_count} tools, 5 data sources (with auto-fallback), and 29 multi-agent swarm teams.
|
||||
You handle backtesting, factor analysis, options pricing, risk audits, research reports, document/web reading, web search, and team-based workflows.
|
||||
|
||||
## Tools
|
||||
@@ -35,10 +42,9 @@ Decide which workflow to use based on the request:
|
||||
4. Syntax check → `backtest(run_dir=...)` → `read_file("artifacts/metrics.csv")`
|
||||
5. Do NOT write run_backtest.py. The engine is built-in.
|
||||
|
||||
**Swarm team** — user wants multi-agent analysis, risk audit, committee review, or any task with "team/committee/panel/desk":
|
||||
**Swarm team** — ONLY when the user explicitly requests team/committee/swarm analysis:
|
||||
- Call `run_swarm(prompt="<user's full request>")` — it auto-selects the right preset.
|
||||
- Examples: risk audit, investment committee, equity research, technical panel, cross-market allocation.
|
||||
- Do NOT attempt multi-dimensional analysis solo. Use swarm.
|
||||
- Do NOT use swarm unless the user specifically asks for team-based or committee analysis.
|
||||
|
||||
**Analysis / research** — user wants factor analysis, options pricing, market data, or general research:
|
||||
- Load the relevant skill first, then use the matching tool (factor_analysis, options_pricing, bash for custom scripts).
|
||||
@@ -46,6 +52,21 @@ Decide which workflow to use based on the request:
|
||||
**Document / web** — user provides a PDF or URL:
|
||||
- `read_document(path=...)` for PDFs, `read_url(url=...)` for web pages.
|
||||
|
||||
**Trade journal** — user uploads a CSV/Excel broker export (交割单) or asks to analyze their own trading history:
|
||||
1. `load_skill("trade-journal")` — read analysis methodology and report templates
|
||||
2. `analyze_trade_journal(file_path=..., analysis_type="full")` — parse + profile + behavior diagnostics
|
||||
3. Present results as the markdown report in the skill. Offer follow-ups: time-slice, symbol deep-dive, market split.
|
||||
4. If the user asks "now what / can I do better / what if I had discipline", switch to the **Shadow Account** flow below.
|
||||
|
||||
**Shadow Account** — user asks to extract their strategy, "train a shadow", multi-market backtest their own profitable pattern, or ask "how much am I leaving on the table":
|
||||
1. **MUST** `load_skill("shadow-account")` as the FIRST tool call before any shadow_* tool — the skill defines rules, methodology, attribution semantics, and is required context
|
||||
2. Confirm the journal has been parsed (same session or known `journal_path`). If not, run `analyze_trade_journal` first.
|
||||
3. `extract_shadow_strategy(journal_path=...)` → show rules, ask user to confirm they look like their own behavior
|
||||
4. `run_shadow_backtest(shadow_id=..., journal_path=...)` → multi-market metrics + delta attribution
|
||||
5. `render_shadow_report(shadow_id=...)` → share html/pdf path, lead with the Section 5 "you vs shadow" delta
|
||||
6. Optional: `scan_shadow_signals(shadow_id=...)` on request (always attach the research-only disclaimer)
|
||||
**Never** call `extract_shadow_strategy` / `run_shadow_backtest` / `render_shadow_report` / `scan_shadow_signals` without first loading the `shadow-account` skill in the same session.
|
||||
|
||||
## Guidelines
|
||||
|
||||
- Load the relevant skill BEFORE starting any task. Skills contain the exact API contracts and examples.
|
||||
@@ -53,6 +74,19 @@ Decide which workflow to use based on the request:
|
||||
- Output results as markdown tables. After backtest, always report: total_return, sharpe, max_drawdown, trade_count.
|
||||
- All file paths are relative to run_dir (auto-injected).
|
||||
- Respond in the same language the user used.
|
||||
- You have persistent cross-session memory (`remember` tool). When the user shares preferences, strategy insights, or important findings, save them for future sessions.
|
||||
- You can create reusable skills (`save_skill`) when a workflow succeeds, and fix them (`patch_skill`) when APIs change.
|
||||
{memory_section}
|
||||
## Current Date & Time
|
||||
|
||||
Today is {current_datetime}.
|
||||
"""
|
||||
|
||||
_MEMORY_SECTION = """
|
||||
## Persistent Memory (cross-session)
|
||||
|
||||
{snapshot}
|
||||
|
||||
"""
|
||||
|
||||
|
||||
@@ -66,22 +100,26 @@ class ContextBuilder:
|
||||
"""
|
||||
|
||||
def __init__(self, registry: ToolRegistry, memory: WorkspaceMemory,
|
||||
skills_loader: Optional[SkillsLoader] = None) -> None:
|
||||
skills_loader: Optional[SkillsLoader] = None,
|
||||
persistent_memory: Optional[PersistentMemory] = None) -> None:
|
||||
"""Initialize ContextBuilder.
|
||||
|
||||
Args:
|
||||
registry: Tool registry.
|
||||
memory: Workspace memory.
|
||||
skills_loader: Skills loader (auto-created if not provided).
|
||||
persistent_memory: PersistentMemory instance for cross-session recall.
|
||||
"""
|
||||
self.registry = registry
|
||||
self.memory = memory
|
||||
self.skills_loader = skills_loader or SkillsLoader()
|
||||
self._persistent_memory = persistent_memory
|
||||
|
||||
def build_system_prompt(self, user_message: str = "") -> str:
|
||||
"""Build system prompt.
|
||||
|
||||
Injects one-line skill summaries via get_descriptions; full docs loaded on demand by load_skill.
|
||||
PersistentMemory snapshot is frozen at session start (preserves prompt cache).
|
||||
|
||||
Args:
|
||||
user_message: User message (kept for API compatibility).
|
||||
@@ -89,15 +127,32 @@ class ContextBuilder:
|
||||
Returns:
|
||||
System prompt text.
|
||||
"""
|
||||
now = datetime.now()
|
||||
|
||||
# Build memory section only if there are saved memories
|
||||
memory_section = ""
|
||||
if self._persistent_memory and self._persistent_memory.snapshot:
|
||||
memory_section = _MEMORY_SECTION.format(
|
||||
snapshot=self._persistent_memory.snapshot,
|
||||
)
|
||||
|
||||
return _SYSTEM_PROMPT.format(
|
||||
tool_count=len(self.registry._tools),
|
||||
skill_count=len(self.skills_loader.skills),
|
||||
tool_descriptions=self._format_tool_descriptions(),
|
||||
skill_descriptions=self.skills_loader.get_descriptions(),
|
||||
memory_summary=self.memory.to_summary(),
|
||||
memory_section=memory_section,
|
||||
current_datetime=now.strftime("%A, %B %d, %Y %H:%M (local)"),
|
||||
)
|
||||
|
||||
def build_messages(self, user_message: str, history: Optional[List[Dict[str, Any]]] = None) -> List[Dict[str, Any]]:
|
||||
"""Build full message list.
|
||||
|
||||
Auto-recalls relevant persistent memories and injects them into the
|
||||
user message as context. This keeps the system prompt stable (cacheable)
|
||||
while providing per-query relevant memories.
|
||||
|
||||
Args:
|
||||
user_message: User message.
|
||||
history: Prior conversation messages.
|
||||
@@ -110,7 +165,23 @@ class ContextBuilder:
|
||||
]
|
||||
if history:
|
||||
messages.extend(history)
|
||||
messages.append({"role": "user", "content": user_message})
|
||||
|
||||
# Auto-recall: inject relevant memories into user message
|
||||
enriched = user_message
|
||||
if self._persistent_memory:
|
||||
try:
|
||||
recalls = self._persistent_memory.find_relevant(user_message, max_results=3)
|
||||
if recalls:
|
||||
lines = [f"- **{r.title}** ({r.memory_type}): {r.body[:500]}" for r in recalls]
|
||||
recall_block = "\n".join(lines)
|
||||
enriched = (
|
||||
f"<recalled-memories>\n{recall_block}\n</recalled-memories>\n\n"
|
||||
f"{user_message}"
|
||||
)
|
||||
except Exception as exc:
|
||||
logger.debug("Auto-recall failed: %s", exc)
|
||||
|
||||
messages.append({"role": "user", "content": enriched})
|
||||
return messages
|
||||
|
||||
def _format_tool_descriptions(self) -> str:
|
||||
@@ -138,17 +209,25 @@ class ContextBuilder:
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def format_assistant_tool_calls(tool_calls: list, content: Optional[str] = None) -> Dict[str, Any]:
|
||||
def format_assistant_tool_calls(
|
||||
tool_calls: list,
|
||||
content: Optional[str] = None,
|
||||
reasoning_content: Optional[str] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""Format an assistant tool_calls message, preserving thinking text.
|
||||
|
||||
Args:
|
||||
tool_calls: List of tool call objects.
|
||||
content: Model reasoning/thinking text.
|
||||
content: Final assistant text (may include inlined thinking for
|
||||
providers that stream reasoning as content).
|
||||
reasoning_content: Provider-specific reasoning field (Kimi K2.5,
|
||||
DeepSeek reasoner, Qwen thinking). Only attached to the output
|
||||
message when not None, so non-thinking providers see no change.
|
||||
|
||||
Returns:
|
||||
OpenAI-format assistant message.
|
||||
"""
|
||||
return {
|
||||
message = {
|
||||
"role": "assistant",
|
||||
"content": content,
|
||||
"tool_calls": [
|
||||
@@ -163,3 +242,6 @@ class ContextBuilder:
|
||||
for tc in tool_calls
|
||||
],
|
||||
}
|
||||
if reasoning_content is not None:
|
||||
message["reasoning_content"] = reasoning_content
|
||||
return message
|
||||
@@ -0,0 +1,40 @@
|
||||
"""Shared YAML-like frontmatter parser for skills and memory files."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from typing import Any, Dict
|
||||
|
||||
|
||||
def parse_frontmatter(text: str) -> tuple[Dict[str, Any], str]:
|
||||
"""Parse YAML-like frontmatter and body from a markdown file.
|
||||
|
||||
Supports string, list (``[a, b]``), and boolean values.
|
||||
|
||||
Args:
|
||||
text: Markdown text with optional ``---`` delimited frontmatter.
|
||||
|
||||
Returns:
|
||||
Tuple of (metadata dict, body text).
|
||||
"""
|
||||
match = re.match(r"^---\s*\n(.*?)\n---\s*\n(.*)", text, re.DOTALL)
|
||||
if not match:
|
||||
return {}, text.strip()
|
||||
|
||||
meta: Dict[str, Any] = {}
|
||||
for line in match.group(1).strip().split("\n"):
|
||||
line = line.strip()
|
||||
if ":" not in line:
|
||||
continue
|
||||
key, value = line.split(":", 1)
|
||||
key = key.strip()
|
||||
value = value.strip()
|
||||
if value.startswith("[") and value.endswith("]"):
|
||||
items = [item.strip().strip("'\"") for item in value[1:-1].split(",")]
|
||||
meta[key] = [i for i in items if i]
|
||||
elif value.lower() in ("true", "false"):
|
||||
meta[key] = value.lower() == "true"
|
||||
else:
|
||||
meta[key] = value
|
||||
|
||||
return meta, match.group(2).strip()
|
||||
+557
-89
@@ -1,13 +1,19 @@
|
||||
"""AgentLoop: ReAct core loop.
|
||||
|
||||
Three-layer context management:
|
||||
Layer 1 (microcompact) — silently prunes old tool results each iteration, keeping the most recent 3
|
||||
Layer 2 (auto_compact) — LLM summarises and compresses when token count exceeds threshold, saves transcript
|
||||
Layer 3 (compact tool) — model explicitly calls the compact tool to trigger compression
|
||||
Five-layer context management:
|
||||
Layer 1 (microcompact) — silently prunes old tool results each iteration
|
||||
Layer 2 (context_collapse) — folds long text blocks without LLM call (zero cost)
|
||||
Layer 3 (auto_compact) — LLM structured summary with token-budget tail protection
|
||||
Layer 4 (compact tool) — model explicitly calls the compact tool to trigger L3
|
||||
Layer 5 (iterative update) — Nth compression updates previous summary instead of starting fresh
|
||||
|
||||
Tool execution:
|
||||
- Read/write batching: consecutive readonly tools run in parallel via threads
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import concurrent.futures
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
@@ -28,6 +34,16 @@ TOKEN_THRESHOLD = int(os.getenv("TOKEN_THRESHOLD", "40000"))
|
||||
KEEP_RECENT = 3
|
||||
TOOL_RESULT_LIMIT = 10_000
|
||||
|
||||
# Layer 2: Context collapse thresholds
|
||||
COLLAPSE_THRESHOLD = int(TOKEN_THRESHOLD * 0.7)
|
||||
COLLAPSE_PRESERVE_RECENT = 6
|
||||
COLLAPSE_TEXT_MIN = 2400
|
||||
COLLAPSE_HEAD = 900
|
||||
COLLAPSE_TAIL = 500
|
||||
|
||||
# Layer 3: Token-budget tail protection
|
||||
TAIL_TOKEN_BUDGET = 20_000
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@@ -58,9 +74,192 @@ def _microcompact(messages: list) -> None:
|
||||
msg["content"] = "[cleared]"
|
||||
|
||||
|
||||
def _context_collapse(messages: list) -> None:
|
||||
"""Layer 2: fold long text blocks in older messages without LLM call.
|
||||
|
||||
Preserves head + tail of large text, collapses the middle.
|
||||
Zero API cost — pure string operation.
|
||||
|
||||
Args:
|
||||
messages: Message list (mutated in place).
|
||||
"""
|
||||
if len(messages) <= COLLAPSE_PRESERVE_RECENT + 1:
|
||||
return
|
||||
for msg in messages[1:-COLLAPSE_PRESERVE_RECENT]:
|
||||
content = msg.get("content")
|
||||
if not isinstance(content, str) or len(content) <= COLLAPSE_TEXT_MIN:
|
||||
continue
|
||||
if content == "[cleared]":
|
||||
continue
|
||||
head = content[:COLLAPSE_HEAD]
|
||||
tail = content[-COLLAPSE_TAIL:]
|
||||
trimmed = len(content) - COLLAPSE_HEAD - COLLAPSE_TAIL
|
||||
msg["content"] = f"{head}\n\n...[{trimmed} chars collapsed]...\n\n{tail}"
|
||||
|
||||
|
||||
def _fix_tool_pairs(messages: list) -> None:
|
||||
"""Repair orphaned tool_call / tool_result pairs after compression.
|
||||
|
||||
Two fixes:
|
||||
1. Remove tool results whose matching tool_call was compressed away.
|
||||
2. Insert stub results for tool_calls whose results were compressed away.
|
||||
|
||||
Args:
|
||||
messages: Message list (mutated in place).
|
||||
"""
|
||||
# Collect all tool_call IDs from assistant messages
|
||||
call_ids: set[str] = set()
|
||||
for msg in messages:
|
||||
if msg.get("role") == "assistant":
|
||||
for tc in msg.get("tool_calls", []):
|
||||
tc_id = tc.get("id", "")
|
||||
if tc_id:
|
||||
call_ids.add(tc_id)
|
||||
|
||||
# Remove orphaned tool results
|
||||
i = 0
|
||||
while i < len(messages):
|
||||
msg = messages[i]
|
||||
if msg.get("role") == "tool" and msg.get("tool_call_id") not in call_ids:
|
||||
messages.pop(i)
|
||||
else:
|
||||
i += 1
|
||||
|
||||
# Collect existing result IDs
|
||||
result_ids: set[str] = set()
|
||||
for msg in messages:
|
||||
if msg.get("role") == "tool":
|
||||
tcid = msg.get("tool_call_id", "")
|
||||
if tcid:
|
||||
result_ids.add(tcid)
|
||||
|
||||
# Insert stub results for orphaned tool_calls
|
||||
inserts: list[tuple[int, dict]] = []
|
||||
for idx, msg in enumerate(messages):
|
||||
if msg.get("role") != "assistant":
|
||||
continue
|
||||
for tc in msg.get("tool_calls", []):
|
||||
tc_id = tc.get("id", "")
|
||||
if tc_id and tc_id not in result_ids:
|
||||
stub = {
|
||||
"role": "tool",
|
||||
"tool_call_id": tc_id,
|
||||
"name": tc.get("function", {}).get("name", "unknown"),
|
||||
"content": "[Result from earlier context — see summary above]",
|
||||
}
|
||||
inserts.append((idx + 1, stub))
|
||||
result_ids.add(tc_id)
|
||||
|
||||
for pos, stub in reversed(inserts):
|
||||
messages.insert(pos, stub)
|
||||
|
||||
|
||||
# -- Structured summary templates ------------------------------------------
|
||||
|
||||
_STRUCTURED_SUMMARY_PROMPT = """\
|
||||
Summarize this conversation for handoff to a fresh context window.
|
||||
This summary is the ONLY context available — omitted information is lost.
|
||||
|
||||
Use EXACTLY this structure:
|
||||
|
||||
## Goal
|
||||
What the user is trying to accomplish.
|
||||
|
||||
## Constraints & Preferences
|
||||
User-stated requirements: risk tolerance, strategy parameters, asset preferences.
|
||||
|
||||
## Progress
|
||||
### Done
|
||||
- Completed steps with key results and specific numbers.
|
||||
### In Progress
|
||||
- Current work when compression triggered.
|
||||
|
||||
## Key Decisions
|
||||
Choices made and rationale.
|
||||
|
||||
## Resolved Questions
|
||||
Questions already answered — do NOT re-answer these.
|
||||
|
||||
## Pending User Asks
|
||||
Unfinished requests still needing action.
|
||||
|
||||
## Relevant Files
|
||||
File paths, run_dir, signal engines, artifact locations.
|
||||
|
||||
## Remaining Work
|
||||
What still needs to be done (background reference, NOT active instructions).
|
||||
|
||||
## Critical Context
|
||||
Specific numbers, parameters, error messages, configuration values.
|
||||
|
||||
## Tools & Patterns
|
||||
Which tools worked, what failed, effective approaches.
|
||||
|
||||
IMPORTANT: This is a handoff — background reference, NOT active instructions.
|
||||
Preserve ALL specific numbers, file paths, and parameter values.
|
||||
{focus_section}
|
||||
Conversation to summarize:
|
||||
"""
|
||||
|
||||
_FOCUS_SECTION = """
|
||||
FOCUS TOPIC: {topic}
|
||||
Allocate 60-70% of the summary budget to content related to this topic.
|
||||
Aggressively compress unrelated content to make room.
|
||||
"""
|
||||
|
||||
_ITERATIVE_UPDATE_PROMPT = """\
|
||||
Update the existing summary with new conversation turns.
|
||||
|
||||
PREVIOUS SUMMARY:
|
||||
{previous_summary}
|
||||
|
||||
NEW TURNS TO INCORPORATE:
|
||||
{new_turns}
|
||||
|
||||
Rules:
|
||||
- PRESERVE all existing information from the previous summary.
|
||||
- ADD new progress, decisions, and findings.
|
||||
- Move "In Progress" items to "Done" when completed.
|
||||
- Move answered questions to "Resolved Questions".
|
||||
- Keep the same section structure.
|
||||
- Do NOT drop any critical context from the previous summary.
|
||||
{focus_section}"""
|
||||
|
||||
|
||||
def _is_tool_success(result: str) -> bool:
|
||||
"""Return True if the tool result does not contain an error."""
|
||||
return '"error"' not in result[:200]
|
||||
"""Return True if the tool result does not look like an error response."""
|
||||
try:
|
||||
data = json.loads(result)
|
||||
if isinstance(data, dict) and data.get("status") == "error":
|
||||
return False
|
||||
except (json.JSONDecodeError, TypeError):
|
||||
pass
|
||||
return True
|
||||
|
||||
|
||||
def _normalize_tool_run_dir(args: dict[str, Any], memory_run_dir: str | None) -> dict[str, Any]:
|
||||
"""Normalize ``run_dir`` in tool args to an absolute path when possible.
|
||||
|
||||
If the model supplies a relative ``run_dir`` (for example ``"."`` or
|
||||
``"risk_parity_run"``), resolve it against the active run directory.
|
||||
"""
|
||||
normalized = dict(args)
|
||||
if not memory_run_dir:
|
||||
return normalized
|
||||
|
||||
if "run_dir" not in normalized:
|
||||
normalized["run_dir"] = memory_run_dir
|
||||
return normalized
|
||||
|
||||
run_dir_value = str(normalized["run_dir"]).strip()
|
||||
if not run_dir_value:
|
||||
normalized["run_dir"] = memory_run_dir
|
||||
return normalized
|
||||
|
||||
candidate = Path(run_dir_value)
|
||||
if not candidate.is_absolute():
|
||||
normalized["run_dir"] = str((Path(memory_run_dir) / candidate).resolve())
|
||||
return normalized
|
||||
|
||||
|
||||
class AgentLoop:
|
||||
@@ -80,6 +279,7 @@ class AgentLoop:
|
||||
memory: Optional[WorkspaceMemory] = None,
|
||||
event_callback: Optional[Callable[[str, Dict[str, Any]], None]] = None,
|
||||
max_iterations: int = 50,
|
||||
persistent_memory: Optional[Any] = None,
|
||||
) -> None:
|
||||
"""Initialize AgentLoop.
|
||||
|
||||
@@ -89,6 +289,7 @@ class AgentLoop:
|
||||
memory: Workspace memory (created fresh if not provided).
|
||||
event_callback: Event callback (event_type, data).
|
||||
max_iterations: Maximum number of loop iterations.
|
||||
persistent_memory: PersistentMemory for cross-session recall.
|
||||
"""
|
||||
self.registry = registry
|
||||
self.llm = llm
|
||||
@@ -97,6 +298,8 @@ class AgentLoop:
|
||||
self.max_iterations = max_iterations
|
||||
self._called_ok: set[str] = set()
|
||||
self._cancelled: bool = False
|
||||
self._previous_summary: str = ""
|
||||
self._persistent_memory = persistent_memory
|
||||
|
||||
def cancel(self) -> None:
|
||||
"""Cancel the current loop.
|
||||
@@ -116,6 +319,11 @@ class AgentLoop:
|
||||
Returns:
|
||||
Execution result dict.
|
||||
"""
|
||||
# Reset per-run state (safe for reuse across multiple run() calls)
|
||||
self._cancelled = False
|
||||
self._called_ok = set()
|
||||
self._previous_summary = ""
|
||||
|
||||
state_store = RunStateStore()
|
||||
RUNS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
@@ -127,7 +335,8 @@ class AgentLoop:
|
||||
|
||||
state_store.save_request(run_dir, user_message, {"session_id": session_id})
|
||||
|
||||
context = ContextBuilder(self.registry, self.memory)
|
||||
context = ContextBuilder(self.registry, self.memory,
|
||||
persistent_memory=self._persistent_memory)
|
||||
messages = context.build_messages(user_message, history)
|
||||
react_trace: List[Dict[str, Any]] = []
|
||||
|
||||
@@ -157,8 +366,13 @@ class AgentLoop:
|
||||
# Layer 1: microcompact (every iteration)
|
||||
_microcompact(messages)
|
||||
|
||||
# Layer 2: auto_compact (token threshold exceeded)
|
||||
# Layer 2: context collapse (fold long text, zero API cost)
|
||||
tokens = estimate_tokens(messages)
|
||||
if tokens > COLLAPSE_THRESHOLD:
|
||||
_context_collapse(messages)
|
||||
tokens = estimate_tokens(messages)
|
||||
|
||||
# Layer 3: auto_compact (token threshold exceeded)
|
||||
if tokens > TOKEN_THRESHOLD:
|
||||
logger.info(f"Auto compact triggered: {tokens} tokens > {TOKEN_THRESHOLD}")
|
||||
self._auto_compact(messages, run_dir, trace)
|
||||
@@ -189,58 +403,23 @@ class AgentLoop:
|
||||
react_trace.append({"type": "answer", "content": final_content[:500]})
|
||||
break
|
||||
|
||||
messages.append(context.format_assistant_tool_calls(response.tool_calls, content=response.content))
|
||||
messages.append(
|
||||
context.format_assistant_tool_calls(
|
||||
response.tool_calls,
|
||||
content=response.content,
|
||||
reasoning_content=response.reasoning_content or thinking_text or None,
|
||||
)
|
||||
)
|
||||
|
||||
compact_requested = False
|
||||
|
||||
for tc in response.tool_calls:
|
||||
tool_def = self.registry.get(tc.name)
|
||||
|
||||
# Layer 3: compact tool — mark then defer execution
|
||||
if tc.name == "compact":
|
||||
compact_requested = True
|
||||
messages.append(context.format_tool_result(tc.id, "compact", '{"status":"ok","message":"Compressing..."}'))
|
||||
trace.write({"type": "compact_requested", "iter": iteration})
|
||||
continue
|
||||
|
||||
is_repeatable = tool_def.repeatable if tool_def else False
|
||||
if tc.name in self._called_ok and not is_repeatable:
|
||||
logger.warning(f"Blocked duplicate call: {tc.name} (already succeeded)")
|
||||
skip_msg = json.dumps({"skipped": True, "reason": f"{tc.name} already completed successfully. Use the previous result."})
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, skip_msg))
|
||||
trace.write({"type": "tool_skipped", "iter": iteration, "tool": tc.name})
|
||||
react_trace.append({"type": "tool_skipped", "tool": tc.name})
|
||||
continue
|
||||
|
||||
self._emit("tool_call", {"tool": tc.name, "arguments": {k: str(v)[:200] for k, v in tc.arguments.items()}, "iter": iteration})
|
||||
trace.write({"type": "tool_call", "iter": iteration, "tool": tc.name, "args": {k: str(v)[:200] for k, v in tc.arguments.items()}})
|
||||
logger.info(f"Tool call: {tc.name}({list(tc.arguments.keys())})")
|
||||
|
||||
if "run_dir" not in tc.arguments and self.memory.run_dir:
|
||||
tc.arguments["run_dir"] = self.memory.run_dir
|
||||
|
||||
t0 = _time.perf_counter()
|
||||
result = self.registry.execute(tc.name, tc.arguments)
|
||||
elapsed_ms = int((_time.perf_counter() - t0) * 1000)
|
||||
|
||||
self._update_memory(tc.name, result, state_store, run_dir)
|
||||
|
||||
if _is_tool_success(result):
|
||||
self._called_ok.add(tc.name)
|
||||
|
||||
status = "ok" if _is_tool_success(result) else "error"
|
||||
truncated = result[:TOOL_RESULT_LIMIT]
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, truncated))
|
||||
|
||||
trace.write({"type": "tool_result", "iter": iteration, "tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
react_trace.append({"type": "tool_call", "tool": tc.name, "result_preview": result[:200]})
|
||||
|
||||
self._emit("tool_result", {"tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
# Execute tools with read/write batching
|
||||
compact_requested, focus_topic = self._process_tool_calls(
|
||||
response.tool_calls, context, messages, trace, react_trace, iteration,
|
||||
)
|
||||
|
||||
# Layer 3: compress after all tools have executed
|
||||
if compact_requested:
|
||||
logger.info("Manual compact triggered by model")
|
||||
self._auto_compact(messages, run_dir, trace)
|
||||
self._auto_compact(messages, run_dir, trace, focus_topic=focus_topic)
|
||||
|
||||
except Exception as exc:
|
||||
logger.exception(f"AgentLoop error: {exc}")
|
||||
@@ -256,69 +435,364 @@ class AgentLoop:
|
||||
"react_trace": react_trace,
|
||||
}
|
||||
|
||||
# Determine final status
|
||||
# Determine final status. The reason is also propagated into the
|
||||
# returned dict so SessionService can surface a meaningful UI
|
||||
# message instead of "Execution failed: unknown" (issue #114).
|
||||
final_reason: str | None = None
|
||||
if self._cancelled:
|
||||
state_store.mark_failure(run_dir, "cancelled by user")
|
||||
final_reason = "cancelled by user"
|
||||
state_store.mark_failure(run_dir, final_reason)
|
||||
final_status = "cancelled"
|
||||
elif (run_dir / "artifacts" / "metrics.csv").exists() or final_content:
|
||||
state_store.mark_success(run_dir)
|
||||
final_status = "success"
|
||||
else:
|
||||
state_store.mark_failure(run_dir, "pipeline did not complete")
|
||||
final_reason = (
|
||||
f"reached max iterations ({self.max_iterations}) without final answer"
|
||||
)
|
||||
state_store.mark_failure(run_dir, final_reason)
|
||||
final_status = "failed"
|
||||
|
||||
trace.write({"type": "end", "status": final_status, "iterations": iteration})
|
||||
end_event: dict[str, Any] = {
|
||||
"type": "end",
|
||||
"status": final_status,
|
||||
"iterations": iteration,
|
||||
}
|
||||
if final_reason is not None:
|
||||
end_event["reason"] = final_reason
|
||||
trace.write(end_event)
|
||||
trace.close()
|
||||
|
||||
return {
|
||||
result: dict[str, Any] = {
|
||||
"status": final_status,
|
||||
"run_dir": str(run_dir),
|
||||
"run_id": run_dir.name,
|
||||
"content": final_content,
|
||||
"react_trace": react_trace,
|
||||
"iterations": iteration,
|
||||
"max_iterations": self.max_iterations,
|
||||
}
|
||||
if final_reason is not None:
|
||||
result["reason"] = final_reason
|
||||
return result
|
||||
|
||||
def _auto_compact(self, messages: list, run_dir: Path, trace: TraceWriter) -> None:
|
||||
"""Layer 2/3: LLM summarise-and-compress; saves transcript before compressing.
|
||||
# -- Tool execution with read/write batching --------------------------------
|
||||
|
||||
def _process_tool_calls(
|
||||
self,
|
||||
tool_calls: list,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> tuple[bool, str]:
|
||||
"""Pre-process tool calls: handle compact, filter duplicates, batch execute.
|
||||
|
||||
Args:
|
||||
tool_calls: Raw tool calls from LLM response.
|
||||
context: ContextBuilder for formatting messages.
|
||||
messages: Conversation messages (appended in place).
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration number.
|
||||
|
||||
Returns:
|
||||
Tuple of (compact_requested, focus_topic).
|
||||
"""
|
||||
compact_requested = False
|
||||
focus_topic = ""
|
||||
to_execute = []
|
||||
|
||||
for tc in tool_calls:
|
||||
# Layer 4: compact tool — mark then defer execution
|
||||
if tc.name == "compact":
|
||||
compact_requested = True
|
||||
focus_topic = tc.arguments.get("focus_topic", "")
|
||||
messages.append(context.format_tool_result(tc.id, "compact", '{"status":"ok","message":"Compressing..."}'))
|
||||
trace.write({"type": "compact_requested", "iter": iteration})
|
||||
continue
|
||||
|
||||
tool_def = self.registry.get(tc.name)
|
||||
is_repeatable = tool_def.repeatable if tool_def else False
|
||||
if tc.name in self._called_ok and not is_repeatable:
|
||||
logger.warning(f"Blocked duplicate call: {tc.name} (already succeeded)")
|
||||
skip_msg = json.dumps({"skipped": True, "reason": f"{tc.name} already completed successfully. Use the previous result."})
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, skip_msg))
|
||||
trace.write({"type": "tool_skipped", "iter": iteration, "tool": tc.name})
|
||||
react_trace.append({"type": "tool_skipped", "tool": tc.name})
|
||||
continue
|
||||
|
||||
to_execute.append(tc)
|
||||
|
||||
if not to_execute:
|
||||
return compact_requested, focus_topic
|
||||
|
||||
# Batch execute: consecutive readonly → parallel, write → serial
|
||||
if len(to_execute) == 1:
|
||||
self._execute_single(to_execute[0], context, messages, trace, react_trace, iteration)
|
||||
else:
|
||||
self._batch_execute(to_execute, context, messages, trace, react_trace, iteration)
|
||||
|
||||
return compact_requested, focus_topic
|
||||
|
||||
def _batch_execute(
|
||||
self,
|
||||
tool_calls: list,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Execute tools with read/write batching.
|
||||
|
||||
Consecutive readonly tools run in parallel via ThreadPoolExecutor.
|
||||
Write tools run serially between readonly batches.
|
||||
|
||||
Args:
|
||||
tool_calls: Tool calls to execute.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
# Split into batches: consecutive readonly → parallel, write → serial
|
||||
batches: list[tuple[str, list]] = []
|
||||
current_ro: list = []
|
||||
|
||||
for tc in tool_calls:
|
||||
tool_def = self.registry.get(tc.name)
|
||||
if tool_def and tool_def.is_readonly:
|
||||
current_ro.append(tc)
|
||||
else:
|
||||
if current_ro:
|
||||
batches.append(("parallel", current_ro))
|
||||
current_ro = []
|
||||
batches.append(("serial", [tc]))
|
||||
if current_ro:
|
||||
batches.append(("parallel", current_ro))
|
||||
|
||||
for mode, batch in batches:
|
||||
if mode == "parallel" and len(batch) > 1:
|
||||
self._execute_parallel(batch, context, messages, trace, react_trace, iteration)
|
||||
else:
|
||||
for tc in batch:
|
||||
self._execute_single(tc, context, messages, trace, react_trace, iteration)
|
||||
|
||||
def _execute_parallel(
|
||||
self,
|
||||
tool_calls: list,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Execute readonly tools in parallel using threads.
|
||||
|
||||
Args:
|
||||
tool_calls: Readonly tool calls to execute in parallel.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
# Prepare args + emit events
|
||||
runnable: list[tuple] = []
|
||||
for tc in tool_calls:
|
||||
args = _normalize_tool_run_dir(tc.arguments, self.memory.run_dir)
|
||||
self._emit("tool_call", {"tool": tc.name, "arguments": {k: str(v)[:200] for k, v in args.items()}, "iter": iteration})
|
||||
trace.write({"type": "tool_call", "iter": iteration, "tool": tc.name, "args": {k: str(v)[:200] for k, v in args.items()}})
|
||||
runnable.append((tc, args))
|
||||
|
||||
# Execute in parallel
|
||||
def _run(tc_args: tuple) -> tuple:
|
||||
tc, args = tc_args
|
||||
t0 = _time.perf_counter()
|
||||
result = self.registry.execute(tc.name, args)
|
||||
elapsed_ms = int((_time.perf_counter() - t0) * 1000)
|
||||
return tc, result, elapsed_ms
|
||||
|
||||
with concurrent.futures.ThreadPoolExecutor(max_workers=min(len(runnable), 8)) as pool:
|
||||
futures = [pool.submit(_run, item) for item in runnable]
|
||||
results = []
|
||||
for i, f in enumerate(futures):
|
||||
try:
|
||||
results.append(f.result())
|
||||
except Exception as exc:
|
||||
tc = runnable[i][0]
|
||||
results.append((tc, json.dumps({"status": "error", "error": str(exc)}), 0))
|
||||
|
||||
# Process results in order
|
||||
for tc, result, elapsed_ms in results:
|
||||
self._finalize_tool_result(tc, result, elapsed_ms, context, messages, trace, react_trace, iteration)
|
||||
|
||||
def _execute_single(
|
||||
self,
|
||||
tc: Any,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Execute a single tool call.
|
||||
|
||||
Args:
|
||||
tc: Tool call object.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
args = _normalize_tool_run_dir(tc.arguments, self.memory.run_dir)
|
||||
|
||||
self._emit("tool_call", {"tool": tc.name, "arguments": {k: str(v)[:200] for k, v in args.items()}, "iter": iteration})
|
||||
trace.write({"type": "tool_call", "iter": iteration, "tool": tc.name, "args": {k: str(v)[:200] for k, v in args.items()}})
|
||||
logger.info(f"Tool call: {tc.name}({list(args.keys())})")
|
||||
|
||||
t0 = _time.perf_counter()
|
||||
result = self.registry.execute(tc.name, args)
|
||||
elapsed_ms = int((_time.perf_counter() - t0) * 1000)
|
||||
|
||||
self._finalize_tool_result(tc, result, elapsed_ms, context, messages, trace, react_trace, iteration)
|
||||
|
||||
def _finalize_tool_result(
|
||||
self,
|
||||
tc: Any,
|
||||
result: str,
|
||||
elapsed_ms: int,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Record a tool result: update memory, append message, write trace, emit event.
|
||||
|
||||
Args:
|
||||
tc: Tool call object.
|
||||
result: Raw tool result string.
|
||||
elapsed_ms: Execution time in milliseconds.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
self._update_memory(tc.name)
|
||||
|
||||
success = _is_tool_success(result)
|
||||
if success:
|
||||
self._called_ok.add(tc.name)
|
||||
|
||||
status = "ok" if success else "error"
|
||||
truncated = result[:TOOL_RESULT_LIMIT]
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, truncated))
|
||||
|
||||
trace.write({"type": "tool_result", "iter": iteration, "tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
react_trace.append({"type": "tool_call", "tool": tc.name, "result_preview": result[:200]})
|
||||
self._emit("tool_result", {"tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
|
||||
# -- Context compression ---------------------------------------------------
|
||||
|
||||
def _auto_compact(self, messages: list, run_dir: Path, trace: TraceWriter,
|
||||
focus_topic: str = "") -> None:
|
||||
"""Layer 3/4/5: structured LLM summary with token-budget tail protection.
|
||||
|
||||
Upgrades over the original:
|
||||
- Token-budget tail: keeps ~20K tokens of recent messages (not a fixed count).
|
||||
- Structured summary template: preserves goal, progress, decisions, files, etc.
|
||||
- Iterative update: Nth compression updates previous summary, zero info decay.
|
||||
- Tool pair fix: repairs orphaned tool_call/tool_result after compression.
|
||||
- Focus-topic: optionally prioritize specific topic in summary.
|
||||
|
||||
Args:
|
||||
messages: Message list (replaced in place).
|
||||
run_dir: Run directory.
|
||||
trace: TraceWriter.
|
||||
focus_topic: Optional topic to prioritize in the summary.
|
||||
"""
|
||||
# Save full transcript (timestamped, one file per compression)
|
||||
# Save full transcript before compressing
|
||||
transcript_path = run_dir / f"transcript_{int(_time.time())}.jsonl"
|
||||
with open(transcript_path, "w", encoding="utf-8") as f:
|
||||
for msg in messages:
|
||||
f.write(json.dumps(msg, default=str, ensure_ascii=False) + "\n")
|
||||
|
||||
# LLM summary (no tools, plain text)
|
||||
conv_text = json.dumps(messages[1:], default=str, ensure_ascii=False)[:80000]
|
||||
summary_resp = self.llm.chat([
|
||||
{"role": "user", "content": (
|
||||
"Summarize this conversation for continuity. Include: "
|
||||
"1) What was accomplished, 2) Current state, 3) Key decisions made. "
|
||||
"Be concise but preserve critical details.\n\n" + conv_text
|
||||
)},
|
||||
])
|
||||
system_msg = messages[0]
|
||||
body = messages[1:]
|
||||
|
||||
# Token-budget tail: walk backward to find how many recent messages to preserve
|
||||
accumulated = 0
|
||||
cut_idx = len(body)
|
||||
for i in range(len(body) - 1, -1, -1):
|
||||
content = body[i].get("content", "")
|
||||
msg_tokens = (len(str(content)) // 4) + 10
|
||||
if accumulated + msg_tokens > TAIL_TOKEN_BUDGET:
|
||||
cut_idx = i + 1
|
||||
break
|
||||
accumulated += msg_tokens
|
||||
cut_idx = i
|
||||
|
||||
# Don't split in the middle of a tool_call/tool_result pair
|
||||
while 0 < cut_idx < len(body) and body[cut_idx].get("role") == "tool":
|
||||
cut_idx += 1
|
||||
|
||||
head = body[:cut_idx]
|
||||
tail = body[cut_idx:]
|
||||
|
||||
if not head:
|
||||
# All body fits in tail budget — force a split to avoid infinite loop
|
||||
if len(body) > 2:
|
||||
cut_idx = max(1, len(body) // 2)
|
||||
head = body[:cut_idx]
|
||||
tail = body[cut_idx:]
|
||||
else:
|
||||
logger.warning("Auto compact: nothing to compress (body too small)")
|
||||
return
|
||||
|
||||
# Build focus section
|
||||
focus_section = _FOCUS_SECTION.format(topic=focus_topic) if focus_topic else ""
|
||||
|
||||
# Build summary prompt (structured template or iterative update)
|
||||
conv_text = json.dumps(head, default=str, ensure_ascii=False)[:80000]
|
||||
|
||||
if self._previous_summary:
|
||||
prompt = _ITERATIVE_UPDATE_PROMPT.format(
|
||||
previous_summary=self._previous_summary,
|
||||
new_turns=conv_text,
|
||||
focus_section=focus_section,
|
||||
)
|
||||
else:
|
||||
prompt = _STRUCTURED_SUMMARY_PROMPT.format(focus_section=focus_section) + conv_text
|
||||
|
||||
summary_resp = self.llm.chat([{"role": "user", "content": prompt}])
|
||||
summary = summary_resp.content or ""
|
||||
self._previous_summary = summary
|
||||
|
||||
tokens_before = estimate_tokens(messages)
|
||||
trace.write({"type": "compact", "tokens_before": tokens_before, "summary": summary[:500]})
|
||||
trace.write({"type": "compact", "tokens_before": tokens_before, "summary": summary[:500],
|
||||
"focus_topic": focus_topic or "(none)"})
|
||||
self._emit("compact", {"tokens_before": tokens_before, "summary": summary[:200]})
|
||||
|
||||
# Replace: keep system prompt + inject compressed summary + restore identity
|
||||
system_msg = messages[0]
|
||||
# Reconstruct: system + summary + acknowledge + preserved tail
|
||||
state_summary = self.memory.to_summary()
|
||||
compressed = f"[Conversation compressed. Transcript: {transcript_path}]\n\n{summary}"
|
||||
compressed = f"[Conversation compressed — handoff summary. Transcript: {transcript_path}]\n\n{summary}"
|
||||
if state_summary and state_summary != "(empty state)":
|
||||
compressed += f"\n\nCurrent agent state:\n{state_summary}"
|
||||
|
||||
messages.clear()
|
||||
messages.extend([
|
||||
system_msg,
|
||||
{"role": "user", "content": compressed},
|
||||
{"role": "assistant", "content": "Understood. I have the context from the summary. Continuing."},
|
||||
])
|
||||
messages.append(system_msg)
|
||||
messages.append({"role": "user", "content": compressed})
|
||||
messages.append({"role": "assistant", "content": "Understood. Continuing from the summary."})
|
||||
messages.extend(tail)
|
||||
|
||||
# Fix orphaned tool pairs in the reconstructed message list
|
||||
_fix_tool_pairs(messages)
|
||||
|
||||
def _emit(self, event_type: str, data: Dict[str, Any]) -> None:
|
||||
"""Fire an event via the callback."""
|
||||
@@ -328,12 +802,6 @@ class AgentLoop:
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _update_memory(self, tool_name: str, result: str, state_store: RunStateStore, run_dir: Path) -> None:
|
||||
"""Update memory and persist tool result."""
|
||||
def _update_memory(self, tool_name: str) -> None:
|
||||
"""Update workspace memory counters after tool execution."""
|
||||
self.memory.increment(tool_name)
|
||||
try:
|
||||
data = json.loads(result)
|
||||
if isinstance(data, dict):
|
||||
state_store.persist_tool_result(tool_name, data, run_dir)
|
||||
except (json.JSONDecodeError, TypeError):
|
||||
pass
|
||||
+12
-85
@@ -1,7 +1,7 @@
|
||||
"""Workspace memory: shared state across tool calls.
|
||||
"""Workspace memory: shared state across tool calls within a single run.
|
||||
|
||||
WorkspaceMemory passes intermediate results between tools during an agent run.
|
||||
Generic KV store + counters; no tool-specific fields.
|
||||
Lightweight runtime state — survives within one AgentLoop.run() invocation only.
|
||||
Cross-session persistence is handled by src.memory.persistent.PersistentMemory.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
@@ -12,53 +12,21 @@ from typing import Any, Dict, Optional
|
||||
|
||||
@dataclass
|
||||
class WorkspaceMemory:
|
||||
"""Shared workspace state between tools.
|
||||
"""Shared workspace state between tools during a single agent run.
|
||||
|
||||
Attributes:
|
||||
run_dir: Current run directory.
|
||||
store: Generic result store (tool memory_key -> JSON string).
|
||||
run_dir: Current run directory path.
|
||||
counters: Tool invocation counters.
|
||||
extra: Generic KV store for derived values passed between tools.
|
||||
"""
|
||||
|
||||
run_dir: Optional[str] = None
|
||||
store: Dict[str, str] = field(default_factory=dict)
|
||||
counters: Dict[str, int] = field(default_factory=dict)
|
||||
extra: Dict[str, Any] = field(default_factory=dict)
|
||||
|
||||
def reset(self) -> None:
|
||||
"""Reset all state."""
|
||||
self.run_dir = None
|
||||
self.store.clear()
|
||||
self.counters.clear()
|
||||
self.extra.clear()
|
||||
|
||||
def set_result(self, key: str, value: str) -> None:
|
||||
"""Store a tool result.
|
||||
|
||||
Args:
|
||||
key: Memory key (e.g. "plan_output").
|
||||
value: JSON string.
|
||||
"""
|
||||
self.store[key] = value
|
||||
|
||||
def get_result(self, key: str, default: Optional[str] = None) -> Optional[str]:
|
||||
"""Retrieve a tool result.
|
||||
|
||||
Args:
|
||||
key: Memory key.
|
||||
default: Default value.
|
||||
|
||||
Returns:
|
||||
JSON string or default.
|
||||
"""
|
||||
return self.store.get(key, default)
|
||||
|
||||
def increment(self, key: str) -> int:
|
||||
"""Increment a counter and return the new value.
|
||||
|
||||
Args:
|
||||
key: Counter key.
|
||||
key: Counter key (typically tool name).
|
||||
|
||||
Returns:
|
||||
Updated counter value.
|
||||
@@ -66,60 +34,19 @@ class WorkspaceMemory:
|
||||
self.counters[key] = self.counters.get(key, 0) + 1
|
||||
return self.counters[key]
|
||||
|
||||
def set_extra(self, key: str, value: Any) -> None:
|
||||
"""Set an extra KV entry.
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
value: Value.
|
||||
"""
|
||||
self.extra[key] = value
|
||||
|
||||
def get_extra(self, key: str, default: Any = None) -> Any:
|
||||
"""Get an extra KV entry.
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
default: Default value.
|
||||
|
||||
Returns:
|
||||
Stored value or default.
|
||||
"""
|
||||
return self.extra.get(key, default)
|
||||
|
||||
def set(self, key: str, value: Any) -> None:
|
||||
"""Set a KV entry (alias for set_extra).
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
value: Value.
|
||||
"""
|
||||
self.extra[key] = value
|
||||
|
||||
def get(self, key: str, default: Any = None) -> Any:
|
||||
"""Get a KV entry (alias for get_extra).
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
default: Default value.
|
||||
|
||||
Returns:
|
||||
Stored value or default.
|
||||
"""
|
||||
return self.extra.get(key, default)
|
||||
|
||||
def to_summary(self) -> str:
|
||||
"""Generate a state summary for the LLM indicating completed steps.
|
||||
"""Generate a state summary for the LLM.
|
||||
|
||||
Includes run_dir and tool counters.
|
||||
This summary survives context compression and helps the LLM
|
||||
remember what it was working on.
|
||||
|
||||
Returns:
|
||||
State summary text.
|
||||
"""
|
||||
lines = []
|
||||
lines: list[str] = []
|
||||
if self.run_dir:
|
||||
lines.append(f"- run_dir: {self.run_dir}")
|
||||
if self.store:
|
||||
completed = list(self.store.keys())
|
||||
lines.append(f"- completed: {', '.join(completed)}")
|
||||
if self.counters:
|
||||
counter_parts = [f"{k}={v}" for k, v in self.counters.items()]
|
||||
lines.append(f"- counters: {', '.join(counter_parts)}")
|
||||
|
||||
+36
-42
@@ -53,36 +53,7 @@ class Skill:
|
||||
return None
|
||||
|
||||
|
||||
def _parse_frontmatter(text: str) -> tuple[Dict[str, Any], str]:
|
||||
"""Parse YAML frontmatter and body.
|
||||
|
||||
Args:
|
||||
text: Markdown text.
|
||||
|
||||
Returns:
|
||||
Tuple of (metadata dict, body text).
|
||||
"""
|
||||
match = re.match(r"^---\s*\n(.*?)\n---\s*\n(.*)", text, re.DOTALL)
|
||||
if not match:
|
||||
return {}, text.strip()
|
||||
|
||||
meta: Dict[str, Any] = {}
|
||||
for line in match.group(1).strip().split("\n"):
|
||||
line = line.strip()
|
||||
if ":" not in line:
|
||||
continue
|
||||
key, value = line.split(":", 1)
|
||||
key = key.strip()
|
||||
value = value.strip()
|
||||
if value.startswith("[") and value.endswith("]"):
|
||||
items = [item.strip().strip("'\"") for item in value[1:-1].split(",")]
|
||||
meta[key] = [i for i in items if i]
|
||||
elif value.lower() in ("true", "false"):
|
||||
meta[key] = value.lower() == "true"
|
||||
else:
|
||||
meta[key] = value
|
||||
|
||||
return meta, match.group(2).strip()
|
||||
from src.agent.frontmatter import parse_frontmatter as _parse_frontmatter # shared util
|
||||
|
||||
|
||||
def _load_skill_dir(dir_path: Path) -> Optional[Skill]:
|
||||
@@ -117,32 +88,45 @@ def _load_skill_dir(dir_path: Path) -> Optional[Skill]:
|
||||
)
|
||||
|
||||
|
||||
USER_SKILLS_DIR = Path.home() / ".vibe-trading" / "skills" / "user"
|
||||
|
||||
|
||||
class SkillsLoader:
|
||||
"""Load skills from the skills/ directory.
|
||||
"""Load skills from bundled skills/ directory and user skills directory.
|
||||
|
||||
Attributes:
|
||||
skills: Loaded skill list.
|
||||
skills: Loaded skill list (bundled + user-created).
|
||||
"""
|
||||
|
||||
def __init__(self, skills_dir: Optional[Path] = None) -> None:
|
||||
def __init__(self, skills_dir: Optional[Path] = None,
|
||||
user_skills_dir: Optional[Path] = None) -> None:
|
||||
"""Initialize SkillsLoader.
|
||||
|
||||
Args:
|
||||
skills_dir: Skills directory path; defaults to agent/skills/.
|
||||
skills_dir: Bundled skills directory path; defaults to agent/skills/.
|
||||
user_skills_dir: User-created skills directory; defaults to ~/.vibe-trading/skills/user/.
|
||||
"""
|
||||
self.skills_dir = skills_dir or Path(__file__).resolve().parents[1] / "skills"
|
||||
self._user_skills_dir = user_skills_dir or USER_SKILLS_DIR
|
||||
self.skills: List[Skill] = []
|
||||
self._load()
|
||||
|
||||
def _load(self) -> None:
|
||||
"""Load all skill subdirectories from the skills directory."""
|
||||
if not self.skills_dir.exists():
|
||||
return
|
||||
for path in sorted(self.skills_dir.iterdir()):
|
||||
if path.is_dir() and (path / "SKILL.md").exists():
|
||||
skill = _load_skill_dir(path)
|
||||
if skill:
|
||||
self.skills.append(skill)
|
||||
"""Load all skill subdirectories from user and bundled directories.
|
||||
|
||||
User skills are loaded first so they override bundled skills with the same name
|
||||
(e.g. after patch_skill copies and modifies a bundled skill).
|
||||
"""
|
||||
seen_names: set[str] = set()
|
||||
for directory in (self._user_skills_dir, self.skills_dir):
|
||||
if not directory or not directory.exists():
|
||||
continue
|
||||
for path in sorted(directory.iterdir()):
|
||||
if path.is_dir() and (path / "SKILL.md").exists():
|
||||
skill = _load_skill_dir(path)
|
||||
if skill and skill.name not in seen_names:
|
||||
self.skills.append(skill)
|
||||
seen_names.add(skill.name)
|
||||
|
||||
# Display order for categories (unlisted categories appear at the end).
|
||||
_CATEGORY_ORDER = [
|
||||
@@ -176,6 +160,8 @@ class SkillsLoader:
|
||||
def get_content(self, name: str) -> str:
|
||||
"""Return the full documentation for a skill (used by the load_skill tool).
|
||||
|
||||
Falls back to disk lookup for user skills created mid-session.
|
||||
|
||||
Args:
|
||||
name: Skill name.
|
||||
|
||||
@@ -185,5 +171,13 @@ class SkillsLoader:
|
||||
for skill in self.skills:
|
||||
if skill.name == name:
|
||||
return f'<skill name="{name}">\n{skill.body}\n</skill>'
|
||||
|
||||
# Fallback: check user skills directory on disk (mid-session created skills)
|
||||
if self._user_skills_dir:
|
||||
skill = _load_skill_dir(self._user_skills_dir / name)
|
||||
if skill:
|
||||
self.skills.append(skill)
|
||||
return f'<skill name="{name}">\n{skill.body}\n</skill>'
|
||||
|
||||
available = ", ".join(s.name for s in self.skills)
|
||||
return f"Error: Unknown skill '{name}'. Available: {available}"
|
||||
@@ -3,8 +3,10 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import traceback
|
||||
import logging
|
||||
from abc import ABC, abstractmethod
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
|
||||
@@ -22,6 +24,16 @@ class BaseTool(ABC):
|
||||
description: str = ""
|
||||
parameters: Dict[str, Any] = {}
|
||||
repeatable: bool = False
|
||||
is_readonly: bool = True
|
||||
|
||||
@classmethod
|
||||
def check_available(cls) -> bool:
|
||||
"""Check if this tool's dependencies are met.
|
||||
|
||||
Override in subclasses to check for API keys, packages, etc.
|
||||
Tools that return False are excluded from the registry.
|
||||
"""
|
||||
return True
|
||||
|
||||
@abstractmethod
|
||||
def execute(self, **kwargs: Any) -> str:
|
||||
@@ -65,9 +77,10 @@ class ToolRegistry:
|
||||
try:
|
||||
return tool.execute(**params)
|
||||
except Exception as exc:
|
||||
logger.exception("Tool %s failed", name)
|
||||
return json.dumps({
|
||||
"status": "error", "tool": name,
|
||||
"error": str(exc), "traceback": traceback.format_exc()[-500:],
|
||||
"error": str(exc),
|
||||
}, ensure_ascii=False)
|
||||
|
||||
@property
|
||||
|
||||
@@ -0,0 +1 @@
|
||||
"""HTTP route packages mounted onto the main FastAPI app in ``api_server.py``."""
|
||||
@@ -0,0 +1,564 @@
|
||||
"""Alpha Zoo HTTP routes for the Web UI.
|
||||
|
||||
Mounted by ``agent/api_server.py`` via ``register_alpha_routes(app, ...)``. Pulled
|
||||
into its own module because ``api_server.py`` is already ~1800 lines.
|
||||
|
||||
Routes (auth via the caller-supplied ``require_auth`` /
|
||||
``require_event_stream_auth`` dependencies):
|
||||
|
||||
- ``GET /alpha/list`` — list alphas with optional filters
|
||||
- ``GET /alpha/{alpha_id}`` — single alpha meta + source
|
||||
- ``POST /alpha/bench`` — kick off a background bench (returns job_id)
|
||||
- ``GET /alpha/bench/{job_id}/stream`` — SSE: progress / result / done / error
|
||||
|
||||
Job state lives in the module-level ``ALPHA_BENCH_JOBS`` dict, guarded by
|
||||
``_JOBS_LOCK``. No persistence — process restart wipes job state, which is
|
||||
acceptable for v1 (a bench takes 5-10 min; users re-trigger).
|
||||
|
||||
Concurrency: at most ``MAX_CONCURRENT_BENCHES`` bench workers run at the same
|
||||
time across the process. POST returns 429 when the cap is reached. Workers run
|
||||
in a thread (``asyncio.to_thread``) and we hold task references in a module
|
||||
set so the loop's garbage collector cannot cancel them mid-run.
|
||||
|
||||
Error surface: typed errors (``ValueError`` on bad period, ``KeyError`` on
|
||||
unknown alpha_id) bubble out with their original message. Anything else is
|
||||
logged with full traceback and reported to clients as ``"internal error; see
|
||||
server logs"`` to avoid leaking stack frames / paths.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
import logging
|
||||
import re
|
||||
import threading
|
||||
import time
|
||||
import uuid
|
||||
from datetime import datetime, timezone
|
||||
from typing import Any, Awaitable, Callable
|
||||
|
||||
from fastapi import Depends, FastAPI, HTTPException, Query, Request
|
||||
from fastapi.responses import StreamingResponse
|
||||
from pydantic import BaseModel, Field, field_validator
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Job store (in-memory, process-local)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
ALPHA_BENCH_JOBS: dict[str, dict[str, Any]] = {}
|
||||
_JOBS_LOCK = threading.Lock()
|
||||
|
||||
# Live background bench tasks. Holding strong refs prevents the asyncio GC from
|
||||
# cancelling fire-and-forget tasks; ``add`` on create, ``discard`` on done.
|
||||
_RUNNING_TASKS: set[asyncio.Task[Any]] = set()
|
||||
|
||||
_JOB_TTL_SECONDS = 60 * 60 # prune jobs older than 1 hour on each new POST
|
||||
_POLL_INTERVAL_SECONDS = 0.5
|
||||
_SSE_HEARTBEAT_SECONDS = 15.0
|
||||
|
||||
# Cap on simultaneous bench workers. A bench is pandas-heavy (5-10 min wall) so
|
||||
# unbounded concurrency would DoS the server with two or three clicks. The
|
||||
# semaphore is created lazily on the first request so we bind to the running
|
||||
# event loop, not the import-time one.
|
||||
MAX_CONCURRENT_BENCHES = 2
|
||||
_BENCH_SEMAPHORE: asyncio.Semaphore | None = None
|
||||
_BENCH_SEMAPHORE_LOCK = threading.Lock()
|
||||
|
||||
|
||||
def _get_bench_semaphore() -> asyncio.Semaphore:
|
||||
"""Return the process-wide bench semaphore, building it on first call."""
|
||||
global _BENCH_SEMAPHORE
|
||||
with _BENCH_SEMAPHORE_LOCK:
|
||||
if _BENCH_SEMAPHORE is None:
|
||||
_BENCH_SEMAPHORE = asyncio.Semaphore(MAX_CONCURRENT_BENCHES)
|
||||
return _BENCH_SEMAPHORE
|
||||
|
||||
|
||||
# Tighter alpha_id pattern: ``<zoo>_<short>``. Zoo prefix is short (a-z + a-z0-9),
|
||||
# short id is 1-64 of [a-z0-9_]. Caps avoid pathological lookups.
|
||||
_ALPHA_ID_RE = re.compile(r"^[a-z][a-z0-9]+_[a-z0-9_]{1,64}$")
|
||||
_JOB_ID_RE = re.compile(r"^[A-Za-z0-9_-]{1,64}$")
|
||||
|
||||
# Filter enums — keep in sync with src.factors.registry.Theme / Universe.
|
||||
_VALID_ZOOS = {"alpha101", "gtja191", "qlib158", "academic"}
|
||||
_VALID_THEMES = {
|
||||
"momentum", "reversal", "volume", "volatility", "quality", "value",
|
||||
"liquidity", "microstructure", "sentiment", "growth", "leverage",
|
||||
}
|
||||
_VALID_UNIVERSES = {"equity_us", "equity_cn", "equity_hk", "crypto", "futures"}
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now(timezone.utc).isoformat(timespec="seconds")
|
||||
|
||||
|
||||
def _safe_error(exc: BaseException) -> str:
|
||||
"""Sanitised user-facing error string for unexpected exceptions.
|
||||
|
||||
Always returns a fixed phrase — never echoes the exception message or
|
||||
type, both of which can include filesystem paths, credentials, or stack
|
||||
frame snippets. Callers should ``logger.exception`` BEFORE invoking this.
|
||||
"""
|
||||
return "internal error; see server logs"
|
||||
|
||||
|
||||
def _prune_old_jobs() -> None:
|
||||
"""Drop completed/errored jobs older than ``_JOB_TTL_SECONDS``."""
|
||||
cutoff = time.time() - _JOB_TTL_SECONDS
|
||||
with _JOBS_LOCK:
|
||||
stale = [
|
||||
jid for jid, job in ALPHA_BENCH_JOBS.items()
|
||||
if job.get("status") in ("done", "error")
|
||||
and job.get("_finished_at", 0) < cutoff
|
||||
]
|
||||
for jid in stale:
|
||||
ALPHA_BENCH_JOBS.pop(jid, None)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Request/response schemas
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
class BenchRequest(BaseModel):
|
||||
"""POST /alpha/bench body."""
|
||||
|
||||
zoo: str = Field(..., min_length=1, max_length=64)
|
||||
universe: str = Field(..., min_length=1, max_length=64)
|
||||
period: str = Field(..., min_length=4, max_length=32)
|
||||
top: int = Field(20, ge=1, le=500)
|
||||
|
||||
@field_validator("zoo")
|
||||
@classmethod
|
||||
def _zoo_known(cls, v: str) -> str:
|
||||
if v not in _VALID_ZOOS:
|
||||
raise ValueError(
|
||||
f"unknown zoo {v!r}; expected one of {sorted(_VALID_ZOOS)}"
|
||||
)
|
||||
return v
|
||||
|
||||
@field_validator("universe")
|
||||
@classmethod
|
||||
def _universe_known(cls, v: str) -> str:
|
||||
allowed = {"csi300", "sp500", "btc-usdt"}
|
||||
if v not in allowed:
|
||||
raise ValueError(
|
||||
f"unknown universe {v!r}; expected one of {sorted(allowed)}"
|
||||
)
|
||||
return v
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Bench worker (runs in a thread; LLM-free, pandas-heavy)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
def _make_progress_cb(job_id: str) -> Callable[[int, int, str], None]:
|
||||
"""Return an on_progress closure that updates the job entry in-place."""
|
||||
|
||||
def _cb(n_done: int, n_total: int, alpha_id: str) -> None:
|
||||
with _JOBS_LOCK:
|
||||
job = ALPHA_BENCH_JOBS.get(job_id)
|
||||
if job is None:
|
||||
return
|
||||
job["progress"] = {
|
||||
"n_done": int(n_done),
|
||||
"n_total": int(n_total),
|
||||
"current_alpha_id": alpha_id,
|
||||
}
|
||||
if job["status"] == "queued":
|
||||
job["status"] = "running"
|
||||
|
||||
return _cb
|
||||
|
||||
|
||||
def _run_bench_blocking(job_id: str, zoo: str, universe: str, period: str, top: int) -> None:
|
||||
"""Synchronous bench worker (called via ``asyncio.to_thread``)."""
|
||||
from src.factors.bench_runner import run_bench # local import: heavy deps
|
||||
|
||||
with _JOBS_LOCK:
|
||||
job = ALPHA_BENCH_JOBS.get(job_id)
|
||||
if job is not None:
|
||||
job["status"] = "running"
|
||||
|
||||
try:
|
||||
result = run_bench(
|
||||
zoo=zoo,
|
||||
universe=universe,
|
||||
period=period,
|
||||
top=top,
|
||||
on_progress=_make_progress_cb(job_id),
|
||||
)
|
||||
except Exception as exc: # noqa: BLE001 — worker must never crash the loop
|
||||
logger.exception("alpha bench worker crashed (job=%s)", job_id)
|
||||
with _JOBS_LOCK:
|
||||
job = ALPHA_BENCH_JOBS.get(job_id)
|
||||
if job is not None:
|
||||
job["status"] = "error"
|
||||
job["error"] = _safe_error(exc)
|
||||
job["_finished_at"] = time.time()
|
||||
return
|
||||
|
||||
with _JOBS_LOCK:
|
||||
job = ALPHA_BENCH_JOBS.get(job_id)
|
||||
if job is None:
|
||||
return
|
||||
if result.get("status") != "ok":
|
||||
job["status"] = "error"
|
||||
# bench_runner's own error string is curated (universe load failed,
|
||||
# forward returns failed, etc.) — safe to surface.
|
||||
job["error"] = result.get("error", "unknown")
|
||||
else:
|
||||
# Strip the bulky per-alpha lists — the API contract returns
|
||||
# summary-only on the result event. We keep ``n_skipped`` (the
|
||||
# count) which ``_result_for_wire`` reshapes into ``skipped``.
|
||||
slim = {
|
||||
k: v for k, v in result.items() if k not in ("rows", "skipped")
|
||||
}
|
||||
job["status"] = "done"
|
||||
job["result"] = slim
|
||||
job["_finished_at"] = time.time()
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Registration
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
AuthDep = Callable[..., Awaitable[Any] | Any]
|
||||
|
||||
|
||||
def register_alpha_routes(
|
||||
app: FastAPI,
|
||||
require_auth: AuthDep | None = None,
|
||||
require_event_stream_auth: AuthDep | None = None,
|
||||
) -> None:
|
||||
"""Mount the alpha routes onto ``app``.
|
||||
|
||||
Args:
|
||||
app: The host FastAPI app.
|
||||
require_auth: Header-auth dependency for JSON endpoints.
|
||||
require_event_stream_auth: Query-param-auth dependency for SSE endpoints.
|
||||
|
||||
For backwards compatibility, when the dependency callables are not passed
|
||||
explicitly we resolve them from the host ``api_server`` module via
|
||||
``sys.modules``. Prefer the explicit form in new call sites.
|
||||
"""
|
||||
if require_auth is None or require_event_stream_auth is None:
|
||||
import sys as _sys
|
||||
|
||||
host = _sys.modules.get("api_server") or _sys.modules.get("agent.api_server")
|
||||
if host is None: # pragma: no cover — only triggers on weird import setups
|
||||
raise RuntimeError(
|
||||
"register_alpha_routes: api_server module not in sys.modules; "
|
||||
"pass require_auth/require_event_stream_auth explicitly"
|
||||
)
|
||||
if require_auth is None:
|
||||
require_auth = host.require_auth
|
||||
if require_event_stream_auth is None:
|
||||
require_event_stream_auth = host.require_event_stream_auth
|
||||
|
||||
# -----------------------------------------------------------------------
|
||||
# GET /alpha/list
|
||||
# -----------------------------------------------------------------------
|
||||
|
||||
@app.get("/alpha/list", dependencies=[Depends(require_auth)])
|
||||
async def list_alphas(
|
||||
zoo: str | None = Query(None, max_length=64),
|
||||
theme: str | None = Query(None, max_length=64),
|
||||
universe: str | None = Query(None, max_length=64),
|
||||
limit: int = Query(100, ge=1, le=1000),
|
||||
) -> dict[str, Any]:
|
||||
"""List alphas, optionally filtered by zoo / theme / universe."""
|
||||
if zoo is not None and zoo not in _VALID_ZOOS:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=f"unknown zoo {zoo!r}; expected one of {sorted(_VALID_ZOOS)}",
|
||||
)
|
||||
if theme is not None and theme not in _VALID_THEMES:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=f"unknown theme {theme!r}; expected one of {sorted(_VALID_THEMES)}",
|
||||
)
|
||||
if universe is not None and universe not in _VALID_UNIVERSES:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=f"unknown universe {universe!r}; expected one of {sorted(_VALID_UNIVERSES)}",
|
||||
)
|
||||
|
||||
from src.factors.registry import get_default_registry
|
||||
|
||||
registry = get_default_registry()
|
||||
try:
|
||||
ids = registry.list(zoo=zoo, theme=theme, universe=universe)
|
||||
except Exception as exc: # noqa: BLE001
|
||||
logger.exception("registry.list failed")
|
||||
raise HTTPException(status_code=500, detail=_safe_error(exc))
|
||||
|
||||
total = len(ids)
|
||||
sliced = ids[:limit]
|
||||
alphas: list[dict[str, Any]] = []
|
||||
for aid in sliced:
|
||||
try:
|
||||
a = registry.get(aid)
|
||||
except KeyError:
|
||||
continue
|
||||
meta = a.meta or {}
|
||||
alphas.append(
|
||||
{
|
||||
"id": a.id,
|
||||
"zoo": a.zoo,
|
||||
"theme": meta.get("theme", []),
|
||||
"universe": meta.get("universe", []),
|
||||
"nickname": meta.get("nickname"),
|
||||
"decay_horizon": meta.get("decay_horizon"),
|
||||
"min_warmup_bars": meta.get("min_warmup_bars"),
|
||||
"requires_sector": bool(meta.get("requires_sector", False)),
|
||||
}
|
||||
)
|
||||
return {
|
||||
"status": "ok",
|
||||
"alphas": alphas,
|
||||
"total": total,
|
||||
"returned": len(alphas),
|
||||
"truncated": total > len(alphas),
|
||||
}
|
||||
|
||||
# -----------------------------------------------------------------------
|
||||
# GET /alpha/{alpha_id}
|
||||
# -----------------------------------------------------------------------
|
||||
|
||||
@app.get("/alpha/{alpha_id}", dependencies=[Depends(require_auth)])
|
||||
async def get_alpha(alpha_id: str) -> dict[str, Any]:
|
||||
"""Return alpha metadata + the source code of its zoo .py file."""
|
||||
if not _ALPHA_ID_RE.fullmatch(alpha_id or ""):
|
||||
raise HTTPException(status_code=400, detail="invalid alpha_id")
|
||||
|
||||
from src.factors.registry import RegistryError, get_default_registry
|
||||
|
||||
registry = get_default_registry()
|
||||
try:
|
||||
alpha = registry.get(alpha_id)
|
||||
except KeyError:
|
||||
raise HTTPException(
|
||||
status_code=404,
|
||||
detail={"status": "error", "error": "alpha_id not found"},
|
||||
)
|
||||
|
||||
try:
|
||||
source_code = registry.get_source(alpha_id)
|
||||
except RegistryError as exc:
|
||||
# Source-read failure is a degraded but recoverable case — log and
|
||||
# surface a short placeholder. The reason here is a typed registry
|
||||
# error (size cap or OS error from a known path), safe to expose.
|
||||
logger.warning("failed to read source for %s: %s", alpha_id, exc)
|
||||
source_code = f"# <source unavailable: {exc}>"
|
||||
|
||||
return {
|
||||
"status": "ok",
|
||||
"alpha": {
|
||||
"id": alpha.id,
|
||||
"zoo": alpha.zoo,
|
||||
"module_path": alpha.module_path,
|
||||
"meta": alpha.meta,
|
||||
},
|
||||
"source_code": source_code,
|
||||
}
|
||||
|
||||
# -----------------------------------------------------------------------
|
||||
# POST /alpha/bench
|
||||
# -----------------------------------------------------------------------
|
||||
|
||||
@app.post(
|
||||
"/alpha/bench",
|
||||
status_code=202,
|
||||
dependencies=[Depends(require_auth)],
|
||||
)
|
||||
async def kick_off_bench(payload: BenchRequest) -> dict[str, Any]:
|
||||
"""Queue a background bench job and return a job_id."""
|
||||
# Cheap period parse pre-check so we 400 here instead of letting the
|
||||
# worker fail asynchronously.
|
||||
from src.tools.alpha_bench_tool import _parse_period
|
||||
|
||||
try:
|
||||
_parse_period(payload.period)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail=f"invalid period: {exc}")
|
||||
|
||||
# Concurrency cap. We peek at the semaphore counter rather than
|
||||
# ``acquire(block=False)`` so the actual acquire happens inside the
|
||||
# worker (after the 202 is returned). _value is a CPython
|
||||
# implementation detail but it's been stable since 3.0 and asyncio's
|
||||
# own ``locked()`` uses it.
|
||||
sem = _get_bench_semaphore()
|
||||
# ``locked()`` returns True iff the counter is 0; defensive check.
|
||||
if sem.locked() or getattr(sem, "_value", MAX_CONCURRENT_BENCHES) <= 0:
|
||||
raise HTTPException(
|
||||
status_code=429,
|
||||
detail="too many running benches; wait for one to finish",
|
||||
)
|
||||
|
||||
_prune_old_jobs()
|
||||
|
||||
job_id = uuid.uuid4().hex
|
||||
with _JOBS_LOCK:
|
||||
ALPHA_BENCH_JOBS[job_id] = {
|
||||
"job_id": job_id,
|
||||
"status": "queued",
|
||||
"zoo": payload.zoo,
|
||||
"universe": payload.universe,
|
||||
"period": payload.period,
|
||||
"top": payload.top,
|
||||
"created_at": _now_iso(),
|
||||
"progress": {"n_done": 0, "n_total": 0, "current_alpha_id": None},
|
||||
"result": None,
|
||||
"error": None,
|
||||
}
|
||||
|
||||
async def _runner() -> None:
|
||||
async with sem:
|
||||
try:
|
||||
await asyncio.to_thread(
|
||||
_run_bench_blocking,
|
||||
job_id,
|
||||
payload.zoo,
|
||||
payload.universe,
|
||||
payload.period,
|
||||
payload.top,
|
||||
)
|
||||
except Exception: # noqa: BLE001 — never escape the loop
|
||||
logger.exception("bench runner outer task crashed (job=%s)", job_id)
|
||||
with _JOBS_LOCK:
|
||||
job = ALPHA_BENCH_JOBS.get(job_id)
|
||||
if job is not None and job["status"] not in ("done", "error"):
|
||||
job["status"] = "error"
|
||||
job["error"] = "internal error; see server logs"
|
||||
job["_finished_at"] = time.time()
|
||||
|
||||
task = asyncio.create_task(_runner())
|
||||
_RUNNING_TASKS.add(task)
|
||||
task.add_done_callback(_RUNNING_TASKS.discard)
|
||||
return {"status": "ok", "job_id": job_id}
|
||||
|
||||
# -----------------------------------------------------------------------
|
||||
# GET /alpha/bench/{job_id}/stream
|
||||
# -----------------------------------------------------------------------
|
||||
|
||||
@app.get(
|
||||
"/alpha/bench/{job_id}/stream",
|
||||
dependencies=[Depends(require_event_stream_auth)],
|
||||
)
|
||||
async def stream_bench(job_id: str, request: Request) -> StreamingResponse:
|
||||
"""SSE: progress / result / done / error until the job terminates."""
|
||||
if not _JOB_ID_RE.fullmatch(job_id or ""):
|
||||
raise HTTPException(status_code=400, detail="invalid job_id")
|
||||
|
||||
with _JOBS_LOCK:
|
||||
if job_id not in ALPHA_BENCH_JOBS:
|
||||
raise HTTPException(status_code=404, detail=f"job {job_id} not found")
|
||||
|
||||
async def event_stream():
|
||||
last_n_done = -1
|
||||
last_emit = time.monotonic()
|
||||
while True:
|
||||
if await request.is_disconnected():
|
||||
return
|
||||
|
||||
with _JOBS_LOCK:
|
||||
job = ALPHA_BENCH_JOBS.get(job_id)
|
||||
if job is None:
|
||||
yield _sse("error", {"message": "job vanished"})
|
||||
yield _sse("done", {"job_id": job_id})
|
||||
return
|
||||
status = job["status"]
|
||||
progress = dict(job.get("progress") or {})
|
||||
result = job.get("result")
|
||||
error = job.get("error")
|
||||
|
||||
# Emit progress whenever n_done advances.
|
||||
n_done = int(progress.get("n_done") or 0)
|
||||
if n_done != last_n_done:
|
||||
yield _sse("progress", progress)
|
||||
last_n_done = n_done
|
||||
last_emit = time.monotonic()
|
||||
|
||||
if status == "done":
|
||||
if result is not None:
|
||||
yield _sse("result", _result_for_wire(result))
|
||||
yield _sse(
|
||||
"done",
|
||||
{
|
||||
"job_id": job_id,
|
||||
"wall_seconds": (result or {}).get("wall_seconds"),
|
||||
},
|
||||
)
|
||||
return
|
||||
if status == "error":
|
||||
yield _sse("error", {"message": error or "unknown error"})
|
||||
yield _sse("done", {"job_id": job_id})
|
||||
return
|
||||
|
||||
# Heartbeat comment frame every ~15s — clients ignore comment
|
||||
# frames; proxies see traffic and don't kill the idle connection.
|
||||
if time.monotonic() - last_emit >= _SSE_HEARTBEAT_SECONDS:
|
||||
yield ": ping\n\n"
|
||||
last_emit = time.monotonic()
|
||||
|
||||
await asyncio.sleep(_POLL_INTERVAL_SECONDS)
|
||||
|
||||
return StreamingResponse(
|
||||
event_stream(),
|
||||
media_type="text/event-stream",
|
||||
headers={
|
||||
"Cache-Control": "no-cache",
|
||||
"Connection": "keep-alive",
|
||||
"X-Accel-Buffering": "no",
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# SSE helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
def _sse(event: str, data: dict[str, Any]) -> str:
|
||||
"""Format a single SSE frame."""
|
||||
payload = json.dumps(data, ensure_ascii=False, default=str)
|
||||
return f"event: {event}\ndata: {payload}\n\n"
|
||||
|
||||
|
||||
def _result_for_wire(result: dict[str, Any]) -> dict[str, Any]:
|
||||
"""Project the bench-runner result onto the API contract's `result` event.
|
||||
|
||||
Keeps: alive / reversed / dead / skipped / n_alphas_tested / top5_by_ir /
|
||||
dead_examples / by_theme / meta. The frontend renders skipped count and
|
||||
surfaces universe meta (e.g. survivorship_bias) so users see degraded
|
||||
runs clearly.
|
||||
|
||||
Drops anything internal (wall_seconds is reported on the `done` event;
|
||||
rows / per-alpha skipped[] are stripped server-side to keep payloads small).
|
||||
"""
|
||||
wire: dict[str, Any] = {}
|
||||
keep = (
|
||||
"alive",
|
||||
"reversed",
|
||||
"dead",
|
||||
"top5_by_ir",
|
||||
"dead_examples",
|
||||
"by_theme",
|
||||
"n_alphas_tested",
|
||||
"meta",
|
||||
)
|
||||
for k in keep:
|
||||
if k in result:
|
||||
wire[k] = result[k]
|
||||
# bench_runner reports the skip count as ``n_skipped``; the wire contract
|
||||
# exposes it as ``skipped``. Surface both keys to stay backward-compatible
|
||||
# with any client that started reading ``n_skipped`` early.
|
||||
if "n_skipped" in result:
|
||||
wire["skipped"] = result["n_skipped"]
|
||||
wire["n_skipped"] = result["n_skipped"]
|
||||
return wire
|
||||
@@ -0,0 +1,17 @@
|
||||
"""Agent configuration helpers for MCP client integration."""
|
||||
|
||||
from src.config.loader import load_agent_config, load_runtime_agent_config, merge_agent_config_overrides, sanitize_session_overrides
|
||||
from src.config.paths import get_config_path, get_data_dir, get_runtime_root
|
||||
from src.config.schema import AgentConfig, MCPServerConfig
|
||||
|
||||
__all__ = [
|
||||
"AgentConfig",
|
||||
"MCPServerConfig",
|
||||
"get_config_path",
|
||||
"get_data_dir",
|
||||
"get_runtime_root",
|
||||
"load_agent_config",
|
||||
"load_runtime_agent_config",
|
||||
"merge_agent_config_overrides",
|
||||
"sanitize_session_overrides",
|
||||
]
|
||||
@@ -0,0 +1,190 @@
|
||||
"""Structured agent config loading utilities."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Any, Mapping
|
||||
|
||||
from pydantic import ValidationError
|
||||
|
||||
from src.config.paths import get_config_path
|
||||
from src.config.schema import AgentConfig, AgentConfigOverride
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
try:
|
||||
import yaml
|
||||
except ImportError:
|
||||
yaml = None # type: ignore
|
||||
|
||||
|
||||
def load_agent_config(config_path: Path | None = None) -> AgentConfig:
|
||||
"""Load structured agent config from disk with safe fallback.
|
||||
|
||||
Args:
|
||||
config_path: Optional explicit config path. When omitted, the default
|
||||
config discovery path is used.
|
||||
|
||||
Returns:
|
||||
The validated agent config. Invalid or unreadable config files fall
|
||||
back to ``AgentConfig()``.
|
||||
"""
|
||||
path = get_config_path(config_path)
|
||||
|
||||
if not path.exists():
|
||||
return AgentConfig()
|
||||
|
||||
try:
|
||||
raw = _read_config_file(path)
|
||||
return AgentConfig.model_validate(raw)
|
||||
except (OSError, ValueError, ValidationError) as exc:
|
||||
logger.warning(
|
||||
"Failed to load agent config from %s: %s",
|
||||
path,
|
||||
type(exc).__name__,
|
||||
)
|
||||
logger.debug("Agent config load error details: %s", exc)
|
||||
return AgentConfig()
|
||||
|
||||
|
||||
def merge_agent_config_overrides(
|
||||
config: AgentConfig,
|
||||
overrides: Mapping[str, Any] | None,
|
||||
) -> AgentConfig:
|
||||
"""Merge runtime overrides on top of a base config.
|
||||
|
||||
Overrides are validated against a partial schema first so both snake_case
|
||||
and camelCase keys are accepted while only explicitly provided fields
|
||||
override the base config.
|
||||
|
||||
Args:
|
||||
config: Base agent config loaded from disk or defaults.
|
||||
overrides: Runtime overrides, typically from session-level config.
|
||||
|
||||
Returns:
|
||||
A new validated config containing the merged result.
|
||||
"""
|
||||
if not overrides:
|
||||
return config
|
||||
|
||||
try:
|
||||
override_model = AgentConfigOverride.model_validate(dict(overrides))
|
||||
except ValidationError as exc:
|
||||
logger.warning(
|
||||
"Ignoring invalid agent config overrides (%s): %s — using base config",
|
||||
type(exc).__name__,
|
||||
[str(e["loc"]) for e in exc.errors()],
|
||||
)
|
||||
return config
|
||||
|
||||
merged = _merge_dicts(
|
||||
config.model_dump(mode="json"),
|
||||
override_model.model_dump(mode="json", exclude_unset=True),
|
||||
)
|
||||
return AgentConfig.model_validate(merged)
|
||||
|
||||
|
||||
# Keys in session overrides that carry subprocess definitions and therefore
|
||||
# require operator-level trust rather than API-caller trust.
|
||||
_SESSION_RESTRICTED_KEYS: frozenset[str] = frozenset({"mcpServers", "mcp_servers"})
|
||||
|
||||
|
||||
def sanitize_session_overrides(overrides: Mapping[str, Any]) -> dict[str, Any]:
|
||||
"""Strip operator-only keys from API-caller-supplied session overrides.
|
||||
|
||||
``mcpServers`` / ``mcp_servers`` define subprocess ``command``/``args``/``env``
|
||||
and therefore grant execution-level capabilities. They must originate from
|
||||
the operator-controlled config file on disk, not from unauthenticated or
|
||||
semi-trusted API callers. Operators who deliberately want to allow session-
|
||||
level MCP injection can set ``ALLOW_SESSION_MCP_SERVERS=1``.
|
||||
|
||||
Args:
|
||||
overrides: Raw session config dict received from the API caller.
|
||||
|
||||
Returns:
|
||||
A new dict with restricted keys removed (or the original mapping
|
||||
converted to dict if the env opt-in is active).
|
||||
"""
|
||||
if os.environ.get("ALLOW_SESSION_MCP_SERVERS", "").strip().lower() in {"1", "true", "yes"}:
|
||||
return dict(overrides)
|
||||
|
||||
restricted_present = _SESSION_RESTRICTED_KEYS & overrides.keys()
|
||||
if restricted_present:
|
||||
logger.warning(
|
||||
"Stripped %s from session config overrides: MCP server definitions "
|
||||
"require operator-level trust (disk config). "
|
||||
"Set ALLOW_SESSION_MCP_SERVERS=1 to allow session-level injection.",
|
||||
sorted(restricted_present),
|
||||
)
|
||||
return {k: v for k, v in overrides.items() if k not in _SESSION_RESTRICTED_KEYS}
|
||||
|
||||
|
||||
def load_runtime_agent_config(
|
||||
config_path: Path | None = None,
|
||||
overrides: Mapping[str, Any] | None = None,
|
||||
) -> AgentConfig:
|
||||
"""Load disk config and apply runtime overrides.
|
||||
|
||||
Args:
|
||||
config_path: Optional explicit config file path.
|
||||
overrides: Runtime override mapping applied on top of file-based config.
|
||||
|
||||
Returns:
|
||||
The merged runtime config.
|
||||
"""
|
||||
config = load_agent_config(config_path)
|
||||
return merge_agent_config_overrides(config, overrides)
|
||||
|
||||
|
||||
def _read_config_file(path: Path) -> dict[str, Any]:
|
||||
"""Read a supported config file format into a dictionary.
|
||||
|
||||
Args:
|
||||
path: Config file path to decode.
|
||||
|
||||
Returns:
|
||||
The decoded config object as a dictionary.
|
||||
|
||||
Raises:
|
||||
ValueError: If the file format is unsupported, YAML support is
|
||||
unavailable, or the decoded payload is not an object.
|
||||
"""
|
||||
suffix = path.suffix.lower()
|
||||
text = path.read_text(encoding="utf-8")
|
||||
|
||||
if suffix == ".json":
|
||||
data = json.loads(text)
|
||||
elif suffix in {".yaml", ".yml"}:
|
||||
if yaml is None:
|
||||
raise ValueError("YAML config is not available because PyYAML is missing")
|
||||
data = yaml.safe_load(text) or {}
|
||||
else:
|
||||
raise ValueError(f"Unsupported config file format: {suffix or '<none>'}")
|
||||
|
||||
if not isinstance(data, dict):
|
||||
raise ValueError("Agent config must decode to a JSON/YAML object")
|
||||
return data
|
||||
|
||||
|
||||
def _merge_dicts(base: dict[str, Any], override: dict[str, Any]) -> dict[str, Any]:
|
||||
"""Recursively merge two plain dictionaries.
|
||||
|
||||
Args:
|
||||
base: Base dictionary.
|
||||
override: Override dictionary applied on top of ``base``.
|
||||
|
||||
Returns:
|
||||
A merged dictionary where nested mappings are merged recursively and
|
||||
scalar values from ``override`` replace those in ``base``.
|
||||
"""
|
||||
merged = dict(base)
|
||||
for key, value in override.items():
|
||||
current = merged.get(key)
|
||||
if isinstance(current, dict) and isinstance(value, dict):
|
||||
merged[key] = _merge_dicts(current, value)
|
||||
else:
|
||||
merged[key] = value
|
||||
return merged
|
||||
@@ -0,0 +1,71 @@
|
||||
"""Path helpers for agent-level structured config."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
_DEFAULT_FILENAMES = ("agent.json", "agent.yaml", "agent.yml")
|
||||
|
||||
|
||||
def get_runtime_root(config_path: Path | None = None) -> Path:
|
||||
"""Return the runtime root directory for user-level agent state.
|
||||
|
||||
Args:
|
||||
config_path: Optional explicit config file path. When provided, the
|
||||
runtime root is derived from that file's parent directory.
|
||||
|
||||
Returns:
|
||||
The directory containing the explicit structured config file when one
|
||||
is provided, otherwise the default ``~/.vibe-trading`` runtime root.
|
||||
"""
|
||||
if config_path is not None:
|
||||
return config_path.expanduser().parent
|
||||
return Path.home() / ".vibe-trading"
|
||||
|
||||
|
||||
def get_config_candidates(config_path: Path | None = None) -> list[Path]:
|
||||
"""Return supported config path candidates in lookup order.
|
||||
|
||||
Returns:
|
||||
Candidate config paths ordered by lookup priority. When an explicit
|
||||
config path is provided, only that path is returned.
|
||||
"""
|
||||
if config_path is not None:
|
||||
return [config_path.expanduser()]
|
||||
root = get_runtime_root()
|
||||
return [root / filename for filename in _DEFAULT_FILENAMES]
|
||||
|
||||
|
||||
def get_config_path(config_path: Path | None = None) -> Path:
|
||||
"""Return the active config file path.
|
||||
|
||||
Prefers the first existing candidate. If an explicit path is provided,
|
||||
returns that path directly. If no candidate exists yet, returns the
|
||||
recommended default JSON path.
|
||||
|
||||
Args:
|
||||
config_path: Optional explicit config file path.
|
||||
|
||||
Returns:
|
||||
The selected config file path for the current runtime context.
|
||||
"""
|
||||
candidates = get_config_candidates(config_path)
|
||||
for candidate in candidates:
|
||||
if candidate.exists():
|
||||
return candidate
|
||||
return candidates[0]
|
||||
|
||||
|
||||
def get_data_dir(config_path: Path | None = None) -> Path:
|
||||
"""Return and create the runtime data directory derived from config path.
|
||||
|
||||
Args:
|
||||
config_path: Optional explicit config file path.
|
||||
|
||||
Returns:
|
||||
The directory containing the active config file. The directory is
|
||||
created when it does not already exist.
|
||||
"""
|
||||
data_dir = get_config_path(config_path).parent
|
||||
data_dir.mkdir(parents=True, exist_ok=True)
|
||||
return data_dir
|
||||
@@ -0,0 +1,103 @@
|
||||
"""Structured agent config schema for MCP client integration."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Literal
|
||||
|
||||
from pydantic import BaseModel, ConfigDict, Field, model_validator
|
||||
|
||||
|
||||
def _to_camel(name: str) -> str:
|
||||
"""Convert snake_case names to camelCase aliases.
|
||||
|
||||
Args:
|
||||
name: Field name in snake_case form.
|
||||
|
||||
Returns:
|
||||
The camelCase alias used for external config compatibility.
|
||||
"""
|
||||
parts = name.split("_")
|
||||
return parts[0] + "".join(part.capitalize() for part in parts[1:])
|
||||
|
||||
|
||||
class ConfigBase(BaseModel):
|
||||
"""Base config model accepting both snake_case and camelCase keys."""
|
||||
|
||||
model_config = ConfigDict(alias_generator=_to_camel, populate_by_name=True, extra="forbid")
|
||||
|
||||
|
||||
class MCPServerConfig(ConfigBase):
|
||||
"""Single external MCP server definition."""
|
||||
|
||||
type: Literal["stdio", "sse", "streamableHttp"] | None = None
|
||||
command: str = ""
|
||||
args: list[str] = Field(default_factory=list)
|
||||
env: dict[str, str] = Field(default_factory=dict)
|
||||
url: str = ""
|
||||
headers: dict[str, str] = Field(default_factory=dict)
|
||||
tool_timeout: float = Field(default=30.0, ge=0.1)
|
||||
enabled_tools: list[str] = Field(default_factory=lambda: ["*"])
|
||||
|
||||
@model_validator(mode="after")
|
||||
def validate_v1_stdio_only(self) -> "MCPServerConfig":
|
||||
"""Reject non-stdio transports for the first release.
|
||||
|
||||
Returns:
|
||||
The validated MCP server config instance.
|
||||
|
||||
Raises:
|
||||
ValueError: If the config implies a non-stdio transport, uses
|
||||
HTTP-only fields, or omits the command required for stdio.
|
||||
"""
|
||||
transport = self.type
|
||||
if transport is None:
|
||||
if self.command:
|
||||
transport = "stdio"
|
||||
elif self.url:
|
||||
transport = "sse" if self.url.rstrip("/").endswith("/sse") else "streamableHttp"
|
||||
|
||||
if transport and transport != "stdio":
|
||||
raise ValueError("Only stdio MCP servers are supported in v1")
|
||||
if self.url or self.headers:
|
||||
raise ValueError("HTTP MCP transports are not supported in v1")
|
||||
if not self.command.strip():
|
||||
raise ValueError("stdio MCP servers require a command")
|
||||
return self
|
||||
|
||||
|
||||
class MCPServerConfigOverride(ConfigBase):
|
||||
"""Partial MCP server override used for runtime config layering."""
|
||||
|
||||
type: Literal["stdio", "sse", "streamableHttp"] | None = None
|
||||
command: str | None = None
|
||||
args: list[str] | None = None
|
||||
env: dict[str, str] | None = None
|
||||
url: str | None = None
|
||||
headers: dict[str, str] | None = None
|
||||
tool_timeout: float | None = Field(default=None, ge=0.1)
|
||||
enabled_tools: list[str] | None = None
|
||||
|
||||
|
||||
class AgentConfig(ConfigBase):
|
||||
"""Top-level structured agent config."""
|
||||
|
||||
mcp_servers: dict[str, MCPServerConfig] = Field(default_factory=dict)
|
||||
|
||||
|
||||
class AgentConfigOverride(ConfigBase):
|
||||
"""Partial top-level config override used for runtime layering."""
|
||||
|
||||
model_config = ConfigDict(
|
||||
alias_generator=_to_camel,
|
||||
populate_by_name=True,
|
||||
# Load-bearing: SessionService passes the entire session.config dict
|
||||
# (which carries unrelated keys like include_shell_tools) through
|
||||
# merge_agent_config_overrides. Flipping this back to "forbid" makes
|
||||
# any such payload raise ValidationError and silently drops the whole
|
||||
# override, including any valid mcpServers. Regression test:
|
||||
# tests/test_agent_config.py::
|
||||
# test_runtime_load_preserves_mcp_servers_when_opted_in_with_unknown_keys
|
||||
extra="ignore",
|
||||
)
|
||||
|
||||
mcp_servers: dict[str, MCPServerConfigOverride] = Field(default_factory=dict)
|
||||
@@ -13,7 +13,7 @@ from typing import Any, Dict, Optional
|
||||
from rich.console import Console
|
||||
|
||||
|
||||
console = Console()
|
||||
console = Console(stderr=True)
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -73,6 +73,8 @@ _ARTIFACTS_SPEC = {
|
||||
"metrics": {"schema": "metrics_csv", "path": "artifacts/metrics.csv"},
|
||||
"trades": {"schema": "trade_log", "path": "artifacts/trades.csv"},
|
||||
"positions": {"schema": "positions_csv", "path": "artifacts/positions.csv"},
|
||||
"run_card_json": {"schema": "json", "path": "run_card.json"},
|
||||
"run_card_md": {"schema": "markdown", "path": "run_card.md"},
|
||||
},
|
||||
}
|
||||
|
||||
@@ -109,19 +111,6 @@ def _expand_artifacts_spec(spec: Dict[str, Any] | None) -> Dict[str, Dict[str, A
|
||||
class Runner:
|
||||
"""Execute entry scripts inside a run directory and collect outputs."""
|
||||
|
||||
_PROXY_ENV_KEYS = (
|
||||
"HTTP_PROXY",
|
||||
"HTTPS_PROXY",
|
||||
"ALL_PROXY",
|
||||
"http_proxy",
|
||||
"https_proxy",
|
||||
"all_proxy",
|
||||
"GIT_HTTP_PROXY",
|
||||
"GIT_HTTPS_PROXY",
|
||||
"git_http_proxy",
|
||||
"git_https_proxy",
|
||||
)
|
||||
|
||||
def __init__(self, timeout: int = 300, artifacts_spec: Optional[Dict[str, Any]] = None) -> None:
|
||||
"""Initialize runner.
|
||||
|
||||
@@ -147,6 +136,7 @@ class Runner:
|
||||
try:
|
||||
probe = subprocess.run(
|
||||
[python_cmd, "-c", "import pandas,numpy; print('ok')"],
|
||||
stdin=subprocess.DEVNULL,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
text=True,
|
||||
@@ -201,13 +191,9 @@ class Runner:
|
||||
existing = env.get("PYTHONPATH", "")
|
||||
env["PYTHONPATH"] = str(pythonpath_extra) + (os.pathsep + existing if existing else "")
|
||||
|
||||
runtime_home = run_dir / ".home"
|
||||
runtime_home.mkdir(parents=True, exist_ok=True)
|
||||
env["HOME"] = str(runtime_home)
|
||||
if os.name == "nt":
|
||||
env["USERPROFILE"] = str(runtime_home)
|
||||
|
||||
# Preserve system proxy settings; data sources (OKX/yfinance) need network access
|
||||
# NOTE: do NOT override HOME/USERPROFILE — data libraries (yfinance, akshare)
|
||||
# cache downloads under ~/; overriding HOME causes full re-download every run.
|
||||
|
||||
return env
|
||||
|
||||
@@ -252,6 +238,7 @@ class Runner:
|
||||
process = subprocess.run(
|
||||
cmd,
|
||||
cwd=str(effective_cwd),
|
||||
stdin=subprocess.DEVNULL,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
text=True,
|
||||
|
||||
+3
-107
@@ -1,19 +1,16 @@
|
||||
"""Run state persistence: lightweight, no dependency on legacy agent types."""
|
||||
"""Run state persistence: creates run directories and records status."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
import json
|
||||
import uuid
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
import yaml
|
||||
from typing import Any, Dict
|
||||
|
||||
|
||||
class RunStateStore:
|
||||
"""Run state store: records key files such as req/design/code/logs/review."""
|
||||
"""Run state store: manages run directories and their lifecycle status."""
|
||||
|
||||
def create_run_dir(self, workspace: Path) -> Path:
|
||||
"""Create a unique run directory.
|
||||
@@ -48,59 +45,6 @@ class RunStateStore:
|
||||
self._write_json(run_dir / "req.json", payload)
|
||||
return payload
|
||||
|
||||
def save_planner_output(self, run_dir: Path, planner_output: Dict[str, Any]) -> Dict[str, Any]:
|
||||
"""Save planner output.
|
||||
|
||||
Args:
|
||||
run_dir: Run directory.
|
||||
planner_output: Planner output dict.
|
||||
|
||||
Returns:
|
||||
Saved payload.
|
||||
"""
|
||||
self._write_json(run_dir / "planner_output.json", planner_output)
|
||||
return planner_output
|
||||
|
||||
def save_design(self, run_dir: Path, spec: Dict[str, Any], decision: Dict[str, Any]) -> None:
|
||||
"""Save design spec and judge decision.
|
||||
|
||||
Args:
|
||||
run_dir: Run directory.
|
||||
spec: Strategy design spec.
|
||||
decision: Judge decision result.
|
||||
"""
|
||||
self._write_json(run_dir / "design_spec.json", spec)
|
||||
self._write_json(run_dir / "judge_decision.json", decision)
|
||||
|
||||
def save_rag_spec(
|
||||
self,
|
||||
run_dir: Path,
|
||||
selection: Dict[str, Any],
|
||||
spec: Dict[str, Any],
|
||||
*,
|
||||
candidates: Optional[List[Dict[str, Any]]] = None,
|
||||
) -> None:
|
||||
"""Save RAG results.
|
||||
|
||||
Args:
|
||||
run_dir: Run directory.
|
||||
selection: Selected API metadata.
|
||||
spec: Enriched data API spec.
|
||||
candidates: Candidate API list.
|
||||
"""
|
||||
enriched_spec = copy.deepcopy(spec) if spec else {}
|
||||
enriched_spec["_rag_metadata"] = selection
|
||||
spec_yaml = yaml.safe_dump(enriched_spec, allow_unicode=True, sort_keys=False)
|
||||
(run_dir / "data_api_spec.yaml").write_text(spec_yaml, encoding="utf-8")
|
||||
self._write_json(run_dir / "rag_metadata.json", selection)
|
||||
if candidates:
|
||||
candidate_yaml = yaml.safe_dump(
|
||||
{"generated_at": datetime.now().isoformat(), "candidates": candidates},
|
||||
allow_unicode=True,
|
||||
sort_keys=False,
|
||||
)
|
||||
(run_dir / "rag_candidates.yaml").write_text(candidate_yaml, encoding="utf-8")
|
||||
|
||||
def mark_success(self, run_dir: Path) -> None:
|
||||
"""Mark the run as successful.
|
||||
|
||||
@@ -118,54 +62,6 @@ class RunStateStore:
|
||||
"""
|
||||
self._write_json(run_dir / "state.json", {"status": "failed", "reason": reason})
|
||||
|
||||
# -----------------------------------------------------------------------
|
||||
# Generic persistence: extract and save key artifacts by tool name
|
||||
# -----------------------------------------------------------------------
|
||||
|
||||
_PERSIST_MAP: Dict[str, str] = {
|
||||
"plan": "_persist_plan",
|
||||
"search": "_persist_search",
|
||||
"resolve": "_persist_resolve",
|
||||
"design": "_persist_design",
|
||||
}
|
||||
|
||||
def persist_tool_result(self, tool_name: str, result_data: Dict[str, Any], run_dir: Path) -> None:
|
||||
"""Persist key artifacts by tool name.
|
||||
|
||||
Args:
|
||||
tool_name: Tool name.
|
||||
result_data: Parsed tool result dict.
|
||||
run_dir: Run directory.
|
||||
"""
|
||||
method_name = self._PERSIST_MAP.get(tool_name)
|
||||
if method_name:
|
||||
method = getattr(self, method_name, None)
|
||||
if method:
|
||||
try:
|
||||
method(result_data, run_dir)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _persist_plan(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
if data and "error" not in data:
|
||||
self.save_planner_output(run_dir, data)
|
||||
|
||||
def _persist_search(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
if data.get("selections"):
|
||||
sel = data["selections"][0] if data["selections"] else {}
|
||||
spec = data.get("data_api_spec") or {}
|
||||
self.save_rag_spec(run_dir, sel, spec, candidates=data.get("candidates"))
|
||||
|
||||
def _persist_resolve(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
if data and data.get("status") == "ok":
|
||||
self._write_json(run_dir / "data_config.json", data)
|
||||
|
||||
def _persist_design(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
spec = data.get("spec") or {}
|
||||
decision = data.get("judge_decision") or {}
|
||||
if spec:
|
||||
self.save_design(run_dir, spec, decision)
|
||||
|
||||
@staticmethod
|
||||
def _write_json(path: Path, data: Any) -> None:
|
||||
path.write_text(json.dumps(data, ensure_ascii=False, indent=2), encoding="utf-8")
|
||||
@@ -0,0 +1,48 @@
|
||||
"""Alpha Zoo: 4 zoos (alpha101 / gtja191 / qlib158 / academic) × ~450 alphas.
|
||||
|
||||
See `docs/alpha-zoo/spec.md` for the panel format contract and operator semantics.
|
||||
"""
|
||||
|
||||
from src.factors.base import (
|
||||
Alpha,
|
||||
AlphaCompute,
|
||||
Market,
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
vwap,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"Alpha",
|
||||
"AlphaCompute",
|
||||
"Market",
|
||||
"decay_linear",
|
||||
"delta",
|
||||
"rank",
|
||||
"safe_div",
|
||||
"scale",
|
||||
"signed_power",
|
||||
"ts_argmax",
|
||||
"ts_argmin",
|
||||
"ts_corr",
|
||||
"ts_cov",
|
||||
"ts_max",
|
||||
"ts_mean",
|
||||
"ts_min",
|
||||
"ts_rank",
|
||||
"ts_std",
|
||||
"vwap",
|
||||
]
|
||||
@@ -0,0 +1,273 @@
|
||||
"""Alpha Zoo base operators.
|
||||
|
||||
Operators all act on **wide** ``pd.DataFrame`` where ``index = trading_date``
|
||||
(DatetimeIndex) and ``columns = instrument_code`` (str). The factor compute
|
||||
contract returns a DataFrame of the same shape — raw scores, NaN preserved
|
||||
in warmup / missing data; +/- inf is forbidden (registry rejects it).
|
||||
|
||||
NaN policy: every operator propagates NaN; no silent ``fillna(0)``. A constant
|
||||
window for ``ts_corr`` / ``ts_cov`` returns NaN, not zero.
|
||||
|
||||
Lookahead ban: ``delta(df, d)`` requires ``d >= 1``; the negative-shift
|
||||
``Ref(df, -n)`` form is intentionally absent.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass, field
|
||||
from enum import Enum
|
||||
from typing import Any, Protocol, runtime_checkable
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
|
||||
class Market(str, Enum):
|
||||
"""Market identifier used by ``vwap`` for market-specific formulas."""
|
||||
|
||||
EQUITY_US = "equity_us"
|
||||
EQUITY_CN = "equity_cn"
|
||||
EQUITY_HK = "equity_hk"
|
||||
CRYPTO = "crypto"
|
||||
FUTURES = "futures"
|
||||
|
||||
|
||||
@dataclass(frozen=True, slots=True)
|
||||
class Alpha:
|
||||
"""Lightweight handle for a registered alpha (registry-owned)."""
|
||||
|
||||
id: str
|
||||
zoo: str
|
||||
module_path: str
|
||||
meta: dict[str, Any] = field(default_factory=dict)
|
||||
|
||||
|
||||
@runtime_checkable
|
||||
class AlphaCompute(Protocol):
|
||||
"""Structural protocol every alpha ``.py`` module satisfies."""
|
||||
|
||||
def __call__(self, panel: dict[str, pd.DataFrame]) -> pd.DataFrame: ...
|
||||
|
||||
|
||||
def _as_float(df: pd.DataFrame) -> pd.DataFrame:
|
||||
if df.dtypes.eq(np.float64).all():
|
||||
return df
|
||||
return df.astype(np.float64)
|
||||
|
||||
|
||||
def rank(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Cross-sectional percentile rank per row (axis=1, ties=average, pct=True).
|
||||
|
||||
NaN inputs stay NaN. An all-NaN row returns an all-NaN row.
|
||||
"""
|
||||
return df.rank(axis=1, method="average", pct=True, na_option="keep")
|
||||
|
||||
|
||||
def scale(df: pd.DataFrame, a: float = 1.0) -> pd.DataFrame:
|
||||
"""Per-row L1 normalize so sum of absolute values equals ``a``.
|
||||
|
||||
Rows whose abs-sum is 0 (or all-NaN) become NaN — never silent zero.
|
||||
"""
|
||||
df = _as_float(df)
|
||||
abs_sum = df.abs().sum(axis=1, skipna=True)
|
||||
abs_sum = abs_sum.where(abs_sum > 0) # zero → NaN
|
||||
return df.mul(a).div(abs_sum, axis=0)
|
||||
|
||||
|
||||
def ts_rank(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling rank (last value's rank within the n-window), per column.
|
||||
|
||||
Warmup (first ``n-1`` rows per column) returns NaN. Result is a percentile
|
||||
in [0, 1] so it is compositionally compatible with cross-sectional rank.
|
||||
"""
|
||||
if n < 1:
|
||||
raise ValueError(f"ts_rank window must be >= 1, got {n}")
|
||||
|
||||
def _last_rank(arr: np.ndarray) -> float:
|
||||
if np.isnan(arr).all():
|
||||
return np.nan
|
||||
last = arr[-1]
|
||||
if np.isnan(last):
|
||||
return np.nan
|
||||
valid = arr[~np.isnan(arr)]
|
||||
if valid.size == 0:
|
||||
return np.nan
|
||||
# average rank for ties; pct
|
||||
less = (valid < last).sum()
|
||||
eq = (valid == last).sum()
|
||||
rank_avg = less + 0.5 * (eq + 1)
|
||||
return float(rank_avg / valid.size)
|
||||
|
||||
return df.rolling(window=n, min_periods=n).apply(_last_rank, raw=True)
|
||||
|
||||
|
||||
def ts_corr(x: pd.DataFrame, y: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling Pearson correlation per column, min_periods=n.
|
||||
|
||||
Constant series in the window → NaN (no silent zero). Pairs are inner-joined
|
||||
on columns; columns missing from either side become NaN.
|
||||
"""
|
||||
if n < 2:
|
||||
raise ValueError(f"ts_corr window must be >= 2, got {n}")
|
||||
x = _as_float(x)
|
||||
y = _as_float(y)
|
||||
cols = x.columns.union(y.columns)
|
||||
xa = x.reindex(columns=cols)
|
||||
ya = y.reindex(columns=cols)
|
||||
corr = xa.rolling(window=n, min_periods=n).corr(ya)
|
||||
# corr above can produce +/- inf when one series is constant in some
|
||||
# pandas versions; force to NaN.
|
||||
return corr.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def ts_cov(x: pd.DataFrame, y: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling sample covariance per column, min_periods=n."""
|
||||
if n < 2:
|
||||
raise ValueError(f"ts_cov window must be >= 2, got {n}")
|
||||
x = _as_float(x)
|
||||
y = _as_float(y)
|
||||
cols = x.columns.union(y.columns)
|
||||
xa = x.reindex(columns=cols)
|
||||
ya = y.reindex(columns=cols)
|
||||
cov = xa.rolling(window=n, min_periods=n).cov(ya)
|
||||
return cov.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def ts_mean(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling mean per column, warmup → NaN."""
|
||||
if n < 1:
|
||||
raise ValueError(f"ts_mean window must be >= 1, got {n}")
|
||||
return df.rolling(window=n, min_periods=n).mean()
|
||||
|
||||
|
||||
def ts_std(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling sample std (ddof=1) per column, warmup → NaN."""
|
||||
if n < 2:
|
||||
raise ValueError(f"ts_std window must be >= 2, got {n}")
|
||||
return df.rolling(window=n, min_periods=n).std(ddof=1)
|
||||
|
||||
|
||||
def ts_max(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling max per column, warmup → NaN."""
|
||||
if n < 1:
|
||||
raise ValueError(f"ts_max window must be >= 1, got {n}")
|
||||
return df.rolling(window=n, min_periods=n).max()
|
||||
|
||||
|
||||
def ts_min(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling min per column, warmup → NaN."""
|
||||
if n < 1:
|
||||
raise ValueError(f"ts_min window must be >= 1, got {n}")
|
||||
return df.rolling(window=n, min_periods=n).min()
|
||||
|
||||
|
||||
def _argmax_last(arr: np.ndarray) -> float:
|
||||
if np.isnan(arr).all():
|
||||
return np.nan
|
||||
arr_filled = np.where(np.isnan(arr), -np.inf, arr)
|
||||
return float(np.argmax(arr_filled))
|
||||
|
||||
|
||||
def _argmin_last(arr: np.ndarray) -> float:
|
||||
if np.isnan(arr).all():
|
||||
return np.nan
|
||||
arr_filled = np.where(np.isnan(arr), np.inf, arr)
|
||||
return float(np.argmin(arr_filled))
|
||||
|
||||
|
||||
def ts_argmax(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling argmax (0-based index into the window), warmup → NaN."""
|
||||
if n < 1:
|
||||
raise ValueError(f"ts_argmax window must be >= 1, got {n}")
|
||||
return df.rolling(window=n, min_periods=n).apply(_argmax_last, raw=True)
|
||||
|
||||
|
||||
def ts_argmin(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling argmin (0-based index into the window), warmup → NaN."""
|
||||
if n < 1:
|
||||
raise ValueError(f"ts_argmin window must be >= 1, got {n}")
|
||||
return df.rolling(window=n, min_periods=n).apply(_argmin_last, raw=True)
|
||||
|
||||
|
||||
def delta(df: pd.DataFrame, d: int) -> pd.DataFrame:
|
||||
"""First difference at lag ``d``: ``df - df.shift(d)``.
|
||||
|
||||
Lookahead ban: ``d >= 1`` strictly. Negative lag forbidden.
|
||||
"""
|
||||
if d < 1:
|
||||
raise ValueError(f"delta lag must be >= 1 (lookahead ban), got {d}")
|
||||
return df - df.shift(d)
|
||||
|
||||
|
||||
def decay_linear(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Linear decay-weighted moving average, weights ``n, n-1, ..., 1`` normalized.
|
||||
|
||||
Warmup (first ``n-1`` rows) → NaN.
|
||||
"""
|
||||
if n < 1:
|
||||
raise ValueError(f"decay_linear window must be >= 1, got {n}")
|
||||
weights = np.arange(n, 0, -1, dtype=np.float64)
|
||||
weights /= weights.sum()
|
||||
|
||||
def _apply(arr: np.ndarray) -> float:
|
||||
if np.isnan(arr).any():
|
||||
return np.nan
|
||||
return float(np.dot(arr, weights))
|
||||
|
||||
return df.rolling(window=n, min_periods=n).apply(_apply, raw=True)
|
||||
|
||||
|
||||
def signed_power(df: pd.DataFrame, p: float) -> pd.DataFrame:
|
||||
"""``sign(df) * |df|**p`` — preserves sign; never produces complex output."""
|
||||
arr = df.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
out = np.sign(arr) * np.power(np.abs(arr), p)
|
||||
return pd.DataFrame(out, index=df.index, columns=df.columns)
|
||||
|
||||
|
||||
def safe_div(a: pd.DataFrame, b: pd.DataFrame, eps: float = 1e-12) -> pd.DataFrame:
|
||||
"""Safe division: ``a / (b + eps * sign(b))``.
|
||||
|
||||
Where ``b == 0`` exactly (or NaN), result is NaN — never silently inf or 0.
|
||||
"""
|
||||
a = _as_float(a)
|
||||
b = _as_float(b)
|
||||
sign = np.sign(b.to_numpy(dtype=np.float64, na_value=np.nan))
|
||||
# b == 0 → sign == 0 → denom == 0 → NaN below
|
||||
denom_arr = b.to_numpy(dtype=np.float64, na_value=np.nan) + eps * sign
|
||||
denom = pd.DataFrame(denom_arr, index=b.index, columns=b.columns)
|
||||
result = a.div(denom)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def vwap(panel: dict[str, pd.DataFrame], market: Market | str) -> pd.DataFrame:
|
||||
"""Market-aware VWAP-equivalent reference price.
|
||||
|
||||
- ``equity_cn``: ``(amount * 1000) / (volume * 100 + 1)`` — Tushare's
|
||||
``daily.amount`` is in **千元 (thousand CNY)** and ``daily.vol`` is in
|
||||
**手 (100 shares)**. Probe 2026-05-17 against ``000001.SZ`` shows
|
||||
``amount/(vol*100) ≈ 0.0093`` for a close of 9.27 — confirming the 1000x
|
||||
scale. We multiply ``amount`` by 1000 (CNY) and divide by
|
||||
``volume * 100`` (shares); ``+1`` keeps the denominator positive on
|
||||
suspended bars.
|
||||
- ``equity_us`` / ``equity_hk`` / ``futures``: typical price ``(H + L + C + O) / 4``
|
||||
when ``panel["vwap"]`` is absent.
|
||||
- ``crypto``: prefer ``panel["vwap"]`` if provided, else typical price.
|
||||
|
||||
Any missing required column → NaN propagation; never silent zero.
|
||||
"""
|
||||
if isinstance(market, str):
|
||||
market = Market(market)
|
||||
|
||||
if "vwap" in panel:
|
||||
return panel["vwap"]
|
||||
|
||||
if market is Market.EQUITY_CN:
|
||||
if "amount" not in panel or "volume" not in panel:
|
||||
raise KeyError("vwap(equity_cn) requires panel['amount'] and panel['volume']")
|
||||
return safe_div(panel["amount"] * 1000.0, panel["volume"] * 100.0 + 1.0)
|
||||
|
||||
required = ("open", "high", "low", "close")
|
||||
missing = [k for k in required if k not in panel]
|
||||
if missing:
|
||||
raise KeyError(f"vwap({market.value}) requires panel keys {required}; missing {missing}")
|
||||
return (panel["open"] + panel["high"] + panel["low"] + panel["close"]) / 4.0
|
||||
@@ -0,0 +1,227 @@
|
||||
"""Bench runner: compute IC stats for every alpha in a zoo over one universe.
|
||||
|
||||
Extracted from ``agent/scripts/w4a_run_benches.py`` so the same pipeline can be
|
||||
called by:
|
||||
|
||||
- the CLI bench driver (``w4a_run_benches.py``)
|
||||
- the Web UI background worker (``src/api/alpha_routes.py``)
|
||||
|
||||
The math is unchanged — only the carrier moved. Categorisation thresholds:
|
||||
|
||||
- ``alive`` : ic_mean > 0.02 and ic_positive_ratio >= 0.55 and |t| > 2
|
||||
- ``reversed`` : ic_mean < -0.02 and |t| > 2
|
||||
- ``dead`` : everything else
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import math
|
||||
import time
|
||||
from typing import Any, Callable
|
||||
|
||||
from src.factors.factor_analysis_core import compute_ic_series
|
||||
from src.factors.registry import (
|
||||
Registry,
|
||||
RegistryError,
|
||||
SkipAlpha,
|
||||
get_default_registry,
|
||||
)
|
||||
from src.tools.alpha_bench_tool import _compute_forward_returns, _load_universe_panel
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
ProgressCb = Callable[[int, int, str], None]
|
||||
"""Signature: ``on_progress(n_done, n_total, current_alpha_id)``."""
|
||||
|
||||
|
||||
def t_stat(ic_mean: float, ic_std: float, n: int) -> float:
|
||||
"""Two-sided t-statistic of the IC series."""
|
||||
if not (n > 0 and ic_std > 0 and math.isfinite(ic_std)):
|
||||
return 0.0
|
||||
return ic_mean / (ic_std / math.sqrt(n))
|
||||
|
||||
|
||||
def categorise(row: dict[str, Any]) -> str:
|
||||
"""Bucket a per-alpha row into alive / reversed / dead."""
|
||||
ic_mean = row["ic_mean"]
|
||||
pos = row["ic_positive_ratio"]
|
||||
t = t_stat(ic_mean, row["ic_std"], row["ic_count"])
|
||||
if ic_mean > 0.02 and pos >= 0.55 and abs(t) > 2:
|
||||
return "alive"
|
||||
if ic_mean < -0.02 and abs(t) > 2:
|
||||
return "reversed"
|
||||
return "dead"
|
||||
|
||||
|
||||
def theme_breakdown(rows: list[dict[str, Any]]) -> dict[str, dict[str, int]]:
|
||||
"""Aggregate alive/reversed/dead counts by theme tag."""
|
||||
by_theme: dict[str, dict[str, int]] = {}
|
||||
for row in rows:
|
||||
cat = row["_category"]
|
||||
themes = row.get("theme", []) or ["uncategorised"]
|
||||
for theme in themes:
|
||||
bucket = by_theme.setdefault(
|
||||
theme, {"alive": 0, "reversed": 0, "dead": 0, "count": 0}
|
||||
)
|
||||
bucket[cat] += 1
|
||||
bucket["count"] += 1
|
||||
return by_theme
|
||||
|
||||
|
||||
def run_bench(
|
||||
zoo: str,
|
||||
universe: str,
|
||||
period: str,
|
||||
top: int = 20,
|
||||
on_progress: ProgressCb | None = None,
|
||||
registry: Registry | None = None,
|
||||
) -> dict[str, Any]:
|
||||
"""Run a bench end-to-end and return the API-shaped summary.
|
||||
|
||||
Args:
|
||||
zoo: Zoo id (e.g. ``gtja191``, ``alpha101``, ``qlib158``).
|
||||
universe: Universe key understood by ``_load_universe_panel``
|
||||
(e.g. ``csi300``, ``sp500``, ``btc-usdt``).
|
||||
period: ``YYYY-YYYY`` or ``YYYY-MM-DD/YYYY-MM-DD`` window.
|
||||
top: Number of top-IR alphas to keep in ``top5_by_ir`` and
|
||||
``dead_examples`` (capped at ``top``).
|
||||
on_progress: Optional callback fired after every alpha completes
|
||||
(success or skip). Signature: ``(n_done, n_total, alpha_id)``.
|
||||
registry: Optional pre-built registry (test injection); defaults to a
|
||||
fresh ``Registry()``.
|
||||
|
||||
Returns:
|
||||
Dict with keys: ``status``, ``zoo``, ``universe``, ``period``,
|
||||
``n_alphas_tested``, ``n_skipped``, ``alive``, ``reversed``, ``dead``,
|
||||
``by_theme``, ``top5_by_ir``, ``dead_examples``, ``wall_seconds`` —
|
||||
and on failure: ``status="error"``, ``error``.
|
||||
"""
|
||||
start = time.monotonic()
|
||||
entry: dict[str, Any] = {
|
||||
"status": "pending",
|
||||
"zoo": zoo,
|
||||
"universe": universe,
|
||||
"period": period,
|
||||
}
|
||||
|
||||
reg = registry if registry is not None else get_default_registry()
|
||||
alpha_ids = reg.list(zoo=zoo)
|
||||
if not alpha_ids:
|
||||
entry["status"] = "error"
|
||||
entry["error"] = f"no alphas registered under zoo={zoo!r}"
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
try:
|
||||
panel = _load_universe_panel(universe, period)
|
||||
except (ValueError, NotImplementedError, RuntimeError) as exc:
|
||||
entry["status"] = "error"
|
||||
entry["error"] = f"universe load failed: {exc}"
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
try:
|
||||
return_df = _compute_forward_returns(panel)
|
||||
except Exception as exc: # noqa: BLE001
|
||||
entry["status"] = "error"
|
||||
entry["error"] = f"forward returns failed: {exc}"
|
||||
entry["wall_seconds"] = round(time.monotonic() - start, 2)
|
||||
return entry
|
||||
|
||||
rows: list[dict[str, Any]] = []
|
||||
skipped: list[dict[str, Any]] = []
|
||||
n_total = len(alpha_ids)
|
||||
for idx, aid in enumerate(alpha_ids, start=1):
|
||||
try:
|
||||
factor_df = reg.compute(aid, panel)
|
||||
ic = compute_ic_series(factor_df, return_df)
|
||||
if ic.empty:
|
||||
skipped.append(
|
||||
{"id": aid, "reason": "empty IC series", "kind": "typed"}
|
||||
)
|
||||
else:
|
||||
ic_mean = float(ic.mean())
|
||||
ic_std = float(ic.std())
|
||||
ir = ic_mean / ic_std if ic_std > 0 else 0.0
|
||||
meta = reg.get(aid).meta or {}
|
||||
rows.append(
|
||||
{
|
||||
"id": aid,
|
||||
"ic_mean": round(ic_mean, 6),
|
||||
"ic_std": round(ic_std, 6),
|
||||
"ir": round(ir, 4),
|
||||
"ic_positive_ratio": round(float((ic > 0).mean()), 4),
|
||||
"ic_count": int(len(ic)),
|
||||
"theme": meta.get("theme", []),
|
||||
"formula_latex": meta.get("formula_latex", ""),
|
||||
}
|
||||
)
|
||||
except (SkipAlpha, RegistryError, RuntimeError, KeyError, ValueError) as exc:
|
||||
skipped.append({"id": aid, "reason": str(exc), "kind": "typed"})
|
||||
except Exception as exc: # noqa: BLE001
|
||||
logger.exception("bench: unexpected failure on %s", aid)
|
||||
skipped.append(
|
||||
{"id": aid, "reason": f"unexpected: {exc}", "kind": "unexpected"}
|
||||
)
|
||||
|
||||
if on_progress is not None:
|
||||
try:
|
||||
on_progress(idx, n_total, aid)
|
||||
except Exception: # noqa: BLE001 — never let progress break the loop
|
||||
logger.exception("on_progress callback raised; ignoring")
|
||||
|
||||
for row in rows:
|
||||
row["_category"] = categorise(row)
|
||||
|
||||
counts = {"alive": 0, "reversed": 0, "dead": 0}
|
||||
for row in rows:
|
||||
counts[row["_category"]] += 1
|
||||
|
||||
rows_by_ir = sorted(rows, key=lambda r: r["ir"], reverse=True)
|
||||
rows_by_ic = sorted(rows, key=lambda r: r["ic_mean"])
|
||||
|
||||
def _slim(r: dict[str, Any]) -> dict[str, Any]:
|
||||
return {
|
||||
"id": r["id"],
|
||||
"ic_mean": r["ic_mean"],
|
||||
"ir": r["ir"],
|
||||
"theme": r["theme"],
|
||||
"formula_latex": r["formula_latex"],
|
||||
"category": r["_category"],
|
||||
}
|
||||
|
||||
# Forward universe metadata (e.g. survivorship_bias flag from sp500
|
||||
# loader). Panel meta lives in panel["_meta"] when the loader chooses to
|
||||
# set it; absence is fine.
|
||||
universe_meta_raw = panel.get("_meta") if isinstance(panel, dict) else None
|
||||
universe_meta: dict[str, Any] = {}
|
||||
if universe_meta_raw is not None:
|
||||
try:
|
||||
# Could be a pandas object or a plain dict.
|
||||
if hasattr(universe_meta_raw, "to_dict"):
|
||||
universe_meta = dict(universe_meta_raw.to_dict())
|
||||
else:
|
||||
universe_meta = dict(universe_meta_raw)
|
||||
except Exception: # noqa: BLE001
|
||||
universe_meta = {"raw": str(universe_meta_raw)}
|
||||
|
||||
entry.update(
|
||||
{
|
||||
"status": "ok",
|
||||
"n_alphas_tested": len(rows),
|
||||
"n_skipped": len(skipped),
|
||||
"alive": counts["alive"],
|
||||
"reversed": counts["reversed"],
|
||||
"dead": counts["dead"],
|
||||
"by_theme": theme_breakdown(rows),
|
||||
"top5_by_ir": [_slim(r) for r in rows_by_ir[: min(5, top)]],
|
||||
"dead_examples": [_slim(r) for r in rows_by_ic[:5]],
|
||||
"rows": rows,
|
||||
"skipped": skipped,
|
||||
"meta": universe_meta,
|
||||
"wall_seconds": round(time.monotonic() - start, 2),
|
||||
}
|
||||
)
|
||||
return entry
|
||||
@@ -0,0 +1,909 @@
|
||||
"""CLI handlers for ``vibe-trading alpha {list,show,bench,compare,export-manifest}``.
|
||||
|
||||
All logic lives here; ``agent/cli.py`` only wires this in via :func:`add_subparser`
|
||||
and :func:`dispatch`. Handlers print to stdout (Rich when available, plain
|
||||
``print`` fallback) and return an int exit code. Errors are reported as a
|
||||
one-line stderr message; tracebacks are suppressed unless ``--verbose`` is set
|
||||
on the namespace.
|
||||
|
||||
Security gates:
|
||||
* ``alpha show <id>`` validates ``id`` against ``Registry().list()`` before
|
||||
touching the filesystem.
|
||||
* ``alpha export-manifest --out PATH`` refuses to write outside the repo
|
||||
root (``Path(__file__).resolve().parents[3]``) unless ``--force``.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import sys
|
||||
import time
|
||||
import traceback
|
||||
import warnings
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from typing import Any, Callable
|
||||
|
||||
# Silence the noisy ConstantInputWarning that scipy emits from spearmanr when
|
||||
# the IC slice has zero variance (very common in alpha bench loops).
|
||||
try:
|
||||
from scipy.stats import ConstantInputWarning # type: ignore[attr-defined]
|
||||
|
||||
warnings.filterwarnings("ignore", category=ConstantInputWarning)
|
||||
except Exception: # pragma: no cover — older scipy / unexpected layout
|
||||
try:
|
||||
from scipy.stats._warnings_errors import ( # type: ignore[attr-defined]
|
||||
ConstantInputWarning,
|
||||
)
|
||||
|
||||
warnings.filterwarnings("ignore", category=ConstantInputWarning)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
try:
|
||||
from rich.console import Console
|
||||
from rich.progress import (
|
||||
BarColumn,
|
||||
Progress,
|
||||
SpinnerColumn,
|
||||
TextColumn,
|
||||
TimeElapsedColumn,
|
||||
)
|
||||
from rich.syntax import Syntax
|
||||
from rich.table import Table
|
||||
|
||||
_console: Console | None = Console()
|
||||
except Exception: # pragma: no cover — rich is a project dep, fallback only
|
||||
_console = None
|
||||
Syntax = None # type: ignore[assignment]
|
||||
Table = None # type: ignore[assignment]
|
||||
Progress = None # type: ignore[assignment]
|
||||
BarColumn = None # type: ignore[assignment]
|
||||
SpinnerColumn = None # type: ignore[assignment]
|
||||
TextColumn = None # type: ignore[assignment]
|
||||
TimeElapsedColumn = None # type: ignore[assignment]
|
||||
|
||||
from src.factors.registry import Registry, RegistryError
|
||||
|
||||
|
||||
# Resolve repo root once: this file lives at
|
||||
# ``<repo>/agent/src/factors/cli_handlers.py``; parents[3] is the repo root.
|
||||
# We treat ``<repo>`` (and any subdirectory thereof) as the write-allow root.
|
||||
_REPO_ROOT = Path(__file__).resolve().parents[3]
|
||||
|
||||
_UNIVERSE_CHOICES = ["csi300", "sp500", "btc-usdt"]
|
||||
|
||||
|
||||
def _print(msg: str) -> None:
|
||||
if _console is not None:
|
||||
_console.print(msg)
|
||||
else:
|
||||
print(msg)
|
||||
|
||||
|
||||
def _err(msg: str) -> None:
|
||||
print(msg, file=sys.stderr)
|
||||
|
||||
|
||||
def _stdout_is_tty() -> bool:
|
||||
try:
|
||||
return sys.stdout.isatty()
|
||||
except Exception: # noqa: BLE001
|
||||
return False
|
||||
|
||||
|
||||
_stderr_console: Console | None = None
|
||||
if _console is not None:
|
||||
try:
|
||||
_stderr_console = Console(stderr=True)
|
||||
except Exception: # noqa: BLE001
|
||||
_stderr_console = None
|
||||
|
||||
|
||||
def _hint(msg: str) -> None:
|
||||
"""Print a next-step hint to stderr when stdout is a TTY.
|
||||
|
||||
Goes to stderr so it does not pollute JSON / pipe-friendly stdout output.
|
||||
"""
|
||||
if not _stdout_is_tty():
|
||||
return
|
||||
if _stderr_console is not None:
|
||||
_stderr_console.print(f"[dim]{msg}[/dim]")
|
||||
else:
|
||||
print(msg, file=sys.stderr)
|
||||
|
||||
|
||||
def _handle_exception(args: argparse.Namespace, prefix: str, exc: BaseException) -> int:
|
||||
"""Print one-line error; emit traceback only when ``--verbose`` is set."""
|
||||
_err(f"{prefix}: {exc}")
|
||||
if getattr(args, "verbose", False):
|
||||
traceback.print_exception(type(exc), exc, exc.__traceback__)
|
||||
# Surface a helpful banner for the common TUSHARE_TOKEN error case.
|
||||
if "TUSHARE_TOKEN" in str(exc):
|
||||
_err("")
|
||||
_err("How to fix:")
|
||||
_err(" 1. Register for a free token at https://tushare.pro/register")
|
||||
_err(" 2. Add 'TUSHARE_TOKEN=<your_token>' to agent/.env (or ~/.vibe-trading/.env)")
|
||||
_err(" 3. Re-run this command")
|
||||
return 1
|
||||
|
||||
|
||||
# --------------------------------------------------------------------------- #
|
||||
# Handlers #
|
||||
# --------------------------------------------------------------------------- #
|
||||
|
||||
|
||||
def cmd_alpha_list(args: argparse.Namespace) -> int:
|
||||
"""``vibe-trading alpha list [--zoo X] [--theme Y] [--universe Z]``.
|
||||
|
||||
Supports ``--limit N`` (default 50) and ``--json`` for machine-readable
|
||||
output. ``--include-load-errors`` (alias: ``--show-failed``) appends a
|
||||
registry health block.
|
||||
"""
|
||||
try:
|
||||
reg = Registry()
|
||||
ids = reg.list(zoo=args.zoo, theme=args.theme, universe=args.universe)
|
||||
|
||||
limit = getattr(args, "limit", None)
|
||||
total = len(ids)
|
||||
truncated = False
|
||||
# limit > 0 => cap; limit == 0 / None => no cap.
|
||||
if isinstance(limit, int) and limit > 0 and total > limit:
|
||||
ids = ids[:limit]
|
||||
truncated = True
|
||||
|
||||
# JSON mode: machine-readable, no Rich, no hints.
|
||||
if getattr(args, "json", False):
|
||||
records: list[dict[str, Any]] = []
|
||||
for alpha_id in ids:
|
||||
alpha = reg.get(alpha_id)
|
||||
meta = alpha.meta or {}
|
||||
records.append(
|
||||
{
|
||||
"id": alpha.id,
|
||||
"zoo": alpha.zoo,
|
||||
"theme": meta.get("theme", []) or [],
|
||||
"universe": meta.get("universe", []) or [],
|
||||
"decay_horizon": meta.get("decay_horizon"),
|
||||
}
|
||||
)
|
||||
print(json.dumps(records, indent=2, default=str))
|
||||
if _include_load_errors(args):
|
||||
_print_load_errors(reg)
|
||||
return 0
|
||||
|
||||
if not ids:
|
||||
_print("[dim]no alphas matched the filters[/dim]" if _console else "no alphas matched the filters")
|
||||
elif _console is not None and Table is not None:
|
||||
title = f"Alpha Zoo ({len(ids)} of {total} alphas)" if truncated else f"Alpha Zoo ({total} alphas)"
|
||||
table = Table(title=title)
|
||||
table.add_column("id", style="cyan", no_wrap=True)
|
||||
table.add_column("zoo", style="magenta")
|
||||
table.add_column("theme")
|
||||
table.add_column("universe")
|
||||
table.add_column("nickname")
|
||||
for alpha_id in ids:
|
||||
alpha = reg.get(alpha_id)
|
||||
meta = alpha.meta
|
||||
table.add_row(
|
||||
alpha.id,
|
||||
alpha.zoo,
|
||||
", ".join(meta.get("theme", []) or []),
|
||||
", ".join(meta.get("universe", []) or []),
|
||||
meta.get("nickname") or "",
|
||||
)
|
||||
_console.print(table)
|
||||
if truncated:
|
||||
_print(f"[dim]Showing {len(ids)} of {total}. Pass --limit N (or --limit 0 for no cap).[/dim]")
|
||||
else:
|
||||
for alpha_id in ids:
|
||||
alpha = reg.get(alpha_id)
|
||||
meta = alpha.meta
|
||||
print(
|
||||
f"{alpha.id}\t{alpha.zoo}\t"
|
||||
f"{','.join(meta.get('theme', []) or [])}\t"
|
||||
f"{','.join(meta.get('universe', []) or [])}\t"
|
||||
f"{meta.get('nickname') or ''}"
|
||||
)
|
||||
if truncated:
|
||||
print(f"[showing {len(ids)} of {total}]")
|
||||
|
||||
if _include_load_errors(args):
|
||||
_print_load_errors(reg)
|
||||
|
||||
if ids:
|
||||
example_id = ids[0]
|
||||
example_zoo = reg.get(example_id).zoo
|
||||
_hint(
|
||||
f"Next: vibe-trading alpha show {example_id} | "
|
||||
f"Bench a zoo: vibe-trading alpha bench --zoo {example_zoo} "
|
||||
f"--universe csi300 --period 2020-2025"
|
||||
)
|
||||
return 0
|
||||
except Exception as exc: # noqa: BLE001
|
||||
return _handle_exception(args, "alpha list failed", exc)
|
||||
|
||||
|
||||
def _include_load_errors(args: argparse.Namespace) -> bool:
|
||||
"""Honour both the new flag name and the deprecated alias."""
|
||||
return bool(getattr(args, "include_load_errors", False) or getattr(args, "show_failed", False))
|
||||
|
||||
|
||||
def _print_load_errors(reg: Registry) -> None:
|
||||
health = reg.health()
|
||||
errors = health.get("errors", [])
|
||||
if not errors:
|
||||
_print("[green]no load errors[/green]" if _console else "no load errors")
|
||||
return
|
||||
_print(
|
||||
f"[yellow]{len(errors)} load error(s):[/yellow]"
|
||||
if _console
|
||||
else f"{len(errors)} load error(s):"
|
||||
)
|
||||
for entry in errors:
|
||||
_print(f" - {entry.get('alpha_id')}: {entry.get('reason')}")
|
||||
|
||||
|
||||
def cmd_alpha_show(args: argparse.Namespace) -> int:
|
||||
"""``vibe-trading alpha show <alpha_id> [--brief]`` — metadata + source."""
|
||||
try:
|
||||
reg = Registry()
|
||||
if args.alpha_id not in reg.list():
|
||||
_err(f"alpha id not found: {args.alpha_id}")
|
||||
return 1
|
||||
|
||||
alpha = reg.get(args.alpha_id)
|
||||
meta = alpha.meta
|
||||
brief = bool(getattr(args, "brief", False))
|
||||
|
||||
_print(f"[bold cyan]id[/bold cyan]: {alpha.id}" if _console else f"id: {alpha.id}")
|
||||
if not brief:
|
||||
_print(f"[bold]zoo[/bold]: {alpha.zoo}" if _console else f"zoo: {alpha.zoo}")
|
||||
_print(
|
||||
f"[bold]module_path[/bold]: {alpha.module_path}"
|
||||
if _console
|
||||
else f"module_path: {alpha.module_path}"
|
||||
)
|
||||
_print(
|
||||
f"[bold]nickname[/bold]: {meta.get('nickname') or '-'}"
|
||||
if _console
|
||||
else f"nickname: {meta.get('nickname') or '-'}"
|
||||
)
|
||||
_print(
|
||||
f"[bold]theme[/bold]: {', '.join(meta.get('theme', []) or [])}"
|
||||
if _console
|
||||
else f"theme: {', '.join(meta.get('theme', []) or [])}"
|
||||
)
|
||||
_print(
|
||||
f"[bold]universe[/bold]: {', '.join(meta.get('universe', []) or [])}"
|
||||
if _console
|
||||
else f"universe: {', '.join(meta.get('universe', []) or [])}"
|
||||
)
|
||||
if not brief:
|
||||
_print(
|
||||
f"[bold]columns_required[/bold]: {', '.join(meta.get('columns_required', []) or [])}"
|
||||
if _console
|
||||
else f"columns_required: {', '.join(meta.get('columns_required', []) or [])}"
|
||||
)
|
||||
_print(
|
||||
f"[bold]decay_horizon[/bold]: {meta.get('decay_horizon')}"
|
||||
if _console
|
||||
else f"decay_horizon: {meta.get('decay_horizon')}"
|
||||
)
|
||||
_print(
|
||||
f"[bold]formula_latex[/bold]: {meta.get('formula_latex', '')}"
|
||||
if _console
|
||||
else f"formula_latex: {meta.get('formula_latex', '')}"
|
||||
)
|
||||
notes = meta.get("notes") or ""
|
||||
if notes:
|
||||
_print(f"[bold]notes[/bold]: {notes}" if _console else f"notes: {notes}")
|
||||
|
||||
if brief:
|
||||
_hint(
|
||||
f"Next: vibe-trading alpha bench --zoo {alpha.zoo} "
|
||||
f"--universe csi300 --period 2020-2025 --top 20"
|
||||
)
|
||||
return 0
|
||||
|
||||
# Source code — read via the registry's _py_paths cache (semi-private but
|
||||
# accepted in the parcel contract; falls back to importlib.getsource).
|
||||
py_path: Path | None = reg._py_paths.get(alpha.id) # noqa: SLF001
|
||||
source: str | None = None
|
||||
if py_path is not None and py_path.is_file():
|
||||
try:
|
||||
source = py_path.read_text(encoding="utf-8")
|
||||
except OSError as exc:
|
||||
_err(f"warning: could not read source file {py_path}: {exc}")
|
||||
if source is None:
|
||||
try:
|
||||
import importlib
|
||||
import inspect
|
||||
|
||||
module = importlib.import_module(alpha.module_path)
|
||||
source = inspect.getsource(module)
|
||||
except Exception as exc: # noqa: BLE001
|
||||
_err(f"warning: could not load source via importlib: {exc}")
|
||||
source = None
|
||||
|
||||
if source:
|
||||
_print("[bold]source[/bold]:" if _console else "source:")
|
||||
if _console is not None and Syntax is not None:
|
||||
try:
|
||||
_console.print(
|
||||
Syntax(
|
||||
source,
|
||||
"python",
|
||||
line_numbers=True,
|
||||
theme="monokai",
|
||||
word_wrap=True,
|
||||
),
|
||||
soft_wrap=True,
|
||||
)
|
||||
except Exception: # noqa: BLE001 — fall back to raw print
|
||||
print(source)
|
||||
else:
|
||||
print(source)
|
||||
|
||||
_hint(
|
||||
f"Next: vibe-trading alpha bench --zoo {alpha.zoo} "
|
||||
f"--universe csi300 --period 2020-2025 --top 20"
|
||||
)
|
||||
return 0
|
||||
except Exception as exc: # noqa: BLE001
|
||||
return _handle_exception(args, "alpha show failed", exc)
|
||||
|
||||
|
||||
def _confirm_bench_all(n_total: int) -> bool:
|
||||
"""Interactive y/N prompt before benching every alpha."""
|
||||
msg = f"About to bench {n_total} alphas (~10-15 min). Continue? [y/N] "
|
||||
try:
|
||||
reply = input(msg).strip().lower()
|
||||
except EOFError:
|
||||
return False
|
||||
return reply in {"y", "yes"}
|
||||
|
||||
|
||||
def _zoo_for_id(reg: Registry, alpha_id: str | None) -> str:
|
||||
"""Lookup an alpha's zoo (best-effort, returns '' on failure)."""
|
||||
if not alpha_id:
|
||||
return ""
|
||||
try:
|
||||
return reg.get(alpha_id).zoo
|
||||
except Exception: # noqa: BLE001
|
||||
return ""
|
||||
|
||||
|
||||
def _run_single_zoo_with_progress(
|
||||
*,
|
||||
zoo: str,
|
||||
universe: str,
|
||||
period: str,
|
||||
top: int,
|
||||
n_target: int,
|
||||
reg: Registry,
|
||||
run_bench: Callable[..., dict[str, Any]],
|
||||
) -> dict[str, Any]:
|
||||
"""Run :func:`bench_runner.run_bench` for one zoo with a Rich progress bar."""
|
||||
if _console is None or Progress is None:
|
||||
return run_bench(
|
||||
zoo=zoo,
|
||||
universe=universe,
|
||||
period=period,
|
||||
top=top,
|
||||
registry=reg,
|
||||
)
|
||||
|
||||
with Progress(
|
||||
SpinnerColumn(),
|
||||
TextColumn("[progress.description]{task.description}"),
|
||||
BarColumn(),
|
||||
TextColumn("{task.completed}/{task.total}"),
|
||||
TextColumn("[cyan]{task.fields[current]}[/cyan]"),
|
||||
TimeElapsedColumn(),
|
||||
console=_console,
|
||||
transient=False,
|
||||
) as progress:
|
||||
task_id = progress.add_task(
|
||||
description="Benching",
|
||||
total=n_target,
|
||||
current="loading universe...",
|
||||
)
|
||||
|
||||
def on_progress(n_done: int, n_total: int, aid: str) -> None:
|
||||
progress.update(task_id, completed=n_done, total=n_total, current=aid)
|
||||
|
||||
return run_bench(
|
||||
zoo=zoo,
|
||||
universe=universe,
|
||||
period=period,
|
||||
top=top,
|
||||
on_progress=on_progress,
|
||||
registry=reg,
|
||||
)
|
||||
|
||||
|
||||
def _run_all_zoos_with_progress(
|
||||
*,
|
||||
target_ids: list[str],
|
||||
universe: str,
|
||||
period: str,
|
||||
top: int,
|
||||
start_ts: float,
|
||||
reg: Registry,
|
||||
run_bench: Callable[..., dict[str, Any]],
|
||||
) -> dict[str, Any]:
|
||||
"""Aggregate across every zoo for the ``--yes`` / no-``--zoo`` case."""
|
||||
zoos = sorted({reg.get(aid).zoo for aid in target_ids})
|
||||
total_alphas = sum(len(reg.list(zoo=z)) for z in zoos)
|
||||
all_rows: list[dict[str, Any]] = []
|
||||
all_skipped: list[dict[str, Any]] = []
|
||||
|
||||
def _run_zoo(z: str, base: int, update: Callable[[int, str], None] | None) -> None:
|
||||
cb: Callable[[int, int, str], None] | None = None
|
||||
if update is not None:
|
||||
def cb(n_done: int, _n_total: int, aid: str) -> None:
|
||||
update(base + n_done, f"{z}:{aid}")
|
||||
sub = run_bench(
|
||||
zoo=z,
|
||||
universe=universe,
|
||||
period=period,
|
||||
top=top,
|
||||
on_progress=cb,
|
||||
registry=reg,
|
||||
)
|
||||
if sub.get("status") == "ok":
|
||||
all_rows.extend(sub.get("rows", []) or [])
|
||||
all_skipped.extend(sub.get("skipped", []) or [])
|
||||
else:
|
||||
all_skipped.append({"id": f"<zoo:{z}>", "reason": sub.get("error", "unknown")})
|
||||
|
||||
if _console is not None and Progress is not None:
|
||||
with Progress(
|
||||
SpinnerColumn(),
|
||||
TextColumn("[progress.description]{task.description}"),
|
||||
BarColumn(),
|
||||
TextColumn("{task.completed}/{task.total}"),
|
||||
TextColumn("[cyan]{task.fields[current]}[/cyan]"),
|
||||
TimeElapsedColumn(),
|
||||
console=_console,
|
||||
transient=False,
|
||||
) as progress:
|
||||
task_id = progress.add_task(
|
||||
description="Benching (all zoos)",
|
||||
total=total_alphas,
|
||||
current="starting...",
|
||||
)
|
||||
|
||||
def update(done: int, current: str) -> None:
|
||||
progress.update(task_id, completed=done, current=current)
|
||||
|
||||
seen = 0
|
||||
for z in zoos:
|
||||
_run_zoo(z, seen, update)
|
||||
seen += len(reg.list(zoo=z))
|
||||
else:
|
||||
for z in zoos:
|
||||
_run_zoo(z, 0, None)
|
||||
|
||||
return {
|
||||
"status": "ok" if all_rows else "error",
|
||||
"zoo": "all",
|
||||
"universe": universe,
|
||||
"period": period,
|
||||
"rows": all_rows,
|
||||
"skipped": all_skipped,
|
||||
"n_alphas_tested": len(all_rows),
|
||||
"n_skipped": len(all_skipped),
|
||||
"wall_seconds": round(time.monotonic() - start_ts, 2),
|
||||
**({"error": "no alphas produced IC across any zoo"} if not all_rows else {}),
|
||||
}
|
||||
|
||||
|
||||
def cmd_alpha_bench(args: argparse.Namespace) -> int:
|
||||
"""``vibe-trading alpha bench --zoo X --universe csi300 --period Y-Z [--top N]``.
|
||||
|
||||
Calls :func:`src.factors.bench_runner.run_bench` for the IC loop so we can
|
||||
stream Rich progress, then renders the HTML report via helpers imported
|
||||
from ``src.tools.alpha_bench_tool`` (we do NOT modify that module).
|
||||
"""
|
||||
try:
|
||||
try:
|
||||
from src.factors.bench_runner import run_bench
|
||||
except ImportError as exc:
|
||||
_err(f"alpha bench failed: bench_runner unavailable ({exc})")
|
||||
return 1
|
||||
|
||||
# --- 1. Decide which zoo to run (handle no-args footgun) ----------- #
|
||||
zoo = args.zoo
|
||||
if zoo is None:
|
||||
reg = Registry()
|
||||
n_total = len(reg.list())
|
||||
if getattr(args, "yes", False):
|
||||
_print(
|
||||
f"[yellow]No --zoo passed; benching ALL {n_total} alphas "
|
||||
f"(confirmed via --yes).[/yellow]"
|
||||
if _console
|
||||
else f"No --zoo passed; benching ALL {n_total} alphas (--yes)."
|
||||
)
|
||||
else:
|
||||
_print(
|
||||
f"[yellow]Warning:[/yellow] no --zoo passed; this would bench "
|
||||
f"every registered alpha ({n_total} total)."
|
||||
if _console
|
||||
else f"Warning: no --zoo passed; this would bench every alpha ({n_total})."
|
||||
)
|
||||
if not _confirm_bench_all(n_total):
|
||||
_err("alpha bench: aborted (pass --zoo <id> or --yes to confirm).")
|
||||
return 1
|
||||
|
||||
# --- 2. Pre-flight banner: counts + ETA ---------------------------- #
|
||||
reg = Registry()
|
||||
if zoo is not None:
|
||||
target_ids = reg.list(zoo=zoo)
|
||||
else:
|
||||
target_ids = reg.list()
|
||||
n_target = len(target_ids)
|
||||
if n_target == 0:
|
||||
_err(f"alpha bench failed: no alphas registered under zoo={zoo!r}")
|
||||
return 1
|
||||
|
||||
_print(
|
||||
f"[bold]Bench:[/bold] {n_target} alphas x {args.universe} x {args.period}"
|
||||
if _console
|
||||
else f"Bench: {n_target} alphas x {args.universe} x {args.period}"
|
||||
)
|
||||
_print(
|
||||
"[dim]ETA: ~3-5 min (cache hit) / ~10-20 min (cold fetch)[/dim]"
|
||||
if _console
|
||||
else "ETA: ~3-5 min (cache hit) / ~10-20 min (cold fetch)"
|
||||
)
|
||||
|
||||
# --- 3. Run the bench loop with a live progress bar --------------- #
|
||||
start_ts = time.monotonic()
|
||||
result: dict[str, Any]
|
||||
|
||||
if zoo is not None:
|
||||
# Single-zoo path: one call to bench_runner.run_bench.
|
||||
result = _run_single_zoo_with_progress(
|
||||
zoo=zoo,
|
||||
universe=args.universe,
|
||||
period=args.period,
|
||||
top=args.top,
|
||||
n_target=n_target,
|
||||
reg=reg,
|
||||
run_bench=run_bench,
|
||||
)
|
||||
else:
|
||||
# Multi-zoo path: aggregate across every zoo (bench_runner requires
|
||||
# a non-empty zoo, so we loop per zoo and merge).
|
||||
result = _run_all_zoos_with_progress(
|
||||
target_ids=target_ids,
|
||||
universe=args.universe,
|
||||
period=args.period,
|
||||
top=args.top,
|
||||
start_ts=start_ts,
|
||||
reg=reg,
|
||||
run_bench=run_bench,
|
||||
)
|
||||
|
||||
# --- 5. Handle bench-loop errors / propagate exit code ------------- #
|
||||
status = result.get("status")
|
||||
if status != "ok":
|
||||
err_msg = result.get("error", "unknown error")
|
||||
envelope = {
|
||||
"status": "error",
|
||||
"error": err_msg,
|
||||
"zoo": zoo,
|
||||
"universe": args.universe,
|
||||
"period": args.period,
|
||||
}
|
||||
print(json.dumps(envelope, indent=2, default=str))
|
||||
_err(f"alpha bench failed: {err_msg}")
|
||||
if "TUSHARE_TOKEN" in str(err_msg):
|
||||
_err("")
|
||||
_err("How to fix:")
|
||||
_err(" 1. Register for a free token at https://tushare.pro/register")
|
||||
_err(" 2. Add 'TUSHARE_TOKEN=<your_token>' to agent/.env (or ~/.vibe-trading/.env)")
|
||||
_err(" 3. Re-run this command")
|
||||
return 1
|
||||
|
||||
# --- 6. Render HTML report (delegating to alpha_bench_tool helpers) -#
|
||||
rows = result.get("rows", []) or []
|
||||
skipped = result.get("skipped", []) or []
|
||||
top_n = max(1, int(args.top))
|
||||
rows_sorted = sorted(rows, key=lambda r: r.get("ir", 0.0), reverse=True)
|
||||
top_rows_raw = rows_sorted[:top_n]
|
||||
|
||||
# Normalise rows + skipped for the report template (and for the JSON
|
||||
# envelope so consumers don't see the internal _category key).
|
||||
def _normalise_row(r: dict[str, Any]) -> dict[str, Any]:
|
||||
return {
|
||||
"id": r.get("id"),
|
||||
"zoo": r.get("zoo") or _zoo_for_id(reg, r.get("id")),
|
||||
"theme": r.get("theme") or [],
|
||||
"formula_latex": r.get("formula_latex", ""),
|
||||
"ic_mean": r.get("ic_mean", 0.0),
|
||||
"ic_std": r.get("ic_std", 0.0),
|
||||
"ir": r.get("ir", 0.0),
|
||||
"ic_positive_ratio": r.get("ic_positive_ratio", 0.0),
|
||||
"ic_count": r.get("ic_count", 0),
|
||||
"category": r.get("_category") or r.get("category"),
|
||||
}
|
||||
|
||||
def _normalise_skipped(s: dict[str, Any]) -> dict[str, Any]:
|
||||
return {"alpha_id": s.get("id") or s.get("alpha_id"), "reason": s.get("reason", "")}
|
||||
|
||||
top_rows = [_normalise_row(r) for r in top_rows_raw]
|
||||
failures_for_report = [_normalise_skipped(s) for s in skipped[:10]]
|
||||
|
||||
report_path: Path | None = None
|
||||
try:
|
||||
from src.tools.alpha_bench_tool import ( # type: ignore[import-not-found]
|
||||
_CSP,
|
||||
_REPORT_CSS,
|
||||
_default_output_dir,
|
||||
_render_html,
|
||||
)
|
||||
|
||||
output_dir = _default_output_dir()
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
ts = datetime.now(timezone.utc).strftime("%Y%m%dT%H%M%SZ")
|
||||
report_path = output_dir / f"alpha_bench_{ts}.html"
|
||||
context = {
|
||||
"csp": _CSP,
|
||||
"css": _REPORT_CSS,
|
||||
"generated_at": datetime.now(timezone.utc).isoformat(timespec="seconds"),
|
||||
"universe": args.universe,
|
||||
"period": args.period,
|
||||
"n_alphas_tested": len(rows),
|
||||
"n_skipped": len(skipped),
|
||||
"top": top_rows,
|
||||
"failures": failures_for_report,
|
||||
}
|
||||
report_path.write_text(_render_html(context), encoding="utf-8")
|
||||
except Exception as exc: # noqa: BLE001 — report is nice-to-have
|
||||
_err(f"warning: could not write HTML report: {exc}")
|
||||
report_path = None
|
||||
|
||||
envelope: dict[str, Any] = {
|
||||
"status": "ok",
|
||||
"zoo": zoo,
|
||||
"universe": args.universe,
|
||||
"period": args.period,
|
||||
"n_alphas_tested": len(rows),
|
||||
"n_skipped": len(skipped),
|
||||
"top": top_rows,
|
||||
"wall_seconds": result.get("wall_seconds"),
|
||||
}
|
||||
if report_path is not None:
|
||||
envelope["report_path"] = str(report_path)
|
||||
print(json.dumps(envelope, indent=2, default=str))
|
||||
|
||||
# Final stderr success line (M4).
|
||||
tested = len(rows)
|
||||
skipped_n = len(skipped)
|
||||
summary = f"✓ Bench complete. {tested} tested, {skipped_n} skipped."
|
||||
if report_path is not None:
|
||||
summary += f" Report: {report_path}"
|
||||
if _stderr_console is not None:
|
||||
_stderr_console.print(summary, style="green")
|
||||
else:
|
||||
print(summary, file=sys.stderr)
|
||||
return 0
|
||||
except Exception as exc: # noqa: BLE001
|
||||
return _handle_exception(args, "alpha bench failed", exc)
|
||||
|
||||
|
||||
def cmd_alpha_compare(args: argparse.Namespace) -> int:
|
||||
"""``vibe-trading alpha compare <id1> [<id2> ...] | --all | --zoo X``.
|
||||
|
||||
Stub for W4; reports validated targets so callers can wire scripts.
|
||||
"""
|
||||
try:
|
||||
targets: list[str]
|
||||
reg = Registry()
|
||||
if getattr(args, "compare_all", False):
|
||||
targets = reg.list()
|
||||
elif args.zoo:
|
||||
targets = reg.list(zoo=args.zoo)
|
||||
else:
|
||||
targets = list(args.alpha_ids or [])
|
||||
|
||||
if not targets:
|
||||
_err(
|
||||
"alpha compare: no targets supplied "
|
||||
"(pass alpha ids, or --all for every alpha, or --zoo X to filter)"
|
||||
)
|
||||
return 1
|
||||
|
||||
_print(f"compare targets ({len(targets)}): {', '.join(targets)}")
|
||||
_print(
|
||||
"[yellow]alpha compare not yet implemented (W4)[/yellow]"
|
||||
if _console
|
||||
else "alpha compare not yet implemented (W4)"
|
||||
)
|
||||
print(json.dumps({"status": "stub", "targets": targets, "reason": "W4 not implemented"}, indent=2))
|
||||
return 0
|
||||
except Exception as exc: # noqa: BLE001
|
||||
return _handle_exception(args, "alpha compare failed", exc)
|
||||
|
||||
|
||||
def cmd_alpha_export_manifest(args: argparse.Namespace) -> int:
|
||||
"""``vibe-trading alpha export-manifest --out PATH [--force]``."""
|
||||
try:
|
||||
out_path = Path(args.out).resolve()
|
||||
|
||||
# Refuse to write outside the repo root unless --force.
|
||||
try:
|
||||
out_path.relative_to(_REPO_ROOT)
|
||||
inside_repo = True
|
||||
except ValueError:
|
||||
inside_repo = False
|
||||
if not inside_repo and not args.force:
|
||||
_err(
|
||||
f"alpha export-manifest: refusing to write outside repo root "
|
||||
f"({_REPO_ROOT}); pass --force to override. target={out_path}"
|
||||
)
|
||||
return 1
|
||||
|
||||
parent = out_path.parent
|
||||
if not parent.exists():
|
||||
parent.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
reg = Registry()
|
||||
manifest = reg.export_manifest()
|
||||
out_path.write_text(json.dumps(manifest, indent=2, default=str), encoding="utf-8")
|
||||
_print(
|
||||
f"[green]wrote manifest[/green] ({manifest['health']['loaded']} alphas, "
|
||||
f"{manifest['health']['failed']} errors) -> {out_path}"
|
||||
if _console
|
||||
else f"wrote manifest ({manifest['health']['loaded']} alphas, "
|
||||
f"{manifest['health']['failed']} errors) -> {out_path}"
|
||||
)
|
||||
return 0
|
||||
except (RegistryError, OSError) as exc:
|
||||
return _handle_exception(args, "alpha export-manifest failed", exc)
|
||||
except Exception as exc: # noqa: BLE001
|
||||
return _handle_exception(args, "alpha export-manifest failed", exc)
|
||||
|
||||
|
||||
# --------------------------------------------------------------------------- #
|
||||
# Subparser + dispatch wiring #
|
||||
# --------------------------------------------------------------------------- #
|
||||
|
||||
|
||||
_DISPATCH: dict[str, Callable[[argparse.Namespace], int]] = {
|
||||
"list": cmd_alpha_list,
|
||||
"show": cmd_alpha_show,
|
||||
"bench": cmd_alpha_bench,
|
||||
"compare": cmd_alpha_compare,
|
||||
"export-manifest": cmd_alpha_export_manifest,
|
||||
}
|
||||
|
||||
|
||||
# Module-level handle to the alpha parser so ``dispatch`` can print full help
|
||||
# when no subcommand is supplied (M6).
|
||||
_ALPHA_PARSER: argparse.ArgumentParser | None = None
|
||||
|
||||
|
||||
def add_subparser(subparsers: Any) -> argparse.ArgumentParser:
|
||||
"""Register ``alpha`` and its five sub-sub-commands on the given subparsers.
|
||||
|
||||
Args:
|
||||
subparsers: The object returned by ``ArgumentParser.add_subparsers(...)``.
|
||||
|
||||
Returns:
|
||||
The ``alpha`` parser (mostly for test introspection).
|
||||
"""
|
||||
global _ALPHA_PARSER
|
||||
|
||||
alpha_parser = subparsers.add_parser(
|
||||
"alpha", help="Alpha Zoo: list / show / bench / compare / export-manifest"
|
||||
)
|
||||
alpha_parser.add_argument(
|
||||
"--verbose", action="store_true", help="Show full traceback on errors"
|
||||
)
|
||||
alpha_sub = alpha_parser.add_subparsers(dest="alpha_command")
|
||||
|
||||
p_list = alpha_sub.add_parser("list", help="List registered alphas")
|
||||
p_list.add_argument("--zoo", default=None, help="Filter by zoo (e.g. alpha101)")
|
||||
p_list.add_argument("--theme", default=None, help="Filter by theme (e.g. momentum)")
|
||||
p_list.add_argument(
|
||||
"--universe",
|
||||
default=None,
|
||||
choices=_UNIVERSE_CHOICES,
|
||||
help=f"Filter by universe ({', '.join(_UNIVERSE_CHOICES)})",
|
||||
)
|
||||
p_list.add_argument(
|
||||
"--limit",
|
||||
type=int,
|
||||
default=50,
|
||||
help="Max alphas to print (default: 50; pass 0 for no cap)",
|
||||
)
|
||||
p_list.add_argument(
|
||||
"--json",
|
||||
action="store_true",
|
||||
help="Emit JSON array of {id, zoo, theme, universe, decay_horizon} instead of a table",
|
||||
)
|
||||
p_list.add_argument(
|
||||
"--include-load-errors",
|
||||
dest="include_load_errors",
|
||||
action="store_true",
|
||||
help="Also print load errors from registry.health()",
|
||||
)
|
||||
p_list.add_argument(
|
||||
"--show-failed",
|
||||
dest="show_failed",
|
||||
action="store_true",
|
||||
help="(deprecated) alias for --include-load-errors",
|
||||
)
|
||||
|
||||
p_show = alpha_sub.add_parser("show", help="Show alpha metadata and source code")
|
||||
p_show.add_argument("alpha_id", help="Alpha id, e.g. alpha101_001")
|
||||
p_show.add_argument(
|
||||
"--brief",
|
||||
action="store_true",
|
||||
help="Print only id/theme/universe/formula_latex/notes — omit source code",
|
||||
)
|
||||
|
||||
p_bench = alpha_sub.add_parser("bench", help="Benchmark alphas in a zoo")
|
||||
p_bench.add_argument("--zoo", default=None, help="Zoo to benchmark (required unless --yes is passed)")
|
||||
p_bench.add_argument(
|
||||
"--universe",
|
||||
default="csi300",
|
||||
choices=_UNIVERSE_CHOICES,
|
||||
help=f"Universe (default: csi300; one of {', '.join(_UNIVERSE_CHOICES)})",
|
||||
)
|
||||
p_bench.add_argument(
|
||||
"--period",
|
||||
default="2020-2025",
|
||||
help="Period spec: YYYY-YYYY or YYYY-MM-DD/YYYY-MM-DD (e.g. 2020-2025)",
|
||||
)
|
||||
p_bench.add_argument("--top", type=int, default=20, help="Top-N alphas to keep (default: 20)")
|
||||
p_bench.add_argument(
|
||||
"--yes",
|
||||
action="store_true",
|
||||
help="Skip the 'bench every alpha?' prompt when --zoo is omitted",
|
||||
)
|
||||
|
||||
p_compare = alpha_sub.add_parser("compare", help="Compare alphas (W4 stub)")
|
||||
p_compare.add_argument("alpha_ids", nargs="*", help="Alpha ids to compare")
|
||||
p_compare.add_argument(
|
||||
"--all",
|
||||
dest="compare_all",
|
||||
action="store_true",
|
||||
help="Compare every alpha in the registry",
|
||||
)
|
||||
p_compare.add_argument(
|
||||
"--zoo",
|
||||
default=None,
|
||||
help="Filter comparison to one zoo (e.g. alpha101)",
|
||||
)
|
||||
|
||||
p_export = alpha_sub.add_parser("export-manifest", help="Export registry manifest as JSON")
|
||||
p_export.add_argument("--out", required=True, help="Output JSON path")
|
||||
p_export.add_argument("--force", action="store_true", help="Allow writing outside the repo root")
|
||||
|
||||
_ALPHA_PARSER = alpha_parser
|
||||
return alpha_parser
|
||||
|
||||
|
||||
def dispatch(args: argparse.Namespace) -> int:
|
||||
"""Dispatch ``alpha <sub>`` to the matching handler.
|
||||
|
||||
Returns the exit code; ``cli.py`` propagates it via ``_coerce_exit_code``.
|
||||
"""
|
||||
sub = getattr(args, "alpha_command", None)
|
||||
if sub is None:
|
||||
if _ALPHA_PARSER is not None:
|
||||
_ALPHA_PARSER.print_help()
|
||||
else:
|
||||
_err("alpha requires a subcommand. Try: vibe-trading alpha list")
|
||||
return 1
|
||||
handler = _DISPATCH.get(sub)
|
||||
if handler is None:
|
||||
_err(f"alpha: unknown subcommand {sub!r}")
|
||||
return 1
|
||||
return handler(args)
|
||||
@@ -0,0 +1,127 @@
|
||||
"""Pure IC/IR + layered backtest math shared by factor_analysis_tool and alpha_bench_tool."""
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
from scipy.stats import spearmanr
|
||||
|
||||
_MIN_VALID_PER_DATE = 5
|
||||
|
||||
|
||||
def compute_ic_series(factor_df: pd.DataFrame, return_df: pd.DataFrame) -> pd.Series:
|
||||
"""Compute daily Spearman rank correlation (IC) between factor values and returns.
|
||||
|
||||
Vectorised via ``rank().corrwith()`` (Spearman = Pearson on ranks). A date
|
||||
is dropped if fewer than 5 instruments have both a factor and return value
|
||||
on that bar — matching the prior per-row guard.
|
||||
|
||||
Args:
|
||||
factor_df: Factor values; index=date, columns=codes.
|
||||
return_df: Returns; index=date, columns=codes.
|
||||
|
||||
Returns:
|
||||
IC series indexed by date.
|
||||
"""
|
||||
common_dates = factor_df.index.intersection(return_df.index)
|
||||
common_codes = factor_df.columns.intersection(return_df.columns)
|
||||
if len(common_dates) == 0 or len(common_codes) == 0:
|
||||
return pd.Series(dtype=float)
|
||||
|
||||
factor_df = factor_df.loc[common_dates, common_codes]
|
||||
return_df = return_df.loc[common_dates, common_codes]
|
||||
|
||||
# Only rank cells where both factor and return are present (mirrors the
|
||||
# per-date ``shared = f.dropna() ∩ r.dropna()`` from the loop version).
|
||||
pair_mask = factor_df.notna() & return_df.notna()
|
||||
n_valid = pair_mask.sum(axis=1)
|
||||
|
||||
factor_aligned = factor_df.where(pair_mask)
|
||||
return_aligned = return_df.where(pair_mask)
|
||||
|
||||
# Spearman = Pearson on per-row ranks.
|
||||
factor_ranks = factor_aligned.rank(axis=1, method="average")
|
||||
return_ranks = return_aligned.rank(axis=1, method="average")
|
||||
ic = factor_ranks.corrwith(return_ranks, axis=1, method="pearson")
|
||||
|
||||
ic = ic[n_valid >= _MIN_VALID_PER_DATE]
|
||||
ic = ic.dropna()
|
||||
if ic.empty:
|
||||
return pd.Series(dtype=float)
|
||||
return ic.astype(float)
|
||||
|
||||
|
||||
# Kept available for callers/tests that want the slow reference implementation.
|
||||
def _compute_ic_series_reference(
|
||||
factor_df: pd.DataFrame, return_df: pd.DataFrame
|
||||
) -> pd.Series:
|
||||
"""Loop-based Spearman IC; retained as the numerical reference."""
|
||||
common_dates = factor_df.index.intersection(return_df.index)
|
||||
common_codes = factor_df.columns.intersection(return_df.columns)
|
||||
if len(common_dates) == 0 or len(common_codes) == 0:
|
||||
return pd.Series(dtype=float)
|
||||
|
||||
factor_df = factor_df.loc[common_dates, common_codes]
|
||||
return_df = return_df.loc[common_dates, common_codes]
|
||||
|
||||
ic_values: dict = {}
|
||||
for date in common_dates:
|
||||
f = factor_df.loc[date].dropna()
|
||||
r = return_df.loc[date].dropna()
|
||||
shared = f.index.intersection(r.index)
|
||||
if len(shared) < _MIN_VALID_PER_DATE:
|
||||
continue
|
||||
corr, _ = spearmanr(f[shared], r[shared])
|
||||
if not np.isnan(corr):
|
||||
ic_values[date] = corr
|
||||
|
||||
return pd.Series(ic_values, dtype=float)
|
||||
|
||||
|
||||
def compute_group_equity(
|
||||
factor_df: pd.DataFrame, return_df: pd.DataFrame, n_groups: int
|
||||
) -> pd.DataFrame:
|
||||
"""Layered backtest: rank by factor value daily, hold equal-weight, compute cumulative NAV.
|
||||
|
||||
Args:
|
||||
factor_df: Factor values; index=date, columns=codes.
|
||||
return_df: Returns; index=date, columns=codes.
|
||||
n_groups: Number of quantile groups.
|
||||
|
||||
Returns:
|
||||
DataFrame with index=date and columns Group_1 ... Group_N holding cumulative NAV.
|
||||
"""
|
||||
common_dates = sorted(factor_df.index.intersection(return_df.index))
|
||||
common_codes = factor_df.columns.intersection(return_df.columns)
|
||||
if len(common_dates) == 0 or len(common_codes) == 0:
|
||||
return pd.DataFrame()
|
||||
|
||||
factor_df = factor_df.loc[common_dates, common_codes]
|
||||
return_df = return_df.loc[common_dates, common_codes]
|
||||
|
||||
group_returns: dict[str, list[float]] = {f"Group_{i+1}": [] for i in range(n_groups)}
|
||||
valid_dates = []
|
||||
|
||||
for date in common_dates:
|
||||
f = factor_df.loc[date].dropna()
|
||||
r = return_df.loc[date].dropna()
|
||||
shared = f.index.intersection(r.index)
|
||||
if len(shared) < n_groups:
|
||||
continue
|
||||
valid_dates.append(date)
|
||||
ranked = f[shared].rank(method="first")
|
||||
bins = pd.qcut(ranked, n_groups, labels=False, duplicates="drop")
|
||||
if bins.nunique() < n_groups:
|
||||
# Not enough distinct values; fall back to equal-width cut
|
||||
bins = pd.cut(ranked, n_groups, labels=False)
|
||||
for g in range(n_groups):
|
||||
members = bins[bins == g].index
|
||||
if len(members) > 0:
|
||||
group_returns[f"Group_{g+1}"].append(r[members].mean())
|
||||
else:
|
||||
group_returns[f"Group_{g+1}"].append(0.0)
|
||||
|
||||
if not valid_dates:
|
||||
return pd.DataFrame()
|
||||
|
||||
ret_df = pd.DataFrame(group_returns, index=valid_dates)
|
||||
equity_df = (1 + ret_df).cumprod()
|
||||
return equity_df
|
||||
@@ -0,0 +1,411 @@
|
||||
"""Alpha registry: AST-scan zoo modules, validate metadata, lazy-import on compute.
|
||||
|
||||
Design contract (frozen — referenced by W3 zoo-porting agents):
|
||||
AlphaMeta (pydantic, ``extra="forbid", frozen=True``) — see fields below
|
||||
Registry.list(zoo=None, theme=None, universe=None) -> list[str]
|
||||
Registry.get(alpha_id) -> Alpha
|
||||
Registry.compute(alpha_id, panel) -> pd.DataFrame
|
||||
Registry.health() -> dict # {loaded, failed, errors}
|
||||
Registry.export_manifest() -> dict
|
||||
Registry.load_alpha_meta_from_py(path) -> AlphaMeta # AST, no import
|
||||
|
||||
Source of truth = ``__alpha_meta__`` dict literal in each ``zoo/<zoo>/<id>.py``.
|
||||
``_meta.yaml`` files are generated by ``export-manifest`` for external consumers
|
||||
(wiki) — not the load path. If we ever load a YAML, we use ``yaml.safe_load``
|
||||
with a 5 MB size cap.
|
||||
|
||||
Module path derivation: ``f"src.factors.zoo.{zoo_id}.{alpha_id_short}"``. Both
|
||||
``zoo_id`` and ``alpha_id_short`` must match ``^[a-z][a-z0-9_]{0,31}$``. We never
|
||||
honour a ``py_module`` field from any data file.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import ast
|
||||
import importlib
|
||||
import importlib.util
|
||||
import logging
|
||||
import re
|
||||
import sys
|
||||
import threading
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
from types import ModuleType
|
||||
from typing import Any, Literal
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
from pydantic import BaseModel, ConfigDict, Field, ValidationError
|
||||
|
||||
from src.factors.base import Alpha
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_ID_RE = re.compile(r"^[a-z][a-z0-9_]{0,31}$")
|
||||
_MAX_YAML_BYTES = 5_000_000
|
||||
_MAX_PY_BYTES = 200_000
|
||||
|
||||
Theme = Literal[
|
||||
"momentum",
|
||||
"reversal",
|
||||
"volume",
|
||||
"volatility",
|
||||
"quality",
|
||||
"value",
|
||||
"liquidity",
|
||||
"microstructure",
|
||||
"sentiment",
|
||||
"growth",
|
||||
"leverage",
|
||||
]
|
||||
|
||||
PanelColumn = Literal["open", "high", "low", "close", "volume", "vwap", "amount"]
|
||||
|
||||
Universe = Literal["equity_us", "equity_cn", "equity_hk", "crypto", "futures"]
|
||||
|
||||
|
||||
class AlphaMeta(BaseModel):
|
||||
"""Strict metadata schema; matches the ``__alpha_meta__`` dict literal."""
|
||||
|
||||
model_config = ConfigDict(extra="forbid", frozen=True)
|
||||
|
||||
id: str = Field(pattern=r"^[a-z][a-z0-9]+_[a-z0-9_]+$")
|
||||
nickname: str | None = None
|
||||
theme: list[Theme]
|
||||
formula_latex: str
|
||||
columns_required: list[PanelColumn]
|
||||
extras_required: list[str] = Field(default_factory=list)
|
||||
requires_sector: bool = False
|
||||
universe: list[Universe]
|
||||
frequency: list[str]
|
||||
decay_horizon: int = Field(ge=0, le=60)
|
||||
min_warmup_bars: int = Field(ge=0)
|
||||
notes: str = ""
|
||||
|
||||
|
||||
class SkipAlpha(Exception):
|
||||
"""Raised when an alpha's preconditions (sector, columns) are not met."""
|
||||
|
||||
|
||||
class RegistryError(Exception):
|
||||
"""Raised on registry-level configuration errors."""
|
||||
|
||||
|
||||
@dataclass(frozen=True, slots=True)
|
||||
class _LoadError:
|
||||
alpha_id: str
|
||||
reason: str
|
||||
|
||||
|
||||
def _validate_id_token(token: str, kind: str) -> None:
|
||||
if not _ID_RE.fullmatch(token):
|
||||
raise RegistryError(f"invalid {kind} {token!r}: must match {_ID_RE.pattern}")
|
||||
|
||||
|
||||
def load_alpha_meta_from_py(path: Path) -> AlphaMeta:
|
||||
"""AST-extract the ``__alpha_meta__`` dict literal from a zoo module.
|
||||
|
||||
No import is performed — purely static parsing. Raises ``RegistryError`` on
|
||||
malformed metadata.
|
||||
"""
|
||||
size = path.stat().st_size
|
||||
if size > _MAX_PY_BYTES:
|
||||
raise RegistryError(f"{path.name}: {size}B exceeds {_MAX_PY_BYTES}B cap")
|
||||
|
||||
source = path.read_text(encoding="utf-8")
|
||||
tree = ast.parse(source, filename=str(path))
|
||||
|
||||
meta_node: ast.expr | None = None
|
||||
for stmt in tree.body:
|
||||
if not isinstance(stmt, ast.Assign):
|
||||
continue
|
||||
targets = [t for t in stmt.targets if isinstance(t, ast.Name)]
|
||||
if any(t.id == "__alpha_meta__" for t in targets):
|
||||
meta_node = stmt.value
|
||||
break
|
||||
|
||||
if meta_node is None:
|
||||
raise RegistryError(f"{path.name}: __alpha_meta__ assignment not found")
|
||||
|
||||
try:
|
||||
raw = ast.literal_eval(meta_node)
|
||||
except (ValueError, SyntaxError) as exc:
|
||||
raise RegistryError(f"{path.name}: __alpha_meta__ not a literal: {exc}") from exc
|
||||
|
||||
if not isinstance(raw, dict):
|
||||
raise RegistryError(f"{path.name}: __alpha_meta__ must be dict, got {type(raw).__name__}")
|
||||
|
||||
try:
|
||||
return AlphaMeta(**raw)
|
||||
except ValidationError as exc:
|
||||
raise RegistryError(f"{path.name}: AlphaMeta validation failed: {exc}") from exc
|
||||
|
||||
|
||||
def _safe_yaml_load(path: Path) -> Any:
|
||||
"""yaml.safe_load with hard 5 MB size cap (defence in depth)."""
|
||||
import yaml # local import keeps registry import-light
|
||||
|
||||
size = path.stat().st_size
|
||||
if size > _MAX_YAML_BYTES:
|
||||
raise RegistryError(f"{path.name}: {size}B exceeds {_MAX_YAML_BYTES}B YAML cap")
|
||||
text = path.read_text(encoding="utf-8")
|
||||
return yaml.safe_load(text)
|
||||
|
||||
|
||||
def _zoo_dir_default() -> Path:
|
||||
return Path(__file__).parent / "zoo"
|
||||
|
||||
|
||||
class Registry:
|
||||
"""In-memory registry of all discoverable alphas across zoo subdirectories."""
|
||||
|
||||
def __init__(self, zoo_root: Path | None = None) -> None:
|
||||
default_root = _zoo_dir_default()
|
||||
self._zoo_root = (zoo_root or default_root).resolve()
|
||||
# When the registry points at the bundled zoo dir, modules are loaded
|
||||
# by package name (warm import cache, supports relative imports). For
|
||||
# any other zoo_root (tests, plugins) we load by file path so the
|
||||
# caller doesn't have to fiddle with sys.path.
|
||||
self._use_filesystem_loader = self._zoo_root != default_root.resolve()
|
||||
self._py_paths: dict[str, Path] = {}
|
||||
self._alphas: dict[str, Alpha] = {}
|
||||
self._load_errors: list[_LoadError] = []
|
||||
self._scan()
|
||||
|
||||
# ------------------------- scanning -------------------------
|
||||
|
||||
def _scan(self) -> None:
|
||||
if not self._zoo_root.is_dir():
|
||||
return
|
||||
for zoo_dir in sorted(self._zoo_root.iterdir()):
|
||||
if not zoo_dir.is_dir():
|
||||
continue
|
||||
zoo_id = zoo_dir.name
|
||||
if zoo_id.startswith("_") or zoo_id == "__pycache__":
|
||||
continue
|
||||
try:
|
||||
_validate_id_token(zoo_id, "zoo_id")
|
||||
except RegistryError as exc:
|
||||
self._load_errors.append(_LoadError(zoo_id, str(exc)))
|
||||
continue
|
||||
for py_file in sorted(zoo_dir.glob("*.py")):
|
||||
if py_file.name.startswith("_"):
|
||||
continue
|
||||
self._try_register(zoo_id, py_file)
|
||||
|
||||
def _try_register(self, zoo_id: str, py_file: Path) -> None:
|
||||
short_id = py_file.stem
|
||||
try:
|
||||
_validate_id_token(short_id, "alpha_id_short")
|
||||
except RegistryError as exc:
|
||||
self._load_errors.append(_LoadError(f"{zoo_id}.{short_id}", str(exc)))
|
||||
return
|
||||
|
||||
try:
|
||||
meta = load_alpha_meta_from_py(py_file)
|
||||
except RegistryError as exc:
|
||||
self._load_errors.append(_LoadError(f"{zoo_id}.{short_id}", str(exc)))
|
||||
return
|
||||
|
||||
# Cross-check: filename matches alpha id (defence vs typos)
|
||||
# id is "<zoo>_<short>" by convention; not strictly required but flagged.
|
||||
module_path = f"src.factors.zoo.{zoo_id}.{short_id}"
|
||||
alpha = Alpha(id=meta.id, zoo=zoo_id, module_path=module_path, meta=meta.model_dump())
|
||||
if alpha.id in self._alphas:
|
||||
self._load_errors.append(_LoadError(alpha.id, "duplicate alpha id"))
|
||||
return
|
||||
self._alphas[alpha.id] = alpha
|
||||
self._py_paths[alpha.id] = py_file
|
||||
|
||||
# ------------------------- public API -------------------------
|
||||
|
||||
def list(
|
||||
self,
|
||||
zoo: str | None = None,
|
||||
theme: str | None = None,
|
||||
universe: str | None = None,
|
||||
) -> list[str]:
|
||||
"""Return alpha IDs matching the (optional) filters."""
|
||||
out: list[str] = []
|
||||
for a in self._alphas.values():
|
||||
if zoo is not None and a.zoo != zoo:
|
||||
continue
|
||||
if theme is not None and theme not in a.meta.get("theme", []):
|
||||
continue
|
||||
if universe is not None and universe not in a.meta.get("universe", []):
|
||||
continue
|
||||
out.append(a.id)
|
||||
return sorted(out)
|
||||
|
||||
def get(self, alpha_id: str) -> Alpha:
|
||||
if alpha_id not in self._alphas:
|
||||
raise KeyError(f"alpha_id {alpha_id!r} not in registry")
|
||||
return self._alphas[alpha_id]
|
||||
|
||||
def get_source(self, alpha_id: str) -> str:
|
||||
"""Return the raw .py source of a registered alpha (size-capped).
|
||||
|
||||
Raises:
|
||||
KeyError: alpha_id unknown.
|
||||
RegistryError: source file exceeds ``_MAX_PY_BYTES`` or cannot be read.
|
||||
"""
|
||||
if alpha_id not in self._alphas:
|
||||
raise KeyError(f"alpha_id {alpha_id!r} not in registry")
|
||||
py_path = self._py_paths.get(alpha_id)
|
||||
if py_path is None:
|
||||
raise RegistryError(f"{alpha_id}: no source path recorded")
|
||||
try:
|
||||
size = py_path.stat().st_size
|
||||
except OSError as exc:
|
||||
raise RegistryError(f"{alpha_id}: cannot stat source: {exc}") from exc
|
||||
if size > _MAX_PY_BYTES:
|
||||
raise RegistryError(
|
||||
f"{alpha_id}: source {size}B exceeds {_MAX_PY_BYTES}B cap"
|
||||
)
|
||||
try:
|
||||
return py_path.read_text(encoding="utf-8")
|
||||
except OSError as exc:
|
||||
raise RegistryError(f"{alpha_id}: cannot read source: {exc}") from exc
|
||||
|
||||
def health(self) -> dict[str, Any]:
|
||||
return {
|
||||
"loaded": len(self._alphas),
|
||||
"failed": len(self._load_errors),
|
||||
"errors": [
|
||||
{"alpha_id": e.alpha_id, "reason": e.reason} for e in self._load_errors
|
||||
],
|
||||
}
|
||||
|
||||
def compute(self, alpha_id: str, panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Lazy-import the alpha module and run its ``compute(panel)``.
|
||||
|
||||
Raises:
|
||||
KeyError: alpha_id unknown.
|
||||
SkipAlpha: required column / sector tag absent in panel.
|
||||
RegistryError: import/compute failed or output failed sanity checks.
|
||||
"""
|
||||
alpha = self.get(alpha_id)
|
||||
meta = alpha.meta
|
||||
|
||||
missing = [c for c in meta.get("columns_required", []) if c not in panel]
|
||||
if missing:
|
||||
raise SkipAlpha(f"{alpha_id}: panel missing required columns {missing}")
|
||||
missing_extra = [c for c in meta.get("extras_required", []) if c not in panel]
|
||||
if missing_extra:
|
||||
raise SkipAlpha(f"{alpha_id}: panel missing extras {missing_extra}")
|
||||
if meta.get("requires_sector") and "sector" not in panel:
|
||||
raise SkipAlpha(f"{alpha_id}: panel missing sector tag")
|
||||
|
||||
try:
|
||||
module = self._load_module(alpha)
|
||||
except Exception as exc: # noqa: BLE001 — isolate import failure
|
||||
raise RegistryError(f"{alpha_id}: import failed: {exc}") from exc
|
||||
|
||||
compute_fn = getattr(module, "compute", None)
|
||||
if compute_fn is None:
|
||||
raise RegistryError(f"{alpha_id}: module has no compute() function")
|
||||
|
||||
try:
|
||||
result = compute_fn(panel)
|
||||
except Exception as exc: # noqa: BLE001 — isolate compute failure
|
||||
raise RegistryError(f"{alpha_id}: compute() raised: {exc}") from exc
|
||||
|
||||
return self._validate_output(alpha_id, result, panel)
|
||||
|
||||
def _load_module(self, alpha: Alpha) -> ModuleType:
|
||||
if not self._use_filesystem_loader:
|
||||
return importlib.import_module(alpha.module_path)
|
||||
py_file = self._py_paths[alpha.id]
|
||||
cached = sys.modules.get(alpha.module_path)
|
||||
if cached is not None and getattr(cached, "__file__", None) == str(py_file):
|
||||
return cached
|
||||
spec = importlib.util.spec_from_file_location(alpha.module_path, py_file)
|
||||
if spec is None or spec.loader is None:
|
||||
raise RegistryError(f"{alpha.id}: could not build import spec for {py_file}")
|
||||
module = importlib.util.module_from_spec(spec)
|
||||
sys.modules[alpha.module_path] = module
|
||||
try:
|
||||
spec.loader.exec_module(module)
|
||||
except Exception:
|
||||
sys.modules.pop(alpha.module_path, None)
|
||||
raise
|
||||
return module
|
||||
|
||||
@staticmethod
|
||||
def _validate_output(
|
||||
alpha_id: str,
|
||||
result: Any,
|
||||
panel: dict[str, pd.DataFrame],
|
||||
) -> pd.DataFrame:
|
||||
if not isinstance(result, pd.DataFrame):
|
||||
raise RegistryError(
|
||||
f"{alpha_id}: compute() returned {type(result).__name__}, expected DataFrame"
|
||||
)
|
||||
ref = panel.get("close")
|
||||
if ref is not None and result.shape != ref.shape:
|
||||
raise RegistryError(
|
||||
f"{alpha_id}: output shape {result.shape} != close shape {ref.shape}"
|
||||
)
|
||||
arr = result.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
if np.isinf(arr).any():
|
||||
raise RegistryError(f"{alpha_id}: output contains +/- inf")
|
||||
nan_ratio = float(np.isnan(arr).mean()) if arr.size > 0 else 1.0
|
||||
if nan_ratio > 0.95:
|
||||
raise RegistryError(f"{alpha_id}: output >95% NaN (nan_ratio={nan_ratio:.3f})")
|
||||
return result
|
||||
|
||||
def export_manifest(self) -> dict[str, Any]:
|
||||
"""Return a JSON-serialisable snapshot for wiki rendering."""
|
||||
from datetime import datetime, timezone
|
||||
|
||||
zoos: dict[str, list[dict[str, Any]]] = {}
|
||||
for a in self._alphas.values():
|
||||
zoos.setdefault(a.zoo, []).append(
|
||||
{
|
||||
"id": a.id,
|
||||
"module_path": a.module_path,
|
||||
"meta": a.meta,
|
||||
}
|
||||
)
|
||||
return {
|
||||
"generated_at": datetime.now(timezone.utc).isoformat(),
|
||||
"zoos": [
|
||||
{"zoo_id": zoo_id, "alphas": sorted(items, key=lambda x: x["id"])}
|
||||
for zoo_id, items in sorted(zoos.items())
|
||||
],
|
||||
"health": self.health(),
|
||||
}
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Process-wide singleton for hot paths (API, bench tool).
|
||||
#
|
||||
# Building a Registry() scans ~450 .py files via AST. Doing that on every API
|
||||
# request is wasteful — the bundled zoo never changes inside a single process.
|
||||
# Callers that need a custom zoo_root (tests, plugins) should keep instantiating
|
||||
# Registry() directly; the singleton is only for the default bundled zoo.
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
_registry_cache: "Registry | None" = None
|
||||
_registry_cache_lock = threading.Lock()
|
||||
|
||||
|
||||
def get_default_registry() -> Registry:
|
||||
"""Return a process-wide cached ``Registry`` for the bundled zoo.
|
||||
|
||||
Thread-safe. First call builds and caches; subsequent calls return the same
|
||||
instance. Use this on hot paths (API handlers, bench tool); use
|
||||
``Registry()`` directly when you need a custom ``zoo_root``.
|
||||
"""
|
||||
global _registry_cache
|
||||
with _registry_cache_lock:
|
||||
if _registry_cache is None:
|
||||
_registry_cache = Registry()
|
||||
return _registry_cache
|
||||
|
||||
|
||||
def reset_default_registry() -> None:
|
||||
"""Drop the cached registry (test hook; do not call in production)."""
|
||||
global _registry_cache
|
||||
with _registry_cache_lock:
|
||||
_registry_cache = None
|
||||
Whitespace-only changes.
@@ -0,0 +1,64 @@
|
||||
# Academic Baseline Factors — Attributions and Stance
|
||||
|
||||
This subdirectory contains price-based proxies for the canonical academic
|
||||
factor portfolios used as long-short benchmarks in the empirical
|
||||
asset-pricing literature. None of the original papers' prose is reproduced
|
||||
here.
|
||||
|
||||
## Source attributions
|
||||
|
||||
- Sharpe, W. F. (1964). "Capital Asset Prices: A Theory of Market
|
||||
Equilibrium under Conditions of Risk." *The Journal of Finance*,
|
||||
19(3), 425-442. — market factor (MKT-RF).
|
||||
- Fama, E. F., & French, K. R. (1993). "Common risk factors in the
|
||||
returns on stocks and bonds." *Journal of Financial Economics*,
|
||||
33(1), 3-56. — SMB (size) and HML (value).
|
||||
- Carhart, M. M. (1997). "On persistence in mutual fund performance."
|
||||
*The Journal of Finance*, 52(1), 57-82. — UMD (momentum).
|
||||
- Fama, E. F., & French, K. R. (2015). "A five-factor asset pricing
|
||||
model." *Journal of Financial Economics*, 116(1), 1-22. — RMW
|
||||
(profitability) and CMA (investment).
|
||||
- Hou, K., Xue, C., & Zhang, L. (2015). "Digesting anomalies: An
|
||||
investment approach." *Review of Financial Studies*, 28(3), 650-705.
|
||||
— Q-factor model (referenced for completeness; not implemented
|
||||
separately because the investment and profitability legs overlap
|
||||
with RMW / CMA in our OHLCV-only setting).
|
||||
|
||||
## Disclosure: these are price-based proxies, not the original factors
|
||||
|
||||
The implementations in this directory use only OHLCV panel inputs.
|
||||
The original factor portfolios use fundamental data (book equity,
|
||||
operating profitability, asset growth) that we do not carry in the
|
||||
panel. We therefore replace each fundamental input with a price- or
|
||||
volume-derived proxy:
|
||||
|
||||
- MKT-RF: 21-day per-stock total return (vs. value-weighted excess
|
||||
market return in the original).
|
||||
- SMB: negative log of 60-day average dollar volume (vs. market
|
||||
capitalization in the original).
|
||||
- HML: negative 252-day return (vs. book-to-market sort in the
|
||||
original).
|
||||
- RMW: negative 60-day return volatility (vs. operating profitability
|
||||
sort in the original).
|
||||
- CMA: negative 60-day change in log average volume (vs. asset-growth
|
||||
sort in the original).
|
||||
- Carhart UMD: 12-month minus 1-month return (matches the original
|
||||
construction; cross-sectional z-score added for ranking).
|
||||
|
||||
Each module's `notes` field repeats this disclosure inline. Users
|
||||
backtesting these factors as research-grade replacements for the
|
||||
published series should obtain the authoritative monthly return series
|
||||
from Kenneth French's data library:
|
||||
|
||||
https://mba.tuck.dartmouth.edu/pages/faculty/ken.french/data_library.html
|
||||
|
||||
We link to that resource and do not copy any of its data files.
|
||||
|
||||
## Stance on factor definitions
|
||||
|
||||
Factor definitions are mathematical / academic concepts and are not
|
||||
copyrightable. We re-state each factor as a cross-sectional ranking
|
||||
signal in our own words and our own code. None of the original papers'
|
||||
prose, tables, or figures is reproduced. The Kenneth French data
|
||||
library's return series are owned by their authors and remain
|
||||
externally hosted.
|
||||
Whitespace-only changes.
@@ -0,0 +1,59 @@
|
||||
"""academic Carhart momentum: 12-month return excluding the most recent month.
|
||||
|
||||
Reference:
|
||||
Carhart, M. M. (1997). "On persistence in mutual fund performance."
|
||||
The Journal of Finance, 52(1), 57-82.
|
||||
|
||||
This is the canonical UMD (Up Minus Down) momentum factor: trailing 12-month
|
||||
return less the most recent month, capturing intermediate-term momentum while
|
||||
avoiding short-term reversal contamination. Computed directly from prices —
|
||||
no fundamental data required — so this matches the original construction
|
||||
modulo the cross-sectional z-score wrapper used for long-short ranking.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import delta, safe_div
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'academic_carhart_mom',
|
||||
'nickname': 'Carhart 1997 momentum — 12m-1m return',
|
||||
'theme': ['momentum'],
|
||||
'formula_latex': r'\mathrm{zscore}_{x}\bigl((\mathrm{close}_t - \mathrm{close}_{t-252})/\mathrm{close}_{t-252} - (\mathrm{close}_t - \mathrm{close}_{t-21})/\mathrm{close}_{t-21}\bigr)',
|
||||
'columns_required': ['close'],
|
||||
'universe': ['equity_us', 'equity_cn', 'equity_hk'],
|
||||
'frequency': ['1d'],
|
||||
'decay_horizon': 60,
|
||||
'min_warmup_bars': 252,
|
||||
'notes': (
|
||||
'Carhart (1997) UMD momentum factor. 12-month return minus 1-month return, '
|
||||
'cross-sectional z-score per date for long-short ranking. Top z-scores = '
|
||||
'winners. Constructed directly from prices, so this matches the original '
|
||||
'definition modulo the z-score wrapper. Canonical 252d window; declared '
|
||||
'decay_horizon=60 due to registry schema cap (le=60); real signal horizon=252.'
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _cross_sectional_zscore(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Per-row z-score: (x - row_mean) / row_std; zero/NaN std rows -> NaN."""
|
||||
mean = df.mean(axis=1, skipna=True)
|
||||
std = df.std(axis=1, ddof=1, skipna=True)
|
||||
centered = df.sub(mean, axis=0)
|
||||
result = centered.div(std.where(std > 0), axis=0)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def compute(panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Return 252-day minus 21-day return z-score (Carhart UMD).
|
||||
|
||||
Uses canonical (252, 21) windows without silent shrink on short panels.
|
||||
Short panels produce all-NaN; the registry surfaces this as >95% NaN
|
||||
(RegistryError) rather than returning a misleading shrunk-window value.
|
||||
"""
|
||||
close = panel['close']
|
||||
ret_long = safe_div(delta(close, 252), close.shift(252))
|
||||
ret_short = safe_div(delta(close, 21), close.shift(21))
|
||||
return _cross_sectional_zscore(ret_long - ret_short)
|
||||
@@ -0,0 +1,61 @@
|
||||
"""academic CMA: investment factor as inverse 60-day volume growth.
|
||||
|
||||
Reference:
|
||||
Fama, E. F., & French, K. R. (2015). "A five-factor asset pricing model."
|
||||
Journal of Financial Economics, 116(1), 1-22.
|
||||
|
||||
This is a price-based proxy: the original CMA (Conservative Minus Aggressive)
|
||||
sorts on asset growth from balance-sheet data. We use the negative of 60-day
|
||||
log-volume change — firms aggressively scaling activity tend to show rising
|
||||
trading volume; conservative firms show stable / shrinking volume. Higher
|
||||
z-scores = volume contraction (conservative).
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import delta, ts_mean
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'academic_cma',
|
||||
'nickname': '[PRICE PROXY] FF2015 CMA — investment via inverse volume growth',
|
||||
'theme': ['quality'],
|
||||
'formula_latex': r'\mathrm{zscore}_{x}\bigl(-\Delta_{60}\log(\mathrm{ts\_mean}(\mathrm{volume},\,60) + 1)\bigr)',
|
||||
'columns_required': ['volume'],
|
||||
'universe': ['equity_us', 'equity_cn', 'equity_hk'],
|
||||
'frequency': ['1d'],
|
||||
'decay_horizon': 60,
|
||||
'min_warmup_bars': 120,
|
||||
'notes': (
|
||||
'[PRICE PROXY] for the Fama-French (2015) CMA (Conservative Minus '
|
||||
'Aggressive) investment factor. The original definition uses total-asset '
|
||||
'growth from fundamental data; here we use the negative 60-day change in '
|
||||
'log average volume as an activity-growth proxy, then cross-sectional '
|
||||
'z-score per date for long-short ranking. Top z-scores = volume contraction '
|
||||
'(conservative / low-growth proxy).'
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _cross_sectional_zscore(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Per-row z-score: (x - row_mean) / row_std; zero/NaN std rows -> NaN."""
|
||||
mean = df.mean(axis=1, skipna=True)
|
||||
std = df.std(axis=1, ddof=1, skipna=True)
|
||||
centered = df.sub(mean, axis=0)
|
||||
result = centered.div(std.where(std > 0), axis=0)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def compute(panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Return inverse 60-day log-volume change z-score per stock.
|
||||
|
||||
Uses the canonical 60-bar rolling mean + 60-bar delta windows without
|
||||
silent shrink on short panels. Short panels produce all-NaN; the
|
||||
registry surfaces this as >95% NaN (RegistryError) so the user sees
|
||||
"insufficient history" rather than a misleading shrunk-window value.
|
||||
"""
|
||||
volume = panel['volume']
|
||||
log_avg_vol = np.log(ts_mean(volume, 60) + 1.0)
|
||||
growth = delta(log_avg_vol, 60)
|
||||
return _cross_sectional_zscore(-growth)
|
||||
@@ -0,0 +1,60 @@
|
||||
"""academic HML: value factor as inverse 252-day return (long-term reversal proxy).
|
||||
|
||||
Reference:
|
||||
Fama, E. F., & French, K. R. (1993). "Common risk factors in the returns on
|
||||
stocks and bonds." Journal of Financial Economics, 33(1), 3-56.
|
||||
|
||||
This is a price-based proxy: the original HML (High Minus Low) sorts on book-
|
||||
to-market, which requires fundamental book equity. We use the negative of the
|
||||
trailing 252-day return — value names tend to be long-term underperformers
|
||||
whose prices have declined relative to book value. Higher z-scores = larger
|
||||
long-term drawdowns (deeper value).
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import delta, safe_div
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'academic_hml',
|
||||
'nickname': '[PRICE PROXY] FF1993 HML — value via inverse 252d return',
|
||||
'theme': ['value'],
|
||||
'formula_latex': r'\mathrm{zscore}_{x}\bigl(-(\mathrm{close}_t - \mathrm{close}_{t-252}) / \mathrm{close}_{t-252}\bigr)',
|
||||
'columns_required': ['close'],
|
||||
'universe': ['equity_us', 'equity_cn', 'equity_hk'],
|
||||
'frequency': ['1d'],
|
||||
'decay_horizon': 60,
|
||||
'min_warmup_bars': 252,
|
||||
'notes': (
|
||||
'[PRICE PROXY] for the Fama-French (1993) HML (High Minus Low) value factor. '
|
||||
'The original definition uses book-to-market ratio from fundamental data; here '
|
||||
'we use the negative 252-day total return as a long-term reversal proxy, then '
|
||||
'cross-sectional z-score per date for long-short ranking. Top z-scores = '
|
||||
'long-term underperformers (deeper value). Canonical 252d window; declared '
|
||||
'decay_horizon=60 due to registry schema cap (le=60); real signal horizon=252.'
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _cross_sectional_zscore(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Per-row z-score: (x - row_mean) / row_std; zero/NaN std rows -> NaN."""
|
||||
mean = df.mean(axis=1, skipna=True)
|
||||
std = df.std(axis=1, ddof=1, skipna=True)
|
||||
centered = df.sub(mean, axis=0)
|
||||
result = centered.div(std.where(std > 0), axis=0)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def compute(panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Return inverse 252-day return cross-sectional z-score per stock.
|
||||
|
||||
Uses the canonical 252-day window without silent shrink on short panels.
|
||||
Short panels produce an all-NaN result, which the registry surfaces as a
|
||||
>95% NaN error (RegistryError) so the user sees "insufficient history"
|
||||
instead of a misleading shrunk-window value.
|
||||
"""
|
||||
close = panel['close']
|
||||
ret = safe_div(delta(close, 252), close.shift(252))
|
||||
return _cross_sectional_zscore(-ret)
|
||||
@@ -0,0 +1,53 @@
|
||||
"""academic MKT_RF: market factor as 21-day return, cross-sectionally z-scored.
|
||||
|
||||
Reference:
|
||||
Sharpe, W. F. (1964). "Capital Asset Prices: A Theory of Market Equilibrium
|
||||
under Conditions of Risk." The Journal of Finance, 19(3), 425-442.
|
||||
|
||||
This is a price-based proxy: the original CAPM market factor is the
|
||||
value-weighted excess return of the market portfolio. We approximate the
|
||||
per-stock market-factor exposure as the 21-day total return cross-sectionally
|
||||
z-scored, suitable for ranking long-short portfolios.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import delta, safe_div
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'academic_mkt_rf',
|
||||
'nickname': '[PRICE PROXY] Market factor (Sharpe 1964) — 21d demeaned return',
|
||||
'theme': ['momentum'],
|
||||
'formula_latex': r'\mathrm{zscore}_{x}\bigl((\mathrm{close}_t - \mathrm{close}_{t-21}) / \mathrm{close}_{t-21}\bigr)',
|
||||
'columns_required': ['close'],
|
||||
'universe': ['equity_us', 'equity_cn', 'equity_hk'],
|
||||
'frequency': ['1d'],
|
||||
'decay_horizon': 21,
|
||||
'min_warmup_bars': 21,
|
||||
'notes': (
|
||||
'[PRICE PROXY] for the Sharpe (1964) / Fama-French market factor (MKT-RF). '
|
||||
'The original definition uses value-weighted market excess returns; here we '
|
||||
'use a 21-day per-stock total return and cross-sectional z-score per date '
|
||||
'for long-short ranking. Top z-scores = strong recent winners; bottom = losers.'
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _cross_sectional_zscore(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Per-row z-score: (x - row_mean) / row_std; zero/NaN std rows -> NaN."""
|
||||
mean = df.mean(axis=1, skipna=True)
|
||||
std = df.std(axis=1, ddof=1, skipna=True)
|
||||
centered = df.sub(mean, axis=0)
|
||||
# std.where(std > 0) turns 0 / NaN std rows into NaN, which propagates
|
||||
# through div to NaN — no silent inf.
|
||||
result = centered.div(std.where(std > 0), axis=0)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def compute(panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Return 21-day return cross-sectional z-score per stock."""
|
||||
close = panel['close']
|
||||
ret = safe_div(delta(close, 21), close.shift(21))
|
||||
return _cross_sectional_zscore(ret)
|
||||
@@ -0,0 +1,54 @@
|
||||
"""academic RMW: profitability factor as inverse 60-day return volatility.
|
||||
|
||||
Reference:
|
||||
Fama, E. F., & French, K. R. (2015). "A five-factor asset pricing model."
|
||||
Journal of Financial Economics, 116(1), 1-22.
|
||||
|
||||
This is a price-based proxy: the original RMW (Robust Minus Weak) sorts on
|
||||
operating profitability from income statements. We use the negative of trailing
|
||||
60-day realized return volatility — robust (profitable) firms historically
|
||||
exhibit lower idiosyncratic volatility (the "low-vol anomaly" overlap). Higher
|
||||
z-scores = lower volatility = quality proxy.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import delta, safe_div, ts_std
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'academic_rmw',
|
||||
'nickname': '[PRICE PROXY] FF2015 RMW — quality via inverse 60d volatility',
|
||||
'theme': ['quality'],
|
||||
'formula_latex': r'\mathrm{zscore}_{x}\bigl(-\mathrm{ts\_std}((\mathrm{close}_t - \mathrm{close}_{t-1}) / \mathrm{close}_{t-1},\,60)\bigr)',
|
||||
'columns_required': ['close'],
|
||||
'universe': ['equity_us', 'equity_cn', 'equity_hk'],
|
||||
'frequency': ['1d'],
|
||||
'decay_horizon': 60,
|
||||
'min_warmup_bars': 60,
|
||||
'notes': (
|
||||
'[PRICE PROXY] for the Fama-French (2015) RMW (Robust Minus Weak) '
|
||||
'profitability factor. The original definition uses operating profitability '
|
||||
'from fundamental data; here we use the negative of 60-day return volatility '
|
||||
'as a low-vol-quality proxy, then cross-sectional z-score per date for '
|
||||
'long-short ranking. Top z-scores = lower vol (quality / robust).'
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _cross_sectional_zscore(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Per-row z-score: (x - row_mean) / row_std; zero/NaN std rows -> NaN."""
|
||||
mean = df.mean(axis=1, skipna=True)
|
||||
std = df.std(axis=1, ddof=1, skipna=True)
|
||||
centered = df.sub(mean, axis=0)
|
||||
result = centered.div(std.where(std > 0), axis=0)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def compute(panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Return inverse 60-day return-volatility z-score per stock."""
|
||||
close = panel['close']
|
||||
ret_1d = safe_div(delta(close, 1), close.shift(1))
|
||||
vol_60 = ts_std(ret_1d, 60)
|
||||
return _cross_sectional_zscore(-vol_60)
|
||||
@@ -0,0 +1,55 @@
|
||||
"""academic SMB: size factor as inverse log of 60-day average dollar volume.
|
||||
|
||||
Reference:
|
||||
Fama, E. F., & French, K. R. (1993). "Common risk factors in the returns on
|
||||
stocks and bonds." Journal of Financial Economics, 33(1), 3-56.
|
||||
|
||||
This is a price-based proxy: the original SMB (Small Minus Big) sorts on market
|
||||
capitalization, which we do not carry in the OHLCV panel. We use average daily
|
||||
dollar volume (close * volume) as a liquidity-weighted size proxy — small caps
|
||||
typically have low dollar volume. Higher z-scores = smaller (illiquid) names.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import ts_mean
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'academic_smb',
|
||||
'nickname': '[PRICE PROXY] FF1993 SMB — small-minus-big via inverse dollar-volume',
|
||||
'theme': ['quality'],
|
||||
'formula_latex': r'\mathrm{zscore}_{x}\bigl(-\log(\mathrm{ts\_mean}(\mathrm{volume} \cdot \mathrm{close},\,60) + 1)\bigr)',
|
||||
'columns_required': ['close', 'volume'],
|
||||
'universe': ['equity_us', 'equity_cn', 'equity_hk'],
|
||||
'frequency': ['1d'],
|
||||
'decay_horizon': 60,
|
||||
'min_warmup_bars': 60,
|
||||
'notes': (
|
||||
'[PRICE PROXY] for the Fama-French (1993) SMB (Small Minus Big) size factor. '
|
||||
'The original definition uses market capitalization from book equity data; here '
|
||||
'we use the negative log of 60-day average dollar volume (close * volume) as a '
|
||||
'liquidity-weighted size proxy, then cross-sectional z-score per date for '
|
||||
'long-short ranking. Top z-scores = smaller / less liquid names.'
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _cross_sectional_zscore(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Per-row z-score: (x - row_mean) / row_std; zero/NaN std rows -> NaN."""
|
||||
mean = df.mean(axis=1, skipna=True)
|
||||
std = df.std(axis=1, ddof=1, skipna=True)
|
||||
centered = df.sub(mean, axis=0)
|
||||
result = centered.div(std.where(std > 0), axis=0)
|
||||
return result.replace([np.inf, -np.inf], np.nan)
|
||||
|
||||
|
||||
def compute(panel: dict[str, pd.DataFrame]) -> pd.DataFrame:
|
||||
"""Return inverse log 60-day dollar-volume z-score per stock."""
|
||||
close = panel['close']
|
||||
volume = panel['volume']
|
||||
dollar_volume = volume * close
|
||||
avg = ts_mean(dollar_volume, 60)
|
||||
log_size = np.log(avg + 1.0)
|
||||
return _cross_sectional_zscore(-log_size)
|
||||
@@ -0,0 +1,80 @@
|
||||
# Kakushadze 101 Formulaic Alphas — License & Provenance
|
||||
|
||||
## Display Name
|
||||
|
||||
**Kakushadze 101 Formulaic Alphas**
|
||||
|
||||
This is the display name used throughout the Vibe-Trading codebase, manifests,
|
||||
wiki, and documentation when referring to the 101 alphas implemented under
|
||||
`agent/src/factors/zoo/alpha101/`. No other branding is used.
|
||||
|
||||
## Source
|
||||
|
||||
* **Paper**: Z. Kakushadze, *"101 Formulaic Alphas"*, 2015.
|
||||
* **arXiv**: <https://arxiv.org/abs/1601.00991>
|
||||
* **DOI**: 10.48550/arXiv.1601.00991
|
||||
* **License of the paper**: arXiv non-exclusive distribution license; the
|
||||
formulas themselves are presented as mathematical artifacts.
|
||||
|
||||
## What we reproduce
|
||||
|
||||
This subdirectory contains 101 standalone Python modules, one per alpha,
|
||||
each implementing the formula given in the appendix of Kakushadze (2015) on
|
||||
top of the operator surface in `agent/src/factors/base.py`. The
|
||||
implementations were written from scratch against the formula table; we
|
||||
did not copy or port source code from any third-party implementation.
|
||||
|
||||
## What we do NOT reproduce
|
||||
|
||||
* No prose, figures, tables, or discussion from the paper is included in
|
||||
this repository.
|
||||
* No commentary on alpha behaviour, holding periods, or empirical
|
||||
performance is reproduced verbatim.
|
||||
* The string commonly associated with the firm of one of the paper's
|
||||
author affiliations **does not appear anywhere in this repository**;
|
||||
the CI gate `tools/ci_grep_gates.sh` enforces this.
|
||||
|
||||
## Trademark / Naming Stance
|
||||
|
||||
Mathematical formulas are not subject to copyright. The formulas as listed
|
||||
in the paper appendix are facts about real-valued functions of OHLCV data
|
||||
and are reproducible by anyone with access to the paper. The choice of
|
||||
display name **"Kakushadze 101 Formulaic Alphas"** credits the paper
|
||||
author and avoids any trademark that may be associated with the
|
||||
institutional affiliation of the work.
|
||||
|
||||
If you redistribute this subdirectory, please:
|
||||
|
||||
1. Keep the arXiv citation intact in each module docstring.
|
||||
2. Keep the display name as **"Kakushadze 101 Formulaic Alphas"**.
|
||||
3. Do not introduce trademark strings that this project deliberately
|
||||
avoids (see CI gate `(b)` in `tools/ci_grep_gates.sh`).
|
||||
|
||||
## Numerical Cross-Validation
|
||||
|
||||
Public reference implementations of these formulas exist (for example
|
||||
Menooker/KunQuant on GitHub). We used those only as a numerical sanity
|
||||
check on small synthetic panels — never as a source of code. No file in
|
||||
this subdirectory was copied, adapted, or text-spliced from a third-party
|
||||
implementation; the Python code here is original and was generated from
|
||||
the formula table by a deterministic templating step (the template
|
||||
generator script is not retained in the published source tree).
|
||||
|
||||
## Implementation Notes
|
||||
|
||||
* The standard panel exposes `open`, `high`, `low`, `close`, `volume`,
|
||||
`vwap`, and (optionally) `amount` and `sector`. Where the paper formula
|
||||
references `cap` (market capitalisation) or `IndClass.industry /
|
||||
subindustry / sector`, we either substitute a degraded value or gate
|
||||
the alpha behind `requires_sector=True`; the per-alpha `notes` field
|
||||
in `__alpha_meta__` records each such degradation.
|
||||
* `delta(x, d)` is restricted to `d >= 1` (no negative-shift forms). The
|
||||
paper's formulas use only positive lags so this is a no-op constraint.
|
||||
* The `delay(x, n)` helper (`x.shift(n)` with `n >= 1`) is implemented
|
||||
inside each alpha module as a small private function rather than
|
||||
imported from `src.factors.base` to keep the public operator surface
|
||||
small.
|
||||
|
||||
## Contact
|
||||
|
||||
Vibe-Trading project — <https://github.com/HKUDS/Vibe-Trading>
|
||||
Whitespace-only changes.
@@ -0,0 +1,58 @@
|
||||
"""Kakushadze Alpha #1.
|
||||
|
||||
Formula (paper appendix): rank(ts_argmax(SignedPower((returns<0)?stddev(returns,20):close, 2.), 5)) - 0.5
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 1.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_001"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_001',
|
||||
'nickname': 'Kakushadze Alpha #1',
|
||||
'theme': ['reversal', 'volatility'],
|
||||
'formula_latex': 'rank(ts_argmax(SignedPower((returns<0)?stddev(returns,20):close, 2.), 5)) - 0.5',
|
||||
'columns_required': ['close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 25,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
|
||||
|
||||
returns = close.pct_change()
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
cond = (returns < 0).astype(float)
|
||||
x = ts_std(returns, 20) * cond + close * (1.0 - cond)
|
||||
out = rank(ts_argmax(signed_power(x, 2.0), 5)) - 0.5
|
||||
return out
|
||||
@@ -0,0 +1,57 @@
|
||||
"""Kakushadze Alpha #2.
|
||||
|
||||
Formula (paper appendix): -1 * correlation(rank(delta(log(volume), 2)), rank(((close-open)/open)), 6)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 2.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_002"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_002',
|
||||
'nickname': 'Kakushadze Alpha #2',
|
||||
'theme': ['volume', 'reversal'],
|
||||
'formula_latex': '-1 * correlation(rank(delta(log(volume), 2)), rank(((close-open)/open)), 6)',
|
||||
'columns_required': ['open', 'close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 10,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
open_ = panel["open"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * ts_corr(rank(delta(np.log(volume), 2)), rank((close - open_) / open_), 6)
|
||||
return out
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Kakushadze Alpha #3.
|
||||
|
||||
Formula (paper appendix): -1 * correlation(rank(open), rank(volume), 10)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 3.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_003"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_003',
|
||||
'nickname': 'Kakushadze Alpha #3',
|
||||
'theme': ['volume', 'reversal'],
|
||||
'formula_latex': '-1 * correlation(rank(open), rank(volume), 10)',
|
||||
'columns_required': ['open', 'volume', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 10,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
open_ = panel["open"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * ts_corr(rank(open_), rank(volume), 10)
|
||||
return out
|
||||
@@ -0,0 +1,55 @@
|
||||
"""Kakushadze Alpha #4.
|
||||
|
||||
Formula (paper appendix): -1 * Ts_Rank(rank(low), 9)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 4.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_004"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_004',
|
||||
'nickname': 'Kakushadze Alpha #4',
|
||||
'theme': ['reversal'],
|
||||
'formula_latex': '-1 * Ts_Rank(rank(low), 9)',
|
||||
'columns_required': ['low', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 9,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
low = panel["low"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * ts_rank(rank(low), 9)
|
||||
return out
|
||||
@@ -0,0 +1,63 @@
|
||||
"""Kakushadze Alpha #5.
|
||||
|
||||
Formula (paper appendix): rank((open - sum(vwap,10)/10)) * (-1 * abs(rank((close - vwap))))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 5.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_005"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_005',
|
||||
'nickname': 'Kakushadze Alpha #5',
|
||||
'theme': ['reversal'],
|
||||
'formula_latex': 'rank((open - sum(vwap,10)/10)) * (-1 * abs(rank((close - vwap))))',
|
||||
'columns_required': ['open', 'close', 'vwap'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 10,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _rolling_sum(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling window sum; warmup -> NaN."""
|
||||
return df.rolling(window=n, min_periods=n).sum()
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
open_ = panel["open"]
|
||||
vwap = panel["vwap"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
rolling_sum = _rolling_sum
|
||||
out = rank(open_ - rolling_sum(vwap, 10) / 10.0) * (-1.0 * rank(close - vwap).abs())
|
||||
return out
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Kakushadze Alpha #6.
|
||||
|
||||
Formula (paper appendix): -1 * correlation(open, volume, 10)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 6.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_006"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_006',
|
||||
'nickname': 'Kakushadze Alpha #6',
|
||||
'theme': ['volume', 'reversal'],
|
||||
'formula_latex': '-1 * correlation(open, volume, 10)',
|
||||
'columns_required': ['open', 'volume', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 10,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
open_ = panel["open"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * ts_corr(open_, volume, 10)
|
||||
return out
|
||||
@@ -0,0 +1,86 @@
|
||||
"""Kakushadze Alpha #7.
|
||||
|
||||
Formula (paper appendix): (adv20<volume)?((-1*ts_rank(abs(delta(close,7)),60))*sign(delta(close,7))):(-1)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 7.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_007"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_007',
|
||||
'nickname': 'Kakushadze Alpha #7',
|
||||
'theme': ['momentum', 'volume'],
|
||||
'formula_latex': '(adv20<volume)?((-1*ts_rank(abs(delta(close,7)),60))*sign(delta(close,7))):(-1)',
|
||||
'columns_required': ['close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 67,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _make_one(ref: pd.DataFrame) -> pd.DataFrame:
|
||||
"""A DataFrame of 1.0 with the same shape/index/columns as ``ref``."""
|
||||
return pd.DataFrame(1.0, index=ref.index, columns=ref.columns)
|
||||
|
||||
|
||||
def _where_ternary(cond, a, b):
|
||||
"""Vectorised ternary `(cond ? a : b)` returning a DataFrame.
|
||||
|
||||
``cond`` is a boolean DataFrame; ``a`` / ``b`` may be DataFrame or scalar.
|
||||
"""
|
||||
if isinstance(a, (int, float)):
|
||||
a_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(a))
|
||||
else:
|
||||
a_arr = a.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
if isinstance(b, (int, float)):
|
||||
b_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(b))
|
||||
else:
|
||||
b_arr = b.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
cond_arr = cond.to_numpy(dtype=bool, na_value=False) if hasattr(cond, "to_numpy") else np.asarray(cond, dtype=bool)
|
||||
out = np.where(cond_arr, a_arr, b_arr)
|
||||
out = np.where(np.isfinite(out), out, np.nan)
|
||||
idx = cond.index if hasattr(cond, "index") else a.index
|
||||
cols = cond.columns if hasattr(cond, "columns") else a.columns
|
||||
return pd.DataFrame(out, index=idx, columns=cols)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
volume = panel["volume"]
|
||||
adv20 = ts_mean(volume, 20)
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
make_one = _make_one
|
||||
where_ternary = _where_ternary
|
||||
d7 = delta(close, 7)
|
||||
expr = (-1.0 * ts_rank(d7.abs(), 60)) * np.sign(d7)
|
||||
out = where_ternary(adv20 < volume, expr, -1.0 * make_one(close))
|
||||
return out
|
||||
@@ -0,0 +1,71 @@
|
||||
"""Kakushadze Alpha #8.
|
||||
|
||||
Formula (paper appendix): -1 * rank((sum(open,5)*sum(returns,5)) - delay(sum(open,5)*sum(returns,5),10))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 8.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_008"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_008',
|
||||
'nickname': 'Kakushadze Alpha #8',
|
||||
'theme': ['reversal'],
|
||||
'formula_latex': '-1 * rank((sum(open,5)*sum(returns,5)) - delay(sum(open,5)*sum(returns,5),10))',
|
||||
'columns_required': ['open', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 15,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _rolling_sum(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling window sum; warmup -> NaN."""
|
||||
return df.rolling(window=n, min_periods=n).sum()
|
||||
|
||||
|
||||
def _delay(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Backward shift by n (lookahead-safe; n>=1 required)."""
|
||||
if n < 1:
|
||||
raise ValueError("delay requires n >= 1 (lookahead ban)")
|
||||
return df.shift(n)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
open_ = panel["open"]
|
||||
|
||||
returns = close.pct_change()
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
rolling_sum = _rolling_sum
|
||||
delay = _delay
|
||||
s = rolling_sum(open_, 5) * rolling_sum(returns, 5)
|
||||
out = -1.0 * rank(s - delay(s, 10))
|
||||
return out
|
||||
@@ -0,0 +1,80 @@
|
||||
"""Kakushadze Alpha #9.
|
||||
|
||||
Formula (paper appendix): (0<ts_min(delta(close,1),5))?delta(close,1):((ts_max(delta(close,1),5)<0)?delta(close,1):(-1*delta(close,1)))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 9.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_009"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_009',
|
||||
'nickname': 'Kakushadze Alpha #9',
|
||||
'theme': ['momentum'],
|
||||
'formula_latex': '(0<ts_min(delta(close,1),5))?delta(close,1):((ts_max(delta(close,1),5)<0)?delta(close,1):(-1*delta(close,1)))',
|
||||
'columns_required': ['close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 6,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _where_ternary(cond, a, b):
|
||||
"""Vectorised ternary `(cond ? a : b)` returning a DataFrame.
|
||||
|
||||
``cond`` is a boolean DataFrame; ``a`` / ``b`` may be DataFrame or scalar.
|
||||
"""
|
||||
if isinstance(a, (int, float)):
|
||||
a_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(a))
|
||||
else:
|
||||
a_arr = a.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
if isinstance(b, (int, float)):
|
||||
b_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(b))
|
||||
else:
|
||||
b_arr = b.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
cond_arr = cond.to_numpy(dtype=bool, na_value=False) if hasattr(cond, "to_numpy") else np.asarray(cond, dtype=bool)
|
||||
out = np.where(cond_arr, a_arr, b_arr)
|
||||
out = np.where(np.isfinite(out), out, np.nan)
|
||||
idx = cond.index if hasattr(cond, "index") else a.index
|
||||
cols = cond.columns if hasattr(cond, "columns") else a.columns
|
||||
return pd.DataFrame(out, index=idx, columns=cols)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
where_ternary = _where_ternary
|
||||
d1 = delta(close, 1)
|
||||
cond1 = ts_min(d1, 5) > 0
|
||||
cond2 = ts_max(d1, 5) < 0
|
||||
out = where_ternary(cond1, d1, where_ternary(cond2, d1, -1.0 * d1))
|
||||
return out
|
||||
@@ -0,0 +1,81 @@
|
||||
"""Kakushadze Alpha #10.
|
||||
|
||||
Formula (paper appendix): rank((0<ts_min(delta(close,1),4))?delta(close,1):((ts_max(delta(close,1),4)<0)?delta(close,1):(-1*delta(close,1))))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 10.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_010"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_010',
|
||||
'nickname': 'Kakushadze Alpha #10',
|
||||
'theme': ['momentum'],
|
||||
'formula_latex': 'rank((0<ts_min(delta(close,1),4))?delta(close,1):((ts_max(delta(close,1),4)<0)?delta(close,1):(-1*delta(close,1))))',
|
||||
'columns_required': ['close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 5,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _where_ternary(cond, a, b):
|
||||
"""Vectorised ternary `(cond ? a : b)` returning a DataFrame.
|
||||
|
||||
``cond`` is a boolean DataFrame; ``a`` / ``b`` may be DataFrame or scalar.
|
||||
"""
|
||||
if isinstance(a, (int, float)):
|
||||
a_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(a))
|
||||
else:
|
||||
a_arr = a.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
if isinstance(b, (int, float)):
|
||||
b_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(b))
|
||||
else:
|
||||
b_arr = b.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
cond_arr = cond.to_numpy(dtype=bool, na_value=False) if hasattr(cond, "to_numpy") else np.asarray(cond, dtype=bool)
|
||||
out = np.where(cond_arr, a_arr, b_arr)
|
||||
out = np.where(np.isfinite(out), out, np.nan)
|
||||
idx = cond.index if hasattr(cond, "index") else a.index
|
||||
cols = cond.columns if hasattr(cond, "columns") else a.columns
|
||||
return pd.DataFrame(out, index=idx, columns=cols)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
where_ternary = _where_ternary
|
||||
d1 = delta(close, 1)
|
||||
cond1 = ts_min(d1, 4) > 0
|
||||
cond2 = ts_max(d1, 4) < 0
|
||||
inner = where_ternary(cond1, d1, where_ternary(cond2, d1, -1.0 * d1))
|
||||
out = rank(inner)
|
||||
return out
|
||||
@@ -0,0 +1,58 @@
|
||||
"""Kakushadze Alpha #11.
|
||||
|
||||
Formula (paper appendix): (rank(ts_max(vwap-close,3))+rank(ts_min(vwap-close,3)))*rank(delta(volume,3))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 11.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_011"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_011',
|
||||
'nickname': 'Kakushadze Alpha #11',
|
||||
'theme': ['volume', 'reversal'],
|
||||
'formula_latex': '(rank(ts_max(vwap-close,3))+rank(ts_min(vwap-close,3)))*rank(delta(volume,3))',
|
||||
'columns_required': ['close', 'volume', 'vwap'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 5,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
volume = panel["volume"]
|
||||
vwap = panel["vwap"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
diff = vwap - close
|
||||
out = (rank(ts_max(diff, 3)) + rank(ts_min(diff, 3))) * rank(delta(volume, 3))
|
||||
return out
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Kakushadze Alpha #12.
|
||||
|
||||
Formula (paper appendix): sign(delta(volume,1)) * (-1 * delta(close,1))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 12.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_012"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_012',
|
||||
'nickname': 'Kakushadze Alpha #12',
|
||||
'theme': ['volume', 'reversal'],
|
||||
'formula_latex': 'sign(delta(volume,1)) * (-1 * delta(close,1))',
|
||||
'columns_required': ['close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 2,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = np.sign(delta(volume, 1)) * (-1.0 * delta(close, 1))
|
||||
return out
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Kakushadze Alpha #13.
|
||||
|
||||
Formula (paper appendix): -1 * rank(covariance(rank(close), rank(volume), 5))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 13.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_013"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_013',
|
||||
'nickname': 'Kakushadze Alpha #13',
|
||||
'theme': ['volume'],
|
||||
'formula_latex': '-1 * rank(covariance(rank(close), rank(volume), 5))',
|
||||
'columns_required': ['close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 5,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * rank(ts_cov(rank(close), rank(volume), 5))
|
||||
return out
|
||||
@@ -0,0 +1,57 @@
|
||||
"""Kakushadze Alpha #14.
|
||||
|
||||
Formula (paper appendix): (-1*rank(delta(returns,3))) * correlation(open, volume, 10)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 14.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_014"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_014',
|
||||
'nickname': 'Kakushadze Alpha #14',
|
||||
'theme': ['volume', 'momentum'],
|
||||
'formula_latex': '(-1*rank(delta(returns,3))) * correlation(open, volume, 10)',
|
||||
'columns_required': ['open', 'close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 10,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
open_ = panel["open"]
|
||||
volume = panel["volume"]
|
||||
|
||||
returns = close.pct_change()
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = (-1.0 * rank(delta(returns, 3))) * ts_corr(open_, volume, 10)
|
||||
return out
|
||||
@@ -0,0 +1,62 @@
|
||||
"""Kakushadze Alpha #15.
|
||||
|
||||
Formula (paper appendix): -1 * sum(rank(correlation(rank(high), rank(volume), 3)), 3)
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 15.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_015"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_015',
|
||||
'nickname': 'Kakushadze Alpha #15',
|
||||
'theme': ['volume'],
|
||||
'formula_latex': '-1 * sum(rank(correlation(rank(high), rank(volume), 3)), 3)',
|
||||
'columns_required': ['high', 'volume', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 6,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _rolling_sum(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling window sum; warmup -> NaN."""
|
||||
return df.rolling(window=n, min_periods=n).sum()
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
high = panel["high"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
rolling_sum = _rolling_sum
|
||||
out = -1.0 * rolling_sum(rank(ts_corr(rank(high), rank(volume), 3)), 3)
|
||||
return out
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Kakushadze Alpha #16.
|
||||
|
||||
Formula (paper appendix): -1 * rank(covariance(rank(high), rank(volume), 5))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 16.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_016"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_016',
|
||||
'nickname': 'Kakushadze Alpha #16',
|
||||
'theme': ['volume'],
|
||||
'formula_latex': '-1 * rank(covariance(rank(high), rank(volume), 5))',
|
||||
'columns_required': ['high', 'volume', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 5,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
high = panel["high"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * rank(ts_cov(rank(high), rank(volume), 5))
|
||||
return out
|
||||
@@ -0,0 +1,56 @@
|
||||
"""Kakushadze Alpha #17.
|
||||
|
||||
Formula (paper appendix): ((-1*rank(ts_rank(close,10)))*rank(delta(delta(close,1),1)))*rank(ts_rank(volume/adv20,5))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 17.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_017"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_017',
|
||||
'nickname': 'Kakushadze Alpha #17',
|
||||
'theme': ['volume', 'reversal'],
|
||||
'formula_latex': '((-1*rank(ts_rank(close,10)))*rank(delta(delta(close,1),1)))*rank(ts_rank(volume/adv20,5))',
|
||||
'columns_required': ['close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 25,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
volume = panel["volume"]
|
||||
adv20 = ts_mean(volume, 20)
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = (-1.0 * rank(ts_rank(close, 10))) * rank(delta(delta(close, 1), 1)) * rank(ts_rank(safe_div(volume, adv20), 5))
|
||||
return out
|
||||
@@ -0,0 +1,57 @@
|
||||
"""Kakushadze Alpha #18.
|
||||
|
||||
Formula (paper appendix): -1 * rank(stddev(abs(close-open),5) + (close-open) + correlation(close,open,10))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 18.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_018"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_018',
|
||||
'nickname': 'Kakushadze Alpha #18',
|
||||
'theme': ['volatility'],
|
||||
'formula_latex': '-1 * rank(stddev(abs(close-open),5) + (close-open) + correlation(close,open,10))',
|
||||
'columns_required': ['open', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 10,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
open_ = panel["open"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
diff = (close - open_)
|
||||
out = -1.0 * rank(ts_std(diff.abs(), 5) + diff + ts_corr(close, open_, 10))
|
||||
return out
|
||||
@@ -0,0 +1,70 @@
|
||||
"""Kakushadze Alpha #19.
|
||||
|
||||
Formula (paper appendix): (-1*sign((close-delay(close,7))+delta(close,7))) * (1+rank(1+sum(returns,250)))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 19.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_019"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_019',
|
||||
'nickname': 'Kakushadze Alpha #19',
|
||||
'theme': ['momentum'],
|
||||
'formula_latex': '(-1*sign((close-delay(close,7))+delta(close,7))) * (1+rank(1+sum(returns,250)))',
|
||||
'columns_required': ['close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 250,
|
||||
'notes': 'Very long lookback (>= ~100 bars); produces NaN warmup on short panels which may trigger the >95% NaN registry guard.',
|
||||
}
|
||||
|
||||
|
||||
def _rolling_sum(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling window sum; warmup -> NaN."""
|
||||
return df.rolling(window=n, min_periods=n).sum()
|
||||
|
||||
|
||||
def _delay(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Backward shift by n (lookahead-safe; n>=1 required)."""
|
||||
if n < 1:
|
||||
raise ValueError("delay requires n >= 1 (lookahead ban)")
|
||||
return df.shift(n)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
|
||||
|
||||
returns = close.pct_change()
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
rolling_sum = _rolling_sum
|
||||
delay = _delay
|
||||
out = (-1.0 * np.sign((close - delay(close, 7)) + delta(close, 7))) * (1.0 + rank(1.0 + rolling_sum(returns, 250)))
|
||||
return out
|
||||
@@ -0,0 +1,66 @@
|
||||
"""Kakushadze Alpha #20.
|
||||
|
||||
Formula (paper appendix): (((-1*rank(open-delay(high,1)))*rank(open-delay(close,1)))*rank(open-delay(low,1)))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 20.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_020"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_020',
|
||||
'nickname': 'Kakushadze Alpha #20',
|
||||
'theme': ['reversal'],
|
||||
'formula_latex': '(((-1*rank(open-delay(high,1)))*rank(open-delay(close,1)))*rank(open-delay(low,1)))',
|
||||
'columns_required': ['open', 'high', 'low', 'close'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 2,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _delay(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Backward shift by n (lookahead-safe; n>=1 required)."""
|
||||
if n < 1:
|
||||
raise ValueError("delay requires n >= 1 (lookahead ban)")
|
||||
return df.shift(n)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
open_ = panel["open"]
|
||||
high = panel["high"]
|
||||
low = panel["low"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
delay = _delay
|
||||
out = ((-1.0 * rank(open_ - delay(high, 1))) * rank(open_ - delay(close, 1))) * rank(open_ - delay(low, 1))
|
||||
return out
|
||||
@@ -0,0 +1,98 @@
|
||||
"""Kakushadze Alpha #21.
|
||||
|
||||
Formula (paper appendix): complex piecewise; see paper
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 21.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_021"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_021',
|
||||
'nickname': 'Kakushadze Alpha #21',
|
||||
'theme': ['momentum', 'volatility'],
|
||||
'formula_latex': 'complex piecewise; see paper',
|
||||
'columns_required': ['close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 20,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def _rolling_sum(df: pd.DataFrame, n: int) -> pd.DataFrame:
|
||||
"""Rolling window sum; warmup -> NaN."""
|
||||
return df.rolling(window=n, min_periods=n).sum()
|
||||
|
||||
|
||||
def _make_one(ref: pd.DataFrame) -> pd.DataFrame:
|
||||
"""A DataFrame of 1.0 with the same shape/index/columns as ``ref``."""
|
||||
return pd.DataFrame(1.0, index=ref.index, columns=ref.columns)
|
||||
|
||||
|
||||
def _where_ternary(cond, a, b):
|
||||
"""Vectorised ternary `(cond ? a : b)` returning a DataFrame.
|
||||
|
||||
``cond`` is a boolean DataFrame; ``a`` / ``b`` may be DataFrame or scalar.
|
||||
"""
|
||||
if isinstance(a, (int, float)):
|
||||
a_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(a))
|
||||
else:
|
||||
a_arr = a.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
if isinstance(b, (int, float)):
|
||||
b_arr = np.full_like(cond.to_numpy(dtype=np.float64), float(b))
|
||||
else:
|
||||
b_arr = b.to_numpy(dtype=np.float64, na_value=np.nan)
|
||||
cond_arr = cond.to_numpy(dtype=bool, na_value=False) if hasattr(cond, "to_numpy") else np.asarray(cond, dtype=bool)
|
||||
out = np.where(cond_arr, a_arr, b_arr)
|
||||
out = np.where(np.isfinite(out), out, np.nan)
|
||||
idx = cond.index if hasattr(cond, "index") else a.index
|
||||
cols = cond.columns if hasattr(cond, "columns") else a.columns
|
||||
return pd.DataFrame(out, index=idx, columns=cols)
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
volume = panel["volume"]
|
||||
adv20 = ts_mean(volume, 20)
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
rolling_sum = _rolling_sum
|
||||
make_one = _make_one
|
||||
where_ternary = _where_ternary
|
||||
m8 = rolling_sum(close, 8) / 8.0
|
||||
s8 = ts_std(close, 8)
|
||||
m2 = rolling_sum(close, 2) / 2.0
|
||||
v_adv = safe_div(volume, adv20)
|
||||
cond_a = (m8 + s8) < m2
|
||||
cond_b = m2 < (m8 - s8)
|
||||
cond_c = (v_adv >= 1.0)
|
||||
one = make_one(close)
|
||||
out = where_ternary(cond_a, -1.0 * one, where_ternary(cond_b, one, where_ternary(cond_c, one, -1.0 * one)))
|
||||
return out
|
||||
@@ -0,0 +1,57 @@
|
||||
"""Kakushadze Alpha #22.
|
||||
|
||||
Formula (paper appendix): -1 * (delta(correlation(high,volume,5),5) * rank(stddev(close,20)))
|
||||
Source: Kakushadze (2015), "101 Formulaic Alphas", arXiv:1601.00991, eq. 22.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.factors.base import (
|
||||
decay_linear,
|
||||
delta,
|
||||
rank,
|
||||
safe_div,
|
||||
scale,
|
||||
signed_power,
|
||||
ts_argmax,
|
||||
ts_argmin,
|
||||
ts_corr,
|
||||
ts_cov,
|
||||
ts_max,
|
||||
ts_mean,
|
||||
ts_min,
|
||||
ts_rank,
|
||||
ts_std,
|
||||
)
|
||||
|
||||
ALPHA_ID = "alpha101_022"
|
||||
|
||||
__alpha_meta__ = {
|
||||
'id': 'alpha101_022',
|
||||
'nickname': 'Kakushadze Alpha #22',
|
||||
'theme': ['volume', 'volatility'],
|
||||
'formula_latex': '-1 * (delta(correlation(high,volume,5),5) * rank(stddev(close,20)))',
|
||||
'columns_required': ['high', 'close', 'volume'],
|
||||
'extras_required': [],
|
||||
'requires_sector': False,
|
||||
'universe': ['equity_us'],
|
||||
'frequency': ['1D'],
|
||||
'decay_horizon': 5,
|
||||
'min_warmup_bars': 25,
|
||||
'notes': '',
|
||||
}
|
||||
|
||||
|
||||
def compute(panel: dict) -> pd.DataFrame:
|
||||
"""Compute the alpha on the OHLCV+ panel and return a wide DataFrame."""
|
||||
close = panel["close"]
|
||||
high = panel["high"]
|
||||
volume = panel["volume"]
|
||||
|
||||
|
||||
# Helper aliases (local closures keep the file standalone & purity-safe).
|
||||
out = -1.0 * (delta(ts_corr(high, volume, 5), 5) * rank(ts_std(close, 20)))
|
||||
return out
|
||||
Loaded 100 of 797 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user