Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 warren618 |
4dcb33034a | ||
|
warren618
|
aae5a7ec1a | ||
|
warren618
|
300f5c2f4f | ||
|
warren618
|
05fc5cac22 | ||
|
Brandy Goodandgenoshide
|
cd999a8d5b | ||
|
warren618
|
69a4dc69f9 | ||
|
MB-Ndhlovu
|
ffa95a9f51 | ||
|
warren618
|
29fd1f91fa | ||
|
warren618
|
0b9b4d8f64 | ||
|
warren618
|
5c9488d30b | ||
|
warren618
|
0a38ba5ef0 | ||
|
warren618
|
8fdf4f8014 | ||
|
Hamza Mobeen
|
bc62206ad6 | ||
|
Hamza Mobeen
|
4b28a4d1b4 | ||
|
warren618
|
b76af14d00 | ||
|
Mothilal M
|
63ca24867c | ||
|
Hamza Mobeen
|
f9022a3ac4 | ||
|
warren618
|
fc708d15c5 | ||
|
warren618
|
a1040bbb71 | ||
|
warren618
|
b769580389 | ||
|
warren618
|
e6ceb5a3b3 | ||
|
warren618
|
d4c730213f | ||
|
warren618
|
f866e5fb14 | ||
|
warren618
|
b6adee5651 | ||
|
warren618
|
73b179a28d | ||
|
warren618
|
da2df110b1 | ||
|
yule153604and@yule153604
|
0efa443429 | ||
|
warren618
|
93db691583 | ||
|
warren618
|
a35e870aad | ||
|
warren618
|
2c80efcd77 | ||
|
warren618
|
25380bac96 | ||
|
warren618
|
c090d1fce8 | ||
|
warren618
|
8e45d2c4ee | ||
|
warren618
|
2b0a775db0 | ||
|
warren618
|
01996fff7c | ||
|
warren618
|
5709e20a20 | ||
|
warren618
|
c0074da1d2 | ||
|
warren618
|
e2a4654edb | ||
|
warren618
|
6caa1d523f | ||
|
warren618
|
c74a059afb | ||
|
jiakeboge
|
0bd40354bc | ||
|
|
e8e86e1a1d | ||
|
warren618
|
5de1f82e27 | ||
|
warren618
|
4e52ed7e77 | ||
|
warren618
|
59fb021c58 | ||
|
warren618
|
1f8f4a005f | ||
|
warren618
|
940624a2d6 | ||
|
warren618
|
e2de75c3b6 | ||
|
Haozhe Wu
|
cb85af67b5 | ||
|
SoufianoDev
|
e9d04a10e5 | ||
|
warren618
|
66cd96a303 | ||
|
warren618
|
ed47b26b5c | ||
|
warren618
|
0aea8b0150 | ||
|
warren618
|
ddeb371632 | ||
|
warren618
|
a8828c16f3 | ||
|
warren618
|
2772ecb688 |
No files matched your search
@@ -67,7 +67,7 @@ body:
|
||||
attributes:
|
||||
label: Version
|
||||
description: "Run `pip show vibe-trading-ai` to check"
|
||||
placeholder: "e.g., 0.1.3"
|
||||
placeholder: "e.g., 0.1.5"
|
||||
|
||||
- type: input
|
||||
id: environment
|
||||
|
||||
+17
-1
@@ -1,4 +1,4 @@
|
||||
.venv/
|
||||
.venv/
|
||||
agent/.venv/
|
||||
__pycache__/
|
||||
.pytest_cache/
|
||||
@@ -16,6 +16,7 @@ agent/sessions/
|
||||
agent/runs/
|
||||
agent/.ui_runtime/
|
||||
agent/.tasks/
|
||||
agent/uploads/
|
||||
agent/tests/*_result.json
|
||||
.ruff_cache/
|
||||
frontend/dist/
|
||||
@@ -40,3 +41,18 @@ agent/vibe_trading_ai.egg-info/
|
||||
agent/tests/e2e_backtest/
|
||||
dist/
|
||||
build/
|
||||
|
||||
# Local demo videos (too large for git; link to external host instead)
|
||||
assets/*.mp4
|
||||
|
||||
# Manual E2E smoke tests — require live API keys (OpenRouter / yfinance),
|
||||
# would break CI if committed. Kept local; run explicitly when validating
|
||||
# a release.
|
||||
agent/tests/e2e_*.py
|
||||
agent/tests/test_e2e_*.py
|
||||
|
||||
# Local working notes
|
||||
NOTES.md
|
||||
|
||||
# Agent tool aliases (auto-generated mirror of CLAUDE.md)
|
||||
AGENTS.md
|
||||
@@ -0,0 +1,128 @@
|
||||
# Contributor Covenant Code of Conduct
|
||||
|
||||
## Our Pledge
|
||||
|
||||
We as members, contributors, and leaders pledge to make participation in our
|
||||
community a harassment-free experience for everyone, regardless of age, body
|
||||
size, visible or invisible disability, ethnicity, sex characteristics, gender
|
||||
identity and expression, level of experience, education, socioeconomic status,
|
||||
nationality, personal appearance, race, religion, or sexual identity
|
||||
and orientation.
|
||||
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming,
|
||||
diverse, inclusive, and healthy community.
|
||||
|
||||
## Our Standards
|
||||
|
||||
Examples of behavior that contributes to a positive environment for our
|
||||
community include:
|
||||
|
||||
- Demonstrating empathy and kindness toward other people
|
||||
- Being respectful of differing opinions, viewpoints, and experiences
|
||||
- Giving and gracefully accepting constructive feedback
|
||||
- Accepting responsibility and apologizing to those affected by our mistakes,
|
||||
and learning from the experience
|
||||
- Focusing on what is best not just for us as individuals, but for the
|
||||
overall community
|
||||
|
||||
Examples of unacceptable behavior include:
|
||||
|
||||
- The use of sexualized language or imagery, and sexual attention or
|
||||
advances of any kind
|
||||
- Trolling, insulting or derogatory comments, and personal or political attacks
|
||||
- Public or private harassment
|
||||
- Publishing others' private information, such as a physical or email
|
||||
address, without their explicit permission
|
||||
- Other conduct which could reasonably be considered inappropriate in a
|
||||
professional setting
|
||||
|
||||
## Enforcement Responsibilities
|
||||
|
||||
Community leaders are responsible for clarifying and enforcing our standards of
|
||||
acceptable behavior and will take appropriate and fair corrective action in
|
||||
response to any behavior that they deem inappropriate, threatening, offensive,
|
||||
or harmful.
|
||||
|
||||
Community leaders have the right and responsibility to remove, edit, or reject
|
||||
comments, commits, code, wiki edits, issues, and other contributions that are
|
||||
not aligned to this Code of Conduct, and will communicate reasons for moderation
|
||||
decisions when appropriate.
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all community spaces, and also applies when
|
||||
an individual is officially representing the community in public spaces.
|
||||
Examples of representing our community include using an official e-mail address,
|
||||
posting via an official social media account, or acting as an appointed
|
||||
representative at an online or offline event.
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be
|
||||
reported to the community leaders responsible for enforcement via
|
||||
[GitHub Issues](https://github.com/HKUDS/Vibe-Trading/issues).
|
||||
All complaints will be reviewed and investigated promptly and fairly.
|
||||
|
||||
All community leaders are obligated to respect the privacy and security of the
|
||||
reporter of any incident.
|
||||
|
||||
## Enforcement Guidelines
|
||||
|
||||
Community leaders will follow these Community Impact Guidelines in determining
|
||||
the consequences for any action they deem in violation of this Code of Conduct:
|
||||
|
||||
### 1. Correction
|
||||
|
||||
**Community Impact**: Use of inappropriate language or other behavior deemed
|
||||
unprofessional or unwelcome in the community.
|
||||
|
||||
**Consequence**: A private, written warning from community leaders, providing
|
||||
clarity around the nature of the violation and an explanation of why the
|
||||
behavior was inappropriate. A public apology may be requested.
|
||||
|
||||
### 2. Warning
|
||||
|
||||
**Community Impact**: A violation through a single incident or series
|
||||
of actions.
|
||||
|
||||
**Consequence**: A warning with consequences for continued behavior. No
|
||||
interaction with the people involved, including unsolicited interaction with
|
||||
those enforcing the Code of Conduct, for a specified period of time. This
|
||||
includes avoiding interactions in community spaces as well as external channels
|
||||
like social media. Violating these terms may lead to a temporary or
|
||||
permanent ban.
|
||||
|
||||
### 3. Temporary Ban
|
||||
|
||||
**Community Impact**: A serious violation of community standards, including
|
||||
sustained inappropriate behavior.
|
||||
|
||||
**Consequence**: A temporary ban from any sort of interaction or public
|
||||
communication with the community for a specified period of time. No public or
|
||||
private interaction with the people involved, including unsolicited interaction
|
||||
with those enforcing the Code of Conduct, is allowed during this period.
|
||||
Violating these terms may lead to a permanent ban.
|
||||
|
||||
### 4. Permanent Ban
|
||||
|
||||
**Community Impact**: Demonstrating a pattern of violation of community
|
||||
standards, including sustained inappropriate behavior, harassment of an
|
||||
individual, or aggression toward or disparagement of classes of individuals.
|
||||
|
||||
**Consequence**: A permanent ban from any sort of public interaction within
|
||||
the community.
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage],
|
||||
version 2.1, available at
|
||||
https://www.contributor-covenant.org/version/2/1/code_of_conduct.html.
|
||||
|
||||
Community Impact Guidelines were inspired by [Mozilla's code of conduct
|
||||
enforcement ladder](https://github.com/mozilla/diversity).
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
|
||||
For answers to common questions about this code of conduct, see the FAQ at
|
||||
https://www.contributor-covenant.org/faq. Translations are available at
|
||||
https://www.contributor-covenant.org/translations.
|
||||
+3
-3
@@ -42,10 +42,10 @@ cd frontend && npm install && npm run dev
|
||||
|
||||
| Directory | What lives here | Open to contribute? |
|
||||
|-----------|----------------|:-------------------:|
|
||||
| `agent/src/skills/` | 68 finance skill definitions (SKILL.md) | Yes |
|
||||
| `agent/src/skills/` | 69 finance skill definitions (SKILL.md) | Yes |
|
||||
| `agent/src/tools/` | 21 agent tools | Yes |
|
||||
| `agent/backtest/` | Backtest engines, loaders, optimizers | Yes |
|
||||
| `agent/config/swarm/` | 29 swarm preset YAMLs | Yes |
|
||||
| `agent/src/swarm/presets/` | 29 swarm preset YAMLs | Yes |
|
||||
| `frontend/` | React 19 + Vite web UI | Yes |
|
||||
| `agent/src/agent/` | ReAct agent core (loop, context, skills) | Ask first |
|
||||
| `agent/src/session/` | Session management | Ask first |
|
||||
@@ -112,7 +112,7 @@ Each skill is a single `SKILL.md` file in `agent/src/skills/<category>/<skill-na
|
||||
|
||||
### Easy: New Swarm Preset
|
||||
|
||||
A YAML file in `agent/config/swarm/` defining agents, roles, and DAG workflow. See existing presets.
|
||||
A YAML file in `agent/src/swarm/presets/` defining agents, roles, and DAG workflow. See existing presets.
|
||||
|
||||
### Medium: New Data Source Loader
|
||||
|
||||
|
||||
+26
@@ -0,0 +1,26 @@
|
||||
include LICENSE
|
||||
include README.md
|
||||
include README_zh.md
|
||||
include README_ja.md
|
||||
include README_ko.md
|
||||
include README_ar.md
|
||||
include pyproject.toml
|
||||
include Dockerfile
|
||||
include docker-compose.yml
|
||||
|
||||
# Developer entry-point template
|
||||
include agent/.env.example
|
||||
|
||||
# Tests shipped so dev installs can run `pytest` against the package.
|
||||
# Files prefixed with `_` are local debug scripts kept untracked — keep
|
||||
# them out of the sdist even if present in the working tree.
|
||||
recursive-include agent/tests *.py
|
||||
recursive-exclude agent/tests _*.py
|
||||
|
||||
# Strip generated / VCS / editor noise
|
||||
global-exclude __pycache__
|
||||
global-exclude *.py[cod]
|
||||
global-exclude *.so
|
||||
global-exclude .DS_Store
|
||||
global-exclude .pytest_cache
|
||||
global-exclude *.egg-info
|
||||
@@ -1,5 +1,5 @@
|
||||
<p align="center">
|
||||
<b>English</b> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a>
|
||||
<b>English</b> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a> | <a href="README_ar.md">العربية</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -19,10 +19,10 @@
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="License"></a>
|
||||
<br>
|
||||
<img src="https://img.shields.io/badge/Skills-68-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Skills-72-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Swarm_Presets-29-7C3AED" alt="Swarm">
|
||||
<img src="https://img.shields.io/badge/Tools-21-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-5-2563EB" alt="Data Sources">
|
||||
<img src="https://img.shields.io/badge/Tools-27-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-6-2563EB" alt="Data Sources">
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
@@ -51,10 +51,29 @@
|
||||
|
||||
## 📰 News
|
||||
|
||||
- **2026-04-10** 📦 **v0.1.4**: Fix Docker build ([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)), add `web_search` MCP tool (17 total), `akshare`/`ccxt` in deps & MCP. 11 LLM providers (DeepSeek, Groq, Gemini, Ollama, etc.), all tuning params via `.env`. Hardened `ml-strategy` skill. Published to PyPI and ClawHub.
|
||||
- **2026-04-09** 📊 **Backtest Wave 2 — multi-asset engines**: added ChinaFutures (CFFEX/SHFE/DCE/ZCE, 50+ contracts), GlobalFutures (CME/ICE/Eurex, 30+ contracts), Forex (24 pairs, spread + swap), Options v2 (American exercise, IV smile). Statistical validation: Monte Carlo permutation test, Bootstrap Sharpe CI, Walk-Forward analysis.
|
||||
- **2026-04-08** 🔧 **Multi-market backtest** with per-market rules; **Pine Script v6 export** for TradingView. **Data source expansion**: 5 sources with auto-fallback, `web_search` tool, skill categorization (7 categories).
|
||||
- **2026-04-01** 🚀 **v0.1.0** — Initial release: ReAct agent, 64 skills, 29 swarm presets, cross-market backtest, CLI + Web UI + MCP server.
|
||||
- **2026-04-28** 🚀 **v0.1.6 released** (`pip install -U vibe-trading-ai`): Fixes `vibe-trading --swarm-presets` returning empty after `pip install` / `uv tool install` ([#55](https://github.com/HKUDS/Vibe-Trading/issues/55)) — preset YAMLs now bundled inside the `src.swarm` package and pinned by a 6-test regression suite. Plus AKShare loader correctly routes ETFs (`510300.SH`) and forex (`USDCNH`) to the right endpoints with hardened registry fallback. Rolls up everything since v0.1.5: benchmark comparison panel, `/upload` streaming + size limits, Futu loader (HK + A-share), vnpy export skill, security hardening, frontend lazy loading (688KB → 262KB).
|
||||
- **2026-04-27** 📊 **Benchmark panel + upload safety**: Backtest output now ships a benchmark comparison panel (ticker / benchmark return / excess return / information ratio) with yfinance-backed resolution for SPY, CSI 300, etc. ([#48](https://github.com/HKUDS/Vibe-Trading/issues/48)). Plus `/upload` streams the request body in 1 MB chunks and aborts past `MAX_UPLOAD_SIZE`, bounding memory under oversized/malformed clients ([#53](https://github.com/HKUDS/Vibe-Trading/pull/53)) — pinned by a 4-case regression suite.
|
||||
- **2026-04-22** 🛡️ **Hardening + new integrations**: Path containment enforced in `safe_path` + journal/shadow tool sandbox, `MANIFEST.in` ships `.env.example` / tests / Docker files in sdist, route-level lazy loading shrinks frontend initial bundle 688KB → 262KB. Plus Futu data loader for HK & A-share equities ([#47](https://github.com/HKUDS/Vibe-Trading/pull/47)) and vnpy CtaTemplate export skill ([#46](https://github.com/HKUDS/Vibe-Trading/pull/46)).
|
||||
|
||||
<details>
|
||||
<summary>Earlier news</summary>
|
||||
|
||||
- **2026-04-21** 🛡️ **Workspace + docs**: Relative `run_dir` normalized to active run dir ([#43](https://github.com/HKUDS/Vibe-Trading/pull/43)). README usage examples ([#45](https://github.com/HKUDS/Vibe-Trading/pull/45)).
|
||||
- **2026-04-20** 🔌 **Reasoning + Swarm**: `reasoning_content` preserved across all `ChatOpenAI` paths — Kimi / DeepSeek / Qwen thinking work end-to-end ([#39](https://github.com/HKUDS/Vibe-Trading/issues/39)). Swarm streaming + clean Ctrl+C ([#42](https://github.com/HKUDS/Vibe-Trading/issues/42)).
|
||||
- **2026-04-19** 📦 **v0.1.5**: Published to PyPI & ClawHub. `python-multipart` CVE floor bump, 5 new MCP tools wired (`analyze_trade_journal` + 4 shadow-account tools), `pattern_recognition` → `pattern` registry fix, Docker dep parity, SKILL manifest synced (22 MCP tools / 71 skills).
|
||||
- **2026-04-18** 👥 **Shadow Account**: Extract your strategy rules from a broker journal → backtest the shadow across markets → 8-section HTML/PDF report showing exactly how much you leave on the table (rule violations, early exits, missed signals, counterfactual trades). 4 new tools, 1 skill, 32 tools total. Trade Journal + Shadow Account samples now live in the web UI welcome screen.
|
||||
- **2026-04-17** 📊 **Trade Journal Analyzer + Universal File Reader**: Upload broker exports (同花顺/东财/富途/generic CSV) → auto trading profile (holding days, win rate, PnL ratio, drawdown) + 4 bias diagnostics (disposition effect, overtrading, chasing momentum, anchoring). `read_document` now dispatches PDF, Word, Excel, PowerPoint, images (OCR), and 40+ text formats behind one unified call.
|
||||
- **2026-04-16** 🧠 **Agent Harness**: Persistent cross-session memory, FTS5 session search, self-evolving skills (full CRUD), 5-layer context compression, read/write tool batching. 27 tools, 107 new tests.
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**: Z.ai provider ([#35](https://github.com/HKUDS/Vibe-Trading/pull/35)), MiniMax temperature fix + model update ([#33](https://github.com/HKUDS/Vibe-Trading/pull/33)). 13 providers.
|
||||
- **2026-04-14** 🔧 **MCP Stability**: Fixed backtest tool `Connection closed` error on stdio transport ([#32](https://github.com/HKUDS/Vibe-Trading/pull/32)).
|
||||
- **2026-04-13** 🌐 **Cross-Market Composite Backtest**: New `CompositeEngine` backtests mixed-market portfolios (e.g. A-shares + crypto) with shared capital pool and per-market rules. Also fixed swarm template variable fallback and frontend timeout.
|
||||
- **2026-04-12** 🌍 **Multi-Platform Export**: `/pine` exports strategies to TradingView (Pine Script v6), TDX (通达信/同花顺/东方财富), and MetaTrader 5 (MQL5) in one command.
|
||||
- **2026-04-11** 🛡️ **Reliability & DX**: `vibe-trading init` .env bootstrap ([#19](https://github.com/HKUDS/Vibe-Trading/pull/19)), preflight checks, runtime data-source fallback, hardened backtest engine. Multi-language README ([#21](https://github.com/HKUDS/Vibe-Trading/pull/21)).
|
||||
- **2026-04-10** 📦 **v0.1.4**: Docker fix ([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)), `web_search` MCP tool, 12 LLM providers, `akshare`/`ccxt` deps. Published to PyPI and ClawHub.
|
||||
- **2026-04-09** 📊 **Backtest Wave 2**: ChinaFutures, GlobalFutures, Forex, Options v2 engines. Monte Carlo, Bootstrap CI, Walk-Forward validation.
|
||||
- **2026-04-08** 🔧 **Multi-market backtest** with per-market rules, Pine Script v6 export, 5 data sources with auto-fallback.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
@@ -63,12 +82,12 @@
|
||||
Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural language requests into executable trading strategies, research insights, and portfolio analysis across global markets.
|
||||
|
||||
### Key Capabilities:
|
||||
• **Strategy Generation** — Automatically writes trading code from your ideas<br>
|
||||
• **Smart Data Access** — 5 data sources with automatic fallback; zero-config for all markets<br>
|
||||
• **Performance Testing** — Tests your strategies against historical market data<br>
|
||||
• **TradingView Export** — One-click convert strategies to Pine Script v6 for TradingView<br>
|
||||
• **Expert Teams** — Deploys specialized AI agents for complex research tasks<br>
|
||||
• **Live Updates** — Watch the entire analysis process in real-time
|
||||
• **Natural Language → Strategy** — Describe an idea; the agent writes, tests, and exports trading code<br>
|
||||
• **5 Data Sources, Zero Config** — A-shares, HK/US, crypto, futures & forex with automatic fallback<br>
|
||||
• **29 Expert Teams** — Pre-built multi-agent swarm workflows for investment, trading & risk<br>
|
||||
• **Cross-Session Memory** — Remembers preferences and insights; creates & evolves reusable skills<br>
|
||||
• **7 Backtest Engines** — Cross-market composite testing with statistical validation & 4 optimizers<br>
|
||||
• **Multi-Platform Export** — One-click to TradingView, TDX (通达信/同花顺), and MetaTrader 5
|
||||
|
||||
---
|
||||
|
||||
@@ -79,12 +98,12 @@ Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural l
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-research.png" height="150" alt="Research"/><br>
|
||||
<h3>🔍 DeepResearch for Trading</h3>
|
||||
<img src="https://img.shields.io/badge/68_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<img src="https://img.shields.io/badge/72_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<div align="left" style="font-size: 4px;">
|
||||
• Multi-domain analysis coverage across markets<br>
|
||||
• Auto strategy and signal generation<br>
|
||||
• Macro economic research and insights<br>
|
||||
• Natural-language task routing via chat
|
||||
• 72 specialist skills with persistent cross-session memory<br>
|
||||
• Self-evolving: agent creates & refines workflows from experience<br>
|
||||
• 5-layer context compression — no info lost in long sessions<br>
|
||||
• Natural-language task routing across all finance domains
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -94,8 +113,8 @@ Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural l
|
||||
<div align="left">
|
||||
• 29 out-of-the-box trading team presets<br>
|
||||
• DAG-based multi-agent orchestration<br>
|
||||
• Real-time decision streaming dashboard<br>
|
||||
• Custom team building through YAML
|
||||
• Real-time streaming dashboard with live agent status<br>
|
||||
• FTS5 session search across all past conversations
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -104,7 +123,7 @@ Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural l
|
||||
<img src="https://img.shields.io/badge/5_Data_Sources-FFD93D?style=for-the-badge&logo=bitcoin&logoColor=black" alt="Backtest" /><br><br>
|
||||
<div align="left">
|
||||
• A-shares, HK/US equities, crypto, futures & forex<br>
|
||||
• 7 market engines: A-share, US/HK equity, crypto, China futures, global futures, forex<br>
|
||||
• 7 market engines + composite cross-market engine with shared capital pool<br>
|
||||
• Statistical validation: Monte Carlo, Bootstrap CI, Walk-Forward<br>
|
||||
• 15+ performance metrics & 4 optimizers
|
||||
</div>
|
||||
@@ -123,16 +142,16 @@ Vibe-Trading is an AI-powered multi-agent finance workspace that turns natural l
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## 68 Skills across 7 Categories
|
||||
## 72 Skills across 7 Categories
|
||||
|
||||
- 📊 68 specialized finance skills organized into 7 categories
|
||||
- 📊 72 specialized finance skills organized into 7 categories
|
||||
- 🌐 Complete coverage from traditional markets to crypto & DeFi
|
||||
- 🔬 Comprehensive capabilities spanning data sourcing to quantitative research
|
||||
|
||||
| Category | Skills | Examples |
|
||||
|----------|--------|----------|
|
||||
| Data Source | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| Strategy | 16 | `strategy-generate`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Strategy | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 15 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis` |
|
||||
| Asset Class | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| Crypto | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
@@ -223,7 +242,7 @@ vibe-trading-mcp # start MCP server (stdio)
|
||||
- **Python 3.11+** for Path B
|
||||
- **Docker** for Path A
|
||||
|
||||
> **Supported LLM providers:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Ollama (local). See `.env.example` for config.
|
||||
> **Supported LLM providers:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Z.ai, Ollama (local). See `.env.example` for config.
|
||||
|
||||
> **Tip:** All markets work without any API keys thanks to automatic fallback. yfinance (HK/US), OKX (crypto), and AKShare (A-shares, US, HK, futures, forex) are all free. Tushare token is optional — AKShare covers A-shares as a free fallback.
|
||||
|
||||
@@ -308,6 +327,18 @@ Copy `agent/.env.example` to `agent/.env` and uncomment the provider block you w
|
||||
|
||||
**Free data (no key needed):** A-shares via AKShare, HK/US equities via yfinance, crypto via OKX, 100+ crypto exchanges via CCXT. The system automatically selects the best available source for each market.
|
||||
|
||||
### 🎯 Recommended Models
|
||||
|
||||
Vibe-Trading is a tool-heavy agent — skills, backtests, memory, and swarms all flow through tool calls. Model choice directly decides whether the agent *uses* its tools or fabricates answers from training data.
|
||||
|
||||
| Tier | Examples | When to use |
|
||||
|------|----------|-------------|
|
||||
| **Best** | `anthropic/claude-opus-4.7`, `anthropic/claude-sonnet-4.6`, `openai/gpt-5.4`, `google/gemini-3.1-pro-preview` | Complex swarms (3+ agents), long research sessions, paper-grade analysis |
|
||||
| **Sweet spot** (default) | `deepseek/deepseek-v3.2`, `x-ai/grok-4.20`, `z-ai/glm-5.1`, `moonshotai/kimi-k2.5`, `qwen/qwen3-max-thinking` | Daily driver — reliable tool-calling at ~1/10 the cost |
|
||||
| **Avoid for agent use** | `*-nano`, `*-flash-lite`, `*-coder-next`, small / distilled variants | Tool-calling is unreliable — the agent will appear to "answer from memory" instead of loading skills or running backtests |
|
||||
|
||||
The default `agent/.env.example` ships with `deepseek/deepseek-v3.2` — the cheapest option in the sweet-spot tier.
|
||||
|
||||
---
|
||||
|
||||
## 🖥 CLI Reference
|
||||
@@ -324,7 +355,7 @@ vibe-trading serve # API server
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/help` | Show all commands |
|
||||
| `/skills` | List all 68 finance skills |
|
||||
| `/skills` | List all 72 finance skills |
|
||||
| `/swarm` | List 29 swarm team presets |
|
||||
| `/swarm run <preset> [vars_json]` | Run a swarm team with live streaming |
|
||||
| `/swarm list` | Swarm run history |
|
||||
@@ -333,7 +364,7 @@ vibe-trading serve # API server
|
||||
| `/list` | Recent runs |
|
||||
| `/show <run_id>` | Run details + metrics |
|
||||
| `/code <run_id>` | Generated strategy code |
|
||||
| `/pine <run_id>` | Pine Script for TradingView |
|
||||
| `/pine <run_id>` | Export indicators (TradingView + TDX + MT5) |
|
||||
| `/trace <run_id>` | Full execution replay |
|
||||
| `/continue <run_id> <prompt>` | Continue a run with new instructions |
|
||||
| `/sessions` | List chat sessions |
|
||||
@@ -361,7 +392,7 @@ vibe-trading --swarm-run investment_committee '{"topic":"BTC outlook"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # Pine Script for TradingView
|
||||
vibe-trading --pine <run_id> # Export indicators (TradingView + TDX + MT5)
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "refine the strategy"
|
||||
vibe-trading --upload report.pdf
|
||||
@@ -371,6 +402,76 @@ vibe-trading --upload report.pdf
|
||||
|
||||
---
|
||||
|
||||
## 💡 Examples
|
||||
|
||||
### Strategy & Backtesting
|
||||
|
||||
```bash
|
||||
# Moving average crossover on US equities
|
||||
vibe-trading run -p "Backtest a 20/50-day moving average crossover on AAPL for the past year, show Sharpe ratio and max drawdown"
|
||||
|
||||
# RSI mean-reversion on crypto
|
||||
vibe-trading run -p "Test RSI(14) mean-reversion on BTC-USDT: buy below 30, sell above 70, last 6 months"
|
||||
|
||||
# Multi-factor strategy on A-shares
|
||||
vibe-trading run -p "Backtest a momentum + value + quality multi-factor strategy on CSI 300 constituents over 2 years"
|
||||
|
||||
# After backtesting, export to TradingView / TDX / MetaTrader 5
|
||||
vibe-trading --pine <run_id>
|
||||
```
|
||||
|
||||
### Market Research
|
||||
|
||||
```bash
|
||||
# Equity deep-dive
|
||||
vibe-trading run -p "Research NVDA: earnings trend, analyst consensus, option flow, and key risks for next quarter"
|
||||
|
||||
# Macro analysis
|
||||
vibe-trading run -p "Analyze the current Fed rate path, USD strength, and impact on EM equities and gold"
|
||||
|
||||
# Crypto on-chain
|
||||
vibe-trading run -p "Deep dive BTC on-chain: whale flows, exchange balances, miner activity, and funding rates"
|
||||
```
|
||||
|
||||
### Swarm Workflows
|
||||
|
||||
```bash
|
||||
# Bull/bear debate on a stock
|
||||
vibe-trading --swarm-run investment_committee '{"topic": "Is TSLA a buy at current levels?"}'
|
||||
|
||||
# Quant strategy from screening to backtest
|
||||
vibe-trading --swarm-run quant_strategy_desk '{"universe": "S&P 500", "horizon": "3 months"}'
|
||||
|
||||
# Crypto desk: funding + liquidation + flow → risk manager
|
||||
vibe-trading --swarm-run crypto_trading_desk '{"asset": "ETH-USDT", "timeframe": "1w"}'
|
||||
|
||||
# Global macro portfolio allocation
|
||||
vibe-trading --swarm-run macro_rates_fx_desk '{"focus": "Fed pivot impact on EM bonds"}'
|
||||
```
|
||||
|
||||
### Cross-Session Memory
|
||||
|
||||
```bash
|
||||
# Save your preferences once
|
||||
vibe-trading run -p "Remember: I prefer RSI-based strategies, max 10% drawdown, hold period 5–20 days"
|
||||
|
||||
# The agent recalls them in future sessions automatically
|
||||
vibe-trading run -p "Build a crypto strategy that fits my risk profile"
|
||||
```
|
||||
|
||||
### Upload & Analyze Documents
|
||||
|
||||
```bash
|
||||
# Analyze a broker export or earnings report
|
||||
vibe-trading --upload trades_export.csv
|
||||
vibe-trading run -p "Profile my trading behavior and identify any biases"
|
||||
|
||||
vibe-trading --upload NVDA_Q1_earnings.pdf
|
||||
vibe-trading run -p "Summarize the key risks and beats/misses from this earnings report"
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 🌐 API Server
|
||||
|
||||
```bash
|
||||
@@ -381,7 +482,7 @@ vibe-trading serve --port 8899
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | List runs |
|
||||
| `GET` | `/runs/{run_id}` | Run details |
|
||||
| `GET` | `/runs/{run_id}/pine` | Pine Script export |
|
||||
| `GET` | `/runs/{run_id}/pine` | Multi-platform indicator export |
|
||||
| `POST` | `/sessions` | Create session |
|
||||
| `POST` | `/sessions/{id}/messages` | Send message |
|
||||
| `GET` | `/sessions/{id}/events` | SSE event stream |
|
||||
@@ -396,7 +497,7 @@ Interactive docs: `http://localhost:8899/docs`
|
||||
|
||||
## 🔌 MCP Plugin
|
||||
|
||||
Vibe-Trading exposes 17 MCP tools for any MCP-compatible client. Runs as a stdio subprocess — no server setup needed. **16 of 17 tools work with zero API keys** (HK/US/crypto). Only `run_swarm` needs an LLM key.
|
||||
Vibe-Trading exposes 22 MCP tools for any MCP-compatible client. Runs as a stdio subprocess — no server setup needed. **21 of 22 tools work with zero API keys** (HK/US/crypto). Only `run_swarm` needs an LLM key.
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
@@ -438,7 +539,7 @@ vibe-trading-mcp --transport sse # SSE for web clients
|
||||
|
||||
</details>
|
||||
|
||||
**MCP tools exposed (17):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
**MCP tools exposed (22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
|
||||
<details>
|
||||
<summary><b>Install from ClawHub (one command)</b></summary>
|
||||
@@ -458,7 +559,7 @@ Browse on ClawHub: [clawhub.ai/skills/vibe-trading](https://clawhub.ai/skills/vi
|
||||
<details>
|
||||
<summary><b>OpenSpace — self-evolving skills</b></summary>
|
||||
|
||||
All 68 finance skills are published on [open-space.cloud](https://open-space.cloud) and evolve autonomously through OpenSpace's self-evolution engine.
|
||||
All 72 finance skills are published on [open-space.cloud](https://open-space.cloud) and evolve autonomously through OpenSpace's self-evolution engine.
|
||||
|
||||
To use with OpenSpace, add both MCP servers to your agent config:
|
||||
|
||||
@@ -480,7 +581,7 @@ To use with OpenSpace, add both MCP servers to your agent config:
|
||||
}
|
||||
```
|
||||
|
||||
OpenSpace will auto-discover all 68 skills, enabling auto-fix, auto-improve, and community sharing. Search for Vibe-Trading skills via `search_skills("finance backtest")` in any OpenSpace-connected agent.
|
||||
OpenSpace will auto-discover all 72 skills, enabling auto-fix, auto-improve, and community sharing. Search for Vibe-Trading skills via `search_skills("finance backtest")` in any OpenSpace-connected agent.
|
||||
|
||||
</details>
|
||||
|
||||
@@ -496,41 +597,42 @@ Vibe-Trading/
|
||||
├── agent/ # Backend (Python)
|
||||
│ ├── cli.py # CLI entrypoint — interactive TUI + subcommands
|
||||
│ ├── api_server.py # FastAPI server — runs, sessions, upload, swarm, SSE
|
||||
│ ├── mcp_server.py # MCP server — 17 tools for OpenClaw / Claude Desktop
|
||||
│ ├── mcp_server.py # MCP server — 22 tools for OpenClaw / Claude Desktop
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # ReAct agent core
|
||||
│ │ │ ├── loop.py # main reasoning loop
|
||||
│ │ │ ├── skills.py # skill loader (68 SKILL.md files, 7 categories)
|
||||
│ │ │ ├── tools.py # tool orchestration
|
||||
│ │ │ ├── context.py # system prompt builder
|
||||
│ │ │ ├── memory.py # run memory / artifact store
|
||||
│ │ │ ├── loop.py # 5-layer compression + read/write tool batching
|
||||
│ │ │ ├── context.py # system prompt + auto-recall from persistent memory
|
||||
│ │ │ ├── skills.py # skill loader (72 bundled + user-created via CRUD)
|
||||
│ │ │ ├── tools.py # tool base class + registry
|
||||
│ │ │ ├── memory.py # lightweight workspace state per run
|
||||
│ │ │ ├── frontmatter.py # shared YAML frontmatter parser
|
||||
│ │ │ └── trace.py # execution trace writer
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 21 agent tools
|
||||
│ │ │ ├── backtest_tool.py # run backtests
|
||||
│ │ │ ├── factor_analysis_tool.py
|
||||
│ │ │ ├── options_pricing_tool.py
|
||||
│ │ │ ├── pattern_tool.py # chart pattern detection
|
||||
│ │ │ ├── doc_reader_tool.py # PDF reader (OCR fallback)
|
||||
│ │ │ ├── web_reader_tool.py # web page reader (Jina)
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo web search
|
||||
│ │ │ ├── swarm_tool.py # launch swarm teams
|
||||
│ │ │ └── ... # file I/O, bash, tasks, etc.
|
||||
│ │ ├── memory/ # Cross-session persistent memory
|
||||
│ │ │ └── persistent.py # file-based memory (~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 68 finance skills in 7 categories (SKILL.md each)
|
||||
│ │ ├── tools/ # 27 auto-discovered agent tools
|
||||
│ │ │ ├── backtest_tool.py # run backtests
|
||||
│ │ │ ├── remember_tool.py # cross-session memory (save/recall/forget)
|
||||
│ │ │ ├── skill_writer_tool.py # skill CRUD (save/patch/delete/file)
|
||||
│ │ │ ├── session_search_tool.py # FTS5 cross-session search
|
||||
│ │ │ ├── swarm_tool.py # launch swarm teams
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo web search
|
||||
│ │ │ └── ... # bash, file I/O, factor analysis, options, etc.
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 72 finance skills in 7 categories (SKILL.md each)
|
||||
│ │ ├── swarm/ # Swarm DAG execution engine
|
||||
│ │ ├── session/ # Multi-turn chat session management
|
||||
│ │ │ └── presets/ # 29 swarm preset YAML definitions
|
||||
│ │ ├── session/ # Multi-turn chat + FTS5 session search
|
||||
│ │ └── providers/ # LLM provider abstraction
|
||||
│ │
|
||||
│ ├── backtest/ # Backtest engines
|
||||
│ │ ├── engines/ # 7 engines: china_a, global_equity, crypto, china_futures, global_futures, forex + options_portfolio
|
||||
│ │ ├── loaders/ # 5 sources: tushare, okx, yfinance, akshare, ccxt
|
||||
│ │ │ ├── base.py # DataLoader Protocol
|
||||
│ │ │ └── registry.py # Registry + auto-fallback chains
|
||||
│ │ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│ │
|
||||
│ └── config/swarm/ # 29 swarm preset YAML definitions
|
||||
│ └── backtest/ # Backtest engines
|
||||
│ ├── engines/ # 7 engines + composite cross-market engine + options_portfolio
|
||||
│ ├── loaders/ # 6 sources: tushare, okx, yfinance, akshare, ccxt, futu
|
||||
│ │ ├── base.py # DataLoader Protocol
|
||||
│ │ └── registry.py # Registry + auto-fallback chains
|
||||
│ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│
|
||||
├── frontend/ # Web UI (React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
@@ -581,17 +683,21 @@ Vibe-Trading is part of the **[HKUDS](https://github.com/HKUDS)** agent ecosyste
|
||||
|
||||
| Phase | Feature | Status |
|
||||
|-------|---------|--------|
|
||||
| **Agent Harness** | Persistent cross-session memory (remember / recall / forget) | **Done** |
|
||||
| | Self-evolving skills — agent creates, patches, and deletes its own workflows | **Done** |
|
||||
| | FTS5 cross-session search across all past conversations | **Done** |
|
||||
| | 5-layer context compression (micro → collapse → auto → manual → iterative) | **Done** |
|
||||
| | Read/write tool batching — parallel execution for readonly tools | **Done** |
|
||||
| **Next Up** | Autonomous research loop — agent iterates hypotheses overnight | In Progress |
|
||||
| | IM integration (Slack / Telegram / WeChat) | Planned |
|
||||
| **Analysis & Viz** | Options volatility surface & Greeks 3D visualization | Planned |
|
||||
| | Cross-asset correlation heatmap with rolling window & clustering | Planned |
|
||||
| | Benchmark comparison in CLI backtest output | Planned |
|
||||
| | Calmar Ratio & Omega Ratio in backtest metrics | Planned |
|
||||
| **Skills & Presets** | Dividend Analysis skill | Planned |
|
||||
| | ESG / Sustainable Investing swarm preset | Planned |
|
||||
| | Emerging Markets Research Desk swarm preset | Planned |
|
||||
| **Portfolio & Optimization** | Advanced portfolio optimizer: leverage, sector caps, turnover constraints | Planned |
|
||||
| **Future** | Beginner tutorial: "5-minute natural language backtest" | Planned |
|
||||
| **Future** | Strategy marketplace (share & discover) | Exploring |
|
||||
| | Live data streaming via WebSocket | Exploring |
|
||||
| | Strategy marketplace (share & discover) | Exploring |
|
||||
|
||||
---
|
||||
|
||||
@@ -625,6 +731,12 @@ MIT License — see [LICENSE](LICENSE)
|
||||
|
||||
---
|
||||
|
||||
## Star History
|
||||
|
||||
[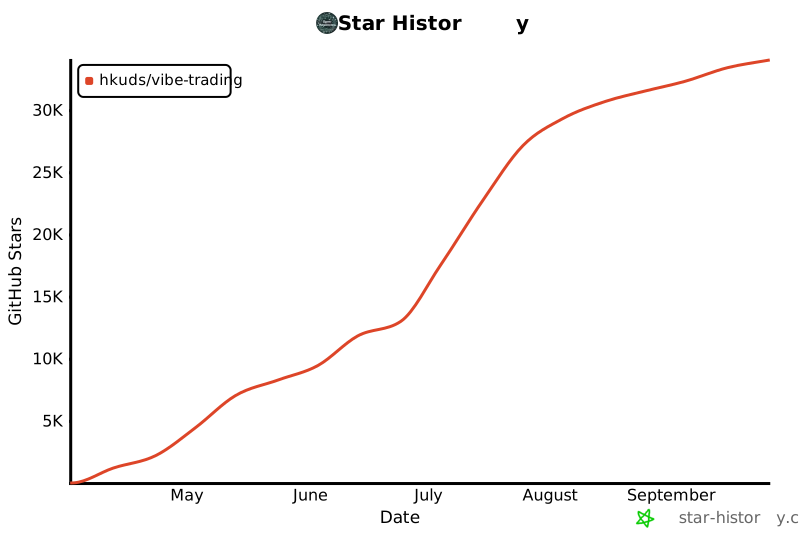](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
Thanks for visiting <b>Vibe-Trading</b> ✨
|
||||
</p>
|
||||
|
||||
+675
@@ -0,0 +1,675 @@
|
||||
<p align="center">
|
||||
<a href="README.md">English</a> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a> | <b>العربية</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<img src="assets/icon.png" width="120" alt="شعار Vibe-Trading"/>
|
||||
</p>
|
||||
|
||||
<h1 align="center">Vibe-Trading: وكيل التداول الشخصي الخاص بك</h1>
|
||||
|
||||
<p align="center">
|
||||
<b>أمر واحد لتمكين وكيلك بقدرات تداول شاملة</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<img src="https://img.shields.io/badge/Python-3.11%2B-3776AB?style=flat&logo=python&logoColor=white" alt="Python">
|
||||
<img src="https://img.shields.io/badge/Backend-FastAPI-009688?style=flat" alt="FastAPI">
|
||||
<img src="https://img.shields.io/badge/Frontend-React%2019-61DAFB?style=flat&logo=react&logoColor=white" alt="React">
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="الرخصة"></a>
|
||||
<br>
|
||||
<img src="https://img.shields.io/badge/Skills-72-orange" alt="المهارات">
|
||||
<img src="https://img.shields.io/badge/Swarm_Presets-29-7C3AED" alt="السرب">
|
||||
<img src="https://img.shields.io/badge/Tools-27-0F766E" alt="الأدوات">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-6-2563EB" alt="مصادر البيانات">
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
<a href="https://discord.gg/2vDYc2w5"><img src="https://img.shields.io/badge/Discord-Join-7289DA?style=flat-square&logo=discord&logoColor=white" alt="Discord"></a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="#-أحدث-الأخبار">الأخبار</a> ·
|
||||
<a href="#-ما-هو-vibe-trading">ما هو</a> ·
|
||||
<a href="#-الميزات-الرئيسية">الميزات</a> ·
|
||||
<a href="#-البدء-السريع">البدء</a> ·
|
||||
<a href="#-مرجع-سطر-الأوامر">CLI</a> ·
|
||||
<a href="#-خادم-api">API</a> ·
|
||||
<a href="#-إضافة-mcp">MCP</a> ·
|
||||
<a href="#-هيكل-المشروع">الهيكل</a> ·
|
||||
<a href="#-خارطة-الطريق">خارطة الطريق</a> ·
|
||||
<a href="#المساهمة">المساهمة</a> ·
|
||||
<a href="#المساهمون">المساهمون</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="#-البدء-السريع"><img src="assets/pip-install.svg" height="45" alt="pip install vibe-trading-ai"></a>
|
||||
</p>
|
||||
|
||||
---
|
||||
|
||||
## 📰 أحدث الأخبار
|
||||
|
||||
- **2026-04-28** 🚀 **إصدار v0.1.6** (`pip install -U vibe-trading-ai`): إصلاح إرجاع `vibe-trading --swarm-presets` فارغًا بعد `pip install` / `uv tool install` ([#55](https://github.com/HKUDS/Vibe-Trading/issues/55)) — ملفات YAML للإعدادات المسبقة الآن مضمّنة داخل حزمة `src.swarm` ومثبّتة بـ 6 اختبارات انحدار. إضافة إلى ذلك، محمّل AKShare يوجّه الآن صناديق ETF (`510300.SH`) والعملات الأجنبية (`USDCNH`) إلى نقاط النهاية الصحيحة مع تعزيز سلسلة البديل. تجميع كل التحديثات منذ v0.1.5: لوحة مقارنة المرجع، تدفق `/upload` + حدود الحجم، محمّل Futu (HK + أسهم A)، مهارة تصدير vnpy، تصليب أمني، التحميل الكسول للواجهة (688KB → 262KB).
|
||||
- **2026-04-27** 📊 **لوحة مقارنة المرجع + أمان الرفع**: مخرجات الاختبار الخلفي تشمل الآن لوحة مقارنة مرجعية (الرمز / عائد المرجع / العائد الفائض / نسبة المعلومات) مع الحلّ عبر yfinance لـ SPY و CSI 300 وغيرها ([#48](https://github.com/HKUDS/Vibe-Trading/issues/48)). إضافة إلى ذلك، نقطة `/upload` تتدفق جسم الطلب في أجزاء 1 ميغابايت وتتوقف فور تجاوز `MAX_UPLOAD_SIZE` مع تنظيف الملف الجزئي، بما يجعل حد 50 ميغابايت فعالاً تحت الطلبات الخبيثة/الضخمة ([#53](https://github.com/HKUDS/Vibe-Trading/pull/53)) — مثبّت بـ 4 اختبارات انحدار.
|
||||
- **2026-04-22** 🛡️ **تصليب + تكاملات جديدة**: فرض احتواء المسار في `safe_path` + عزل أدوات سجل التداول/حساب الظل، إضافة `MANIFEST.in` لتضمين `.env.example` / الاختبارات / ملفات Docker في sdist، التحميل الكسول على مستوى المسار يقلّص حزمة الواجهة الأولية من 688KB إلى 262KB. إضافة محمّل بيانات Futu لأسهم هونغ كونغ وA ([#47](https://github.com/HKUDS/Vibe-Trading/pull/47)) ومهارة تصدير vnpy CtaTemplate ([#46](https://github.com/HKUDS/Vibe-Trading/pull/46)).
|
||||
|
||||
<details>
|
||||
<summary>أخبار سابقة</summary>
|
||||
|
||||
- **2026-04-21** 🛡️ **مساحة العمل + الوثائق**: تطبيع `run_dir` النسبي إلى دليل التشغيل النشط ([#43](https://github.com/HKUDS/Vibe-Trading/pull/43)). إضافة أمثلة استخدام إلى README ([#45](https://github.com/HKUDS/Vibe-Trading/pull/45)).
|
||||
- **2026-04-20** 🔌 **نماذج التفكير + إصلاحات Swarm**: الحفاظ على `reasoning_content` عبر جميع مسارات تسلسل `ChatOpenAI` — يعمل Kimi / DeepSeek / Qwen thinking من البداية إلى النهاية ([#39](https://github.com/HKUDS/Vibe-Trading/issues/39)). تدفق Swarm + إيقاف نظيف بـ Ctrl+C ([#42](https://github.com/HKUDS/Vibe-Trading/issues/42)).
|
||||
- **2026-04-19** 📦 **v0.1.5**: تم النشر على PyPI وClawHub. رفع حد `python-multipart` لسد ثغرة CVE، ربط 5 أدوات MCP جديدة (`analyze_trade_journal` + 4 أدوات حساب الظل)، إصلاح عدم تطابق اسم السجل `pattern_recognition` → `pattern`، مزامنة تبعيات Docker، مزامنة بيان SKILL (22 أداة MCP / 71 مهارة).
|
||||
- **2026-04-18** 👥 **حساب الظل Shadow Account**: استخرج قواعد إستراتيجيتك من سجل التداول الخاص بك → اختبر الظل عبر الأسواق → تقرير HTML/PDF من 8 أقسام يوضح بدقة أين فقدت المال (خرق القواعد، الخروج المبكر، الإشارات المفقودة، الصفقات العكسية). 4 أدوات جديدة، مهارة واحدة جديدة، إجمالي 32 أداة. أمثلة Trade Journal / Shadow Account متاحة الآن في شاشة الترحيب على واجهة الويب.
|
||||
- **2026-04-17** 📊 **محلل سجل التداول + قارئ ملفات عالمي**: حمّل سجلات التداول من الوسطاء (同花顺/东财/富途/CSV عام) → ملف تعريف تداول تلقائي (أيام الاحتفاظ، معدل الفوز، نسبة الربح/الخسارة، أقصى تراجع) + تشخيص 4 تحيزات سلوكية (تأثير التصرف، الإفراط في التداول، مطاردة الزخم، التثبيت السعري). `read_document` يوزّع الآن PDF وWord وExcel وPowerPoint والصور (OCR) و40+ صيغة نصية خلف استدعاء موحد.
|
||||
- **2026-04-16** 🧠 **هيكل الوكيل**: ذاكرة دائمة عبر الجلسات، بحث جلسات FTS5، مهارات ذاتية التطور (CRUD كامل)، ضغط سياق 5 طبقات، معالجة أدوات القراءة/الكتابة دفعة واحدة. 27 أداة، 107 اختبار جديد.
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**: إضافة مزود Z.ai ([#35](https://github.com/HKUDS/Vibe-Trading/pull/35))، إصلاح temperature وتحديث نموذج MiniMax ([#33](https://github.com/HKUDS/Vibe-Trading/pull/33)). 13 مزوداً.
|
||||
- **2026-04-14** 🔧 **استقرار MCP**: إصلاح خطأ `Connection closed` في أداة الاختبار الرجعي عبر نقل stdio ([#32](https://github.com/HKUDS/Vibe-Trading/pull/32)).
|
||||
- **2026-04-13** 🌐 **الاختبار الرجعي المركب عبر الأسواق**: محرك `CompositeEngine` الجديد لاختبار محافظ متعددة الأسواق (مثل أسهم A + العملات المشفرة) بمجمع رأسمال مشترك. إصلاح متغيرات قوالب Swarm ومهلة الواجهة الأمامية.
|
||||
- **2026-04-12** 🌍 **تصدير متعدد المنصات**: أمر `/pine` يصدّر إلى TradingView (Pine Script v6) وTDX (通达信/同花顺/东方财富) وMetaTrader 5 (MQL5) دفعة واحدة.
|
||||
- **2026-04-11** 🛡️ **الموثوقية وDX**: إعداد `.env` عبر `vibe-trading init` ([#19](https://github.com/HKUDS/Vibe-Trading/pull/19))، فحوصات مسبقة، بديل تلقائي لمصادر البيانات، تعزيز محرك الاختبار الرجعي. README متعدد اللغات ([#21](https://github.com/HKUDS/Vibe-Trading/pull/21)).
|
||||
- **2026-04-10** 📦 **v0.1.4**: إصلاح Docker ([#8](https://github.com/HKUDS/Vibe-Trading/issues/8))، أداة MCP `web_search`، 12 مزود LLM، تبعيات `akshare`/`ccxt`. النشر على PyPI وClawHub.
|
||||
- **2026-04-09** 📊 **الموجة الثانية من الاختبار الرجعي**: محركات ChinaFutures وGlobalFutures وForex وOptions v2. تحقق مونت كارلو وBootstrap CI وWalk-Forward.
|
||||
- **2026-04-08** 🔧 **اختبار رجعي متعدد الأسواق**: قواعد خاصة بكل سوق، تصدير Pine Script v6، 5 مصادر بيانات مع بديل تلقائي.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 💡 ما هو Vibe-Trading؟
|
||||
|
||||
Vibe-Trading هو مساحة عمل مالية متعددة الوكلاء مدعومة بالذكاء الاصطناعي تحول الطلبات بلغة طبيعية إلى استراتيجيات تداول قابلة للتنفيذ ورؤى بحثية وتحليل محافظ عبر الأسواق العالمية.
|
||||
|
||||
### القدرات الرئيسية:
|
||||
• **لغة طبيعية → استراتيجية** — صِف فكرتك؛ الوكيل يكتب الكود ويختبره ويصدّره<br>
|
||||
• **6 مصادر بيانات، بدون إعداد** — أسهم A، HK/US، العملات المشفرة، العقود الآجلة، الفوركس مع بديل تلقائي<br>
|
||||
• **29 فريق خبراء** — سير عمل سرب متعدد الوكلاء للاستثمار والتداول وإدارة المخاطر<br>
|
||||
• **ذاكرة عبر الجلسات** — يتذكر التفضيلات والرؤى؛ ينشئ ويطور المهارات القابلة لإعادة الاستخدام<br>
|
||||
• **7 محركات اختبار رجعي** — اختبار مركب عبر الأسواق + تحقق إحصائي + 4 محسّنات<br>
|
||||
• **تصدير متعدد المنصات** — نقرة واحدة إلى TradingView وTDX وMetaTrader 5
|
||||
|
||||
---
|
||||
|
||||
## ✨ الميزات الرئيسية
|
||||
|
||||
<table width="100%">
|
||||
<tr>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-research.png" height="150" alt="البحث"/><br>
|
||||
<h3>🔍 بحث عميق للتداول</h3>
|
||||
<img src="https://img.shields.io/badge/72_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="المهارات" /><br><br>
|
||||
<div align="left" style="font-size: 4px;">
|
||||
• 72 مهارة متخصصة مع ذاكرة دائمة عبر الجلسات<br>
|
||||
• تطور ذاتي: الوكيل ينشئ ويحسّن سير العمل من التجربة<br>
|
||||
• ضغط سياق 5 طبقات — بلا فقدان معلومات في المحادثات الطويلة<br>
|
||||
• توجيه المهام بلغة طبيعية عبر جميع المجالات المالية
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-swarm.png" height="150" alt="السرب"/><br>
|
||||
<h3>🐝 ذكاء السرب</h3>
|
||||
<img src="https://img.shields.io/badge/29_Trading_Teams-4ECDC4?style=for-the-badge&logo=hive&logoColor=white" alt="السرب" /><br><br>
|
||||
<div align="left">
|
||||
• 29 إعداد مسبق لفرق التداول الجاهزة<br>
|
||||
• تنسيق متعدد الوكلاء قائم على DAG<br>
|
||||
• لوحة معلومات بث مباشر مع حالة الوكلاء الحية<br>
|
||||
• بحث FTS5 عبر الجلسات في جميع المحادثات السابقة
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-backtest.png" height="150" alt="الاختبار الرجعي"/><br>
|
||||
<h3>📊 اختبار رجعي عبر الأسواق</h3>
|
||||
<img src="https://img.shields.io/badge/5_Data_Sources-FFD93D?style=for-the-badge&logo=bitcoin&logoColor=black" alt="الاختبار الرجعي" /><br><br>
|
||||
<div align="left">
|
||||
• أسهم A، أسهم HK/US، العملات المشفرة، العقود الآجلة والفوركس<br>
|
||||
• 7 محركات سوق: أسهم A، أسهم US/HK، العملات المشفرة، العقود الآجلة الصينية، العقود الآجلة العالمية، الفوركس<br>
|
||||
• التحقق الإحصائي: مونت كارلو، Bootstrap CI، المشي للأمام<br>
|
||||
• 15+ مقياس أداء و4 محسّنات
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-quant.png" height="150" alt="الكمي"/><br>
|
||||
<h3>🧮 أدوات التحليل الكمي</h3>
|
||||
<img src="https://img.shields.io/badge/Quant_Tools-C77DFF?style=for-the-badge&logo=wolfram&logoColor=white" alt="الكمي" /><br><br>
|
||||
<div align="left">
|
||||
• تحليل العامل IC/IR والاختبار الرجعي للشرائح<br>
|
||||
• تسعير Black-Scholes وحساب كامل للمتغيرات اليونانية<br>
|
||||
• التعرف على الأنماط الفنية واكتشافها<br>
|
||||
• تحسين المحافظ عبر MVO/Risk Parity/BL
|
||||
</div>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## 72 مهارة عبر 7 فئات
|
||||
|
||||
- 📊 72 مهارة مالية متخصصة منظمة في 7 فئات
|
||||
- 🌐 تغطية شاملة من الأسواق التقليدية إلى العملات المشفرة وDeFi
|
||||
- 🔬 قدرات شاملة تمتد من مصادر البيانات إلى البحث الكمي
|
||||
|
||||
| الفئة | المهارات | أمثلة |
|
||||
|----------|--------|----------|
|
||||
| مصدر البيانات | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| الاستراتيجية | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| التحليل | 15 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis` |
|
||||
| فئة الأصول | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| العملات المشفرة | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
| التدفقات | 7 | `hk-connect-flow`, `us-etf-flow`, `edgar-sec-filings`, `financial-statement`, `adr-hshare` |
|
||||
| الأدوات | 8 | `backtest-diagnose`, `report-generate`, `pine-script`, `doc-reader`, `web-reader` |
|
||||
|
||||
## 29 إعداد مسبق لفرق وكلاء السرب
|
||||
|
||||
- 🏢 29 فرق وكلاء جاهزة للاستخدام
|
||||
- ⚡ سير عمل مالية مُعدة مسبقاً
|
||||
- 🎯 إعدادات مسبقة للاستثمار والتداول وإدارة المخاطر
|
||||
|
||||
| الإعداد المسبق | سير العمل |
|
||||
|--------|----------|
|
||||
| `investment_committee` | مناظرة صعود/هبوط ← مراجعة مخاطر ← قرار مدير المحفظة النهائي |
|
||||
| `global_equities_desk` | باحث أسهم A + HK/US + العملات المشفرة ← استراتيجي عالمي |
|
||||
| `crypto_trading_desk` | التمويل/الأساس + التصفية + التدفق ← مدير مخاطر |
|
||||
| `earnings_research_desk` | أساسي + مراجعة + خيارات ← استراتيجي الأرباح |
|
||||
| `macro_rates_fx_desk` | أسعار الفائدة + الفوركس + السلع ← مدير محفظة كلية |
|
||||
| `quant_strategy_desk` | فرز + بحث العوامل ← اختبار رجعي ← تدقيق مخاطر |
|
||||
| `technical_analysis_panel` | TA كلاسيكي + إيشيموكو + هارمونيك + إليوت + SMC ← إجماع |
|
||||
| `risk_committee` | السحب + مخاطر الذيل + مراجعة النظام ← موافقة |
|
||||
| `global_allocation_committee` | أسهم A + عملات مشفرة + HK/US ← تخصيص عبر الأسواق |
|
||||
|
||||
<sub>بالإضافة إلى 20+ إعداد مسبق متخصص إضافي — شغّل vibe-trading --swarm-presets لاستكشافها جميعاً.
|
||||
|
||||
</sub>
|
||||
|
||||
### 🎬 عرض توضيحي
|
||||
|
||||
<div align="center">
|
||||
<table>
|
||||
<tr>
|
||||
<td width="50%">
|
||||
|
||||
https://github.com/user-attachments/assets/4e4dcb80-7358-4b9a-92f0-1e29612e6e86
|
||||
|
||||
</td>
|
||||
<td width="50%">
|
||||
|
||||
https://github.com/user-attachments/assets/3754a414-c3ee-464f-b1e8-78e1a74fbd30
|
||||
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td colspan="2" align="center"><sub>☝️ اختبار رجعي بلغة طبيعية ومناظرة سرب متعدد الوكلاء — واجهة ويب + CLI</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 🚀 البدء السريع
|
||||
|
||||
### تثبيت بسطر واحد (PyPI)
|
||||
|
||||
```bash
|
||||
pip install vibe-trading-ai
|
||||
```
|
||||
|
||||
> **اسم الحزمة مقابل الأوامر:** حزمة PyPI هي `vibe-trading-ai`. بعد التثبيت، ستحصل على ثلاثة أوامر:
|
||||
>
|
||||
> | الأمر | الغرض |
|
||||
> |---------|---------|
|
||||
> | `vibe-trading` | CLI تفاعلي / TUI |
|
||||
> | `vibe-trading serve` | تشغيل خادم ويب FastAPI |
|
||||
> | `vibe-trading-mcp` | بدء خادم MCP (لـ Claude Desktop, OpenClaw, Cursor, إلخ) |
|
||||
|
||||
```bash
|
||||
vibe-trading init # إعداد تفاعلي لملف .env
|
||||
vibe-trading # تشغيل CLI
|
||||
vibe-trading serve --port 8899 # تشغيل واجهة الويب
|
||||
vibe-trading-mcp # بدء خادم MCP (stdio)
|
||||
```
|
||||
|
||||
### أو اختر مساراً
|
||||
|
||||
| المسار | الأنسب لـ | الوقت |
|
||||
|------|----------|------|
|
||||
| **A. Docker** | تجربته الآن، بدون إعداد محلي | دقيقتان |
|
||||
| **B. تثبيت محلي** | التطوير، وصول كامل لـ CLI | 5 دقائق |
|
||||
| **C. إضافة MCP** | ربطه بوكيلك الحالي | 3 دقائق |
|
||||
| **D. ClawHub** | أمر واحد، بدون استنساخ | دقيقة واحدة |
|
||||
|
||||
### المتطلبات المسبقة
|
||||
|
||||
- **مفتاح API لنموذج لغة** من أي مزود مدعوم — أو التشغيل محلياً مع **Ollama** (بدون مفتاح)
|
||||
- **Python 3.11+** للمسار B
|
||||
- **Docker** للمسار A
|
||||
|
||||
> **مزودو نماذج اللغة المدعومون:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Z.ai, Ollama (محلي). راجع `.env.example` للإعدادات.
|
||||
|
||||
> **نصيحة:** جميع الأسواق تعمل بدون أي مفاتيح API بفضل البديل التلقائي. yfinance (HK/US) و OKX (العملات المشفرة) و AKShare (أسهم A، US، HK، العقود الآجلة، الفوركس) جميعها مجانية. رمز Tushare اختياري — AKShare يغطي أسهم A كبديل مجاني.
|
||||
|
||||
### المسار A: Docker (بدون إعداد)
|
||||
|
||||
```bash
|
||||
git clone https://github.com/HKUDS/Vibe-Trading.git
|
||||
cd Vibe-Trading
|
||||
cp agent/.env.example agent/.env
|
||||
# عدّل agent/.env — أزل التعليق عن مزود نموذج اللغة وحدد مفتاح API
|
||||
docker compose up --build
|
||||
```
|
||||
|
||||
افتح `http://localhost:8899`. الخلفية + الواجهة الأمامية في حاوية واحدة.
|
||||
|
||||
### المسار B: التثبيت المحلي
|
||||
|
||||
```bash
|
||||
git clone https://github.com/HKUDS/Vibe-Trading.git
|
||||
cd Vibe-Trading
|
||||
python -m venv .venv
|
||||
|
||||
# التفعيل
|
||||
source .venv/bin/activate # Linux / macOS
|
||||
# .venv\Scripts\Activate.ps1 # Windows PowerShell
|
||||
|
||||
pip install -e .
|
||||
cp agent/.env.example agent/.env # عدّل — حدد مفتاح API لمزود نموذج اللغة
|
||||
vibe-trading # تشغيل TUI التفاعلي
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary><b>تشغيل واجهة الويب (اختياري)</b></summary>
|
||||
|
||||
```bash
|
||||
# الطرفية 1: خادم API
|
||||
vibe-trading serve --port 8899
|
||||
|
||||
# الطرفية 2: خادم تطوير الواجهة الأمامية
|
||||
cd frontend && npm install && npm run dev
|
||||
```
|
||||
|
||||
افتح `http://localhost:5899`. تعيد الواجهة الأمامية توجيه استدعاءات API إلى `localhost:8899`.
|
||||
|
||||
**وضع الإنتاج (خادم واحد):**
|
||||
|
||||
```bash
|
||||
cd frontend && npm run build && cd ..
|
||||
vibe-trading serve --port 8899 # يخدم FastAPI مجلد dist/ كملفات ثابتة
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### المسار C: إضافة MCP
|
||||
|
||||
راجع قسم [إضافة MCP](#-إضافة-mcp) أدناه.
|
||||
|
||||
### المسار D: ClawHub (أمر واحد)
|
||||
|
||||
```bash
|
||||
npx clawhub@latest install vibe-trading --force
|
||||
```
|
||||
|
||||
يتم تنزيل المهارة + إعدادات MCP إلى مجلد مهارات وكيلك. راجع [تثبيت ClawHub](#-إضافة-mcp) للتفاصيل.
|
||||
|
||||
---
|
||||
|
||||
## 🧠 متغيرات البيئة
|
||||
|
||||
انسخ `agent/.env.example` إلى `agent/.env` وأزل التعليق عن كتلة المزود التي تريدها. كل مزود يحتاج إلى 3-4 متغيرات:
|
||||
|
||||
| المتغير | مطلوب | الوصف |
|
||||
|----------|:--------:|-------------|
|
||||
| `LANGCHAIN_PROVIDER` | نعم | اسم المزود (`openrouter`, `deepseek`, `groq`, `z.ai`, `ollama`, إلخ) |
|
||||
| `<PROVIDER>_API_KEY` | نعم* | مفتاح API (`OPENROUTER_API_KEY`, `DEEPSEEK_API_KEY`, إلخ) |
|
||||
| `<PROVIDER>_BASE_URL` | نعم | رابط نقطة نهاية API |
|
||||
| `LANGCHAIN_MODEL_NAME` | نعم | اسم النموذج (مثلاً `deepseek/deepseek-v3.2`) |
|
||||
| `TUSHARE_TOKEN` | لا | رمز Tushare Pro لبيانات أسهم A (بديل AKShare) |
|
||||
| `TIMEOUT_SECONDS` | لا | مهلة استدعاء نموذج اللغة، الافتراضي 120 ثانية |
|
||||
|
||||
<sub>* Ollama لا يتطلب مفتاح API.</sub>
|
||||
|
||||
**بيانات مجانية (بدون مفتاح):** أسهم A عبر AKShare، أسهم HK/US عبر yfinance، العملات المشفرة عبر OKX، 100+ بورصة عملات مشفرة عبر CCXT. يختار النظام تلقائياً أفضل مصدر متاح لكل سوق.
|
||||
|
||||
### 🎯 النماذج الموصى بها
|
||||
|
||||
Vibe-Trading وكيل يعتمد بكثافة على استدعاءات الأدوات — المهارات والاختبار الخلفي والذاكرة و swarm كلها تعمل عبر tool calls. اختيار النموذج يحدد مباشرة ما إذا كان الوكيل **يستخدم أدواته فعلاً** أو يلفّق الإجابات من بيانات التدريب.
|
||||
|
||||
| المستوى | أمثلة | متى يُستخدم |
|
||||
|---------|-------|-------------|
|
||||
| **الأفضل** | `anthropic/claude-opus-4.7`، `anthropic/claude-sonnet-4.6`، `openai/gpt-5.4`، `google/gemini-3.1-pro-preview` | swarm معقد (3+ وكلاء)، جلسات بحث طويلة، تحليل بمستوى ورقة علمية |
|
||||
| **نقطة مثلى** (افتراضي) | `deepseek/deepseek-v3.2`، `x-ai/grok-4.20`، `z-ai/glm-5.1`، `moonshotai/kimi-k2.5`، `qwen/qwen3-max-thinking` | الاستخدام اليومي — tool-calling موثوق بحوالي 1/10 من التكلفة |
|
||||
| **تجنّب كوكيل** | `*-nano`، `*-flash-lite`، `*-coder-next`، إصدارات صغيرة / مُقطّرة | tool-calling غير موثوق — سيبدو الوكيل وكأنه "يجيب من الذاكرة" بدلاً من تحميل المهارات أو تشغيل الاختبار الخلفي |
|
||||
|
||||
يأتي `agent/.env.example` الافتراضي مع `deepseek/deepseek-v3.2` — الخيار الأرخص في مستوى النقطة المثلى.
|
||||
|
||||
---
|
||||
|
||||
## 🖥 مرجع سطر الأوامر
|
||||
|
||||
```bash
|
||||
vibe-trading # TUI تفاعلي
|
||||
vibe-trading run -p "..." # تشغيل واحد
|
||||
vibe-trading serve # خادم API
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary><b>أوامر الشرطة المائلة داخل TUI</b></summary>
|
||||
|
||||
| الأمر | الوصف |
|
||||
|---------|-------------|
|
||||
| `/help` | عرض جميع الأوامر |
|
||||
| `/skills` | عرض جميع مهارات التداول الـ 69 |
|
||||
| `/swarm` | عرض إعدادات فرق السرب الـ 29 |
|
||||
| `/swarm run <preset> [vars_json]` | تشغيل فريق سرب مع بث مباشر |
|
||||
| `/swarm list` | سجل تشغيلات السرب |
|
||||
| `/swarm show <run_id>` | تفاصيل تشغيل السرب |
|
||||
| `/swarm cancel <run_id>` | إلغاء سرب قيد التشغيل |
|
||||
| `/list` | التشغيلات الأخيرة |
|
||||
| `/show <run_id>` | تفاصيل التشغيل + المقاييس |
|
||||
| `/code <run_id>` | كود الاستراتيجية المولّدة |
|
||||
| `/pine <run_id>` | Pine Script لـ TradingView |
|
||||
| `/trace <run_id>` | إعادة تشغيل التنفيذ الكاملة |
|
||||
| `/continue <run_id> <prompt>` | متابعة تشغيل بتعليمات جديدة |
|
||||
| `/sessions` | عرض جلسات الدردشة |
|
||||
| `/settings` | عرض إعدادات التشغيل |
|
||||
| `/clear` | مسح الشاشة |
|
||||
| `/quit` | الخروج |
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>التشغيل الفردي والعلامات</b></summary>
|
||||
|
||||
```bash
|
||||
vibe-trading run -p "اختبر استراتيجية BTC-USDT MACD رجعياً، آخر 30 يوماً"
|
||||
vibe-trading run -p "حلل زخم AAPL" --json
|
||||
vibe-trading run -f strategy.txt
|
||||
echo "اختبر 000001.SZ RSI رجعياً" | vibe-trading run
|
||||
```
|
||||
|
||||
```bash
|
||||
vibe-trading -p "طلبك"
|
||||
vibe-trading --skills
|
||||
vibe-trading --swarm-presets
|
||||
vibe-trading --swarm-run investment_committee '{"topic":"توقعات BTC"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # Pine Script لـ TradingView
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "حسّن الاستراتيجية"
|
||||
vibe-trading --upload report.pdf
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 🌐 خادم API
|
||||
|
||||
```bash
|
||||
vibe-trading serve --port 8899
|
||||
```
|
||||
|
||||
| الطريقة | نقطة النهاية | الوصف |
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | عرض التشغيلات |
|
||||
| `GET` | `/runs/{run_id}` | تفاصيل التشغيل |
|
||||
| `GET` | `/runs/{run_id}/pine` | تصدير Pine Script |
|
||||
| `POST` | `/sessions` | إنشاء جلسة |
|
||||
| `POST` | `/sessions/{id}/messages` | إرسال رسالة |
|
||||
| `GET` | `/sessions/{id}/events` | بث أحداث SSE |
|
||||
| `POST` | `/upload` | رفع PDF/ملف |
|
||||
| `GET` | `/swarm/presets` | عرض إعدادات السرب |
|
||||
| `POST` | `/swarm/runs` | بدء تشغيل سرب |
|
||||
| `GET` | `/swarm/runs/{id}/events` | بث SSE للسرب |
|
||||
|
||||
توثيق تفاعلي: `http://localhost:8899/docs`
|
||||
|
||||
---
|
||||
|
||||
## 🔌 إضافة MCP
|
||||
|
||||
يقدم Vibe-Trading 22 أداة MCP لأي عميل متوافق مع MCP. يعمل كعملية فرعية stdio — بدون إعداد خادم. **21 من 22 أداة تعمل بدون مفاتيح API** (HK/US/العملات المشفرة). فقط `run_swarm` يحتاج إلى مفتاح نموذج لغة.
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
|
||||
أضف إلى `claude_desktop_config.json`:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"vibe-trading": {
|
||||
"command": "vibe-trading-mcp"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>OpenClaw</b></summary>
|
||||
|
||||
أضف إلى `~/.openclaw/config.yaml`:
|
||||
|
||||
```yaml
|
||||
skills:
|
||||
- name: vibe-trading
|
||||
command: vibe-trading-mcp
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Cursor / Windsurf / عملاء MCP الآخرين</b></summary>
|
||||
|
||||
```bash
|
||||
vibe-trading-mcp # stdio (الافتراضي)
|
||||
vibe-trading-mcp --transport sse # SSE لعملاء الويب
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
**أدوات MCP المتاحة (22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
|
||||
<details>
|
||||
<summary><b>التثبيت من ClawHub (أمر واحد)</b></summary>
|
||||
|
||||
```bash
|
||||
npx clawhub@latest install vibe-trading --force
|
||||
```
|
||||
|
||||
> `--force` مطلوب لأن المهارة تشير إلى واجهات برمجية خارجية، مما يؤدي إلى فحص تلقائي من VirusTotal. الكود مفتوح المصدر بالكامل وآمن للفحص.
|
||||
|
||||
هذا ينزّل المهارة + إعدادات MCP إلى مجلد مهارات وكيلك. بدون الحاجة للاستنساخ.
|
||||
|
||||
تصفح على ClawHub: [clawhub.ai/skills/vibe-trading](https://clawhub.ai/skills/vibe-trading)
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>OpenSpace — مهارات ذاتية التطور</b></summary>
|
||||
|
||||
جميع مهارات التداول الـ 69 منشورة على [open-space.cloud](https://open-space.cloud) وتتطور بشكل مستقل عبر محرك التطور الذاتي من OpenSpace.
|
||||
|
||||
للاستخدام مع OpenSpace، أضف خادمي MCP إلى إعدادات وكيلك:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"openspace": {
|
||||
"command": "openspace-mcp",
|
||||
"toolTimeout": 600,
|
||||
"env": {
|
||||
"OPENSPACE_HOST_SKILL_DIRS": "/path/to/vibe-trading/agent/src/skills",
|
||||
"OPENSPACE_WORKSPACE": "/path/to/OpenSpace"
|
||||
}
|
||||
},
|
||||
"vibe-trading": {
|
||||
"command": "vibe-trading-mcp"
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
سيكتشف OpenSpace تلقائياً جميع المهارات الـ 69، مما يتيح الإصلاح التلقائي والتحسين التلقائي والمشاركة المجتمعية. ابحث عن مهارات Vibe-Trading عبر `search_skills("finance backtest")` في أي وكيل متصل بـ OpenSpace.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 📁 هيكل المشروع
|
||||
|
||||
<details>
|
||||
<summary><b>انقر للتوسيع</b></summary>
|
||||
|
||||
```
|
||||
Vibe-Trading/
|
||||
├── agent/ # الخلفية (Python)
|
||||
│ ├── cli.py # نقطة دخول CLI — TUI تفاعلي + أوامر فرعية
|
||||
│ ├── api_server.py # خادم FastAPI — تشغيلات، جلسات، رفع، سرب، SSE
|
||||
│ ├── mcp_server.py # خادم MCP — 22 أداة لـ OpenClaw / Claude Desktop
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # نواة وكيل ReAct
|
||||
│ │ │ ├── loop.py # ضغط 5 طبقات + معالجة أدوات القراءة/الكتابة دفعة واحدة
|
||||
│ │ │ ├── context.py # موجه النظام + استرجاع تلقائي من الذاكرة الدائمة
|
||||
│ │ │ ├── skills.py # محمل المهارات (69 مدمجة + إنشاء CRUD من المستخدم)
|
||||
│ │ │ ├── tools.py # فئة الأدوات الأساسية + السجل
|
||||
│ │ │ ├── memory.py # حالة مساحة عمل خفيفة لكل تشغيل
|
||||
│ │ │ ├── frontmatter.py # محلل YAML frontmatter مشترك
|
||||
│ │ │ └── trace.py # كاتب أثر التنفيذ
|
||||
│ │ │
|
||||
│ │ ├── memory/ # ذاكرة دائمة عبر الجلسات
|
||||
│ │ │ └── persistent.py # ذاكرة قائمة على الملفات (~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 27 أداة وكيل مكتشفة تلقائياً
|
||||
│ │ │ ├── backtest_tool.py # تشغيل الاختبارات الرجعية
|
||||
│ │ │ ├── remember_tool.py # ذاكرة عبر الجلسات (حفظ/استرجاع/نسيان)
|
||||
│ │ │ ├── skill_writer_tool.py # CRUD للمهارات (حفظ/تصحيح/حذف/ملف)
|
||||
│ │ │ ├── session_search_tool.py # بحث FTS5 عبر الجلسات
|
||||
│ │ │ ├── swarm_tool.py # إطلاق فرق السرب
|
||||
│ │ │ ├── web_search_tool.py # بحث ويب DuckDuckGo
|
||||
│ │ │ └── ... # bash، إدخال/إخراج ملف، تحليل العوامل، الخيارات، إلخ
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 72 مهارة مالية في 7 فئات (SKILL.md لكل منها)
|
||||
│ │ ├── swarm/ # محرك تنفيذ DAG للسرب
|
||||
│ │ │ └── presets/ # 29 تعريف YAML للإعدادات المسبقة للسرب
|
||||
│ │ ├── session/ # دردشة متعددة الأدوار + بحث FTS5 عبر الجلسات
|
||||
│ │ └── providers/ # تجريد مزود نموذج اللغة
|
||||
│ │
|
||||
│ └── backtest/ # محركات الاختبار الرجعي
|
||||
│ ├── engines/ # 7 محركات + محرك مركب عبر الأسواق + options_portfolio
|
||||
│ ├── loaders/ # 6 مصادر: tushare, okx, yfinance, akshare, ccxt, futu
|
||||
│ │ ├── base.py # بروتوكول DataLoader
|
||||
│ │ └── registry.py # السجل + سلاسل البديل التلقائي
|
||||
│ └── optimizers/ # MVO، تساوي التقلب، أقصى تنويع، تكافؤ المخاطر
|
||||
│
|
||||
├── frontend/ # واجهة الويب (React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
│ ├── pages/ # الرئيسية، الوكيل، تفاصيل التشغيل، المقارنة
|
||||
│ ├── components/ # دردشة، رسوم بيانية، تخطيط
|
||||
│ └── stores/ # إدارة حالة Zustand
|
||||
│
|
||||
├── Dockerfile # بناء متعدد المراحل
|
||||
├── docker-compose.yml # نشر بأمر واحد
|
||||
├── pyproject.toml # إعدادات الحزمة + نقطة دخول CLI
|
||||
└── LICENSE # MIT
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 🏛 النظام البيئي
|
||||
|
||||
Vibe-Trading هو جزء من النظام البيئي للوكلاء **[HKUDS](https://github.com/HKUDS)**:
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/ClawTeam"><b>ClawTeam</b></a><br>
|
||||
<sub>ذكاء سرب الوكلاء</sub>
|
||||
</td>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/nanobot"><b>NanoBot</b></a><br>
|
||||
<sub>مساعد ذكاء اصطناعي شخصي فائق الخفة</sub>
|
||||
</td>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/CLI-Anything"><b>CLI-Anything</b></a><br>
|
||||
<sub>جعل جميع البرامج أصلية للوكلاء</sub>
|
||||
</td>
|
||||
<td align="center" width="25%">
|
||||
<a href="https://github.com/HKUDS/OpenSpace"><b>OpenSpace</b></a><br>
|
||||
<sub>مهارات وكلاء ذكاء اصطناعي ذاتية التطور</sub>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
---
|
||||
|
||||
## 🗺 خارطة الطريق
|
||||
|
||||
> نشحن على مراحل. تنتقل العناصر إلى [المشكلات](https://github.com/HKUDS/Vibe-Trading/issues) عند بدء العمل.
|
||||
|
||||
| المرحلة | الميزة | الحالة |
|
||||
|-------|---------|--------|
|
||||
| **هيكل الوكيل** | ذاكرة دائمة عبر الجلسات (حفظ / استرجاع / نسيان) | **تم** |
|
||||
| | مهارات ذاتية التطور — الوكيل ينشئ ويعدل ويحذف سير العمل بنفسه | **تم** |
|
||||
| | بحث FTS5 عبر الجلسات في جميع المحادثات السابقة | **تم** |
|
||||
| | ضغط سياق 5 طبقات (micro → collapse → auto → manual → iterative) | **تم** |
|
||||
| | معالجة أدوات القراءة/الكتابة دفعة واحدة — تنفيذ موازٍ للأدوات للقراءة فقط | **تم** |
|
||||
| **التالي** | حلقة بحث مستقلة — الوكيل يكرر الفرضيات طوال الليل | قيد التنفيذ |
|
||||
| | تكامل المراسلة (Slack / Telegram / WeChat) | مخطط |
|
||||
| **التحليل والتصور** | سطح التقلب للخيارات والمتغيرات اليونانية مع تصور ثلاثي الأبعاد | مخطط |
|
||||
| | خريطة حرارة الارتباط عبر الأصول مع نافذة متدحرجة وتجميع | مخطط |
|
||||
| | مقارنة المعيار في مخرجات الاختبار الرجعي لـ CLI | مخطط |
|
||||
| **المهارات والإعدادات المسبقة** | مهارة تحليل الأرباح | مخطط |
|
||||
| | إعداد سرب مسبق للاستثمار المستدام / ESG | مخطط |
|
||||
| **المحافظ والتحسين** | محسّن محافظ متقدم: الرافعة المالية، حدود القطاعات، قيود التداول | مخطط |
|
||||
| **المستقبل** | سوق الاستراتيجيات (مشاركة واكتشاف) | قيد الاستكشاف |
|
||||
| | بث بيانات مباشر عبر WebSocket | قيد الاستكشاف |
|
||||
|
||||
---
|
||||
|
||||
## المساهمة
|
||||
|
||||
نرحب بالمساهمات! راجع [CONTRIBUTING.md](CONTRIBUTING.md) للإرشادات.
|
||||
|
||||
**المشكلات الجيدة للمبتدئين** محددة بعلامة [`good first issue`](https://github.com/HKUDS/Vibe-Trading/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22) — اختر واحدة وابدأ.
|
||||
|
||||
ترغب في المساهمة بشيء أكبر؟ راجع [خارطة الطريق](#-خارطة-الطريق) أعلاه وافتح مشكلة للمناقشة قبل البدء.
|
||||
|
||||
---
|
||||
|
||||
## المساهمون
|
||||
|
||||
شكراً لكل من ساهم في Vibe-Trading!
|
||||
|
||||
<a href="https://github.com/HKUDS/Vibe-Trading/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=HKUDS/Vibe-Trading" />
|
||||
</a>
|
||||
|
||||
---
|
||||
|
||||
## إخلاء المسؤولية
|
||||
|
||||
Vibe-Trading مخصص للبحث والمحاكاة والاختبار الرجعي فقط. وهو ليس نصيحة استثمارية ولا ينفذ صفقات حية. الأداء السابق لا يضمن النتائج المستقبلية.
|
||||
|
||||
## الرخصة
|
||||
|
||||
رخصة MIT — راجع [LICENSE](LICENSE)
|
||||
|
||||
---
|
||||
|
||||
## تاريخ النجوم
|
||||
|
||||
[](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
شكراً لزيارتك <b>Vibe-Trading</b> ✨
|
||||
</p>
|
||||
<p align="center">
|
||||
<img src="https://visitor-badge.laobi.icu/badge?page_id=HKUDS.Vibe-Trading&style=flat" alt="الزوار"/>
|
||||
</p>
|
||||
+106
-64
@@ -1,5 +1,5 @@
|
||||
<p align="center">
|
||||
<a href="README.md">English</a> | <a href="README_zh.md">中文</a> | <b>日本語</b> | <a href="README_ko.md">한국어</a>
|
||||
<a href="README.md">English</a> | <a href="README_zh.md">中文</a> | <b>日本語</b> | <a href="README_ko.md">한국어</a> | <a href="README_ar.md">العربية</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -19,10 +19,10 @@
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="License"></a>
|
||||
<br>
|
||||
<img src="https://img.shields.io/badge/Skills-68-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Skills-72-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Swarm_Presets-29-7C3AED" alt="Swarm">
|
||||
<img src="https://img.shields.io/badge/Tools-21-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-5-2563EB" alt="Data Sources">
|
||||
<img src="https://img.shields.io/badge/Tools-27-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-6-2563EB" alt="Data Sources">
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
@@ -51,10 +51,29 @@
|
||||
|
||||
## 📰 ニュース
|
||||
|
||||
- **2026-04-10** 📦 **v0.1.4**: Dockerビルドを修正([#8](https://github.com/HKUDS/Vibe-Trading/issues/8))、`web_search` MCPツールを追加(合計17)、依存関係とMCPに`akshare`/`ccxt`を追加。11のLLMプロバイダー(DeepSeek, Groq, Gemini, Ollama など)、すべての調整パラメータを`.env`で設定可能。`ml-strategy`スキルを強化。PyPIとClawHubに公開。
|
||||
- **2026-04-09** 📊 **Backtest Wave 2 — マルチアセットエンジン**: ChinaFutures(CFFEX/SHFE/DCE/ZCE、50+銘柄)、GlobalFutures(CME/ICE/Eurex、30+銘柄)、Forex(24通貨ペア、スプレッド+スワップ)、Options v2(アメリカン行使、IVスマイル)を追加。統計的検証: モンテカルロ置換検定、ブートストラップSharpe信頼区間、ウォークフォワード分析。
|
||||
- **2026-04-08** 🔧 **マルチマーケットバックテスト**(市場別ルール対応)と**TradingView向けPine Script v6エクスポート**。**データソース拡張**: 自動フォールバック付き5ソース、`web_search`ツール、スキル分類(7カテゴリ)。
|
||||
- **2026-04-01** 🚀 **v0.1.0** — 初期リリース: ReActエージェント、64スキル、29スウォームプリセット、クロスマーケットバックテスト、CLI + Web UI + MCPサーバー。
|
||||
- **2026-04-28** 🚀 **v0.1.6 リリース**(`pip install -U vibe-trading-ai`): `pip install` / `uv tool install` 後に `vibe-trading --swarm-presets` が空を返す問題を修正([#55](https://github.com/HKUDS/Vibe-Trading/issues/55))— プリセット YAML を `src.swarm` パッケージ内に同梱、6 件の回帰テストでピン留め。加えて AKShare ローダーが ETF(`510300.SH`)と外国為替(`USDCNH`)を正しいエンドポイントにルーティング、レジストリフォールバックも強化。v0.1.5 以降の更新を集約: ベンチマーク比較パネル、`/upload` ストリーミング + サイズ制限、Futu ローダー(HK + A 株)、vnpy エクスポートスキル、セキュリティ強化、フロントエンド遅延ロード(688KB → 262KB)。
|
||||
- **2026-04-27** 📊 **ベンチマーク比較パネル + アップロード安全性**: バックテスト出力にベンチマーク比較パネル(銘柄 / ベンチマークリターン / 超過リターン / 情報比率)を追加、yfinance 経由で SPY・CSI 300 などを解決([#48](https://github.com/HKUDS/Vibe-Trading/issues/48))。加えて `/upload` を 1MB チャンクのストリーミングに変更し、`MAX_UPLOAD_SIZE` を超えた時点で中断 + 部分ファイルをクリーンアップ。50MB 上限が悪意/巨大リクエスト下でも実効化([#53](https://github.com/HKUDS/Vibe-Trading/pull/53))—— 4 件の回帰テストでピン留め。
|
||||
- **2026-04-22** 🛡️ **ハードニング + 新規連携**: `safe_path` でパス封じ込めを強制 + 取引明細/シャドウアカウント系ツールをサンドボックス化、`MANIFEST.in` を追加して sdist に `.env.example` / テスト / Docker ファイルを同梱、フロントエンドのルート単位遅延ロードで初期バンドル 688KB → 262KB。加えて富途(Futu)の香港株/A 株データローダー([#47](https://github.com/HKUDS/Vibe-Trading/pull/47))と vnpy CtaTemplate エクスポートスキル([#46](https://github.com/HKUDS/Vibe-Trading/pull/46))を追加。
|
||||
|
||||
<details>
|
||||
<summary>過去のニュース</summary>
|
||||
|
||||
- **2026-04-21** 🛡️ **ワークスペース + ドキュメント**: 相対 `run_dir` をアクティブな run ディレクトリに正規化([#43](https://github.com/HKUDS/Vibe-Trading/pull/43))。README に使用例を追加([#45](https://github.com/HKUDS/Vibe-Trading/pull/45))。
|
||||
- **2026-04-20** 🔌 **推論モデル + Swarm 修正**: `reasoning_content` を `ChatOpenAI` の全シリアライズパスで保持 — Kimi / DeepSeek / Qwen thinking がエンドツーエンドで動作([#39](https://github.com/HKUDS/Vibe-Trading/issues/39))。Swarm をストリーミング化 + Ctrl+C のクリーン終了([#42](https://github.com/HKUDS/Vibe-Trading/issues/42))。
|
||||
- **2026-04-19** 📦 **v0.1.5**: PyPI と ClawHub に公開。`python-multipart` CVE 下限バンプ、新規 MCP ツール5つ接続(`analyze_trade_journal` + シャドウアカウント系4つ)、`pattern_recognition` → `pattern` レジストリ名の不一致を修正、Docker 依存を本体に合わせる、SKILL マニフェスト同期(22 MCP ツール / 71 スキル)。
|
||||
- **2026-04-18** 👥 **シャドウアカウント Shadow Account**: ブローカーの取引明細から自分の戦略ルールを抽出 → マーケット横断でシャドウをバックテスト → 8セクションのHTML/PDFレポートが、どこでいくら取りこぼしたか(ルール違反・早すぎる利確・見逃したシグナル・逆張り)を正確に可視化。新規ツール4つ、新スキル1つ、合計32ツール。Trade Journal / Shadow Accountのサンプル例文がWeb UIウェルカム画面に追加。
|
||||
- **2026-04-17** 📊 **取引明細アナライザー + ユニバーサルファイルリーダー**: ブローカーの取引明細(同花順/東方財富/富途/汎用CSV)をアップロード → 取引プロフィール(保有日数、勝率、損益比、最大ドローダウン)+ 4つの行動バイアス診断(処分効果、過剰取引、追随買い、アンカリング)を自動生成。`read_document`はPDF、Word、Excel、PowerPoint、画像(OCR)、40+テキスト形式を1回の呼び出しで統一処理。
|
||||
- **2026-04-16** 🧠 **エージェントハーネス**: クロスセッション永続メモリ、FTS5セッション検索、自己進化スキル(完全CRUD)、5層コンテキスト圧縮、読み書きツールバッチ処理。27ツール、107新テスト。
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**: Z.aiプロバイダー追加([#35](https://github.com/HKUDS/Vibe-Trading/pull/35))、MiniMax temperature修正+モデル更新([#33](https://github.com/HKUDS/Vibe-Trading/pull/33))。13プロバイダー対応。
|
||||
- **2026-04-14** 🔧 **MCP安定性**: バックテストツールのstdioトランスポートにおける`Connection closed`エラーを修正([#32](https://github.com/HKUDS/Vibe-Trading/pull/32))。
|
||||
- **2026-04-13** 🌐 **クロスマーケット複合バックテスト**: 新`CompositeEngine`で異なる市場の銘柄(例:A株+暗号資産)を共有資金プールで同時バックテスト、市場ルールは銘柄ごとに適用。Swarmテンプレート変数フォールバックとフロントエンドタイムアウトも修正。
|
||||
- **2026-04-12** 🌍 **マルチプラットフォーム出力**: `/pine`でTradingView (Pine Script v6)、TDX(通達信/同花順/東方財富)、MetaTrader 5 (MQL5) に一括エクスポート。
|
||||
- **2026-04-11** 🛡️ **信頼性とDX**: `vibe-trading init` .envブートストラップ([#19](https://github.com/HKUDS/Vibe-Trading/pull/19))、プリフライトチェック、データソースフォールバック、バックテストエンジン強化。多言語README([#21](https://github.com/HKUDS/Vibe-Trading/pull/21))。
|
||||
- **2026-04-10** 📦 **v0.1.4**: Docker修正([#8](https://github.com/HKUDS/Vibe-Trading/issues/8))、`web_search` MCPツール、12 LLMプロバイダー、`akshare`/`ccxt`依存追加。PyPIとClawHubに公開。
|
||||
- **2026-04-09** 📊 **Backtest Wave 2**: ChinaFutures、GlobalFutures、Forex、Options v2エンジン追加。モンテカルロ、Bootstrap CI、ウォークフォワード検証。
|
||||
- **2026-04-08** 🔧 **マルチマーケットバックテスト**: 市場別ルール、Pine Script v6エクスポート、自動フォールバック付き5データソース。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
@@ -63,12 +82,12 @@
|
||||
Vibe-Tradingは、自然言語リクエストをグローバル市場向けの実行可能なトレーディング戦略、リサーチ洞察、ポートフォリオ分析へと変換する、AI駆動のマルチエージェント金融ワークスペースです。
|
||||
|
||||
### 主な能力:
|
||||
• **Strategy Generation** — アイデアから自動でトレーディングコードを生成<br>
|
||||
• **Smart Data Access** — 自動フォールバック付き5つのデータソース、全市場ゼロ設定<br>
|
||||
• **Performance Testing** — 歴史的市場データで戦略を検証<br>
|
||||
• **TradingView Export** — ワンクリックでTradingView用Pine Script v6に変換<br>
|
||||
• **Expert Teams** — 複雑なリサーチタスクに特化したAIエージェントチームを展開<br>
|
||||
• **Live Updates** — 分析プロセス全体をリアルタイムで観察
|
||||
• **自然言語 → 戦略** — アイデアを記述するだけ、エージェントがコードの作成・テスト・エクスポートを実行<br>
|
||||
• **5データソース、ゼロ設定** — A株、HK/US、暗号、先物、FX対応、自動フォールバック<br>
|
||||
• **29の専門チーム** — 投資・トレーディング・リスク向けマルチエージェントスウォームワークフロー<br>
|
||||
• **クロスセッションメモリ** — ユーザーの好みやインサイトを記憶し、再利用可能なスキルを自動生成・進化<br>
|
||||
• **7つのバックテストエンジン** — クロスマーケット複合テスト + 統計検証 + 4種オプティマイザー<br>
|
||||
• **マルチプラットフォームエクスポート** — ワンクリックでTradingView、TDX、MetaTrader 5へ
|
||||
|
||||
---
|
||||
|
||||
@@ -79,12 +98,12 @@ Vibe-Tradingは、自然言語リクエストをグローバル市場向けの
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-research.png" height="150" alt="Research"/><br>
|
||||
<h3>🔍 トレーディング向けDeepResearch</h3>
|
||||
<img src="https://img.shields.io/badge/68_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<img src="https://img.shields.io/badge/72_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<div align="left" style="font-size: 4px;">
|
||||
• 市場横断のマルチドメイン分析<br>
|
||||
• 自動ストラテジー/シグナル生成<br>
|
||||
• マクロ経済リサーチとインサイト<br>
|
||||
• チャットによる自然言語タスクルーティング
|
||||
• 72の専門スキル + クロスセッション永続メモリ<br>
|
||||
• 自己進化: エージェントが経験からワークフローを構築・改善<br>
|
||||
• 5層コンテキスト圧縮 — 長い会話でも情報損失なし<br>
|
||||
• 全金融ドメインにわたる自然言語タスクルーティング
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -94,8 +113,8 @@ Vibe-Tradingは、自然言語リクエストをグローバル市場向けの
|
||||
<div align="left">
|
||||
• 即戦力の29種トレーディングチームプリセット<br>
|
||||
• DAGベースのマルチエージェントオーケストレーション<br>
|
||||
• リアルタイム意思決定ストリーミングダッシュボード<br>
|
||||
• YAMLによるカスタムチーム構築
|
||||
• リアルタイムストリーミングダッシュボード(エージェントステータス表示)<br>
|
||||
• FTS5クロスセッション検索で過去の全会話を横断検索
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -104,7 +123,7 @@ Vibe-Tradingは、自然言語リクエストをグローバル市場向けの
|
||||
<img src="https://img.shields.io/badge/5_Data_Sources-FFD93D?style=for-the-badge&logo=bitcoin&logoColor=black" alt="Backtest" /><br><br>
|
||||
<div align="left">
|
||||
• A株、HK/US株式、暗号資産、先物、FXに対応<br>
|
||||
• 7つの市場エンジン: A株、US/HK株、暗号資産、中国先物、グローバル先物、FX<br>
|
||||
• 7つの市場エンジン + クロスマーケット複合エンジン(共有資金プール)<br>
|
||||
• 統計的検証: モンテカルロ、ブートストラップCI、ウォークフォワード<br>
|
||||
• 15以上のパフォーマンス指標と4種類のオプティマイザー
|
||||
</div>
|
||||
@@ -123,16 +142,16 @@ Vibe-Tradingは、自然言語リクエストをグローバル市場向けの
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## 7カテゴリにわたる68スキル
|
||||
## 7カテゴリにわたる72スキル
|
||||
|
||||
- 📊 68の金融特化スキルを7カテゴリに整理
|
||||
- 📊 72の金融特化スキルを7カテゴリに整理
|
||||
- 🌐 伝統的市場から暗号・DeFiまで完全カバー
|
||||
- 🔬 データ取得からクオンツリサーチまでの包括的能力
|
||||
|
||||
| Category | Skills | Examples |
|
||||
|----------|--------|----------|
|
||||
| Data Source | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| Strategy | 16 | `strategy-generate`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Strategy | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 15 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis` |
|
||||
| Asset Class | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| Crypto | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
@@ -221,7 +240,7 @@ vibe-trading-mcp # MCPサーバー(stdio)起動
|
||||
- Path Bでは**Python 3.11+**
|
||||
- Path Aでは**Docker**
|
||||
|
||||
> **サポートされるLLMプロバイダー:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Ollama(ローカル)。設定は`.env.example`を参照。
|
||||
> **サポートされるLLMプロバイダー:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Z.ai, Ollama(ローカル)。設定は`.env.example`を参照。
|
||||
|
||||
> **Tip:** すべての市場でAPIキーなしでも動作(自動フォールバック)。yfinance(HK/US)、OKX(暗号)、AKShare(A株・US・HK・先物・FX)は無料。Tushareトークンは任意 — A株はAKShareで無料フォールバック。
|
||||
|
||||
@@ -306,6 +325,18 @@ npx clawhub@latest install vibe-trading --force
|
||||
|
||||
**無料データ(キー不要):** AKShare経由のA株、yfinance経由のHK/US株式、OKX経由の暗号、CCXT経由の100+暗号取引所。市場ごとに最適なソースを自動選択。
|
||||
|
||||
### 🎯 推奨モデル
|
||||
|
||||
Vibe-Tradingはツール呼び出しに大きく依存するエージェントです — skill・バックテスト・メモリ・swarmはすべてtool callで動作します。モデル選択が、エージェントが**実際にツールを使う**か、訓練データから答えを捏造するかを直接決定します。
|
||||
|
||||
| 層 | 例 | 用途 |
|
||||
|----|-----|------|
|
||||
| **ベスト** | `anthropic/claude-opus-4.7`、`anthropic/claude-sonnet-4.6`、`openai/gpt-5.4`、`google/gemini-3.1-pro-preview` | 複雑なswarm(3+エージェント)、長い研究セッション、論文レベル分析 |
|
||||
| **コスパ**(デフォルト) | `deepseek/deepseek-v3.2`、`x-ai/grok-4.20`、`z-ai/glm-5.1`、`moonshotai/kimi-k2.5`、`qwen/qwen3-max-thinking` | 日常利用 — tool-callingが安定、コスト約1/10 |
|
||||
| **エージェント用途では非推奨** | `*-nano`、`*-flash-lite`、`*-coder-next`、小型 / 蒸留版 | tool-callingが不安定 — skillのロードやbacktest実行をせず「記憶で回答」してしまう |
|
||||
|
||||
デフォルトの `agent/.env.example` は `deepseek/deepseek-v3.2` — コスパ層の最安オプション。
|
||||
|
||||
---
|
||||
|
||||
## 🖥 CLI リファレンス
|
||||
@@ -322,7 +353,7 @@ vibe-trading serve # APIサーバー
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/help` | すべてのコマンドを表示 |
|
||||
| `/skills` | 68の金融スキルを一覧表示 |
|
||||
| `/skills` | 72の金融スキルを一覧表示 |
|
||||
| `/swarm` | 29のスウォームチームプリセットを一覧表示 |
|
||||
| `/swarm run <preset> [vars_json]` | スウォームチームをライブストリーミングで実行 |
|
||||
| `/swarm list` | スウォーム実行履歴 |
|
||||
@@ -331,7 +362,7 @@ vibe-trading serve # APIサーバー
|
||||
| `/list` | 直近の実行 |
|
||||
| `/show <run_id>` | 実行詳細と指標 |
|
||||
| `/code <run_id>` | 生成された戦略コード |
|
||||
| `/pine <run_id>` | TradingView用Pine Script |
|
||||
| `/pine <run_id>` | インジケーターエクスポート(TradingView + TDX + MT5)|
|
||||
| `/trace <run_id>` | 実行リプレイ |
|
||||
| `/continue <run_id> <prompt>` | 実行を新指示で継続 |
|
||||
| `/sessions` | チャットセッション一覧 |
|
||||
@@ -358,7 +389,7 @@ vibe-trading --swarm-run investment_committee '{"topic":"BTC outlook"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # TradingView用Pine Script
|
||||
vibe-trading --pine <run_id> # インジケーターエクスポート(TradingView + TDX + MT5)
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "refine the strategy"
|
||||
vibe-trading --upload report.pdf
|
||||
@@ -378,7 +409,7 @@ vibe-trading serve --port 8899
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | 実行一覧 |
|
||||
| `GET` | `/runs/{run_id}` | 実行詳細 |
|
||||
| `GET` | `/runs/{run_id}/pine` | Pine Scriptエクスポート |
|
||||
| `GET` | `/runs/{run_id}/pine` | マルチプラットフォームインジケーターエクスポート |
|
||||
| `POST` | `/sessions` | セッション作成 |
|
||||
| `POST` | `/sessions/{id}/messages` | メッセージ送信 |
|
||||
| `GET` | `/sessions/{id}/events` | SSEイベントストリーム |
|
||||
@@ -393,7 +424,7 @@ vibe-trading serve --port 8899
|
||||
|
||||
## 🔌 MCP プラグイン
|
||||
|
||||
Vibe-Tradingは、あらゆるMCP互換クライアント向けに17のMCPツールを提供します。stdioサブプロセスとして実行 — サーバーセットアップ不要。**17中16ツールはAPIキー不要**(HK/US/暗号)。`run_swarm`のみLLMキーが必要。
|
||||
Vibe-Tradingは、あらゆるMCP互換クライアント向けに22のMCPツールを提供します。stdioサブプロセスとして実行 — サーバーセットアップ不要。**22中21ツールはAPIキー不要**(HK/US/暗号)。`run_swarm`のみLLMキーが必要。
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
@@ -435,7 +466,7 @@ vibe-trading-mcp --transport sse # Webクライアント向けSSE
|
||||
|
||||
</details>
|
||||
|
||||
**公開MCPツール(17):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`。
|
||||
**公開MCPツール(22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`。
|
||||
|
||||
<details>
|
||||
<summary><b>ClawHubからインストール(ワンコマンド)</b></summary>
|
||||
@@ -455,7 +486,7 @@ ClawHubで閲覧: [clawhub.ai/skills/vibe-trading](https://clawhub.ai/skills/vib
|
||||
<details>
|
||||
<summary><b>OpenSpace — 自己進化スキル</b></summary>
|
||||
|
||||
全68金融スキルは[open-space.cloud](https://open-space.cloud)に公開され、OpenSpaceの自己進化エンジンで自律的に進化します。
|
||||
全72金融スキルは[open-space.cloud](https://open-space.cloud)に公開され、OpenSpaceの自己進化エンジンで自律的に進化します。
|
||||
|
||||
OpenSpaceで使うには、両方のMCPサーバーをエージェント設定に追加:
|
||||
|
||||
@@ -477,7 +508,7 @@ OpenSpaceで使うには、両方のMCPサーバーをエージェント設定
|
||||
}
|
||||
```
|
||||
|
||||
OpenSpaceが全68スキルを自動検出し、auto-fix/auto-improve/コミュニティ共有を有効化。`search_skills("finance backtest")`でVibe-Tradingスキルを検索可能。
|
||||
OpenSpaceが全72スキルを自動検出し、auto-fix/auto-improve/コミュニティ共有を有効化。`search_skills("finance backtest")`でVibe-Tradingスキルを検索可能。
|
||||
|
||||
</details>
|
||||
|
||||
@@ -493,41 +524,42 @@ Vibe-Trading/
|
||||
├── agent/ # バックエンド (Python)
|
||||
│ ├── cli.py # CLIエントリーポイント — 対話型TUI + サブコマンド
|
||||
│ ├── api_server.py # FastAPIサーバー — runs, sessions, upload, swarm, SSE
|
||||
│ ├── mcp_server.py # MCPサーバー — OpenClaw / Claude Desktop向け17ツール
|
||||
│ ├── mcp_server.py # MCPサーバー — OpenClaw / Claude Desktop向け22ツール
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # ReActエージェントコア
|
||||
│ │ │ ├── loop.py # メイン推論ループ
|
||||
│ │ │ ├── skills.py # スキルローダー(68 SKILL.md, 7カテゴリ)
|
||||
│ │ │ ├── tools.py # ツールオーケストレーション
|
||||
│ │ │ ├── context.py # システムプロンプトビルダー
|
||||
│ │ │ ├── memory.py # 実行メモリ / アーティファクトストア
|
||||
│ │ │ ├── loop.py # 5層圧縮 + 読み書きツールバッチ処理
|
||||
│ │ │ ├── context.py # システムプロンプト + 永続メモリからの自動リコール
|
||||
│ │ │ ├── skills.py # スキルローダー(72バンドル + ユーザーCRUD作成)
|
||||
│ │ │ ├── tools.py # ツール基底クラス + レジストリ
|
||||
│ │ │ ├── memory.py # 実行ごとの軽量ワークスペースステート
|
||||
│ │ │ ├── frontmatter.py # 共有YAMLフロントマターパーサー
|
||||
│ │ │ └── trace.py # 実行トレースライター
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 21のエージェントツール
|
||||
│ │ │ ├── backtest_tool.py # バックテスト実行
|
||||
│ │ │ ├── factor_analysis_tool.py
|
||||
│ │ │ ├── options_pricing_tool.py
|
||||
│ │ │ ├── pattern_tool.py # チャートパターン検出
|
||||
│ │ │ ├── doc_reader_tool.py # PDFリーダー(OCRフォールバック)
|
||||
│ │ │ ├── web_reader_tool.py # webページリーダー(Jina)
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGoウェブ検索
|
||||
│ │ │ ├── swarm_tool.py # スウォームチーム起動
|
||||
│ │ │ └── ... # ファイルI/O, bash, tasks など
|
||||
│ │ ├── memory/ # クロスセッション永続メモリ
|
||||
│ │ │ └── persistent.py # ファイルベースメモリ (~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 7カテゴリに渡る68金融スキル (各SKILL.md)
|
||||
│ │ ├── tools/ # 27の自動検出エージェントツール
|
||||
│ │ │ ├── backtest_tool.py # バックテスト実行
|
||||
│ │ │ ├── remember_tool.py # クロスセッションメモリ (保存/リコール/削除)
|
||||
│ │ │ ├── skill_writer_tool.py # スキルCRUD (保存/パッチ/削除/ファイル)
|
||||
│ │ │ ├── session_search_tool.py # FTS5クロスセッション検索
|
||||
│ │ │ ├── swarm_tool.py # スウォームチーム起動
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGoウェブ検索
|
||||
│ │ │ └── ... # bash, ファイルI/O, ファクター分析, オプション等
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 7カテゴリに渡る72金融スキル (各SKILL.md)
|
||||
│ │ ├── swarm/ # スウォームDAG実行エンジン
|
||||
│ │ ├── session/ # マルチターンチャットセッション管理
|
||||
│ │ │ └── presets/ # 29のスウォームプリセットYAML定義
|
||||
│ │ ├── session/ # マルチターンチャット + FTS5セッション検索
|
||||
│ │ └── providers/ # LLMプロバイダー抽象化
|
||||
│ │
|
||||
│ ├── backtest/ # バックテストエンジン
|
||||
│ │ ├── engines/ # 7エンジン: china_a, global_equity, crypto, china_futures, global_futures, forex + options_portfolio
|
||||
│ │ ├── loaders/ # 5ソース: tushare, okx, yfinance, akshare, ccxt
|
||||
│ │ │ ├── base.py # DataLoader Protocol
|
||||
│ │ │ └── registry.py # レジストリ + 自動フォールバックチェーン
|
||||
│ │ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│ │
|
||||
│ └── config/swarm/ # 29のスウォームプリセットYAML定義
|
||||
│ └── backtest/ # バックテストエンジン
|
||||
│ ├── engines/ # 7エンジン + クロスマーケット複合エンジン + options_portfolio
|
||||
│ ├── loaders/ # 6ソース: tushare, okx, yfinance, akshare, ccxt, futu
|
||||
│ │ ├── base.py # DataLoader Protocol
|
||||
│ │ └── registry.py # レジストリ + 自動フォールバックチェーン
|
||||
│ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│
|
||||
├── frontend/ # Web UI (React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
@@ -578,17 +610,21 @@ Vibe-Tradingは**[HKUDS](https://github.com/HKUDS)**エージェントエコシ
|
||||
|
||||
| Phase | Feature | Status |
|
||||
|-------|---------|--------|
|
||||
| **Agent Harness** | クロスセッション永続メモリ(保存/リコール/削除) | **Done** |
|
||||
| | 自己進化スキル — エージェントが自らワークフローを作成・修正・削除 | **Done** |
|
||||
| | FTS5クロスセッション検索(過去の全会話を横断) | **Done** |
|
||||
| | 5層コンテキスト圧縮(micro → collapse → auto → manual → iterative) | **Done** |
|
||||
| | 読み書きツールバッチ処理 — 読み取り専用ツールの並列実行 | **Done** |
|
||||
| **Next Up** | 自律リサーチループ — エージェントが仮説を一晩中反復 | In Progress |
|
||||
| | IM統合(Slack / Telegram / WeChat) | Planned |
|
||||
| **Analysis & Viz** | オプションボラティリティサーフェスとギリシャ値3D可視化 | Planned |
|
||||
| | ローリングウィンドウ+クラスタリングによるクロスアセット相関ヒートマップ | Planned |
|
||||
| | CLIバックテスト出力でのベンチマーク比較 | Planned |
|
||||
| | バックテスト指標へのCalmar Ratio & Omega Ratio追加 | Planned |
|
||||
| **Skills & Presets** | 配当分析スキル | Planned |
|
||||
| | ESG/サステナブル投資スウォームプリセット | Planned |
|
||||
| | 新興市場リサーチデスクスウォームプリセット | Planned |
|
||||
| **Portfolio & Optimization** | レバレッジ・セクター上限・回転率制約付き高度ポートフォリオオプティマイザー | Planned |
|
||||
| **Future** | 初心者チュートリアル: 「5分で自然言語バックテスト」 | Planned |
|
||||
| **Future** | ストラテジーマーケットプレイス(共有・発見) | Exploring |
|
||||
| | WebSocket経由のライブデータストリーミング | Exploring |
|
||||
| | ストラテジーマーケットプレイス(共有・発見) | Exploring |
|
||||
|
||||
---
|
||||
|
||||
@@ -622,6 +658,12 @@ MIT License — [LICENSE](LICENSE)を参照
|
||||
|
||||
---
|
||||
|
||||
## スター履歴
|
||||
|
||||
[](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
<b>Vibe-Trading</b>への訪問に感謝 ✨
|
||||
</p>
|
||||
|
||||
+107
-65
@@ -1,5 +1,5 @@
|
||||
<p align="center">
|
||||
<a href="README.md">English</a> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <b>한국어</b>
|
||||
<a href="README.md">English</a> | <a href="README_zh.md">中文</a> | <a href="README_ja.md">日本語</a> | <b>한국어</b> | <a href="README_ar.md">العربية</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -19,10 +19,10 @@
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="License"></a>
|
||||
<br>
|
||||
<img src="https://img.shields.io/badge/Skills-68-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Skills-72-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Swarm_Presets-29-7C3AED" alt="Swarm">
|
||||
<img src="https://img.shields.io/badge/Tools-21-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-5-2563EB" alt="Data Sources">
|
||||
<img src="https://img.shields.io/badge/Tools-27-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-6-2563EB" alt="Data Sources">
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
@@ -51,10 +51,29 @@
|
||||
|
||||
## 📰 뉴스
|
||||
|
||||
- **2026-04-10** 📦 **v0.1.4**: Docker 빌드 수정([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)), `web_search` MCP 도구 추가(총 17개), 의존성 및 MCP에 `akshare`/`ccxt` 추가. 11개 LLM 제공자(DeepSeek, Groq, Gemini, Ollama 등), 모든 튜닝 파라미터를 `.env`로 설정. `ml-strategy` 스킬 하드닝. PyPI와 ClawHub에 게시.
|
||||
- **2026-04-09** 📊 **Backtest Wave 2 — 멀티자산 엔진**: ChinaFutures(CFFEX/SHFE/DCE/ZCE, 50+ 종목), GlobalFutures(CME/ICE/Eurex, 30+ 종목), Forex(24 페어, 스프레드 + 스왑), Options v2(미국형 행사, IV 스마일) 추가. 통계 검증: 몬테카를로 순열 테스트, Bootstrap 샤프 CI, 워크포워드 분석.
|
||||
- **2026-04-08** 🔧 **다중 시장 백테스트**: 시장별 규칙, TradingView용 **Pine Script v6 내보내기**. **데이터 소스 확장**: 자동 폴백 포함 5개 소스, `web_search` 도구, 스킬 7개 카테고리화.
|
||||
- **2026-04-01** 🚀 **v0.1.0** — 초기 릴리스: ReAct 에이전트, 64 스킬, 29 스웜 프리셋, 크로스마켓 백테스트, CLI + Web UI + MCP 서버.
|
||||
- **2026-04-28** 🚀 **v0.1.6 릴리스**(`pip install -U vibe-trading-ai`): `pip install` / `uv tool install` 설치 후 `vibe-trading --swarm-presets`가 비어 있는 문제 수정([#55](https://github.com/HKUDS/Vibe-Trading/issues/55)) — 프리셋 YAML을 `src.swarm` 패키지 내부에 번들링, 6개 회귀 테스트로 고정. 또한 AKShare 로더가 ETF(`510300.SH`)와 외환(`USDCNH`)을 올바른 엔드포인트로 라우팅하고 레지스트리 폴백 강화. v0.1.5 이후 업데이트 종합: 벤치마크 비교 패널, `/upload` 스트리밍 + 크기 제한, Futu 로더(HK + A주), vnpy 내보내기 스킬, 보안 강화, 프론트엔드 지연 로딩(688KB → 262KB).
|
||||
- **2026-04-27** 📊 **벤치마크 비교 패널 + 업로드 안전성**: 백테스트 출력에 벤치마크 비교 패널(티커 / 벤치마크 수익률 / 초과 수익률 / 정보 비율) 추가, yfinance로 SPY · CSI 300 등 자동 해석([#48](https://github.com/HKUDS/Vibe-Trading/issues/48)). 또한 `/upload` 엔드포인트를 1MB 청크 스트리밍으로 전환, `MAX_UPLOAD_SIZE` 초과 시 즉시 중단 + 부분 파일 정리. 50MB 상한이 악성/초대형 요청에도 실효화([#53](https://github.com/HKUDS/Vibe-Trading/pull/53)) — 4개 회귀 테스트로 고정.
|
||||
- **2026-04-22** 🛡️ **하드닝 + 신규 연동**: `safe_path`에 경로 컨테인먼트 강제 + 거래 명세서/섀도우 계정 도구 샌드박스화, `MANIFEST.in` 추가로 sdist에 `.env.example` / 테스트 / Docker 파일 포함, 프론트엔드 라우트 단위 지연 로딩으로 초기 번들 688KB → 262KB. 또한 Futu 홍콩/A주 데이터 로더([#47](https://github.com/HKUDS/Vibe-Trading/pull/47))와 vnpy CtaTemplate 내보내기 스킬([#46](https://github.com/HKUDS/Vibe-Trading/pull/46)) 추가.
|
||||
|
||||
<details>
|
||||
<summary>이전 뉴스</summary>
|
||||
|
||||
- **2026-04-21** 🛡️ **워크스페이스 + 문서**: 상대 `run_dir`을 활성 run 디렉토리로 정규화([#43](https://github.com/HKUDS/Vibe-Trading/pull/43)). README 사용 예제 추가([#45](https://github.com/HKUDS/Vibe-Trading/pull/45)).
|
||||
- **2026-04-20** 🔌 **추론 모델 + Swarm 수정**: `reasoning_content`을 모든 `ChatOpenAI` 직렬화 경로에서 보존 — Kimi / DeepSeek / Qwen thinking 엔드투엔드 작동([#39](https://github.com/HKUDS/Vibe-Trading/issues/39)). Swarm 스트리밍 + 깔끔한 Ctrl+C 종료([#42](https://github.com/HKUDS/Vibe-Trading/issues/42)).
|
||||
- **2026-04-19** 📦 **v0.1.5**: PyPI 및 ClawHub에 게시. `python-multipart` CVE 하한 버전 업데이트, 5개 신규 MCP 도구 연결(`analyze_trade_journal` + 4개 섀도우 계정 도구), `pattern_recognition` → `pattern` 레지스트리 이름 불일치 수정, Docker 의존성 동기화, SKILL 매니페스트 동기화(22개 MCP 도구 / 71개 스킬).
|
||||
- **2026-04-18** 👥 **섀도우 계정 Shadow Account**: 증권사 거래 명세서에서 자신의 전략 규칙을 추출 → 여러 시장에서 섀도우 백테스트 실행 → 8개 섹션 HTML/PDF 리포트가 어디에서 얼마를 놓쳤는지(규칙 위반, 조기 익절, 놓친 시그널, 역방향 거래) 정확히 보여줌. 신규 도구 4개, 신규 스킬 1개, 총 32개 도구. Trade Journal / Shadow Account 샘플 프롬프트가 Web UI 웰컴 화면에 추가.
|
||||
- **2026-04-17** 📊 **거래 명세서 분석기 + 유니버설 파일 리더**: 증권사 거래 명세서(同花顺/东财/富途/일반 CSV) 업로드 → 거래 프로필(보유 일수, 승률, 손익비, 최대 드로다운) + 4가지 행동 편향 진단(처분 효과, 과잉 거래, 추격 매수, 앵커링) 자동 생성. `read_document`는 이제 PDF, Word, Excel, PowerPoint, 이미지(OCR), 40+ 텍스트 형식을 하나의 호출로 통합 처리.
|
||||
- **2026-04-16** 🧠 **에이전트 하네스**: 크로스세션 영구 메모리, FTS5 세션 검색, 자가 진화 스킬(전체 CRUD), 5계층 컨텍스트 압축, 읽기/쓰기 도구 배치 처리. 27개 도구, 107개 신규 테스트.
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**: Z.ai 제공자 추가([#35](https://github.com/HKUDS/Vibe-Trading/pull/35)), MiniMax temperature 수정 + 모델 업데이트([#33](https://github.com/HKUDS/Vibe-Trading/pull/33)). 13개 제공자.
|
||||
- **2026-04-14** 🔧 **MCP 안정성**: 백테스트 도구의 stdio 전송에서 `Connection closed` 오류 수정([#32](https://github.com/HKUDS/Vibe-Trading/pull/32)).
|
||||
- **2026-04-13** 🌐 **크로스마켓 복합 백테스트**: 새 `CompositeEngine`으로 서로 다른 시장 종목(예: A주 + 암호화폐)을 공유 자금 풀로 동시 백테스트, 시장 규칙은 종목별 적용. Swarm 템플릿 변수 폴백 및 프론트엔드 타임아웃도 수정.
|
||||
- **2026-04-12** 🌍 **멀티 플랫폼 내보내기**: `/pine`으로 TradingView (Pine Script v6), TDX (통달신/동화순/동방재부), MetaTrader 5 (MQL5) 한 번에 내보내기.
|
||||
- **2026-04-11** 🛡️ **안정성 및 DX**: `vibe-trading init` .env 부트스트랩([#19](https://github.com/HKUDS/Vibe-Trading/pull/19)), 프리플라이트 체크, 데이터소스 폴백, 백테스트 엔진 강화. 다국어 README([#21](https://github.com/HKUDS/Vibe-Trading/pull/21)).
|
||||
- **2026-04-10** 📦 **v0.1.4**: Docker 수정([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)), `web_search` MCP 도구, 12개 LLM 제공자, `akshare`/`ccxt` 의존성. PyPI와 ClawHub에 게시.
|
||||
- **2026-04-09** 📊 **Backtest Wave 2**: ChinaFutures, GlobalFutures, Forex, Options v2 엔진. 몬테카를로, Bootstrap CI, 워크포워드 검증.
|
||||
- **2026-04-08** 🔧 **다중 시장 백테스트**: 시장별 규칙, Pine Script v6 내보내기, 자동 폴백 5개 데이터 소스.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
@@ -63,12 +82,12 @@
|
||||
Vibe-Trading은 AI 기반 멀티 에이전트 금융 워크스페이스로, 자연어 요청을 전 세계 시장의 실행 가능한 트레이딩 전략, 리서치 인사이트, 포트폴리오 분석으로 전환합니다.
|
||||
|
||||
### 핵심 역량:
|
||||
• **전략 생성** — 아이디어를 자동으로 트레이딩 코드로 작성<br>
|
||||
• **스마트 데이터 접근** — 자동 폴백이 있는 5개 데이터 소스; 모든 시장 무설정<br>
|
||||
• **성능 테스트** — 전략을 과거 시장 데이터로 검증<br>
|
||||
• **TradingView 내보내기** — 클릭 한 번으로 전략을 Pine Script v6로 변환<br>
|
||||
• **전문 팀** — 복잡한 리서치 작업에 특화 에이전트 팀 배치<br>
|
||||
• **실시간 업데이트** — 전체 분석 과정을 실시간 스트리밍
|
||||
• **자연어 → 전략** — 아이디어를 설명하면 에이전트가 코드 작성, 테스트, 내보내기까지 실행<br>
|
||||
• **5개 데이터 소스, 무설정** — A주, HK/US, 크립토, 선물, FX 자동 폴백<br>
|
||||
• **29개 전문 팀** — 투자, 트레이딩, 리스크를 위한 멀티 에이전트 스웜 워크플로우<br>
|
||||
• **크로스세션 메모리** — 선호도와 인사이트를 기억하고 재사용 가능한 스킬을 자동 생성·진화<br>
|
||||
• **7개 백테스트 엔진** — 크로스마켓 복합 테스트 + 통계 검증 + 4개 옵티마이저<br>
|
||||
• **멀티 플랫폼 내보내기** — 클릭 한 번으로 TradingView, TDX(통달신/동화순), MetaTrader 5
|
||||
|
||||
---
|
||||
|
||||
@@ -79,12 +98,12 @@ Vibe-Trading은 AI 기반 멀티 에이전트 금융 워크스페이스로, 자
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-research.png" height="150" alt="Research"/><br>
|
||||
<h3>🔍 트레이딩용 DeepResearch</h3>
|
||||
<img src="https://img.shields.io/badge/68_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<img src="https://img.shields.io/badge/72_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<div align="left" style="font-size: 4px;">
|
||||
• 시장 전반을 아우르는 다중 도메인 분석<br>
|
||||
• 자동 전략 및 시그널 생성<br>
|
||||
• 거시경제 리서치와 인사이트<br>
|
||||
• 대화형 자연어 태스크 라우팅
|
||||
• 72개 전문 스킬 + 크로스세션 영구 메모리<br>
|
||||
• 자가 진화: 에이전트가 경험으로부터 워크플로우를 생성·개선<br>
|
||||
• 5계층 컨텍스트 압축 — 긴 대화에서도 정보 손실 없음<br>
|
||||
• 전 금융 도메인에 걸친 자연어 태스크 라우팅
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -94,8 +113,8 @@ Vibe-Trading은 AI 기반 멀티 에이전트 금융 워크스페이스로, 자
|
||||
<div align="left">
|
||||
• 29개 즉시 사용 가능한 트레이딩 팀 프리셋<br>
|
||||
• DAG 기반 멀티 에이전트 오케스트레이션<br>
|
||||
• 실시간 의사결정 스트리밍 대시보드<br>
|
||||
• YAML을 통한 커스텀 팀 구성
|
||||
• 실시간 스트리밍 대시보드(에이전트 상태 표시)<br>
|
||||
• FTS5 크로스세션 검색으로 모든 과거 대화 검색
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -104,7 +123,7 @@ Vibe-Trading은 AI 기반 멀티 에이전트 금융 워크스페이스로, 자
|
||||
<img src="https://img.shields.io/badge/5_Data_Sources-FFD93D?style=for-the-badge&logo=bitcoin&logoColor=black" alt="Backtest" /><br><br>
|
||||
<div align="left">
|
||||
• A주, 홍콩/미국 주식, 크립토, 선물 및 FX<br>
|
||||
• 7개 시장 엔진: A주, 미/홍콩 주식, 크립토, 중국 선물, 글로벌 선물, FX<br>
|
||||
• 7개 시장 엔진 + 크로스마켓 복합 엔진(공유 자금 풀)<br>
|
||||
• 통계 검증: 몬테카를로, Bootstrap CI, 워크포워드<br>
|
||||
• 15+ 성과 지표 및 4개 옵티마이저
|
||||
</div>
|
||||
@@ -123,16 +142,16 @@ Vibe-Trading은 AI 기반 멀티 에이전트 금융 워크스페이스로, 자
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## 7개 카테고리에 걸친 68개 스킬
|
||||
## 7개 카테고리에 걸친 72개 스킬
|
||||
|
||||
- 📊 7개 카테고리에 조직된 68개 금융 스킬
|
||||
- 📊 7개 카테고리에 조직된 72개 금융 스킬
|
||||
- 🌐 전통 시장부터 크립토·DeFi까지 완전 커버리지
|
||||
- 🔬 데이터 소싱부터 정량 리서치까지 포괄적 기능
|
||||
|
||||
| 카테고리 | 스킬 | 예시 |
|
||||
|----------|------|------|
|
||||
| Data Source | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| Strategy | 16 | `strategy-generate`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Strategy | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 15 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis` |
|
||||
| Asset Class | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| Crypto | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
@@ -221,7 +240,7 @@ vibe-trading-mcp # MCP 서버 시작(stdio)
|
||||
- 경로 B용 **Python 3.11+**
|
||||
- 경로 A용 **Docker**
|
||||
|
||||
> **지원 LLM 제공자:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Ollama(로컬). 설정은 `.env.example` 참고.
|
||||
> **지원 LLM 제공자:** OpenRouter, OpenAI, DeepSeek, Gemini, Groq, DashScope/Qwen, Zhipu, Moonshot/Kimi, MiniMax, Xiaomi MIMO, Z.ai, Ollama(로컬). 설정은 `.env.example` 참고.
|
||||
|
||||
> **팁:** 모든 시장은 자동 폴백 덕분에 API 키 없이도 작동합니다. yfinance(HK/US), OKX(크립토), AKShare(A주, 미국, HK, 선물, FX)는 모두 무료입니다. Tushare 토큰은 선택 사항 — AKShare가 A주 무료 폴백을 제공합니다.
|
||||
|
||||
@@ -295,7 +314,7 @@ npx clawhub@latest install vibe-trading --force
|
||||
|
||||
| Variable | Required | Description |
|
||||
|----------|:--------:|-------------|
|
||||
| `LANGCHAIN_PROVIDER` | Yes | 제공자 이름(`openrouter`, `deepseek`, `groq`, `ollama` 등) |
|
||||
| `LANGCHAIN_PROVIDER` | Yes | 제공자 이름(`openrouter`, `deepseek`, `groq`, `z.ai`, `ollama` 등) |
|
||||
| `<PROVIDER>_API_KEY` | Yes* | API 키(`OPENROUTER_API_KEY`, `DEEPSEEK_API_KEY` 등) |
|
||||
| `<PROVIDER>_BASE_URL` | Yes | API 엔드포인트 URL |
|
||||
| `LANGCHAIN_MODEL_NAME` | Yes | 모델 이름(예: `deepseek/deepseek-v3.2`) |
|
||||
@@ -306,6 +325,18 @@ npx clawhub@latest install vibe-trading --force
|
||||
|
||||
**무료 데이터(키 불필요):** AKShare의 A주, yfinance의 HK/US 주식, OKX의 크립토, CCXT의 100+ 크립토 거래소. 시스템이 시장별로 최적 소스를 자동 선택합니다.
|
||||
|
||||
### 🎯 권장 모델
|
||||
|
||||
Vibe-Trading은 툴 호출에 크게 의존하는 에이전트입니다 — skill, 백테스트, 메모리, swarm이 모두 tool call을 통해 실행됩니다. 모델 선택이 에이전트가 **실제로 툴을 사용하는지**, 아니면 학습 데이터에서 답을 꾸며내는지를 결정합니다.
|
||||
|
||||
| 등급 | 예시 | 용도 |
|
||||
|------|------|------|
|
||||
| **최상** | `anthropic/claude-opus-4.7`, `anthropic/claude-sonnet-4.6`, `openai/gpt-5.4`, `google/gemini-3.1-pro-preview` | 복잡한 swarm(3+ 에이전트), 긴 연구 세션, 논문급 분석 |
|
||||
| **가성비**(기본값) | `deepseek/deepseek-v3.2`, `x-ai/grok-4.20`, `z-ai/glm-5.1`, `moonshotai/kimi-k2.5`, `qwen/qwen3-max-thinking` | 일상 사용 — 안정적인 tool-calling, 비용 약 1/10 |
|
||||
| **에이전트용으로 피할 것** | `*-nano`, `*-flash-lite`, `*-coder-next`, 소형 / 증류 버전 | tool-calling 불안정 — skill 로드나 backtest 실행 대신 "기억으로 답변" |
|
||||
|
||||
기본 `agent/.env.example`은 `deepseek/deepseek-v3.2` 사용 — 가성비 등급에서 가장 저렴한 옵션.
|
||||
|
||||
---
|
||||
|
||||
## 🖥 CLI 참조
|
||||
@@ -322,7 +353,7 @@ vibe-trading serve # API 서버
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/help` | 모든 명령 표시 |
|
||||
| `/skills` | 68개 금융 스킬 목록 |
|
||||
| `/skills` | 72개 금융 스킬 목록 |
|
||||
| `/swarm` | 29개 스웜 팀 프리셋 목록 |
|
||||
| `/swarm run <preset> [vars_json]` | 라이브 스트리밍으로 스웜 팀 실행 |
|
||||
| `/swarm list` | 스웜 실행 이력 |
|
||||
@@ -331,7 +362,7 @@ vibe-trading serve # API 서버
|
||||
| `/list` | 최근 실행 |
|
||||
| `/show <run_id>` | 실행 상세 + 지표 |
|
||||
| `/code <run_id>` | 생성된 전략 코드 |
|
||||
| `/pine <run_id>` | TradingView용 Pine Script |
|
||||
| `/pine <run_id>` | 인디케이터 내보내기 (TradingView + TDX + MT5) |
|
||||
| `/trace <run_id>` | 전체 실행 리플레이 |
|
||||
| `/continue <run_id> <prompt>` | 새 지시로 실행 계속 |
|
||||
| `/sessions` | 채팅 세션 목록 |
|
||||
@@ -359,7 +390,7 @@ vibe-trading --swarm-run investment_committee '{"topic":"BTC outlook"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # Pine Script for TradingView
|
||||
vibe-trading --pine <run_id> # 인디케이터 내보내기 (TradingView + TDX + MT5)
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "refine the strategy"
|
||||
vibe-trading --upload report.pdf
|
||||
@@ -379,7 +410,7 @@ vibe-trading serve --port 8899
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | 실행 목록 |
|
||||
| `GET` | `/runs/{run_id}` | 실행 상세 |
|
||||
| `GET` | `/runs/{run_id}/pine` | Pine Script 내보내기 |
|
||||
| `GET` | `/runs/{run_id}/pine` | 멀티 플랫폼 인디케이터 내보내기 |
|
||||
| `POST` | `/sessions` | 세션 생성 |
|
||||
| `POST` | `/sessions/{id}/messages` | 메시지 전송 |
|
||||
| `GET` | `/sessions/{id}/events` | SSE 이벤트 스트림 |
|
||||
@@ -394,7 +425,7 @@ vibe-trading serve --port 8899
|
||||
|
||||
## 🔌 MCP 플러그인
|
||||
|
||||
Vibe-Trading은 MCP 호환 클라이언트용 17개 MCP 도구를 제공합니다. stdio 서브프로세스로 실행 — 서버 설정 불필요. **17개 중 16개 도구는 API 키 없이 작동**(HK/US/크립토). `run_swarm`만 LLM 키가 필요합니다.
|
||||
Vibe-Trading은 MCP 호환 클라이언트용 22개 MCP 도구를 제공합니다. stdio 서브프로세스로 실행 — 서버 설정 불필요. **22개 중 21개 도구는 API 키 없이 작동**(HK/US/크립토). `run_swarm`만 LLM 키가 필요합니다.
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
@@ -436,7 +467,7 @@ vibe-trading-mcp --transport sse # 웹 클라이언트용 SSE
|
||||
|
||||
</details>
|
||||
|
||||
**제공 MCP 도구(17):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
**제공 MCP 도구(22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`.
|
||||
|
||||
<details>
|
||||
<summary><b>ClawHub에서 설치(한 줄)</b></summary>
|
||||
@@ -456,7 +487,7 @@ ClawHub에서 보기: [clawhub.ai/skills/vibe-trading](https://clawhub.ai/skills
|
||||
<details>
|
||||
<summary><b>OpenSpace — 자가 진화 스킬</b></summary>
|
||||
|
||||
모든 68개 금융 스킬은 [open-space.cloud](https://open-space.cloud)에 게시되어 OpenSpace의 자가 진화 엔진을 통해 스스로 발전합니다.
|
||||
모든 72개 금융 스킬은 [open-space.cloud](https://open-space.cloud)에 게시되어 OpenSpace의 자가 진화 엔진을 통해 스스로 발전합니다.
|
||||
|
||||
OpenSpace와 함께 사용하려면 두 MCP 서버를 에이전트 설정에 추가하세요:
|
||||
|
||||
@@ -478,7 +509,7 @@ OpenSpace와 함께 사용하려면 두 MCP 서버를 에이전트 설정에 추
|
||||
}
|
||||
```
|
||||
|
||||
OpenSpace는 모든 68개 스킬을 자동으로 탐지하여 자동 수정, 자동 개선, 커뮤니티 공유를 활성화합니다. OpenSpace 연결 에이전트에서 `search_skills("finance backtest")`로 Vibe-Trading 스킬을 검색하세요.
|
||||
OpenSpace는 모든 72개 스킬을 자동으로 탐지하여 자동 수정, 자동 개선, 커뮤니티 공유를 활성화합니다. OpenSpace 연결 에이전트에서 `search_skills("finance backtest")`로 Vibe-Trading 스킬을 검색하세요.
|
||||
|
||||
</details>
|
||||
|
||||
@@ -494,41 +525,42 @@ Vibe-Trading/
|
||||
├── agent/ # Backend (Python)
|
||||
│ ├── cli.py # CLI 엔트리포인트 — 인터랙티브 TUI + 서브커맨드
|
||||
│ ├── api_server.py # FastAPI 서버 — 실행, 세션, 업로드, 스웜, SSE
|
||||
│ ├── mcp_server.py # MCP 서버 — OpenClaw / Claude Desktop용 17개 도구
|
||||
│ ├── mcp_server.py # MCP 서버 — OpenClaw / Claude Desktop용 22개 도구
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # ReAct 에이전트 코어
|
||||
│ │ │ ├── loop.py # 메인 추론 루프
|
||||
│ │ │ ├── skills.py # 스킬 로더(68 SKILL.md, 7 카테고리)
|
||||
│ │ │ ├── tools.py # 도구 오케스트레이션
|
||||
│ │ │ ├── context.py # 시스템 프롬프트 빌더
|
||||
│ │ │ ├── memory.py # 실행 메모리 / 아티팩트 저장소
|
||||
│ │ │ ├── loop.py # 5계층 압축 + 읽기/쓰기 도구 배치 처리
|
||||
│ │ │ ├── context.py # 시스템 프롬프트 + 영구 메모리 자동 리콜
|
||||
│ │ │ ├── skills.py # 스킬 로더(69 번들 + 사용자 CRUD 생성)
|
||||
│ │ │ ├── tools.py # 도구 기본 클래스 + 레지스트리
|
||||
│ │ │ ├── memory.py # 실행별 경량 워크스페이스 상태
|
||||
│ │ │ ├── frontmatter.py # 공유 YAML frontmatter 파서
|
||||
│ │ │ └── trace.py # 실행 트레이스 기록기
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 21개 에이전트 도구
|
||||
│ │ │ ├── backtest_tool.py # 백테스트 실행
|
||||
│ │ │ ├── factor_analysis_tool.py
|
||||
│ │ │ ├── options_pricing_tool.py
|
||||
│ │ │ ├── pattern_tool.py # 차트 패턴 감지
|
||||
│ │ │ ├── doc_reader_tool.py # PDF 리더(OCR 폴백)
|
||||
│ │ │ ├── web_reader_tool.py # 웹 페이지 리더(Jina)
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo 웹 검색
|
||||
│ │ │ ├── swarm_tool.py # 스웜 팀 실행
|
||||
│ │ │ └── ... # 파일 I/O, bash, 태스크 등
|
||||
│ │ ├── memory/ # 크로스세션 영구 메모리
|
||||
│ │ │ └── persistent.py # 파일 기반 메모리 (~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 7개 카테고리의 68개 금융 스킬(SKILL.md 각각)
|
||||
│ │ ├── tools/ # 27개 자동 탐지 에이전트 도구
|
||||
│ │ │ ├── backtest_tool.py # 백테스트 실행
|
||||
│ │ │ ├── remember_tool.py # 크로스세션 메모리 (저장/리콜/삭제)
|
||||
│ │ │ ├── skill_writer_tool.py # 스킬 CRUD (저장/패치/삭제/파일)
|
||||
│ │ │ ├── session_search_tool.py # FTS5 크로스세션 검색
|
||||
│ │ │ ├── swarm_tool.py # 스웜 팀 실행
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo 웹 검색
|
||||
│ │ │ └── ... # bash, 파일 I/O, 팩터 분석, 옵션 등
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 7개 카테고리의 72개 금융 스킬(SKILL.md 각각)
|
||||
│ │ ├── swarm/ # 스웜 DAG 실행 엔진
|
||||
│ │ ├── session/ # 멀티턴 채팅 세션 관리
|
||||
│ │ │ └── presets/ # 29개 스웜 프리셋 YAML 정의
|
||||
│ │ ├── session/ # 멀티턴 채팅 + FTS5 세션 검색
|
||||
│ │ └── providers/ # LLM 제공자 추상화
|
||||
│ │
|
||||
│ ├── backtest/ # 백테스트 엔진
|
||||
│ │ ├── engines/ # 7개 엔진: china_a, global_equity, crypto, china_futures, global_futures, forex + options_portfolio
|
||||
│ │ ├── loaders/ # 5개 소스: tushare, okx, yfinance, akshare, ccxt
|
||||
│ │ │ ├── base.py # DataLoader Protocol
|
||||
│ │ │ └── registry.py # 레지스트리 + 자동 폴백 체인
|
||||
│ │ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│ │
|
||||
│ └── config/swarm/ # 29개 스웜 프리셋 YAML 정의
|
||||
│ └── backtest/ # 백테스트 엔진
|
||||
│ ├── engines/ # 7개 엔진 + 크로스마켓 복합 엔진 + options_portfolio
|
||||
│ ├── loaders/ # 6개 소스: tushare, okx, yfinance, akshare, ccxt, futu
|
||||
│ │ ├── base.py # DataLoader Protocol
|
||||
│ │ └── registry.py # 레지스트리 + 자동 폴백 체인
|
||||
│ └── optimizers/ # MVO, equal vol, max div, risk parity
|
||||
│
|
||||
├── frontend/ # Web UI (React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
@@ -579,17 +611,21 @@ Vibe-Trading은 **[HKUDS](https://github.com/HKUDS)** 에이전트 생태계의
|
||||
|
||||
| Phase | Feature | Status |
|
||||
|-------|---------|--------|
|
||||
| **Agent Harness** | 크로스세션 영구 메모리 (저장 / 리콜 / 삭제) | **Done** |
|
||||
| | 자가 진화 스킬 — 에이전트가 스스로 워크플로우를 생성·수정·삭제 | **Done** |
|
||||
| | FTS5 크로스세션 검색 (모든 과거 대화 횡단) | **Done** |
|
||||
| | 5계층 컨텍스트 압축 (micro → collapse → auto → manual → iterative) | **Done** |
|
||||
| | 읽기/쓰기 도구 배치 처리 — 읽기 전용 도구 병렬 실행 | **Done** |
|
||||
| **Next Up** | 자율 리서치 루프 — 에이전트가 밤새 가설을 반복 | In Progress |
|
||||
| | IM 통합 (Slack / Telegram / WeChat) | Planned |
|
||||
| **Analysis & Viz** | 옵션 변동성 서피스 및 그릭스 3D 시각화 | Planned |
|
||||
| | 롤링 윈도우 + 클러스터링 기반 크로스자산 상관 히트맵 | Planned |
|
||||
| | CLI 백테스트 출력에 벤치마크 비교 | Planned |
|
||||
| | 백테스트 지표에 Calmar Ratio & Omega Ratio | Planned |
|
||||
| **Skills & Presets** | 배당 분석 스킬 | Planned |
|
||||
| | ESG / 지속가능 투자 스웜 프리셋 | Planned |
|
||||
| | 이머징 마켓 리서치 데스크 스웜 프리셋 | Planned |
|
||||
| **Portfolio & Optimization** | 레버리지, 섹터 캡, 턴오버 제약을 포함한 고급 포트폴리오 옵티마이저 | Planned |
|
||||
| **Future** | 초보자 튜토리얼: "5분 자연어 백테스트" | Planned |
|
||||
| **Future** | 전략 마켓플레이스 (공유 & 발견) | Exploring |
|
||||
| | WebSocket 기반 실시간 데이터 스트리밍 | Exploring |
|
||||
| | 전략 마켓플레이스(공유 & 발견) | Exploring |
|
||||
|
||||
---
|
||||
|
||||
@@ -623,6 +659,12 @@ MIT License — [LICENSE](LICENSE) 참조
|
||||
|
||||
---
|
||||
|
||||
## 스타 히스토리
|
||||
|
||||
[](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
방문해 주셔서 감사합니다 <b>Vibe-Trading</b> ✨
|
||||
</p>
|
||||
|
||||
+107
-65
@@ -1,5 +1,5 @@
|
||||
<p align="center">
|
||||
<a href="README.md">English</a> | <b>中文</b> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a>
|
||||
<a href="README.md">English</a> | <b>中文</b> | <a href="README_ja.md">日本語</a> | <a href="README_ko.md">한국어</a> | <a href="README_ar.md">العربية</a>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -19,10 +19,10 @@
|
||||
<a href="https://pypi.org/project/vibe-trading-ai/"><img src="https://img.shields.io/pypi/v/vibe-trading-ai?style=flat&logo=pypi&logoColor=white" alt="PyPI"></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/License-MIT-yellow?style=flat" alt="License"></a>
|
||||
<br>
|
||||
<img src="https://img.shields.io/badge/Skills-68-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Skills-72-orange" alt="Skills">
|
||||
<img src="https://img.shields.io/badge/Swarm_Presets-29-7C3AED" alt="Swarm">
|
||||
<img src="https://img.shields.io/badge/Tools-21-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-5-2563EB" alt="Data Sources">
|
||||
<img src="https://img.shields.io/badge/Tools-27-0F766E" alt="Tools">
|
||||
<img src="https://img.shields.io/badge/Data_Sources-6-2563EB" alt="Data Sources">
|
||||
<br>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/Feishu-Group-E9DBFC?style=flat-square&logo=feishu&logoColor=white" alt="Feishu"></a>
|
||||
<a href="https://github.com/HKUDS/.github/blob/main/profile/README.md"><img src="https://img.shields.io/badge/WeChat-Group-C5EAB4?style=flat-square&logo=wechat&logoColor=white" alt="WeChat"></a>
|
||||
@@ -51,10 +51,29 @@
|
||||
|
||||
## 📰 新闻
|
||||
|
||||
- **2026-04-10** 📦 **v0.1.4**:修复 Docker 构建([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)),新增 `web_search` MCP 工具(共 17 个),在依赖与 MCP 中加入 `akshare`/`ccxt`。支持 11 家 LLM 提供商(DeepSeek、Groq、Gemini、Ollama 等),全部调优参数可通过 `.env` 配置。加固 `ml-strategy` 技能。已发布至 PyPI 和 ClawHub。
|
||||
- **2026-04-09** 📊 **回测 Wave 2 —— 多资产引擎**:新增 ChinaFutures(CFFEX/SHFE/DCE/ZCE,50+ 合约)、GlobalFutures(CME/ICE/Eurex,30+ 合约)、Forex(24 货币对,点差 + 掉期)、Options v2(美式行权、IV 微笑)。统计验证:蒙特卡洛置换检验、Bootstrap 夏普区间、Walk-Forward 分析。
|
||||
- **2026-04-08** 🔧 **多市场回测** 支持分市场规则;**TradingView Pine Script v6 导出**。**数据源扩展**:5 源自动回退,`web_search` 工具,技能分 7 类。
|
||||
- **2026-04-01** 🚀 **v0.1.0** —— 初始发布:ReAct 代理,64 技能,29 个 swarm 预设,跨市场回测,CLI + Web UI + MCP 服务器。
|
||||
- **2026-04-28** 🚀 **v0.1.6 发布**(`pip install -U vibe-trading-ai`):修复 `pip install` / `uv tool install` 安装后 `vibe-trading --swarm-presets` 返回空的问题([#55](https://github.com/HKUDS/Vibe-Trading/issues/55))—— 预设 YAML 现已打包进 `src.swarm` 包内,配套 6 个回归测试。同时 AKShare 加载器正确路由 ETF(`510300.SH`)和外汇(`USDCNH`)到对应端点,并加固注册表回退链。汇总自 v0.1.5 以来全部更新:基准对比面板、`/upload` 流式上传 + 大小限制、富途数据源(港股/A 股)、vnpy 导出技能、安全加固、前端懒加载(688KB → 262KB)。
|
||||
- **2026-04-27** 📊 **基准对比面板 + 上传安全**:回测输出新增基准对比面板(标的 / 基准收益 / 超额收益 / 信息比率),通过 yfinance 解析 SPY、沪深 300 等基准([#48](https://github.com/HKUDS/Vibe-Trading/issues/48))。同时 `/upload` 端点改为 1MB 分块流式落盘,超过 `MAX_UPLOAD_SIZE` 立即中断并清理半截文件,让 50MB 上限在恶意/超大请求下真正生效([#53](https://github.com/HKUDS/Vibe-Trading/pull/53))—— 配套 4 个回归测试。
|
||||
- **2026-04-22** 🛡️ **加固 + 新接入**:`safe_path` 强制路径包含校验 + 交割单/影子账户工具沙箱化,新增 `MANIFEST.in` 让 sdist 打包 `.env.example` / 测试 / Docker 文件,前端按路由懒加载把首屏包从 688KB 压到 262KB。同时新增富途港股/A 股数据加载器([#47](https://github.com/HKUDS/Vibe-Trading/pull/47))和 vnpy CtaTemplate 导出技能([#46](https://github.com/HKUDS/Vibe-Trading/pull/46))。
|
||||
|
||||
<details>
|
||||
<summary>更早的新闻</summary>
|
||||
|
||||
- **2026-04-21** 🛡️ **工作区与文档**:相对路径 `run_dir` 归一化到当前 run 目录([#43](https://github.com/HKUDS/Vibe-Trading/pull/43))。README 加入使用示例([#45](https://github.com/HKUDS/Vibe-Trading/pull/45))。
|
||||
- **2026-04-20** 🔌 **推理模型与 Swarm 修复**:`reasoning_content` 在所有 `ChatOpenAI` 序列化路径上保留 —— Kimi / DeepSeek / Qwen thinking 端到端可用([#39](https://github.com/HKUDS/Vibe-Trading/issues/39))。Swarm 切流式调用 + 干净的 Ctrl+C 退出([#42](https://github.com/HKUDS/Vibe-Trading/issues/42))。
|
||||
- **2026-04-19** 📦 **v0.1.5**:发布至 PyPI 与 ClawHub。`python-multipart` CVE 版本下限升级,5 个新 MCP 工具接入(`analyze_trade_journal` + 4 个影子账户工具),修复 `pattern_recognition` → `pattern` 工具注册名不一致,Docker 依赖对齐,SKILL 清单同步(22 MCP 工具 / 71 技能)。
|
||||
- **2026-04-18** 👥 **影子账户 Shadow Account**:从券商交割单提取你自己的策略规则 → 跨市场回测这个"影子" → 8 节 HTML/PDF 报告精确告诉你每一块钱是怎么错过的(规则违反、过早止盈、漏掉信号、反向操作)。4 个新工具、1 个新技能、共 32 工具。Trade Journal / Shadow Account 例句已进 Web UI 欢迎屏。
|
||||
- **2026-04-17** 📊 **交割单分析器 + 通用文件阅读器**:上传券商交割单(同花顺/东财/富途/通用 CSV)→ 自动生成交易画像(持仓天数、胜率、盈亏比、最大回撤)+ 4 项行为偏差诊断(处置效应、过度交易、追涨杀跌、锚定效应)。`read_document` 现统一分发 PDF、Word、Excel、PowerPoint、图片(OCR)及 40+ 文本格式,一个调用走全部类型。
|
||||
- **2026-04-16** 🧠 **Agent Harness**:跨会话持久记忆、FTS5 会话搜索、自进化技能(完整 CRUD)、5 层上下文压缩、读写工具批处理。27 工具,107 新测试。
|
||||
- **2026-04-15** 🤖 **Z.ai + MiniMax**:新增 Z.ai 提供商([#35](https://github.com/HKUDS/Vibe-Trading/pull/35)),修复 MiniMax temperature 及模型更新([#33](https://github.com/HKUDS/Vibe-Trading/pull/33))。共 13 家提供商。
|
||||
- **2026-04-14** 🔧 **MCP 稳定性**:修复回测工具在 stdio 传输中的 `Connection closed` 错误([#32](https://github.com/HKUDS/Vibe-Trading/pull/32))。
|
||||
- **2026-04-13** 🌐 **跨市场复合回测**:新增 `CompositeEngine`,混合不同市场标的(如 A 股 + 加密货币)共享资金池回测,各市场规则按标的独立执行。同时修复 swarm 模板变量回退和前端超时问题。
|
||||
- **2026-04-12** 🌍 **多平台指标导出**:`/pine` 一次性导出 TradingView (Pine Script v6)、通达信/同花顺/东方财富 (TDX)、MetaTrader 5 (MQL5) 三大平台。
|
||||
- **2026-04-11** 🛡️ **可靠性与 DX**:`vibe-trading init` .env 引导([#19](https://github.com/HKUDS/Vibe-Trading/pull/19)),启动预检、数据源自动回退、回测引擎加固。多语言 README([#21](https://github.com/HKUDS/Vibe-Trading/pull/21))。
|
||||
- **2026-04-10** 📦 **v0.1.4**:Docker 修复([#8](https://github.com/HKUDS/Vibe-Trading/issues/8)),`web_search` MCP 工具,12 家 LLM 提供商,`akshare`/`ccxt` 依赖。已发布至 PyPI 和 ClawHub。
|
||||
- **2026-04-09** 📊 **回测 Wave 2**:新增 ChinaFutures、GlobalFutures、Forex、Options v2 引擎。蒙特卡洛、Bootstrap CI、Walk-Forward 统计验证。
|
||||
- **2026-04-08** 🔧 **多市场回测**:分市场规则,Pine Script v6 导出,5 数据源自动回退。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
@@ -63,12 +82,12 @@
|
||||
Vibe-Trading 是一个由 AI 驱动的多代理金融工作台,将自然语言请求转化为可执行的交易策略、研究洞见和跨全球市场的投资组合分析。
|
||||
|
||||
### 核心能力:
|
||||
• **Strategy Generation** —— 从你的想法自动生成交易代码<br>
|
||||
• **Smart Data Access** —— 5 大数据源自动回退;所有市场零配置<br>
|
||||
• **Performance Testing** —— 使用历史行情测试你的策略<br>
|
||||
• **TradingView Export** —— 一键转换为 TradingView 的 Pine Script v6<br>
|
||||
• **Expert Teams** —— 部署专职 AI 代理处理复杂研究任务<br>
|
||||
• **Live Updates** —— 全程实时查看分析过程
|
||||
• **自然语言 → 策略** —— 描述想法,代理自动编写、测试、导出交易代码<br>
|
||||
• **5 大数据源,零配置** —— A 股、港美股、加密、期货、外汇自动回退<br>
|
||||
• **29 支专家团队** —— 预构建的多代理 swarm 工作流,覆盖投资、交易与风控<br>
|
||||
• **跨会话记忆** —— 记住偏好与洞察;自动创建、进化可复用技能<br>
|
||||
• **7 大回测引擎** —— 跨市场复合测试 + 统计验证 + 4 种优化器<br>
|
||||
• **多平台导出** —— 一键到 TradingView、TDX(通达信/同花顺)和 MetaTrader 5
|
||||
|
||||
---
|
||||
|
||||
@@ -79,12 +98,12 @@ Vibe-Trading 是一个由 AI 驱动的多代理金融工作台,将自然语言
|
||||
<td align="center" width="25%" valign="top">
|
||||
<img src="assets/scene-research.png" height="150" alt="Research"/><br>
|
||||
<h3>🔍 面向交易的深度研究</h3>
|
||||
<img src="https://img.shields.io/badge/68_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<img src="https://img.shields.io/badge/72_Skills-FF6B6B?style=for-the-badge&logo=bookstack&logoColor=white" alt="Skills" /><br><br>
|
||||
<div align="left" style="font-size: 4px;">
|
||||
• 覆盖多市场的多领域分析<br>
|
||||
• 自动生成策略与信号<br>
|
||||
• 宏观经济研究与洞察<br>
|
||||
• 基于聊天的自然语言任务路由
|
||||
• 72 个专长技能 + 跨会话持久记忆<br>
|
||||
• 自进化:代理从经验中创建并优化工作流<br>
|
||||
• 5 层上下文压缩——长对话不丢失信息<br>
|
||||
• 覆盖全金融领域的自然语言任务路由
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -94,8 +113,8 @@ Vibe-Trading 是一个由 AI 驱动的多代理金融工作台,将自然语言
|
||||
<div align="left">
|
||||
• 29 个开箱即用的交易团队预设<br>
|
||||
• 基于 DAG 的多代理编排<br>
|
||||
• 实时决策流式仪表盘<br>
|
||||
• 通过 YAML 自定义团队
|
||||
• 实时流式仪表盘,显示代理运行状态<br>
|
||||
• FTS5 跨会话搜索全部历史对话
|
||||
</div>
|
||||
</td>
|
||||
<td align="center" width="25%" valign="top">
|
||||
@@ -104,7 +123,7 @@ Vibe-Trading 是一个由 AI 驱动的多代理金融工作台,将自然语言
|
||||
<img src="https://img.shields.io/badge/5_Data_Sources-FFD93D?style=for-the-badge&logo=bitcoin&logoColor=black" alt="Backtest" /><br><br>
|
||||
<div align="left">
|
||||
• A 股、港美股、加密、期货与外汇<br>
|
||||
• 7 个市场引擎:A 股、美港股、加密、中国期货、全球期货、外汇<br>
|
||||
• 7 个市场引擎 + 跨市场复合引擎(共享资金池)<br>
|
||||
• 统计验证:蒙特卡洛、Bootstrap 置信区间、Walk-Forward<br>
|
||||
• 15+ 绩效指标与 4 种优化器
|
||||
</div>
|
||||
@@ -123,16 +142,16 @@ Vibe-Trading 是一个由 AI 驱动的多代理金融工作台,将自然语言
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## 7 大类别中的 68 个技能
|
||||
## 7 大类别中的 72 个技能
|
||||
|
||||
- 📊 68 个金融专长技能,划分 7 大类
|
||||
- 📊 72 个金融专长技能,划分 7 大类
|
||||
- 🌐 覆盖传统市场到加密与 DeFi
|
||||
- 🔬 覆盖数据获取到量化研究的全链路能力
|
||||
|
||||
| Category | Skills | Examples |
|
||||
|----------|--------|----------|
|
||||
| Data Source | 6 | `data-routing`, `tushare`, `yfinance`, `okx-market`, `akshare`, `ccxt` |
|
||||
| Strategy | 16 | `strategy-generate`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Strategy | 17 | `strategy-generate`, `cross-market-strategy`, `technical-basic`, `candlestick`, `ichimoku`, `elliott-wave`, `smc`, `multi-factor`, `ml-strategy` |
|
||||
| Analysis | 15 | `factor-research`, `macro-analysis`, `global-macro`, `valuation-model`, `earnings-forecast`, `credit-analysis` |
|
||||
| Asset Class | 9 | `options-strategy`, `options-advanced`, `convertible-bond`, `etf-analysis`, `asset-allocation`, `sector-rotation` |
|
||||
| Crypto | 7 | `perp-funding-basis`, `liquidation-heatmap`, `stablecoin-flow`, `defi-yield`, `onchain-analysis` |
|
||||
@@ -221,7 +240,7 @@ vibe-trading-mcp # 启动 MCP 服务器(stdio)
|
||||
- Path B 需 **Python 3.11+**
|
||||
- Path A 需 **Docker**
|
||||
|
||||
> **支持的 LLM 提供商:** OpenRouter、OpenAI、DeepSeek、Gemini、Groq、DashScope/Qwen、智谱、Moonshot/Kimi、MiniMax、小米 MIMO、Ollama(本地)。参见 `.env.example` 配置。
|
||||
> **支持的 LLM 提供商:** OpenRouter、OpenAI、DeepSeek、Gemini、Groq、DashScope/Qwen、智谱、Moonshot/Kimi、MiniMax、小米 MIMO、Z.ai、Ollama(本地)。参见 `.env.example` 配置。
|
||||
|
||||
> **提示:** 所有市场都可在无 API key 情况下运行,因自动回退。yfinance(港美股)、OKX(加密)、AKShare(A 股、美股、港股、期货、外汇)均免费。Tushare token 可选——A 股可回退到 AKShare 免费获取。
|
||||
|
||||
@@ -295,7 +314,7 @@ npx clawhub@latest install vibe-trading --force
|
||||
|
||||
| Variable | Required | Description |
|
||||
|----------|:--------:|-------------|
|
||||
| `LANGCHAIN_PROVIDER` | Yes | 提供商名称(`openrouter`、`deepseek`、`groq`、`ollama` 等) |
|
||||
| `LANGCHAIN_PROVIDER` | Yes | 提供商名称(`openrouter`、`deepseek`、`groq`、`z.ai`、`ollama` 等) |
|
||||
| `<PROVIDER>_API_KEY` | Yes* | API key(`OPENROUTER_API_KEY`、`DEEPSEEK_API_KEY` 等) |
|
||||
| `<PROVIDER>_BASE_URL` | Yes | API 端点 URL |
|
||||
| `LANGCHAIN_MODEL_NAME` | Yes | 模型名(如 `deepseek/deepseek-v3.2`) |
|
||||
@@ -306,6 +325,18 @@ npx clawhub@latest install vibe-trading --force
|
||||
|
||||
**免费数据(无需 key):** A 股经 AKShare,港美股经 yfinance,加密经 OKX,100+ 加密交易所经 CCXT。系统会为每个市场自动选择最佳可用数据源。
|
||||
|
||||
### 🎯 推荐模型
|
||||
|
||||
Vibe-Trading 是重度依赖工具调用的 agent — skills、回测、记忆、swarm 全部通过 tool call 完成。模型选择直接决定 agent 是**真的在用工具**,还是从训练数据里编答案。
|
||||
|
||||
| 等级 | 示例 | 适用场景 |
|
||||
|------|------|---------|
|
||||
| **最佳** | `anthropic/claude-opus-4.7`、`anthropic/claude-sonnet-4.6`、`openai/gpt-5.4`、`google/gemini-3.1-pro-preview` | 复杂 swarm(3+ agent)、长研究会话、论文级分析 |
|
||||
| **性价比**(默认) | `deepseek/deepseek-v3.2`、`x-ai/grok-4.20`、`z-ai/glm-5.1`、`moonshotai/kimi-k2.5`、`qwen/qwen3-max-thinking` | 日常使用 — tool-calling 稳定,成本约 1/10 |
|
||||
| **不建议用于 agent** | `*-nano`、`*-flash-lite`、`*-coder-next`、小参数 / 蒸馏版 | tool-calling 不可靠 — agent 会"凭记忆回答"而不加载 skill 或跑回测 |
|
||||
|
||||
默认 `agent/.env.example` 使用 `deepseek/deepseek-v3.2` — 性价比档里最便宜的选项。
|
||||
|
||||
---
|
||||
|
||||
## 🖥 CLI 参考
|
||||
@@ -322,7 +353,7 @@ vibe-trading serve # API 服务器
|
||||
| Command | Description |
|
||||
|---------|-------------|
|
||||
| `/help` | 显示全部命令 |
|
||||
| `/skills` | 列出 68 个金融技能 |
|
||||
| `/skills` | 列出 72 个金融技能 |
|
||||
| `/swarm` | 列出 29 个 swarm 团队预设 |
|
||||
| `/swarm run <preset> [vars_json]` | 以流式输出运行一个 swarm 团队 |
|
||||
| `/swarm list` | Swarm 运行历史 |
|
||||
@@ -331,7 +362,7 @@ vibe-trading serve # API 服务器
|
||||
| `/list` | 最近的运行 |
|
||||
| `/show <run_id>` | 运行详情与指标 |
|
||||
| `/code <run_id>` | 生成的策略代码 |
|
||||
| `/pine <run_id>` | TradingView 的 Pine Script |
|
||||
| `/pine <run_id>` | 导出指标代码(TradingView + TDX + MT5)|
|
||||
| `/trace <run_id>` | 完整执行回放 |
|
||||
| `/continue <run_id> <prompt>` | 带新指令继续运行 |
|
||||
| `/sessions` | 列出聊天会话 |
|
||||
@@ -358,7 +389,7 @@ vibe-trading --swarm-run investment_committee '{"topic":"BTC outlook"}'
|
||||
vibe-trading --list
|
||||
vibe-trading --show <run_id>
|
||||
vibe-trading --code <run_id>
|
||||
vibe-trading --pine <run_id> # TradingView 的 Pine Script
|
||||
vibe-trading --pine <run_id> # 导出指标代码(TradingView + TDX + MT5)
|
||||
vibe-trading --trace <run_id>
|
||||
vibe-trading --continue <run_id> "refine the strategy"
|
||||
vibe-trading --upload report.pdf
|
||||
@@ -378,7 +409,7 @@ vibe-trading serve --port 8899
|
||||
|--------|----------|-------------|
|
||||
| `GET` | `/runs` | 列出运行 |
|
||||
| `GET` | `/runs/{run_id}` | 运行详情 |
|
||||
| `GET` | `/runs/{run_id}/pine` | Pine Script 导出 |
|
||||
| `GET` | `/runs/{run_id}/pine` | 多平台指标导出 |
|
||||
| `POST` | `/sessions` | 创建会话 |
|
||||
| `POST` | `/sessions/{id}/messages` | 发送消息 |
|
||||
| `GET` | `/sessions/{id}/events` | SSE 事件流 |
|
||||
@@ -393,7 +424,7 @@ vibe-trading serve --port 8899
|
||||
|
||||
## 🔌 MCP 插件
|
||||
|
||||
Vibe-Trading 为任意 MCP 兼容客户端提供 17 个 MCP 工具。以 stdio 子进程运行——无需服务器部署。**17 个工具中有 16 个无需任何 API key**(港美股/加密)。仅 `run_swarm` 需要 LLM key。
|
||||
Vibe-Trading 为任意 MCP 兼容客户端提供 22 个 MCP 工具。以 stdio 子进程运行——无需服务器部署。**22 个工具中有 21 个无需任何 API key**(港美股/加密)。仅 `run_swarm` 需要 LLM key。
|
||||
|
||||
<details>
|
||||
<summary><b>Claude Desktop</b></summary>
|
||||
@@ -435,7 +466,7 @@ vibe-trading-mcp --transport sse # 供 Web 客户端的 SSE
|
||||
|
||||
</details>
|
||||
|
||||
**已暴露的 MCP 工具(17):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`。
|
||||
**已暴露的 MCP 工具(22):** `list_skills`, `load_skill`, `backtest`, `factor_analysis`, `analyze_options`, `pattern_recognition`, `get_market_data`, `web_search`, `read_url`, `read_document`, `read_file`, `write_file`, `analyze_trade_journal`, `extract_shadow_strategy`, `run_shadow_backtest`, `render_shadow_report`, `scan_shadow_signals`, `list_swarm_presets`, `run_swarm`, `get_swarm_status`, `get_run_result`, `list_runs`。
|
||||
|
||||
<details>
|
||||
<summary><b>ClawHub 一键安装</b></summary>
|
||||
@@ -455,7 +486,7 @@ npx clawhub@latest install vibe-trading --force
|
||||
<details>
|
||||
<summary><b>OpenSpace — 自进化技能</b></summary>
|
||||
|
||||
全部 68 个金融技能已发布在 [open-space.cloud](https://open-space.cloud),并通过 OpenSpace 的自进化引擎自动演进。
|
||||
全部 72 个金融技能已发布在 [open-space.cloud](https://open-space.cloud),并通过 OpenSpace 的自进化引擎自动演进。
|
||||
|
||||
要在 OpenSpace 中使用,在代理配置中添加两个 MCP 服务器:
|
||||
|
||||
@@ -477,7 +508,7 @@ npx clawhub@latest install vibe-trading --force
|
||||
}
|
||||
```
|
||||
|
||||
OpenSpace 会自动发现全部 68 个技能,支持自动修复、自动改进与社区共享。在任意连接 OpenSpace 的代理中通过 `search_skills("finance backtest")` 搜索 Vibe-Trading 技能。
|
||||
OpenSpace 会自动发现全部 72 个技能,支持自动修复、自动改进与社区共享。在任意连接 OpenSpace 的代理中通过 `search_skills("finance backtest")` 搜索 Vibe-Trading 技能。
|
||||
|
||||
</details>
|
||||
|
||||
@@ -493,41 +524,42 @@ Vibe-Trading/
|
||||
├── agent/ # 后端(Python)
|
||||
│ ├── cli.py # CLI 入口——交互式 TUI + 子命令
|
||||
│ ├── api_server.py # FastAPI 服务器——运行、会话、上传、swarm、SSE
|
||||
│ ├── mcp_server.py # MCP 服务器——为 OpenClaw / Claude Desktop 提供 17 个工具
|
||||
│ ├── mcp_server.py # MCP 服务器——为 OpenClaw / Claude Desktop 提供 22 个工具
|
||||
│ │
|
||||
│ ├── src/
|
||||
│ │ ├── agent/ # ReAct 代理核心
|
||||
│ │ │ ├── loop.py # 主推理循环
|
||||
│ │ │ ├── skills.py # 技能加载器(68 个 SKILL.md,7 类)
|
||||
│ │ │ ├── tools.py # 工具编排
|
||||
│ │ │ ├── context.py # 系统提示构建器
|
||||
│ │ │ ├── memory.py # 运行记忆 / artifact 存储
|
||||
│ │ │ ├── loop.py # 5 层压缩 + 读写工具批处理
|
||||
│ │ │ ├── context.py # 系统提示 + 持久记忆自动召回
|
||||
│ │ │ ├── skills.py # 技能加载器(69 内置 + 用户 CRUD 创建)
|
||||
│ │ │ ├── tools.py # 工具基类 + 注册表
|
||||
│ │ │ ├── memory.py # 单次运行轻量工作区状态
|
||||
│ │ │ ├── frontmatter.py # 共享 YAML frontmatter 解析器
|
||||
│ │ │ └── trace.py # 执行轨迹写入
|
||||
│ │ │
|
||||
│ │ ├── tools/ # 21 个代理工具
|
||||
│ │ │ ├── backtest_tool.py # 运行回测
|
||||
│ │ │ ├── factor_analysis_tool.py
|
||||
│ │ │ ├── options_pricing_tool.py
|
||||
│ │ │ ├── pattern_tool.py # 图表形态检测
|
||||
│ │ │ ├── doc_reader_tool.py # PDF 阅读(OCR 回退)
|
||||
│ │ │ ├── web_reader_tool.py # 网页读取(Jina)
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo 搜索
|
||||
│ │ │ ├── swarm_tool.py # 启动 swarm 团队
|
||||
│ │ │ └── ... # 文件 I/O、bash、任务等
|
||||
│ │ ├── memory/ # 跨会话持久记忆
|
||||
│ │ │ └── persistent.py # 基于文件的记忆(~/.vibe-trading/memory/)
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 68 个金融技能(7 类,每个 SKILL.md)
|
||||
│ │ ├── tools/ # 27 个自动发现的代理工具
|
||||
│ │ │ ├── backtest_tool.py # 运行回测
|
||||
│ │ │ ├── remember_tool.py # 跨会话记忆(保存/召回/遗忘)
|
||||
│ │ │ ├── skill_writer_tool.py # 技能 CRUD(保存/修补/删除/文件)
|
||||
│ │ │ ├── session_search_tool.py # FTS5 跨会话搜索
|
||||
│ │ │ ├── swarm_tool.py # 启动 swarm 团队
|
||||
│ │ │ ├── web_search_tool.py # DuckDuckGo 搜索
|
||||
│ │ │ └── ... # bash、文件 I/O、因子分析、期权等
|
||||
│ │ │
|
||||
│ │ ├── skills/ # 72 个金融技能(7 类,每个 SKILL.md)
|
||||
│ │ ├── swarm/ # Swarm DAG 执行引擎
|
||||
│ │ ├── session/ # 多轮对话管理
|
||||
│ │ │ └── presets/ # 29 个 swarm 预设 YAML 定义
|
||||
│ │ ├── session/ # 多轮对话 + FTS5 会话搜索
|
||||
│ │ └── providers/ # LLM 提供商抽象
|
||||
│ │
|
||||
│ ├── backtest/ # 回测引擎
|
||||
│ │ ├── engines/ # 7 个引擎:china_a、global_equity、crypto、china_futures、global_futures、forex + options_portfolio
|
||||
│ │ ├── loaders/ # 5 个数据源:tushare、okx、yfinance、akshare、ccxt
|
||||
│ │ │ ├── base.py # DataLoader Protocol
|
||||
│ │ │ └── registry.py # 注册表 + 自动回退链
|
||||
│ │ └── optimizers/ # MVO、等波动、最大分散、风险平价
|
||||
│ │
|
||||
│ └── config/swarm/ # 29 个 swarm 预设 YAML 定义
|
||||
│ └── backtest/ # 回测引擎
|
||||
│ ├── engines/ # 7 个引擎 + 跨市场复合引擎 + options_portfolio
|
||||
│ ├── loaders/ # 6 个数据源:tushare、okx、yfinance、akshare、ccxt、futu
|
||||
│ │ ├── base.py # DataLoader Protocol
|
||||
│ │ └── registry.py # 注册表 + 自动回退链
|
||||
│ └── optimizers/ # MVO、等波动、最大分散、风险平价
|
||||
│
|
||||
├── frontend/ # Web UI(React 19 + Vite + TypeScript)
|
||||
│ └── src/
|
||||
@@ -578,17 +610,21 @@ Vibe-Trading 属于 **[HKUDS](https://github.com/HKUDS)** 代理生态的一部
|
||||
|
||||
| Phase | Feature | Status |
|
||||
|-------|---------|--------|
|
||||
| **Agent Harness** | 跨会话持久记忆(保存 / 召回 / 遗忘) | **Done** |
|
||||
| | 自进化技能——代理自主创建、修补和删除工作流 | **Done** |
|
||||
| | FTS5 跨会话搜索全部历史对话 | **Done** |
|
||||
| | 5 层上下文压缩(微压缩 → 折叠 → 自动 → 手动 → 迭代) | **Done** |
|
||||
| | 读写工具批处理——只读工具并行执行 | **Done** |
|
||||
| **Next Up** | 自主研究循环——代理通宵迭代假设 | In Progress |
|
||||
| | IM 集成(Slack / Telegram / 微信) | Planned |
|
||||
| **Analysis & Viz** | 期权波动率曲面与 Greeks 三维可视化 | Planned |
|
||||
| | 跨资产相关性热力图(滚动窗口 + 聚类) | Planned |
|
||||
| | CLI 回测输出中的基准对比 | Planned |
|
||||
| | 回测指标新增 Calmar Ratio 与 Omega Ratio | Planned |
|
||||
| **Skills & Presets** | 分红分析技能 | Planned |
|
||||
| | ESG / 可持续投资 swarm 预设 | Planned |
|
||||
| | 新兴市场研究台 swarm 预设 | Planned |
|
||||
| **Portfolio & Optimization** | 高级组合优化器:杠杆、行业上限、换手约束 | Planned |
|
||||
| **Future** | 新手教程:“5 分钟自然语言回测” | Planned |
|
||||
| **Future** | 策略市场(分享与发现) | Exploring |
|
||||
| | 通过 WebSocket 的实时数据流 | Exploring |
|
||||
| | 策略市场(分享与发现) | Exploring |
|
||||
|
||||
---
|
||||
|
||||
@@ -622,6 +658,12 @@ MIT 许可证——参见 [LICENSE](LICENSE)
|
||||
|
||||
---
|
||||
|
||||
## Star 历史
|
||||
|
||||
[](https://star-history.com/#HKUDS/Vibe-Trading&Date)
|
||||
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
感谢关注 <b>Vibe-Trading</b> ✨
|
||||
</p>
|
||||
|
||||
+26
@@ -0,0 +1,26 @@
|
||||
# Security Policy
|
||||
|
||||
## Supported Versions
|
||||
|
||||
| Version | Supported |
|
||||
|---------|:---------:|
|
||||
| latest | ✅ |
|
||||
|
||||
## Reporting a Vulnerability
|
||||
|
||||
If you discover a security vulnerability, please report it responsibly:
|
||||
|
||||
1. **Do NOT open a public issue.**
|
||||
2. Use the [GitHub Security Advisory](https://github.com/HKUDS/Vibe-Trading/security/advisories/new) to report privately.
|
||||
3. Include steps to reproduce, potential impact, and any suggested fixes.
|
||||
|
||||
We will acknowledge your report within **5 business days** and work with you to resolve the issue.
|
||||
|
||||
## Scope
|
||||
|
||||
This policy applies to the [HKUDS/Vibe-Trading](https://github.com/HKUDS/Vibe-Trading) repository.
|
||||
|
||||
## Disclosure
|
||||
|
||||
- Please do not publicly disclose the vulnerability until we have released a fix.
|
||||
- We will credit reporters in the release notes (unless you prefer anonymity).
|
||||
+58
-32
@@ -1,89 +1,115 @@
|
||||
# ============================================================================
|
||||
# LLM Provider — uncomment ONE block below
|
||||
# LLM Provider — uncomment ONE provider block below
|
||||
# ============================================================================
|
||||
LANGCHAIN_TEMPERATURE=0.0
|
||||
|
||||
# --- OpenRouter ---
|
||||
# --- OpenRouter (recommended, multi-model gateway) ---
|
||||
LANGCHAIN_PROVIDER=openrouter
|
||||
LANGCHAIN_MODEL_NAME=deepseek/deepseek-v3.2
|
||||
OPENROUTER_API_KEY=sk-or-v1-your-key-here
|
||||
OPENROUTER_BASE_URL=https://openrouter.ai/api/v1
|
||||
LANGCHAIN_MODEL_NAME=deepseek/deepseek-v3.2
|
||||
|
||||
# --- DeepSeek ---
|
||||
# LANGCHAIN_PROVIDER=deepseek
|
||||
# DEEPSEEK_API_KEY=sk-xxx
|
||||
# DEEPSEEK_BASE_URL=https://api.deepseek.com/v1
|
||||
# LANGCHAIN_MODEL_NAME=deepseek-chat
|
||||
|
||||
# --- OpenAI ---
|
||||
# LANGCHAIN_PROVIDER=openai
|
||||
# LANGCHAIN_MODEL_NAME=gpt-4o
|
||||
# OPENAI_API_KEY=sk-xxx
|
||||
# OPENAI_BASE_URL=https://api.openai.com/v1
|
||||
# LANGCHAIN_MODEL_NAME=gpt-4o
|
||||
|
||||
# --- DeepSeek ---
|
||||
# LANGCHAIN_PROVIDER=deepseek
|
||||
# LANGCHAIN_MODEL_NAME=deepseek-chat
|
||||
# DEEPSEEK_API_KEY=sk-xxx
|
||||
# DEEPSEEK_BASE_URL=https://api.deepseek.com/v1
|
||||
|
||||
# --- Gemini ---
|
||||
# LANGCHAIN_PROVIDER=gemini
|
||||
# LANGCHAIN_MODEL_NAME=gemini-2.5-flash
|
||||
# GEMINI_API_KEY=xxx
|
||||
# GEMINI_BASE_URL=https://generativelanguage.googleapis.com/v1beta/openai/
|
||||
# LANGCHAIN_MODEL_NAME=gemini-2.5-flash
|
||||
|
||||
# --- Groq ---
|
||||
# LANGCHAIN_PROVIDER=groq
|
||||
# LANGCHAIN_MODEL_NAME=llama-3.3-70b-versatile
|
||||
# GROQ_API_KEY=gsk_xxx
|
||||
# GROQ_BASE_URL=https://api.groq.com/openai/v1
|
||||
# LANGCHAIN_MODEL_NAME=llama-3.3-70b-versatile
|
||||
|
||||
# --- DashScope / Qwen ---
|
||||
# LANGCHAIN_PROVIDER=dashscope
|
||||
# LANGCHAIN_MODEL_NAME=qwen-plus
|
||||
# DASHSCOPE_API_KEY=sk-xxx
|
||||
# DASHSCOPE_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
|
||||
# LANGCHAIN_MODEL_NAME=qwen-plus
|
||||
|
||||
# --- Zhipu ---
|
||||
# LANGCHAIN_PROVIDER=zhipu
|
||||
# LANGCHAIN_MODEL_NAME=glm-4-plus
|
||||
# ZHIPU_API_KEY=xxx
|
||||
# ZHIPU_BASE_URL=https://open.bigmodel.cn/api/paas/v4
|
||||
# LANGCHAIN_MODEL_NAME=glm-4-plus
|
||||
|
||||
# --- Moonshot / Kimi ---
|
||||
# LANGCHAIN_PROVIDER=moonshot
|
||||
# LANGCHAIN_MODEL_NAME=kimi-k2.5
|
||||
# MOONSHOT_API_KEY=sk-xxx
|
||||
# MOONSHOT_BASE_URL=https://api.moonshot.ai/v1
|
||||
# LANGCHAIN_MODEL_NAME=kimi-k2.5
|
||||
|
||||
# --- MiniMax ---
|
||||
# LANGCHAIN_PROVIDER=minimax
|
||||
# LANGCHAIN_MODEL_NAME=MiniMax-M2.7 # or MiniMax-M2.7-highspeed (faster)
|
||||
# MINIMAX_API_KEY=xxx
|
||||
# MINIMAX_BASE_URL=https://api.minimax.io/v1
|
||||
# LANGCHAIN_MODEL_NAME=MiniMax-Text-01
|
||||
# Note: MiniMax requires temperature > 0. Set LANGCHAIN_TEMPERATURE=1.0 (default when using MiniMax)
|
||||
|
||||
# --- Xiaomi MIMO ---
|
||||
# LANGCHAIN_PROVIDER=mimo
|
||||
# LANGCHAIN_MODEL_NAME=MiMo-72B-A27B
|
||||
# MIMO_API_KEY=xxx
|
||||
# MIMO_BASE_URL=https://api.xiaomimimo.com/v1
|
||||
# LANGCHAIN_MODEL_NAME=MiMo-72B-A27B
|
||||
|
||||
# --- Ollama ---
|
||||
# --- Z.ai (for Coding Plan) ---
|
||||
# LANGCHAIN_PROVIDER=zai
|
||||
# LANGCHAIN_MODEL_NAME=glm-5.1
|
||||
# ZAI_API_KEY=xxx
|
||||
# ZAI_BASE_URL=https://api.z.ai/api/coding/paas/v4
|
||||
|
||||
# --- Ollama (local) ---
|
||||
# LANGCHAIN_PROVIDER=ollama
|
||||
# OLLAMA_BASE_URL=http://localhost:11434/v1
|
||||
# LANGCHAIN_MODEL_NAME=qwen2.5:32b
|
||||
# OLLAMA_BASE_URL=http://localhost:11434/v1
|
||||
|
||||
# ============================================================================
|
||||
# Data Providers
|
||||
# ============================================================================
|
||||
# A-shares: Tushare Pro (requires token, https://tushare.pro)
|
||||
TUSHARE_TOKEN=your-tushare-token
|
||||
# HK/US equities: yfinance (free, no key needed)
|
||||
# Crypto: OKX public API (free, no key needed)
|
||||
|
||||
# ============================================================================
|
||||
# Runtime
|
||||
# ============================================================================
|
||||
# LLM parameters
|
||||
LANGCHAIN_TEMPERATURE=0.0
|
||||
TIMEOUT_SECONDS=120
|
||||
MAX_RETRIES=2
|
||||
|
||||
# Enable reasoning on relays that require opt-in (e.g. OpenRouter thinking models).
|
||||
# Forwarded as extra_body.reasoning.effort = low / medium / high.
|
||||
# Leave unset for Moonshot / DeepSeek official APIs — they return reasoning_content by default.
|
||||
# LANGCHAIN_REASONING_EFFORT=medium
|
||||
|
||||
# ============================================================================
|
||||
# Swarm / Subagent tuning (optional, defaults are sensible)
|
||||
# Data Sources
|
||||
# ============================================================================
|
||||
# A-shares: Tushare Pro token (https://tushare.pro)
|
||||
TUSHARE_TOKEN=your-tushare-token
|
||||
# HK/US equities: yfinance (free, no config needed)
|
||||
# Crypto: OKX public API (free, no config needed)
|
||||
# Crypto fallback exchange (default: binance). Change if OKX is blocked:
|
||||
# CCXT_EXCHANGE=binance
|
||||
# HK / A-share equities via Futu OpenAPI (optional, requires FutuOpenD running locally)
|
||||
# Download FutuOpenD: https://www.futunn.com/download/openAPI
|
||||
# FUTU_HOST=127.0.0.1
|
||||
# FUTU_PORT=11111
|
||||
|
||||
# ============================================================================
|
||||
# API Server (optional)
|
||||
# ============================================================================
|
||||
# Bearer token for API auth (empty = no auth, dev mode)
|
||||
# API_AUTH_KEY=
|
||||
# CORS allowed origins (comma-separated)
|
||||
# CORS_ORIGINS=http://localhost:3000,http://localhost:5173,http://localhost:8000
|
||||
# Enable session runtime
|
||||
# ENABLE_SESSION_RUNTIME=true
|
||||
|
||||
# ============================================================================
|
||||
# Agent Tuning (optional, defaults are sensible)
|
||||
# ============================================================================
|
||||
# SWARM_WORKER_TIMEOUT=300
|
||||
# SWARM_WORKER_MAX_ITER=50
|
||||
|
||||
+34
-15
@@ -1,7 +1,7 @@
|
||||
---
|
||||
name: vibe-trading
|
||||
version: 0.1.4
|
||||
description: Professional finance research toolkit — backtesting (6 engines), factor analysis, options pricing, 68 finance skills, and 29 multi-agent swarm teams across 5 data sources (tushare, yfinance, okx, akshare, ccxt).
|
||||
version: 0.1.6
|
||||
description: Professional finance research toolkit — backtesting (7 engines + benchmark comparison panel), factor analysis, options pricing, 72 finance skills, 29 multi-agent swarm teams, Trade Journal analyzer, and Shadow Account (extract → backtest → render) across 6 data sources (tushare, yfinance, okx, akshare, ccxt, futu).
|
||||
dependencies:
|
||||
python: ">=3.11"
|
||||
pip:
|
||||
@@ -11,7 +11,7 @@ env:
|
||||
description: "Tushare API token for China A-share data (optional — HK/US/crypto work without any key)"
|
||||
required: false
|
||||
- name: OPENAI_API_KEY
|
||||
description: "OpenAI-compatible API key — only needed for run_swarm (multi-agent teams). All other 16 tools work without it."
|
||||
description: "OpenAI-compatible API key — only needed for run_swarm (multi-agent teams). All other tools work without it."
|
||||
required: false
|
||||
- name: LANGCHAIN_MODEL_NAME
|
||||
description: "LLM model name for run_swarm (e.g. deepseek/deepseek-v3.2). Only needed if using run_swarm."
|
||||
@@ -23,7 +23,7 @@ mcp:
|
||||
|
||||
# Vibe-Trading
|
||||
|
||||
Professional finance research toolkit with AI-powered backtesting (6 engines), multi-agent teams, and 68 specialized skills.
|
||||
Professional finance research toolkit with AI-powered backtesting (7 engines), multi-agent teams, 72 specialized skills, and the Shadow Account loop — extract your implicit trading rules from a journal, backtest them across A股/港股/美股/crypto, then see where they would have served you better.
|
||||
|
||||
## Setup
|
||||
|
||||
@@ -53,7 +53,7 @@ Add to your agent's MCP config:
|
||||
|
||||
### API Key Requirements
|
||||
|
||||
**16 of 17 MCP tools work with zero API keys.** After `pip install`, backtesting, market data, factor analysis, options pricing, chart patterns, web search, and all 68 skills are ready to use for HK/US equities and crypto.
|
||||
**21 of 22 MCP tools work with zero API keys.** After `pip install`, backtesting, market data, factor analysis, options pricing, chart patterns, web search, document reading, trade journal analysis, shadow-account extraction/backtest/report, and all 72 skills are ready to use for HK/US equities and crypto.
|
||||
|
||||
| Feature | Key needed | When |
|
||||
|---------|-----------|------|
|
||||
@@ -63,12 +63,22 @@ Add to your agent's MCP config:
|
||||
|
||||
## What You Can Do
|
||||
|
||||
### Shadow Account — flagship loop
|
||||
|
||||
Feed a CSV broker export (同花顺 / 东财 / 富途 / generic), and the agent will:
|
||||
1. `analyze_trade_journal` — profile your behavior (holding period, win rate, disposition effect, chasing, overtrading, anchoring).
|
||||
2. `extract_shadow_strategy` — distill 3-5 if-then rules that describe your profitable roundtrips.
|
||||
3. `run_shadow_backtest` — backtest those rules across A/HK/US/crypto and compute delta-PnL vs your realized trades.
|
||||
4. `render_shadow_report` — produce an HTML/PDF report (8 sections + charts) with today's matching signals.
|
||||
5. `scan_shadow_signals` — list today's symbols that match your shadow's entry cadence (research only).
|
||||
|
||||
### Backtesting
|
||||
Create and run quantitative strategies across 6 engines (ChinaA, GlobalEquity, Crypto, ChinaFutures, GlobalFutures, Forex + options) with 5 data sources:
|
||||
Create and run quantitative strategies across 7 engines (ChinaA, GlobalEquity, Crypto, ChinaFutures, GlobalFutures, Forex + options) with 6 data sources:
|
||||
- **HK/US equities** via yfinance (free, no API key)
|
||||
- **Cryptocurrency** via OKX or CCXT/100+ exchanges (free, no API key)
|
||||
- **China A-shares** via Tushare (token) or AKShare (free fallback)
|
||||
- **Futures, forex, macro** via AKShare (free, no API key)
|
||||
- **HK & A-share equities** via Futu (broker login required, optional)
|
||||
|
||||
Example workflow:
|
||||
1. Use `list_skills()` to discover strategy patterns
|
||||
@@ -89,34 +99,40 @@ Example workflow:
|
||||
|
||||
Use `list_swarm_presets()` to see all teams, then `run_swarm()` to execute.
|
||||
|
||||
### Finance Skills (68)
|
||||
### Finance Skills (72)
|
||||
Comprehensive knowledge base covering:
|
||||
- Technical analysis (candlestick, Elliott wave, Ichimoku, SMC)
|
||||
- Quantitative methods (factor research, ML strategy, pair trading)
|
||||
- Technical analysis (candlestick, Elliott wave, Ichimoku, SMC, harmonic, chanlun)
|
||||
- Quantitative methods (factor research, ML strategy, pair trading, multi-factor)
|
||||
- Risk management (VaR/CVaR, stress testing, hedging)
|
||||
- Options (Black-Scholes, Greeks, multi-leg strategies)
|
||||
- Options (Black-Scholes, Greeks, multi-leg strategies, payoff diagrams)
|
||||
- HK/US equities (SEC filings, earnings revisions, ETF flows, ADR/H-share arbitrage)
|
||||
- Crypto trading desk (funding rates, liquidation heatmaps, stablecoin flows, token unlocks, DeFi yields)
|
||||
- Behavioral finance, trade journal diagnostics, shadow account
|
||||
- Macro analysis, credit research, sector rotation, and more
|
||||
|
||||
Use `load_skill(name)` to access full methodology docs with code templates.
|
||||
|
||||
## Available MCP Tools (17)
|
||||
## Available MCP Tools (22)
|
||||
|
||||
| Tool | Description | API Key |
|
||||
|------|-------------|---------|
|
||||
| `list_skills` | List all 68 finance skills | None |
|
||||
| `list_skills` | List all 72 finance skills | None |
|
||||
| `load_skill` | Load full skill documentation | None |
|
||||
| `backtest` | Run vectorized backtest engine | None* |
|
||||
| `factor_analysis` | IC/IR analysis + layered backtest | None* |
|
||||
| `analyze_options` | Black-Scholes price + Greeks | None |
|
||||
| `pattern_recognition` | Detect chart patterns (H&S, double top, etc.) | None |
|
||||
| `get_market_data` | Fetch OHLCV data across 5 sources (auto-detect + fallback) | None* |
|
||||
| `get_market_data` | Fetch OHLCV data across 6 sources (auto-detect + fallback) | None* |
|
||||
| `web_search` | Search the web via DuckDuckGo | None |
|
||||
| `read_url` | Fetch web page as Markdown | None |
|
||||
| `read_document` | Extract text from PDF (with OCR) | None |
|
||||
| `read_document` | Extract text from PDF/DOCX/XLSX/PPTX/images | None |
|
||||
| `write_file` | Write files (config, strategy code) | None |
|
||||
| `read_file` | Read file contents | None |
|
||||
| `analyze_trade_journal` | Parse broker CSV → profile + behavior diagnostics | None |
|
||||
| `extract_shadow_strategy` | Distill 3-5 if-then rules from profitable roundtrips | None |
|
||||
| `run_shadow_backtest` | Multi-market backtest + delta-PnL attribution | None* |
|
||||
| `render_shadow_report` | HTML/PDF shadow report (8 sections + charts) | None |
|
||||
| `scan_shadow_signals` | Today's symbols matching the shadow's cadence | None |
|
||||
| `list_swarm_presets` | List multi-agent team presets | None |
|
||||
| `run_swarm` | Execute a multi-agent research team | LLM key |
|
||||
| `get_swarm_status` | Poll swarm run status without blocking | None |
|
||||
@@ -131,13 +147,16 @@ Use `load_skill(name)` to access full methodology docs with code templates.
|
||||
pip install vibe-trading-ai
|
||||
```
|
||||
|
||||
That's it — no API keys needed for HK/US/crypto markets. Start using `backtest`, `get_market_data`, `analyze_options`, `web_search`, and all 68 skills immediately.
|
||||
That's it — no API keys needed for HK/US/crypto markets. Start using `backtest`, `get_market_data`, `analyze_options`, `analyze_trade_journal`, `extract_shadow_strategy`, `web_search`, and all 72 skills immediately.
|
||||
|
||||
## Examples
|
||||
|
||||
**Backtest a MACD strategy on Apple:**
|
||||
> Backtest AAPL with MACD crossover strategy (fast=12, slow=26, signal=9) for 2024
|
||||
|
||||
**Analyze my trade journal and build a Shadow Account:**
|
||||
> Call analyze_trade_journal on ~/Downloads/tonghuashun.csv, then extract_shadow_strategy with min_support=3, then run_shadow_backtest for the last year, then render_shadow_report.
|
||||
|
||||
**Run an investment committee review:**
|
||||
> Use run_swarm with investment_committee preset to evaluate NVDA. Variables: target=NVDA.US, market=US
|
||||
|
||||
|
||||
+81
-13
@@ -18,7 +18,7 @@ from pathlib import Path
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
from fastapi import BackgroundTasks, Depends, FastAPI, HTTPException, Query, Request, Security, UploadFile, status
|
||||
from fastapi.responses import StreamingResponse
|
||||
from fastapi.responses import FileResponse, StreamingResponse
|
||||
from fastapi.security import HTTPAuthorizationCredentials, HTTPBearer
|
||||
from pydantic import BaseModel, Field
|
||||
from fastapi.middleware.cors import CORSMiddleware
|
||||
@@ -38,6 +38,7 @@ SESSIONS_DIR = Path(__file__).resolve().parent / "sessions"
|
||||
UPLOADS_DIR = Path(__file__).resolve().parent / "uploads"
|
||||
|
||||
MAX_UPLOAD_SIZE = 50 * 1024 * 1024 # 50 MB
|
||||
_UPLOAD_CHUNK_SIZE = 1024 * 1024 # 1 MB
|
||||
|
||||
# Rich console for colored logs
|
||||
console = Console()
|
||||
@@ -501,13 +502,15 @@ async def list_runs(limit: int = 20):
|
||||
try:
|
||||
req_data = json.loads(req_file.read_text(encoding="utf-8"))
|
||||
prompt = req_data.get("prompt")
|
||||
except: pass
|
||||
except:
|
||||
pass
|
||||
|
||||
if not prompt and planner_file.exists():
|
||||
try:
|
||||
planner_data = json.loads(planner_file.read_text(encoding="utf-8"))
|
||||
prompt = planner_data.get("user_goal") or planner_data.get("goal")
|
||||
except: pass
|
||||
except:
|
||||
pass
|
||||
|
||||
if not prompt:
|
||||
prompt_file = d / "user_prompt.txt"
|
||||
@@ -814,24 +817,90 @@ async def session_events(
|
||||
# File Upload
|
||||
# ============================================================================
|
||||
|
||||
_BLOCKED_UPLOAD_EXT = {
|
||||
# binaries / executables we should never accept
|
||||
".exe", ".msi", ".bat", ".cmd", ".com", ".scr", ".app", ".dmg",
|
||||
".so", ".dll", ".dylib",
|
||||
# archives — don't auto-extract; user can unpack locally
|
||||
".zip", ".rar", ".7z", ".tar", ".gz", ".tgz", ".bz2", ".xz",
|
||||
}
|
||||
|
||||
|
||||
_SHADOW_ID_RE = __import__("re").compile(r"^shadow_[0-9a-f]{8}$")
|
||||
|
||||
|
||||
@app.get("/shadow-reports/{shadow_id}")
|
||||
async def get_shadow_report(shadow_id: str, format: str = "html"):
|
||||
"""Serve a rendered Shadow Account report (HTML by default, PDF if available).
|
||||
|
||||
Reports live under ``~/.vibe-trading/shadow_reports/<shadow_id>.{html,pdf}``.
|
||||
"""
|
||||
if not _SHADOW_ID_RE.match(shadow_id):
|
||||
raise HTTPException(status_code=400, detail="invalid shadow_id")
|
||||
if format not in ("html", "pdf"):
|
||||
raise HTTPException(status_code=400, detail="format must be html or pdf")
|
||||
|
||||
reports_dir = Path.home() / ".vibe-trading" / "shadow_reports"
|
||||
path = reports_dir / f"{shadow_id}.{format}"
|
||||
if not path.exists():
|
||||
raise HTTPException(status_code=404, detail=f"Shadow report not found: {shadow_id}.{format}")
|
||||
|
||||
media_type = "text/html; charset=utf-8" if format == "html" else "application/pdf"
|
||||
# Inline so browsers render HTML/PDF directly instead of forcing download.
|
||||
return FileResponse(
|
||||
path,
|
||||
media_type=media_type,
|
||||
headers={"Content-Disposition": f'inline; filename="{shadow_id}.{format}"'},
|
||||
)
|
||||
|
||||
|
||||
@app.post("/upload", dependencies=[Depends(require_auth)])
|
||||
async def upload_file(file: UploadFile):
|
||||
"""Upload a PDF; stored under uploads/ with a UUID name (max 50MB)."""
|
||||
if not file.filename or not file.filename.lower().endswith(".pdf"):
|
||||
raise HTTPException(status_code=400, detail="Only PDF files are allowed")
|
||||
"""Upload any document or data file (max 50MB).
|
||||
|
||||
content = await file.read()
|
||||
if len(content) > MAX_UPLOAD_SIZE:
|
||||
Accepts most common formats: PDF, Word, Excel, PowerPoint, images,
|
||||
CSV/TSV, plain text, JSON/YAML/TOML, source code. Executables and
|
||||
archives are rejected — unpack locally before uploading.
|
||||
"""
|
||||
if not file.filename:
|
||||
raise HTTPException(status_code=400, detail="Missing filename")
|
||||
ext = Path(file.filename).suffix.lower()
|
||||
if ext in _BLOCKED_UPLOAD_EXT:
|
||||
raise HTTPException(
|
||||
status_code=413,
|
||||
detail=f"File too large (limit {MAX_UPLOAD_SIZE // (1024 * 1024)} MB)",
|
||||
status_code=400,
|
||||
detail=f"File type {ext} is not allowed (executables/archives blocked).",
|
||||
)
|
||||
|
||||
UPLOADS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
safe_name = f"{uuid.uuid4().hex}.pdf"
|
||||
safe_name = f"{uuid.uuid4().hex}{ext}"
|
||||
dest = UPLOADS_DIR / safe_name
|
||||
dest.write_bytes(content)
|
||||
total_size = 0
|
||||
|
||||
try:
|
||||
with dest.open("wb") as handle:
|
||||
while True:
|
||||
chunk = await file.read(_UPLOAD_CHUNK_SIZE)
|
||||
if not chunk:
|
||||
break
|
||||
total_size += len(chunk)
|
||||
if total_size > MAX_UPLOAD_SIZE:
|
||||
handle.close()
|
||||
if dest.exists():
|
||||
dest.unlink()
|
||||
raise HTTPException(
|
||||
status_code=413,
|
||||
detail=f"File too large (limit {MAX_UPLOAD_SIZE // (1024 * 1024)} MB)",
|
||||
)
|
||||
handle.write(chunk)
|
||||
except HTTPException:
|
||||
raise
|
||||
except OSError as exc:
|
||||
if dest.exists():
|
||||
dest.unlink()
|
||||
raise HTTPException(status_code=500, detail=f"Failed to store upload: {exc}") from exc
|
||||
finally:
|
||||
await file.close()
|
||||
|
||||
return {
|
||||
"status": "ok",
|
||||
@@ -1025,4 +1094,3 @@ def serve_main(argv: list[str] | None = None) -> int:
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(serve_main())
|
||||
|
||||
@@ -0,0 +1,152 @@
|
||||
"""Benchmark ticker resolution and fetch for backtest comparison.
|
||||
|
||||
Provides a lightweight, zero-dependency way to fetch benchmark reference
|
||||
data given a set of strategy codes and a data source.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.yfinance_loader import DataLoader as YfinanceLoader
|
||||
|
||||
|
||||
# -------------------------------------------------------------------
|
||||
# Benchmark map: market type → default ticker
|
||||
# -------------------------------------------------------------------
|
||||
|
||||
MARKET_BENCHMARKS: dict[str, Optional[str]] = {
|
||||
"us_equity": "SPY",
|
||||
"hk_equity": "HK.03100", # Hang Seng China Enterprises ETF
|
||||
"a_share": "000300.SH", # CSI 300 (China A-share core index)
|
||||
"crypto": "BTC-USDT",
|
||||
"futures": "ES.CME", # E-mini S&P 500 futures
|
||||
"forex": None, # no universal benchmark
|
||||
}
|
||||
|
||||
|
||||
@dataclass
|
||||
class BenchmarkResult:
|
||||
ticker: str
|
||||
ret_series: pd.Series # per-bar returns, index = timestamps
|
||||
total_ret: float # total return over the period
|
||||
|
||||
|
||||
def resolve_benchmark(
|
||||
strategy_codes: list[str],
|
||||
source: str,
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
interval: str = "1D",
|
||||
explicit: Optional[str] = None,
|
||||
) -> Optional[BenchmarkResult]:
|
||||
"""Resolve the appropriate benchmark ticker and fetch its return series.
|
||||
|
||||
Args:
|
||||
strategy_codes: Instruments being backtested (used for market inference).
|
||||
source: Data source name (tushare / yfinance / okx / akshare / ccxt).
|
||||
start_date: Backtest start date.
|
||||
end_date: Backtest end date.
|
||||
interval: Bar interval (1m / 5m / 15m / 30m / 1H / 4H / 1D).
|
||||
explicit: Override ticker (e.g. "SPY" passed via config).
|
||||
|
||||
Returns:
|
||||
BenchmarkResult with return series and total return, or None if no
|
||||
benchmark applies (forex, or fetch failure).
|
||||
"""
|
||||
ticker = _resolve_ticker(strategy_codes, source, explicit)
|
||||
if ticker is None:
|
||||
return None
|
||||
|
||||
try:
|
||||
bench_df = _fetch_benchmark(ticker, start_date, end_date, interval)
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
if bench_df.empty or "close" not in bench_df.columns:
|
||||
return None
|
||||
|
||||
close = bench_df["close"].dropna()
|
||||
if len(close) < 2:
|
||||
return None
|
||||
|
||||
ret_series = close.pct_change().fillna(0.0)
|
||||
total_ret = float((1 + ret_series).prod() - 1)
|
||||
|
||||
return BenchmarkResult(ticker=ticker, ret_series=ret_series, total_ret=total_ret)
|
||||
|
||||
|
||||
# -------------------------------------------------------------------
|
||||
# Internal helpers
|
||||
# -------------------------------------------------------------------
|
||||
|
||||
def _resolve_ticker(
|
||||
codes: list[str],
|
||||
source: str,
|
||||
explicit: Optional[str],
|
||||
) -> Optional[str]:
|
||||
"""Pick the benchmark ticker to use."""
|
||||
|
||||
if explicit:
|
||||
return explicit
|
||||
|
||||
# Infer market from source + first code pattern
|
||||
market = _infer_market(codes, source)
|
||||
ticker = MARKET_BENCHMARKS.get(market)
|
||||
|
||||
# yfinance is the universal fallback for benchmark fetch
|
||||
# but it only works for us_equity / hk_equity market types
|
||||
if ticker and market not in {"us_equity", "hk_equity"}:
|
||||
# Only use benchmark if we can actually fetch it
|
||||
pass
|
||||
|
||||
return ticker
|
||||
|
||||
|
||||
def _infer_market(codes: list[str], source: str) -> str:
|
||||
"""Rough market inference from symbol patterns and source."""
|
||||
if not codes:
|
||||
return "us_equity"
|
||||
|
||||
first = codes[0].upper()
|
||||
|
||||
if source in ("okx", "ccxt") or "-" in first or "/" in first:
|
||||
return "crypto"
|
||||
if first.endswith(".US"):
|
||||
return "us_equity"
|
||||
if first.endswith(".HK"):
|
||||
return "hk_equity"
|
||||
if source in ("tushare", "akshare"):
|
||||
if first.isdigit() and len(first) == 6:
|
||||
return "a_share"
|
||||
if first.startswith(("IF", "IC", "IH", "IM", "T", "TF")):
|
||||
return "futures"
|
||||
return "a_share"
|
||||
|
||||
return "us_equity"
|
||||
|
||||
|
||||
def _fetch_benchmark(
|
||||
ticker: str,
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
interval: str,
|
||||
) -> pd.DataFrame:
|
||||
"""Fetch benchmark OHLCV data via yfinance (single symbol, no auth)."""
|
||||
loader = YfinanceLoader()
|
||||
result = loader.fetch([ticker], start_date, end_date, interval=interval)
|
||||
|
||||
if isinstance(result, dict):
|
||||
df = result.get(ticker)
|
||||
elif isinstance(result, pd.DataFrame):
|
||||
df = result
|
||||
else:
|
||||
return pd.DataFrame()
|
||||
|
||||
if df is None or (isinstance(df, pd.DataFrame) and df.empty):
|
||||
return pd.DataFrame()
|
||||
|
||||
return df
|
||||
@@ -13,12 +13,17 @@ Wave 2:
|
||||
- GlobalFuturesEngine: International futures (CME/ICE/Eurex)
|
||||
- ForexEngine: FX spot/CFD (spread, swap, high leverage)
|
||||
|
||||
Wave 3:
|
||||
- CompositeEngine: Cross-market engine with shared capital pool
|
||||
- _market_hooks: Extracted on_bar logic (funding, liquidation, swap)
|
||||
|
||||
Inheritance:
|
||||
BaseEngine
|
||||
├── ChinaAEngine
|
||||
├── GlobalEquityEngine
|
||||
├── CryptoEngine
|
||||
├── ForexEngine
|
||||
├── CompositeEngine (delegates to sub-engines as rule providers)
|
||||
└── FuturesBaseEngine
|
||||
├── ChinaFuturesEngine
|
||||
└── GlobalFuturesEngine
|
||||
|
||||
@@ -0,0 +1,180 @@
|
||||
"""Extracted per-bar market hooks as pure functions.
|
||||
|
||||
Both the original engines (CryptoEngine, ForexEngine) and CompositeEngine
|
||||
call these same functions. Zero duplication — one source of truth.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Dict
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.models import Position
|
||||
|
||||
# ── Crypto: OKX tiered maintenance margin table (simplified) ──
|
||||
|
||||
_TIER_TABLE = [
|
||||
(100_000, 0.004),
|
||||
(500_000, 0.006),
|
||||
(1_000_000, 0.01),
|
||||
(5_000_000, 0.02),
|
||||
(10_000_000, 0.05),
|
||||
(float("inf"), 0.10),
|
||||
]
|
||||
|
||||
FUNDING_HOURS = {0, 8, 16}
|
||||
|
||||
|
||||
def _maintenance_rate(notional_usd: float) -> float:
|
||||
"""Look up tiered maintenance margin rate."""
|
||||
for tier_max, rate in _TIER_TABLE:
|
||||
if notional_usd <= tier_max:
|
||||
return rate
|
||||
return _TIER_TABLE[-1][1]
|
||||
|
||||
|
||||
def calc_crypto_funding_fee(
|
||||
symbol: str,
|
||||
bar: pd.Series,
|
||||
timestamp: pd.Timestamp,
|
||||
positions: Dict[str, Position],
|
||||
funding_rate: float,
|
||||
applied_set: set,
|
||||
daily_done_set: set,
|
||||
) -> float:
|
||||
"""Calculate crypto funding fee for one symbol.
|
||||
|
||||
Args:
|
||||
symbol: Instrument code.
|
||||
bar: Current bar data.
|
||||
timestamp: Bar timestamp.
|
||||
positions: Shared positions dict.
|
||||
funding_rate: Fixed rate per settlement.
|
||||
applied_set: (symbol, date, hour) dedup set — mutated.
|
||||
daily_done_set: (symbol, date) dedup set — mutated.
|
||||
|
||||
Returns:
|
||||
Fee amount (positive = longs pay, negative = longs receive).
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return 0.0
|
||||
|
||||
current_date = timestamp.date()
|
||||
hour = timestamp.hour if hasattr(timestamp, "hour") else 0
|
||||
|
||||
if hour in FUNDING_HOURS:
|
||||
key = (symbol, current_date, hour)
|
||||
if key in applied_set:
|
||||
return 0.0
|
||||
applied_set.add(key)
|
||||
else:
|
||||
day_key = (symbol, current_date)
|
||||
if day_key in daily_done_set:
|
||||
return 0.0
|
||||
daily_done_set.add(day_key)
|
||||
|
||||
pos = positions.get(symbol)
|
||||
if pos is None:
|
||||
return 0.0
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
notional = pos.size * mark_price
|
||||
return notional * funding_rate * pos.direction
|
||||
|
||||
|
||||
def check_crypto_liquidation(
|
||||
symbol: str,
|
||||
bar: pd.Series,
|
||||
positions: Dict[str, Position],
|
||||
) -> bool:
|
||||
"""Check if a crypto position should be liquidated.
|
||||
|
||||
Args:
|
||||
symbol: Instrument code.
|
||||
bar: Current bar data.
|
||||
positions: Shared positions dict.
|
||||
|
||||
Returns:
|
||||
True if liquidation should be triggered.
|
||||
Does NOT execute the liquidation -- caller handles that.
|
||||
"""
|
||||
pos = positions.get(symbol)
|
||||
if pos is None or pos.leverage <= 1.0:
|
||||
return False
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
margin = pos.size * pos.entry_price / pos.leverage
|
||||
unrealized = pos.direction * pos.size * (mark_price - pos.entry_price)
|
||||
|
||||
notional = pos.size * mark_price
|
||||
maint_rate = _maintenance_rate(notional)
|
||||
maint_margin = notional * maint_rate
|
||||
|
||||
return (margin + unrealized) <= maint_margin
|
||||
|
||||
|
||||
# ── Forex: swap tables ──
|
||||
|
||||
_SWAP_LONG: dict[str, float] = {
|
||||
"EUR/USD": -6.5, "GBP/USD": -3.0, "USD/JPY": 8.0, "USD/CHF": 4.0,
|
||||
"AUD/USD": -2.0, "USD/CAD": 2.0, "NZD/USD": -1.5,
|
||||
}
|
||||
_SWAP_SHORT: dict[str, float] = {
|
||||
"EUR/USD": 3.5, "GBP/USD": -1.0, "USD/JPY": -12.0, "USD/CHF": -8.0,
|
||||
"AUD/USD": -1.0, "USD/CAD": -5.0, "NZD/USD": -2.0,
|
||||
}
|
||||
|
||||
|
||||
def _normalize_symbol(symbol: str) -> str:
|
||||
"""Normalize forex symbol to 'XXX/YYY' format."""
|
||||
s = symbol.replace(".FX", "").replace(".", "").strip()
|
||||
if "/" in s:
|
||||
return s.upper()
|
||||
if len(s) == 6:
|
||||
return f"{s[:3]}/{s[3:]}".upper()
|
||||
return s.upper()
|
||||
|
||||
|
||||
def calc_forex_swap(
|
||||
symbol: str,
|
||||
timestamp: pd.Timestamp,
|
||||
positions: Dict[str, Position],
|
||||
lot_size: float,
|
||||
last_swap_dates: dict,
|
||||
) -> float:
|
||||
"""Calculate forex swap for one symbol.
|
||||
|
||||
Args:
|
||||
symbol: Forex pair.
|
||||
timestamp: Bar timestamp.
|
||||
positions: Shared positions dict.
|
||||
lot_size: Standard lot size (e.g. 100_000).
|
||||
last_swap_dates: Per-symbol date tracking dict -- mutated.
|
||||
|
||||
Returns:
|
||||
Swap amount (positive = credit, negative = debit).
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return 0.0
|
||||
|
||||
current_date = timestamp.date()
|
||||
if last_swap_dates.get(symbol) == current_date:
|
||||
return 0.0
|
||||
last_swap_dates[symbol] = current_date
|
||||
|
||||
pos = positions.get(symbol)
|
||||
if pos is None:
|
||||
return 0.0
|
||||
|
||||
pair = _normalize_symbol(symbol)
|
||||
lots = pos.size / lot_size
|
||||
|
||||
if pos.direction == 1:
|
||||
swap_per_lot = _SWAP_LONG.get(pair, -1.0)
|
||||
else:
|
||||
swap_per_lot = _SWAP_SHORT.get(pair, -1.0)
|
||||
|
||||
# Wednesday = triple swap (covers Sat+Sun)
|
||||
multiplier = 3.0 if timestamp.weekday() == 2 else 1.0
|
||||
return lots * swap_per_lot * multiplier
|
||||
@@ -10,6 +10,7 @@ from __future__ import annotations
|
||||
|
||||
import importlib
|
||||
import json
|
||||
import logging
|
||||
import sys
|
||||
from abc import ABC, abstractmethod
|
||||
from pathlib import Path
|
||||
@@ -18,6 +19,8 @@ from typing import Any, Callable, Dict, List, Optional
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
from backtest.metrics import (
|
||||
by_exit_reason_stats,
|
||||
by_symbol_stats,
|
||||
@@ -26,6 +29,23 @@ from backtest.metrics import (
|
||||
from backtest.models import EquitySnapshot, Position, TradeRecord
|
||||
|
||||
|
||||
# ─── Market detection (lightweight, for signal alignment only) ───
|
||||
|
||||
import re as _re
|
||||
|
||||
_CRYPTO_RE = _re.compile(r"^[A-Z]+-USDT$|^[A-Z]+/USDT$", _re.I)
|
||||
_FOREX_RE = _re.compile(r"^[A-Z]{3}/[A-Z]{3}$|^[A-Z]{6}\.FX$")
|
||||
|
||||
|
||||
def _detect_market_for_align(code: str) -> str:
|
||||
"""Lightweight market detection for ffill_limit calculation."""
|
||||
if _CRYPTO_RE.match(code):
|
||||
return "crypto"
|
||||
if _FOREX_RE.match(code):
|
||||
return "forex"
|
||||
return "equity"
|
||||
|
||||
|
||||
# ─── Signal alignment (reused from daily_portfolio logic) ───
|
||||
|
||||
|
||||
@@ -57,12 +77,28 @@ def _align(
|
||||
close = pd.DataFrame(index=dates, columns=codes, dtype=float)
|
||||
for c in codes:
|
||||
close[c] = data_map[c]["close"].reindex(dates)
|
||||
close = close.ffill().bfill()
|
||||
|
||||
# ffill with limit to avoid masking long suspensions (e.g. 3-week halt)
|
||||
# Cross-market needs larger limit (Chinese New Year can be 9-10 bars)
|
||||
ffill_limit = 10 if len({_detect_market_for_align(c) for c in codes}) > 1 else 5
|
||||
close = close.ffill(limit=ffill_limit)
|
||||
|
||||
# Drop symbols that are entirely NaN (no data overlap with date range)
|
||||
all_nan_cols = [c for c in codes if close[c].isna().all()]
|
||||
if all_nan_cols:
|
||||
logger.warning("Symbols dropped (no usable price data): %s", all_nan_cols)
|
||||
codes = [c for c in codes if c not in all_nan_cols]
|
||||
if not codes:
|
||||
raise ValueError(f"All symbols have no data in the requested date range")
|
||||
close = close[codes]
|
||||
|
||||
pos = pd.DataFrame(0.0, index=dates, columns=codes)
|
||||
for c in codes:
|
||||
raw = signal_map[c].reindex(dates).fillna(0.0).clip(-1.0, 1.0)
|
||||
pos[c] = raw.shift(1).fillna(0.0)
|
||||
# Shift on each symbol's OWN trading calendar, then ffill to unified
|
||||
own_dates = data_map[c].index
|
||||
raw = signal_map[c].reindex(own_dates).fillna(0.0).clip(-1.0, 1.0)
|
||||
shifted = raw.shift(1).fillna(0.0)
|
||||
pos[c] = shifted.reindex(dates).ffill(limit=ffill_limit).fillna(0.0)
|
||||
|
||||
ret = close.pct_change().fillna(0.0)
|
||||
|
||||
@@ -255,6 +291,9 @@ class BaseEngine(ABC):
|
||||
data_map, signal_map, valid_codes, optimizer=opt_fn,
|
||||
)
|
||||
|
||||
# Sync codes after _align may have dropped all-NaN symbols
|
||||
valid_codes = [c for c in valid_codes if c in target_pos.columns]
|
||||
|
||||
# 4. Bar-by-bar execution
|
||||
self._execute_bars(dates, data_map, close_df, target_pos, valid_codes)
|
||||
|
||||
@@ -264,6 +303,26 @@ class BaseEngine(ABC):
|
||||
index=[s.timestamp for s in self.equity_snapshots],
|
||||
)
|
||||
bench_ret = ret_df.mean(axis=1) if ret_df.shape[1] > 0 else pd.Series(0.0, index=dates)
|
||||
|
||||
# ── External benchmark fetch ──────────────────────────────────────────
|
||||
bench_ticker = config.get("benchmark")
|
||||
if bench_ticker and bench_ticker != "auto":
|
||||
from backtest.benchmark import resolve_benchmark
|
||||
bench_result = resolve_benchmark(
|
||||
strategy_codes=codes,
|
||||
source=config.get("source", "yfinance"),
|
||||
start_date=config.get("start_date", ""),
|
||||
end_date=config.get("end_date", ""),
|
||||
interval=interval,
|
||||
explicit=bench_ticker,
|
||||
)
|
||||
if bench_result is not None:
|
||||
bench_ret = bench_result.ret_series.reindex(dates).fillna(0.0)
|
||||
bench_equity = self.initial_capital * (1 + bench_ret).cumprod()
|
||||
m["benchmark_ticker"] = bench_result.ticker
|
||||
m["benchmark_return"] = bench_result.total_ret
|
||||
# ── External benchmark fetch ──────────────────────────────────────────
|
||||
|
||||
bench_equity = self.initial_capital * (1 + bench_ret).cumprod()
|
||||
|
||||
# 6. Metrics
|
||||
@@ -314,8 +373,11 @@ class BaseEngine(ABC):
|
||||
# b. Rebalance each symbol to target weight
|
||||
equity = self._calc_equity(close_df, ts)
|
||||
for c in codes:
|
||||
target_w = float(target_pos.at[ts, c]) if ts in target_pos.index else 0.0
|
||||
self._rebalance(c, target_w, data_map.get(c), ts, equity)
|
||||
try:
|
||||
target_w = float(target_pos.at[ts, c]) if ts in target_pos.index else 0.0
|
||||
self._rebalance(c, target_w, data_map.get(c), ts, equity)
|
||||
except Exception as exc:
|
||||
logger.warning("Rebalance failed for %s at %s: %s", c, ts, exc)
|
||||
|
||||
# c. Record equity snapshot
|
||||
snap_equity = self._calc_equity(close_df, ts)
|
||||
|
||||
@@ -0,0 +1,217 @@
|
||||
"""Composite cross-market backtest engine.
|
||||
|
||||
Manages a shared capital pool across multiple market engines.
|
||||
Sub-engines are used as stateless "rule books" for market-specific
|
||||
calculations (commission, slippage, lot rounding, etc.).
|
||||
All state (capital, positions, trades) lives in CompositeEngine.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from typing import Dict, List
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.engines.base import BaseEngine
|
||||
from backtest.engines._market_hooks import (
|
||||
calc_crypto_funding_fee,
|
||||
check_crypto_liquidation,
|
||||
calc_forex_swap,
|
||||
)
|
||||
|
||||
|
||||
# ── Market detection (same patterns as runner.py) ──
|
||||
|
||||
_MARKET_PATTERNS = [
|
||||
(re.compile(r"^\d{6}\.(SZ|SH|BJ)$", re.I), "a_share"),
|
||||
(re.compile(r"^(51|15|56)\d{4}\.(SZ|SH)$", re.I), "a_share"),
|
||||
(re.compile(r"^[A-Z]+\.US$", re.I), "us_equity"),
|
||||
(re.compile(r"^\d{3,5}\.HK$", re.I), "hk_equity"),
|
||||
(re.compile(r"^[A-Z]+-USDT$", re.I), "crypto"),
|
||||
(re.compile(r"^[A-Z]+/USDT$", re.I), "crypto"),
|
||||
(re.compile(r"^[A-Za-z]{1,2}\d{3,4}\.(ZCE|DCE|SHFE|INE|CFFEX|GFEX)$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{2,4}[FGHJKMNQUVXZ]\d{1,2}$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{2,4}\d{4}$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{2,4}\.(CME|CBOT|NYMEX|COMEX|ICE|EUREX)$", re.I), "futures"),
|
||||
(re.compile(r"^[A-Z]{3}/[A-Z]{3}$"), "forex"),
|
||||
(re.compile(r"^[A-Z]{6}\.FX$"), "forex"),
|
||||
]
|
||||
|
||||
_CHINA_EXCHANGES = {"CFFEX", "SHFE", "DCE", "ZCE", "INE", "GFEX"}
|
||||
|
||||
|
||||
def _detect_market(code: str) -> str:
|
||||
"""Infer market type from symbol format."""
|
||||
for pattern, market in _MARKET_PATTERNS:
|
||||
if pattern.match(code):
|
||||
return market
|
||||
return "a_share"
|
||||
|
||||
|
||||
def _is_china_futures(code: str) -> bool:
|
||||
"""Check if futures code belongs to a Chinese exchange."""
|
||||
parts = code.upper().split(".")
|
||||
return len(parts) == 2 and parts[1] in _CHINA_EXCHANGES
|
||||
|
||||
|
||||
def _build_rule_engines(config: dict, codes: List[str]) -> Dict[str, BaseEngine]:
|
||||
"""Instantiate one sub-engine per market type detected in codes."""
|
||||
markets = {_detect_market(c) for c in codes}
|
||||
engines: Dict[str, BaseEngine] = {}
|
||||
|
||||
for market in markets:
|
||||
if market == "a_share":
|
||||
from backtest.engines.china_a import ChinaAEngine
|
||||
engines["a_share"] = ChinaAEngine(config)
|
||||
elif market == "us_equity":
|
||||
from backtest.engines.global_equity import GlobalEquityEngine
|
||||
engines["us_equity"] = GlobalEquityEngine(config, market="us")
|
||||
elif market == "hk_equity":
|
||||
from backtest.engines.global_equity import GlobalEquityEngine
|
||||
engines["hk_equity"] = GlobalEquityEngine(config, market="hk")
|
||||
elif market == "crypto":
|
||||
from backtest.engines.crypto import CryptoEngine
|
||||
engines["crypto"] = CryptoEngine(config)
|
||||
elif market == "forex":
|
||||
from backtest.engines.forex import ForexEngine
|
||||
engines["forex"] = ForexEngine(config)
|
||||
elif market == "futures":
|
||||
china = any(
|
||||
_is_china_futures(c) for c in codes if _detect_market(c) == "futures"
|
||||
)
|
||||
if china:
|
||||
from backtest.engines.china_futures import ChinaFuturesEngine
|
||||
engines["futures"] = ChinaFuturesEngine(config)
|
||||
else:
|
||||
from backtest.engines.global_futures import GlobalFuturesEngine
|
||||
engines["futures"] = GlobalFuturesEngine(config)
|
||||
|
||||
return engines
|
||||
|
||||
|
||||
class CompositeEngine(BaseEngine):
|
||||
"""Cross-market engine with shared capital pool.
|
||||
|
||||
Sub-engines are stateless rule providers. All positions, capital,
|
||||
and trades live here (inherited from BaseEngine).
|
||||
|
||||
Args:
|
||||
config: Backtest configuration dict.
|
||||
codes: List of instrument codes spanning multiple markets.
|
||||
"""
|
||||
|
||||
def __init__(self, config: dict, codes: List[str]):
|
||||
super().__init__(config)
|
||||
|
||||
# Build symbol -> market mapping
|
||||
self._symbol_market: Dict[str, str] = {c: _detect_market(c) for c in codes}
|
||||
|
||||
# Build sub-engines (one per market type)
|
||||
self._rule_engines = _build_rule_engines(config, codes)
|
||||
|
||||
# Crypto dedup state (owned by CompositeEngine, not sub-engine)
|
||||
self._funding_applied: set = set()
|
||||
self._funding_daily_done: set = set()
|
||||
|
||||
# Forex dedup state
|
||||
self._last_swap_dates: dict = {}
|
||||
|
||||
def _rule_for(self, symbol: str) -> BaseEngine:
|
||||
"""Get the sub-engine that provides rules for this symbol."""
|
||||
market = self._symbol_market.get(symbol, "a_share")
|
||||
return self._rule_engines[market]
|
||||
|
||||
# ── Stateless method dispatch ──
|
||||
|
||||
def can_execute(self, symbol: str, direction: int, bar: pd.Series) -> bool:
|
||||
"""Market-rule check with T+1 interceptor for A-shares."""
|
||||
market = self._symbol_market.get(symbol, "a_share")
|
||||
|
||||
# T+1: intercept here because sub-engine has no access to shared positions
|
||||
if market == "a_share" and direction == 0:
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is not None:
|
||||
bar_date = None
|
||||
if hasattr(bar, "name") and hasattr(bar.name, "date"):
|
||||
bar_date = bar.name.date()
|
||||
entry_date = (
|
||||
pos.entry_time.date()
|
||||
if hasattr(pos.entry_time, "date")
|
||||
else None
|
||||
)
|
||||
if bar_date and entry_date and bar_date == entry_date:
|
||||
return False
|
||||
|
||||
# Delegate remaining checks (price limits, short-sell block, etc.)
|
||||
return self._rule_for(symbol).can_execute(symbol, direction, bar)
|
||||
|
||||
def round_size(self, raw_size: float, price: float) -> float:
|
||||
"""Delegate to active symbol's sub-engine."""
|
||||
return self._rule_for(self._active_symbol).round_size(raw_size, price)
|
||||
|
||||
def calc_commission(
|
||||
self, size: float, price: float, direction: int, is_open: bool,
|
||||
) -> float:
|
||||
"""Delegate to active symbol's sub-engine."""
|
||||
return self._rule_for(self._active_symbol).calc_commission(
|
||||
size, price, direction, is_open,
|
||||
)
|
||||
|
||||
def apply_slippage(self, price: float, direction: int) -> float:
|
||||
"""Delegate to active symbol's sub-engine."""
|
||||
sub = self._rule_for(self._active_symbol)
|
||||
# ForexEngine needs _active_symbol set on the sub-engine
|
||||
sub._active_symbol = self._active_symbol
|
||||
return sub.apply_slippage(price, direction)
|
||||
|
||||
# ── PnL / margin dispatch (route by symbol, not _active_symbol) ──
|
||||
|
||||
def _calc_pnl(
|
||||
self, symbol: str, direction: int, size: float,
|
||||
entry_price: float, exit_price: float,
|
||||
) -> float:
|
||||
return self._rule_for(symbol)._calc_pnl(
|
||||
symbol, direction, size, entry_price, exit_price,
|
||||
)
|
||||
|
||||
def _calc_margin(
|
||||
self, symbol: str, size: float, price: float, leverage: float,
|
||||
) -> float:
|
||||
return self._rule_for(symbol)._calc_margin(symbol, size, price, leverage)
|
||||
|
||||
def _calc_raw_size(
|
||||
self, symbol: str, target_notional: float, price: float,
|
||||
) -> float:
|
||||
return self._rule_for(symbol)._calc_raw_size(symbol, target_notional, price)
|
||||
|
||||
# ── Stateful hooks (implemented directly, NO delegation) ──
|
||||
|
||||
def on_bar(self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp) -> None:
|
||||
"""Per-bar hooks dispatched by market type."""
|
||||
market = self._symbol_market.get(symbol)
|
||||
|
||||
if market == "crypto":
|
||||
crypto_sub = self._rule_engines["crypto"]
|
||||
fee = calc_crypto_funding_fee(
|
||||
symbol, bar, timestamp, self.positions,
|
||||
crypto_sub.funding_rate,
|
||||
self._funding_applied, self._funding_daily_done,
|
||||
)
|
||||
self.capital -= fee
|
||||
|
||||
if check_crypto_liquidation(symbol, bar, self.positions):
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is not None:
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
liq_price = crypto_sub.apply_slippage(mark_price, -pos.direction)
|
||||
self._close_position(symbol, liq_price, timestamp, "liquidation")
|
||||
|
||||
elif market == "forex":
|
||||
forex_sub = self._rule_engines["forex"]
|
||||
if forex_sub.swap_enabled:
|
||||
swap = calc_forex_swap(
|
||||
symbol, timestamp, self.positions,
|
||||
forex_sub.lot_size, self._last_swap_dates,
|
||||
)
|
||||
self.capital += swap
|
||||
@@ -13,21 +13,10 @@ from __future__ import annotations
|
||||
import pandas as pd
|
||||
|
||||
from backtest.engines.base import BaseEngine
|
||||
|
||||
|
||||
# OKX tiered maintenance margin table (simplified)
|
||||
# (max_notional_usd, maintenance_margin_rate)
|
||||
_TIER_TABLE = [
|
||||
(100_000, 0.004),
|
||||
(500_000, 0.006),
|
||||
(1_000_000, 0.01),
|
||||
(5_000_000, 0.02),
|
||||
(10_000_000, 0.05),
|
||||
(float("inf"), 0.10),
|
||||
]
|
||||
|
||||
# Funding fee settlement hours (UTC)
|
||||
_FUNDING_HOURS = {0, 8, 16}
|
||||
from backtest.engines._market_hooks import (
|
||||
calc_crypto_funding_fee,
|
||||
check_crypto_liquidation,
|
||||
)
|
||||
|
||||
|
||||
class CryptoEngine(BaseEngine):
|
||||
@@ -70,80 +59,15 @@ class CryptoEngine(BaseEngine):
|
||||
|
||||
def on_bar(self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp) -> None:
|
||||
"""Crypto per-bar hooks: funding fee + liquidation check."""
|
||||
self._apply_funding_fee(symbol, bar, timestamp)
|
||||
self._check_liquidation(symbol, bar, timestamp)
|
||||
|
||||
# ── Funding fee (exchange-enforced, every 8h) ──
|
||||
|
||||
def _apply_funding_fee(
|
||||
self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp,
|
||||
) -> None:
|
||||
"""Deduct/credit funding fee at settlement hours.
|
||||
|
||||
Positive rate: longs pay shorts. Negative rate: shorts pay longs.
|
||||
|
||||
For intraday bars: applies at each 8h settlement (0/8/16 UTC).
|
||||
For daily bars: applies once per calendar day regardless of hour.
|
||||
Dedup is per-(symbol, date, hour) so multi-symbol portfolios work.
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return
|
||||
|
||||
current_date = timestamp.date()
|
||||
hour = timestamp.hour if hasattr(timestamp, "hour") else 0
|
||||
|
||||
if hour in _FUNDING_HOURS:
|
||||
key = (symbol, current_date, hour)
|
||||
if key in self._funding_applied:
|
||||
return
|
||||
self._funding_applied.add(key)
|
||||
else:
|
||||
# Non-settlement hour (e.g. daily bar at 12:00 UTC)
|
||||
# Apply once per day as approximation
|
||||
day_key = (symbol, current_date)
|
||||
if day_key in self._funding_daily_done:
|
||||
return
|
||||
self._funding_daily_done.add(day_key)
|
||||
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is None:
|
||||
return
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
notional = pos.size * mark_price
|
||||
fee = notional * self.funding_rate * pos.direction
|
||||
fee = calc_crypto_funding_fee(
|
||||
symbol, bar, timestamp, self.positions,
|
||||
self.funding_rate, self._funding_applied, self._funding_daily_done,
|
||||
)
|
||||
self.capital -= fee
|
||||
|
||||
# ── Liquidation (exchange-enforced) ──
|
||||
|
||||
def _check_liquidation(
|
||||
self, symbol: str, bar: pd.Series, timestamp: pd.Timestamp,
|
||||
) -> None:
|
||||
"""Force-close when maintenance margin ratio drops to / below 100%."""
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is None or pos.leverage <= 1.0:
|
||||
return # spot has no liquidation
|
||||
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
margin = pos.size * pos.entry_price / pos.leverage
|
||||
unrealized = pos.direction * pos.size * (mark_price - pos.entry_price)
|
||||
|
||||
# Maintenance margin rate (tiered)
|
||||
notional = pos.size * mark_price
|
||||
maint_rate = self._maintenance_rate(notional)
|
||||
maint_margin = notional * maint_rate
|
||||
|
||||
# Margin ratio = (margin + unrealized) / maint_margin
|
||||
equity_in_pos = margin + unrealized
|
||||
if equity_in_pos <= maint_margin:
|
||||
# Liquidation: close at mark price with taker fee
|
||||
liq_price = self.apply_slippage(mark_price, -pos.direction)
|
||||
self._close_position(symbol, liq_price, timestamp, "liquidation")
|
||||
|
||||
@staticmethod
|
||||
def _maintenance_rate(notional_usd: float) -> float:
|
||||
"""Look up tiered maintenance margin rate."""
|
||||
for tier_max, rate in _TIER_TABLE:
|
||||
if notional_usd <= tier_max:
|
||||
return rate
|
||||
return _TIER_TABLE[-1][1]
|
||||
if check_crypto_liquidation(symbol, bar, self.positions):
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is not None:
|
||||
mark_price = float(bar.get("close", pos.entry_price))
|
||||
liq_price = self.apply_slippage(mark_price, -pos.direction)
|
||||
self._close_position(symbol, liq_price, timestamp, "liquidation")
|
||||
@@ -15,6 +15,7 @@ from __future__ import annotations
|
||||
import pandas as pd
|
||||
|
||||
from backtest.engines.base import BaseEngine
|
||||
from backtest.engines._market_hooks import calc_forex_swap
|
||||
|
||||
|
||||
# ── Typical spreads in pips (1 pip = 0.0001 for most pairs, 0.01 for JPY) ──
|
||||
@@ -33,18 +34,6 @@ _SPREAD_PIPS: dict[str, float] = {
|
||||
}
|
||||
_DEFAULT_SPREAD_PIPS = 2.0
|
||||
|
||||
# ── Daily swap points (per standard lot, in account currency) ──
|
||||
# Positive = receive, negative = pay. Varies by broker/rates; simplified table.
|
||||
|
||||
_SWAP_LONG: dict[str, float] = {
|
||||
"EUR/USD": -6.5, "GBP/USD": -3.0, "USD/JPY": 8.0, "USD/CHF": 4.0,
|
||||
"AUD/USD": -2.0, "USD/CAD": 2.0, "NZD/USD": -1.5,
|
||||
}
|
||||
_SWAP_SHORT: dict[str, float] = {
|
||||
"EUR/USD": 3.5, "GBP/USD": -1.0, "USD/JPY": -12.0, "USD/CHF": -8.0,
|
||||
"AUD/USD": -1.0, "USD/CAD": -5.0, "NZD/USD": -2.0,
|
||||
}
|
||||
|
||||
# Standard lot size
|
||||
STANDARD_LOT = 100_000
|
||||
|
||||
@@ -149,41 +138,12 @@ class ForexEngine(BaseEngine):
|
||||
"""Apply daily swap/rollover at end of trading day."""
|
||||
if not self.swap_enabled:
|
||||
return
|
||||
self._apply_swap(symbol, timestamp)
|
||||
swap = calc_forex_swap(
|
||||
symbol, timestamp, self.positions,
|
||||
self.lot_size, self._last_swap_dates,
|
||||
)
|
||||
self.capital += swap
|
||||
|
||||
def get_contract_multiplier(self, symbol: str) -> float:
|
||||
"""Forex: multiplier is 1.0 (size is in currency units)."""
|
||||
return 1.0
|
||||
|
||||
# ── Swap (overnight rollover) ──
|
||||
|
||||
def _apply_swap(self, symbol: str, timestamp: pd.Timestamp) -> None:
|
||||
"""Deduct/credit swap at daily rollover (once per calendar day).
|
||||
|
||||
Triple swap on Wednesday (covers weekend).
|
||||
"""
|
||||
if not hasattr(timestamp, "date"):
|
||||
return
|
||||
|
||||
current_date = timestamp.date()
|
||||
if self._last_swap_dates.get(symbol) == current_date:
|
||||
return
|
||||
self._last_swap_dates[symbol] = current_date
|
||||
|
||||
pos = self.positions.get(symbol)
|
||||
if pos is None:
|
||||
return
|
||||
|
||||
pair = _normalize_symbol(symbol)
|
||||
lots = pos.size / self.lot_size
|
||||
|
||||
if pos.direction == 1:
|
||||
swap_per_lot = _SWAP_LONG.get(pair, -1.0)
|
||||
else:
|
||||
swap_per_lot = _SWAP_SHORT.get(pair, -1.0)
|
||||
|
||||
# Wednesday = triple swap (covers Sat+Sun)
|
||||
multiplier = 3.0 if timestamp.weekday() == 2 else 1.0
|
||||
swap = lots * swap_per_lot * multiplier
|
||||
|
||||
self.capital += swap
|
||||
@@ -11,6 +11,7 @@ from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -38,6 +39,38 @@ def _is_crypto(code: str) -> bool:
|
||||
return "-USDT" in code.upper() or "/USDT" in code.upper()
|
||||
|
||||
|
||||
# Exchange-listed ETF / LOF prefix codes:
|
||||
# SH: 50/51/52/56/58 (ETFs), SZ: 15/16 (ETFs + LOFs).
|
||||
# Issue #50 — these symbols look like A-shares (.SH / .SZ) but stock_zh_a_hist
|
||||
# can't price them; route through fund_etf_hist_sina instead.
|
||||
_ETF_PREFIXES = frozenset({"15", "16", "50", "51", "52", "56", "58"})
|
||||
|
||||
|
||||
def _is_etf_listed(code: str) -> bool:
|
||||
"""Detect exchange-listed ETF / LOF symbols (e.g. 518880.SH, 159915.SZ)."""
|
||||
upper = code.upper()
|
||||
if not upper.endswith((".SH", ".SZ")):
|
||||
return False
|
||||
digits = upper.split(".")[0]
|
||||
if len(digits) != 6 or not digits.isdigit():
|
||||
return False
|
||||
return digits[:2] in _ETF_PREFIXES
|
||||
|
||||
|
||||
def _is_forex(code: str) -> bool:
|
||||
"""Detect forex pairs by matching against AKShare's symbol_market_map.
|
||||
|
||||
Issue #54 — forex symbols (EURUSD, GBPUSD, etc.) have no exchange suffix
|
||||
and previously fell through to the A-share endpoint.
|
||||
"""
|
||||
upper = code.upper().removesuffix(".FX")
|
||||
try:
|
||||
from akshare.forex.cons import symbol_market_map
|
||||
except Exception:
|
||||
return False
|
||||
return upper in symbol_market_map
|
||||
|
||||
|
||||
@register
|
||||
class DataLoader:
|
||||
"""AKShare universal OHLCV loader (free, no auth)."""
|
||||
@@ -78,6 +111,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping symbol -> OHLCV DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
result: Dict[str, pd.DataFrame] = {}
|
||||
for code in codes:
|
||||
try:
|
||||
@@ -94,12 +129,17 @@ class DataLoader:
|
||||
"""Fetch a single symbol."""
|
||||
import akshare as ak
|
||||
|
||||
# ETF check must precede A-share — 518880.SH ends with .SH but is an ETF.
|
||||
if _is_etf_listed(code):
|
||||
return self._fetch_etf(ak, code, start_date, end_date)
|
||||
if _is_a_share(code):
|
||||
return self._fetch_a_share(ak, code, start_date, end_date, interval)
|
||||
if _is_us(code):
|
||||
return self._fetch_us(ak, code, start_date, end_date)
|
||||
if _is_hk(code):
|
||||
return self._fetch_hk(ak, code, start_date, end_date)
|
||||
if _is_forex(code):
|
||||
return self._fetch_forex(ak, code, start_date, end_date)
|
||||
# Default: try A-share
|
||||
return self._fetch_a_share(ak, code, start_date, end_date, interval)
|
||||
|
||||
@@ -142,6 +182,49 @@ class DataLoader:
|
||||
continue
|
||||
return None
|
||||
|
||||
def _fetch_etf(self, ak, code: str, start_date: str, end_date: str) -> Optional[pd.DataFrame]:
|
||||
"""Fetch exchange-listed ETF / LOF via fund_etf_hist_sina.
|
||||
|
||||
Sina symbol format is ``sh518880`` / ``sz159915``. The endpoint returns
|
||||
the full history; we filter to the requested window after fetching.
|
||||
"""
|
||||
digits, _, suffix = code.upper().partition(".")
|
||||
symbol = f"{suffix.lower()}{digits}"
|
||||
df = ak.fund_etf_hist_sina(symbol=symbol)
|
||||
if df is None or df.empty:
|
||||
return None
|
||||
df = self._normalize(df, date_col="date")
|
||||
# fund_etf_hist_sina returns full history — clip to window.
|
||||
return df.loc[start_date:end_date]
|
||||
|
||||
def _fetch_forex(self, ak, code: str, start_date: str, end_date: str) -> Optional[pd.DataFrame]:
|
||||
"""Fetch forex pair via forex_hist_em.
|
||||
|
||||
Columns returned are 日期 / 代码 / 名称 / 今开 / 最新价 / 最高 / 最低 / 振幅
|
||||
— note ``最新价`` (latest) plays the role of close. Volume isn't reported,
|
||||
so we synthesize a zero column to satisfy the OHLCV contract.
|
||||
"""
|
||||
symbol = code.upper().removesuffix(".FX")
|
||||
df = ak.forex_hist_em(symbol=symbol)
|
||||
if df is None or df.empty:
|
||||
return None
|
||||
df = df.rename(columns={
|
||||
"日期": "trade_date",
|
||||
"今开": "open",
|
||||
"最新价": "close",
|
||||
"最高": "high",
|
||||
"最低": "low",
|
||||
})
|
||||
df["trade_date"] = pd.to_datetime(df["trade_date"])
|
||||
df = df.set_index("trade_date").sort_index()
|
||||
df["volume"] = 0.0
|
||||
for col in ("open", "high", "low", "close"):
|
||||
df[col] = pd.to_numeric(df[col], errors="coerce")
|
||||
df = df[["open", "high", "low", "close", "volume"]].dropna(
|
||||
subset=["open", "high", "low", "close"]
|
||||
)
|
||||
return df.loc[start_date:end_date]
|
||||
|
||||
def _fetch_hk(self, ak, code: str, start_date: str, end_date: str) -> Optional[pd.DataFrame]:
|
||||
"""Fetch HK stock via stock_hk_hist."""
|
||||
symbol = code.replace(".HK", "").zfill(5)
|
||||
|
||||
@@ -11,6 +11,25 @@ class NoAvailableSourceError(Exception):
|
||||
"""Raised when no data source is available for a given market."""
|
||||
|
||||
|
||||
def validate_date_range(start_date: str, end_date: str) -> None:
|
||||
"""Validate that start_date <= end_date.
|
||||
|
||||
Args:
|
||||
start_date: Start date string (YYYY-MM-DD).
|
||||
end_date: End date string (YYYY-MM-DD).
|
||||
|
||||
Raises:
|
||||
ValueError: If dates are invalid or start > end.
|
||||
"""
|
||||
try:
|
||||
start = pd.Timestamp(start_date)
|
||||
end = pd.Timestamp(end_date)
|
||||
except Exception as exc:
|
||||
raise ValueError(f"Invalid date format: start={start_date!r}, end={end_date!r}") from exc
|
||||
if start > end:
|
||||
raise ValueError(f"start_date ({start_date}) > end_date ({end_date})")
|
||||
|
||||
|
||||
@runtime_checkable
|
||||
class DataLoaderProtocol(Protocol):
|
||||
"""Interface that every data source loader must satisfy."""
|
||||
|
||||
@@ -13,6 +13,7 @@ from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -73,6 +74,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping symbol -> OHLCV DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
exchange = self._get_exchange()
|
||||
timeframe = _INTERVAL_MAP.get(interval, "1d")
|
||||
since_ms = int(pd.Timestamp(start_date).timestamp() * 1000)
|
||||
|
||||
@@ -0,0 +1,163 @@
|
||||
"""Futu OpenAPI-backed loader for HK and China A-share OHLCV data."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import os
|
||||
from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import NoAvailableSourceError, validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_OHLCV_COLUMNS = ["open", "high", "low", "close", "volume"]
|
||||
|
||||
_INTERVAL_MAP: dict[str, str] = {
|
||||
"1D": "K_DAY",
|
||||
"1H": "K_60M",
|
||||
"4H": "K_240M",
|
||||
"1W": "K_WEEK",
|
||||
"1M": "K_MON",
|
||||
}
|
||||
|
||||
|
||||
def _to_futu_symbol(code: str) -> str:
|
||||
"""Convert project symbol to Futu OpenAPI format.
|
||||
|
||||
Examples:
|
||||
700.HK -> HK.00700
|
||||
5.HK -> HK.00005
|
||||
000001.SZ -> SZ.000001
|
||||
600519.SH -> SH.600519
|
||||
"""
|
||||
upper = code.strip().upper()
|
||||
if upper.endswith(".HK"):
|
||||
return f"HK.{upper[:-3].zfill(5)}"
|
||||
if upper.endswith(".SZ"):
|
||||
return f"SZ.{upper[:-3].zfill(6)}"
|
||||
if upper.endswith(".SH"):
|
||||
return f"SH.{upper[:-3].zfill(6)}"
|
||||
return upper
|
||||
|
||||
|
||||
def _to_futu_ktype(interval: str):
|
||||
"""Map project interval string to a futu KLType enum value.
|
||||
|
||||
Lazy-imports futu so the module can be imported without futu installed.
|
||||
Unknown intervals fall back to K_DAY.
|
||||
"""
|
||||
from futu import KLType # noqa: PLC0415
|
||||
return getattr(KLType, _INTERVAL_MAP.get(interval.strip(), "K_DAY"))
|
||||
|
||||
|
||||
def _normalize_frame(df: pd.DataFrame) -> pd.DataFrame:
|
||||
"""Normalise a Futu kline DataFrame to the standard OHLCV schema.
|
||||
|
||||
Args:
|
||||
df: Raw DataFrame returned by ``request_history_kline()``.
|
||||
|
||||
Returns:
|
||||
DataFrame with columns [open, high, low, close, volume] indexed
|
||||
by ``trade_date`` (timezone-naive DatetimeIndex), sorted ascending.
|
||||
"""
|
||||
if df.empty:
|
||||
return pd.DataFrame(columns=_OHLCV_COLUMNS)
|
||||
|
||||
result = df.copy()
|
||||
result.index = pd.to_datetime(result["time_key"])
|
||||
result.index.name = "trade_date"
|
||||
result = result[_OHLCV_COLUMNS].copy()
|
||||
result = result.apply(pd.to_numeric, errors="coerce")
|
||||
result["volume"] = result["volume"].fillna(0.0)
|
||||
result = result.dropna(subset=["open", "high", "low", "close"])
|
||||
return result.sort_index()
|
||||
|
||||
|
||||
@register
|
||||
class FutuLoader:
|
||||
"""Fetch HK and China A-share bars from Futu OpenAPI.
|
||||
|
||||
Requires FutuOpenD running locally (https://www.futunn.com/download/openAPI)
|
||||
and the environment variables ``FUTU_HOST`` / ``FUTU_PORT`` to be set.
|
||||
"""
|
||||
|
||||
name = "futu"
|
||||
markets = {"hk_equity", "a_share"}
|
||||
requires_auth = True
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._host = os.environ.get("FUTU_HOST", "127.0.0.1")
|
||||
self._port = int(os.environ.get("FUTU_PORT", "11111"))
|
||||
|
||||
def is_available(self) -> bool:
|
||||
"""Return True if env vars are set and FutuOpenD is reachable."""
|
||||
if not os.environ.get("FUTU_HOST") or not os.environ.get("FUTU_PORT"):
|
||||
return False
|
||||
try:
|
||||
import futu # noqa: PLC0415
|
||||
ctx = futu.OpenQuoteContext(host=self._host, port=self._port)
|
||||
ctx.close()
|
||||
return True
|
||||
except Exception:
|
||||
return False
|
||||
|
||||
def fetch(
|
||||
self,
|
||||
codes: List[str],
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
*,
|
||||
interval: str = "1D",
|
||||
fields: Optional[List[str]] = None,
|
||||
) -> Dict[str, pd.DataFrame]:
|
||||
"""Fetch OHLCV history from Futu OpenAPI.
|
||||
|
||||
Args:
|
||||
codes: Project symbols such as ``700.HK`` or ``000001.SZ``.
|
||||
start_date: Start date in ``YYYY-MM-DD`` format.
|
||||
end_date: End date in ``YYYY-MM-DD`` format.
|
||||
interval: Backtest interval — ``1D``, ``1H``, or ``4H``.
|
||||
fields: Ignored; included for interface compatibility.
|
||||
|
||||
Returns:
|
||||
Mapping of input symbol to normalised OHLCV dataframe.
|
||||
|
||||
Raises:
|
||||
NoAvailableSourceError: If FutuOpenD connection fails.
|
||||
"""
|
||||
del fields
|
||||
if not codes:
|
||||
return {}
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
try:
|
||||
import futu # noqa: PLC0415
|
||||
ktype = _to_futu_ktype(interval)
|
||||
ctx = futu.OpenQuoteContext(host=self._host, port=self._port)
|
||||
except Exception as exc:
|
||||
raise NoAvailableSourceError(
|
||||
f"Cannot connect to FutuOpenD at {self._host}:{self._port}: {exc}"
|
||||
) from exc
|
||||
|
||||
results: Dict[str, pd.DataFrame] = {}
|
||||
try:
|
||||
for code in codes:
|
||||
futu_code = _to_futu_symbol(code)
|
||||
ret, data = ctx.request_history_kline(
|
||||
futu_code,
|
||||
start=start_date,
|
||||
end=end_date,
|
||||
ktype=ktype,
|
||||
max_count=10_000,
|
||||
)
|
||||
if ret != futu.RET_OK:
|
||||
logger.warning("Futu returned error for %s: %s", futu_code, data)
|
||||
continue
|
||||
results[code] = _normalize_frame(data)
|
||||
finally:
|
||||
ctx.close()
|
||||
|
||||
return results
|
||||
@@ -10,6 +10,7 @@ from typing import Dict, List, Optional
|
||||
import pandas as pd
|
||||
import requests
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
BASE_URL = "https://www.okx.com/api/v5"
|
||||
@@ -52,6 +53,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping symbol -> DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
if fields:
|
||||
print(f"[WARN] OKX ignores extra fields: {fields}")
|
||||
|
||||
|
||||
@@ -52,6 +52,7 @@ def _ensure_registered() -> None:
|
||||
"backtest.loaders.yfinance_loader",
|
||||
"backtest.loaders.akshare_loader",
|
||||
"backtest.loaders.ccxt_loader",
|
||||
"backtest.loaders.futu",
|
||||
]
|
||||
import importlib
|
||||
for mod in _loader_modules:
|
||||
@@ -68,7 +69,7 @@ def _ensure_registered() -> None:
|
||||
FALLBACK_CHAINS: dict[str, list[str]] = {
|
||||
"a_share": ["tushare", "akshare"],
|
||||
"us_equity": ["yfinance", "akshare"],
|
||||
"hk_equity": ["yfinance", "akshare"],
|
||||
"hk_equity": ["yfinance", "futu", "akshare"],
|
||||
"crypto": ["okx", "ccxt"],
|
||||
"futures": ["tushare", "akshare"],
|
||||
"fund": ["tushare", "akshare"],
|
||||
@@ -98,8 +99,15 @@ def resolve_loader(market: str) -> Any:
|
||||
for name in chain:
|
||||
if name not in LOADER_REGISTRY:
|
||||
continue
|
||||
loader = LOADER_REGISTRY[name]()
|
||||
tried.append(name)
|
||||
# Issue #50 — some loaders (e.g. Tushare) call into the SDK during
|
||||
# __init__ and raise on missing credentials. Treat that the same as
|
||||
# is_available()=False so the fallback chain keeps walking.
|
||||
try:
|
||||
loader = LOADER_REGISTRY[name]()
|
||||
except Exception as exc:
|
||||
logger.debug("loader %s failed to construct: %s", name, exc)
|
||||
continue
|
||||
if loader.is_available():
|
||||
return loader
|
||||
raise NoAvailableSourceError(
|
||||
@@ -125,8 +133,12 @@ def get_loader_cls_with_fallback(source: str) -> Type[Any]:
|
||||
raise NoAvailableSourceError(f"Unknown data source: {source}")
|
||||
|
||||
loader_cls = LOADER_REGISTRY[source]
|
||||
instance = loader_cls()
|
||||
if instance.is_available():
|
||||
try:
|
||||
instance = loader_cls()
|
||||
except Exception as exc:
|
||||
logger.debug("loader %s failed to construct: %s", source, exc)
|
||||
instance = None
|
||||
if instance is not None and instance.is_available():
|
||||
return loader_cls
|
||||
|
||||
# Source unavailable — try same-market fallback
|
||||
|
||||
@@ -9,6 +9,7 @@ from typing import Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
|
||||
@@ -51,6 +52,8 @@ class DataLoader:
|
||||
Returns:
|
||||
Mapping code -> OHLCV DataFrame.
|
||||
"""
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
if interval != "1D":
|
||||
return self._fetch_minutes(codes, start_date, end_date, interval)
|
||||
|
||||
|
||||
@@ -8,6 +8,7 @@ from typing import Dict, List, Optional, Union
|
||||
import pandas as pd
|
||||
import yfinance as yf
|
||||
|
||||
from backtest.loaders.base import validate_date_range
|
||||
from backtest.loaders.registry import register
|
||||
|
||||
_OHLCV_COLUMNS = ["open", "high", "low", "close", "volume"]
|
||||
@@ -230,6 +231,7 @@ class DataLoader:
|
||||
del fields
|
||||
if not codes:
|
||||
return {}
|
||||
validate_date_range(start_date, end_date)
|
||||
|
||||
requested_interval = str(interval or "1D").strip()
|
||||
yf_interval = _to_yfinance_interval(requested_interval)
|
||||
|
||||
@@ -147,7 +147,7 @@ def calc_metrics(
|
||||
equity_curve: pd.Series,
|
||||
trades: List[TradeRecord],
|
||||
initial_cash: float,
|
||||
bars_per_year: int = 252,
|
||||
bars_per_year: Optional[int] = 252,
|
||||
bench_ret: Optional[pd.Series] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""Full set of performance metrics.
|
||||
@@ -156,7 +156,8 @@ def calc_metrics(
|
||||
equity_curve: Equity time series (index=timestamp, values=equity).
|
||||
trades: Completed round-trip trades.
|
||||
initial_cash: Starting capital.
|
||||
bars_per_year: Bars per year for annualisation.
|
||||
bars_per_year: Bars per year for annualisation. None = auto-detect
|
||||
from equity curve dates (calendar-day method, for cross-market).
|
||||
bench_ret: Benchmark per-bar return series (optional).
|
||||
|
||||
Returns:
|
||||
@@ -166,7 +167,15 @@ def calc_metrics(
|
||||
return _empty_metrics(initial_cash)
|
||||
|
||||
n = len(equity_curve)
|
||||
bpy = bars_per_year
|
||||
|
||||
# Calendar-day annualization for cross-market (bars_per_year=None)
|
||||
if bars_per_year is None:
|
||||
first, last = equity_curve.index[0], equity_curve.index[-1]
|
||||
calendar_days = (last - first).days
|
||||
years = calendar_days / 365.25 if calendar_days > 0 else 1.0
|
||||
bpy = int(n / years) if years > 0 else 252
|
||||
else:
|
||||
bpy = bars_per_year
|
||||
|
||||
port_ret = equity_curve.pct_change().fillna(0.0)
|
||||
|
||||
|
||||
+125
-3
@@ -13,7 +13,10 @@ import logging
|
||||
import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Dict, List
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
import pandas as pd
|
||||
from pydantic import BaseModel, ConfigDict, model_validator, field_validator
|
||||
|
||||
try:
|
||||
from dotenv import load_dotenv
|
||||
@@ -22,6 +25,7 @@ except ImportError:
|
||||
pass
|
||||
|
||||
from backtest.loaders.registry import (
|
||||
FALLBACK_CHAINS,
|
||||
LOADER_REGISTRY,
|
||||
get_loader_cls_with_fallback,
|
||||
resolve_loader,
|
||||
@@ -30,6 +34,70 @@ from backtest.loaders.base import NoAvailableSourceError
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_VALID_INTERVALS = {"1m", "5m", "15m", "30m", "1H", "4H", "1D"}
|
||||
_VALID_ENGINES = {"daily", "options"}
|
||||
_VALID_SOURCES = {"tushare", "okx", "yfinance", "akshare", "ccxt", "auto"}
|
||||
|
||||
|
||||
class BacktestConfigSchema(BaseModel):
|
||||
"""Validates backtest config.json before execution."""
|
||||
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
codes: List[str]
|
||||
start_date: str
|
||||
end_date: str
|
||||
source: str = "tushare"
|
||||
interval: str = "1D"
|
||||
engine: str = "daily"
|
||||
|
||||
@field_validator("codes")
|
||||
@classmethod
|
||||
def codes_not_empty(cls, v: List[str]) -> List[str]:
|
||||
if not v:
|
||||
raise ValueError("codes must be a non-empty list")
|
||||
if any(not c.strip() for c in v):
|
||||
raise ValueError("codes must not contain empty strings")
|
||||
return v
|
||||
|
||||
@field_validator("start_date", "end_date")
|
||||
@classmethod
|
||||
def valid_date(cls, v: str) -> str:
|
||||
try:
|
||||
pd.Timestamp(v)
|
||||
except Exception:
|
||||
raise ValueError(f"invalid date format: {v!r} (expected YYYY-MM-DD)")
|
||||
return v
|
||||
|
||||
@field_validator("interval")
|
||||
@classmethod
|
||||
def valid_interval(cls, v: str) -> str:
|
||||
if v not in _VALID_INTERVALS:
|
||||
raise ValueError(f"unsupported interval {v!r}, must be one of {_VALID_INTERVALS}")
|
||||
return v
|
||||
|
||||
@field_validator("engine")
|
||||
@classmethod
|
||||
def valid_engine(cls, v: str) -> str:
|
||||
if v not in _VALID_ENGINES:
|
||||
raise ValueError(f"unsupported engine {v!r}, must be one of {_VALID_ENGINES}")
|
||||
return v
|
||||
|
||||
@field_validator("source")
|
||||
@classmethod
|
||||
def valid_source(cls, v: str) -> str:
|
||||
if v not in _VALID_SOURCES:
|
||||
raise ValueError(f"unsupported source {v!r}, must be one of {_VALID_SOURCES}")
|
||||
return v
|
||||
|
||||
@model_validator(mode="after")
|
||||
def start_before_end(self) -> "BacktestConfigSchema":
|
||||
if pd.Timestamp(self.start_date) > pd.Timestamp(self.end_date):
|
||||
raise ValueError(
|
||||
f"start_date ({self.start_date}) must be <= end_date ({self.end_date})"
|
||||
)
|
||||
return self
|
||||
|
||||
|
||||
def _load_module_from_file(file_path: Path, module_name: str):
|
||||
"""Load a Python module from a file path via importlib.
|
||||
@@ -192,7 +260,17 @@ def main(run_dir: Path) -> None:
|
||||
print(json.dumps({"error": "config.json not found"}))
|
||||
sys.exit(1)
|
||||
|
||||
config = json.loads(config_path.read_text(encoding="utf-8"))
|
||||
raw_config = json.loads(config_path.read_text(encoding="utf-8"))
|
||||
|
||||
# Validate config schema
|
||||
try:
|
||||
BacktestConfigSchema(**raw_config)
|
||||
except Exception as exc:
|
||||
errors = str(exc)
|
||||
print(json.dumps({"error": f"Invalid config: {errors}"}))
|
||||
sys.exit(1)
|
||||
|
||||
config = raw_config
|
||||
source = config.get("source", "tushare")
|
||||
codes = config.get("codes", [])
|
||||
|
||||
@@ -225,6 +303,25 @@ def main(run_dir: Path) -> None:
|
||||
fields=config.get("extra_fields") or None,
|
||||
interval=interval,
|
||||
)
|
||||
# Runtime fallback: try next sources in chain when primary returns empty
|
||||
if not data_map and codes:
|
||||
market = _detect_market(codes[0])
|
||||
for fb_name in FALLBACK_CHAINS.get(market, []):
|
||||
if fb_name == source or fb_name not in LOADER_REGISTRY:
|
||||
continue
|
||||
fb_loader = LOADER_REGISTRY[fb_name]()
|
||||
if not fb_loader.is_available():
|
||||
continue
|
||||
fb_codes = _normalize_codes(codes, fb_name)
|
||||
data_map = fb_loader.fetch(
|
||||
fb_codes, config.get("start_date", ""),
|
||||
config.get("end_date", ""), interval=interval,
|
||||
)
|
||||
if data_map:
|
||||
logger.info("Runtime fallback: %s -> %s", source, fb_name)
|
||||
source = fb_name
|
||||
loader = fb_loader
|
||||
break
|
||||
if not data_map:
|
||||
print(json.dumps({"error": "No data fetched"}))
|
||||
sys.exit(1)
|
||||
@@ -236,7 +333,12 @@ def main(run_dir: Path) -> None:
|
||||
# Annualization bars
|
||||
effective_source = _detect_primary_source(codes, source)
|
||||
from backtest.metrics import calc_bars_per_year
|
||||
bars_per_year = calc_bars_per_year(interval, effective_source)
|
||||
# Cross-market: use calendar-day annualization (bars_per_year=None)
|
||||
market_types = {_detect_market(c) for c in codes}
|
||||
if len(market_types) > 1:
|
||||
bars_per_year = None
|
||||
else:
|
||||
bars_per_year = calc_bars_per_year(interval, effective_source)
|
||||
|
||||
# Auto mode: wrap preloaded data in a dummy loader
|
||||
if source == "auto":
|
||||
@@ -268,6 +370,11 @@ def _create_market_engine(source: str, config: dict, codes: List[str]):
|
||||
# Detect dominant market type from codes
|
||||
markets = {_detect_market(c) for c in codes} if codes else set()
|
||||
|
||||
# Cross-market -> CompositeEngine
|
||||
if len(markets) > 1:
|
||||
from backtest.engines.composite import CompositeEngine
|
||||
return CompositeEngine(config, codes)
|
||||
|
||||
# Futures routing (Wave 2)
|
||||
if "futures" in markets:
|
||||
# Distinguish China vs global futures by exchange suffix
|
||||
@@ -399,6 +506,21 @@ def _fetch_auto(codes: List[str], config: dict, interval: str = "1D") -> dict:
|
||||
normalized_codes = _normalize_codes(market_codes, src_name)
|
||||
fields = config.get("extra_fields") if src_name == "tushare" else None
|
||||
result = loader.fetch(normalized_codes, start_date, end_date, fields=fields, interval=interval)
|
||||
|
||||
# Runtime fallback: try remaining sources when primary returns empty
|
||||
if not result:
|
||||
for fb_name in FALLBACK_CHAINS.get(market, []):
|
||||
if fb_name == src_name or fb_name not in LOADER_REGISTRY:
|
||||
continue
|
||||
fb_loader = LOADER_REGISTRY[fb_name]()
|
||||
if not fb_loader.is_available():
|
||||
continue
|
||||
fb_codes = _normalize_codes(market_codes, fb_name)
|
||||
result = fb_loader.fetch(fb_codes, start_date, end_date, interval=interval)
|
||||
if result:
|
||||
logger.info("Runtime fallback: %s -> %s for %s", src_name, fb_name, market)
|
||||
break
|
||||
|
||||
merged.update(result)
|
||||
|
||||
return merged
|
||||
|
||||
+112
-25
@@ -51,7 +51,7 @@ EXIT_RUN_FAILED = 1
|
||||
EXIT_USAGE_ERROR = 2
|
||||
RICH_TAG_PATTERN = re.compile(r"\[/?[^\]]+\]")
|
||||
|
||||
_VERSION = "0.1.0"
|
||||
_VERSION = "0.1.5"
|
||||
|
||||
# Agent color assignments for swarm display
|
||||
_AGENT_STYLES = ["cyan", "magenta", "green", "yellow", "blue", "bright_red", "bright_cyan", "bright_magenta"]
|
||||
@@ -172,17 +172,10 @@ def _format_tool_call_args(tool: str, args: Dict[str, str]) -> str:
|
||||
if tool in ("bash", "background_run"):
|
||||
cmd = args.get("command", "")[:80]
|
||||
return f' [yellow]{cmd}[/yellow]'
|
||||
if tool == "subagent":
|
||||
desc = args.get("description", args.get("prompt", "")[:60])
|
||||
return f' [magenta]{desc}[/magenta]'
|
||||
if tool == "task_create":
|
||||
return f' "{args.get("subject", "")}"'
|
||||
if tool == "task_update":
|
||||
return f' #{args.get("task_id", "")} -> {args.get("status", "")}'
|
||||
if tool == "check_background":
|
||||
tid = args.get("task_id", "")
|
||||
return f' {tid}' if tid else ""
|
||||
if tool in ("backtest", "compact", "task_list"):
|
||||
if tool in ("backtest", "compact"):
|
||||
return ""
|
||||
for v in args.values():
|
||||
if v and v != "None":
|
||||
@@ -203,15 +196,18 @@ def _format_tool_result_preview(tool: str, status: str, preview: str) -> str:
|
||||
if ret:
|
||||
parts.append(f"return={float(ret.group(1))*100:.1f}%")
|
||||
return ", ".join(parts) if parts else ""
|
||||
if tool == "render_shadow_report":
|
||||
url = re.search(r'"report_url":\s*"([^"]+)"', preview)
|
||||
if url:
|
||||
return f"[bold cyan]report:[/bold cyan] [link]{url.group(1)}[/link]"
|
||||
return ""
|
||||
if tool in ("extract_shadow_strategy", "run_shadow_backtest"):
|
||||
sid = re.search(r'"shadow_id":\s*"([^"]+)"', preview)
|
||||
return f"shadow_id={sid.group(1)}" if sid else ""
|
||||
if tool in ("bash", "background_run"):
|
||||
if "OK" in preview[:50]:
|
||||
return "OK"
|
||||
return preview[:60].replace("\n", " ")
|
||||
if tool == "subagent":
|
||||
m = re.search(r'"summary":\s*"(.{0,80})', preview)
|
||||
return m.group(1).rstrip('"') if m else ""
|
||||
if tool in ("task_create", "task_update"):
|
||||
return preview[:60].replace("\n", " ")
|
||||
if tool in ("read_file", "load_skill", "compact"):
|
||||
return ""
|
||||
return ""
|
||||
@@ -283,11 +279,15 @@ def _run_agent(
|
||||
tokens = data.get("tokens_before", "?")
|
||||
console.print(f"\n [yellow]\u27f3 context compressed[/yellow] [dim]({tokens} tokens \u2192 summary)[/dim]\n")
|
||||
|
||||
from src.memory.persistent import PersistentMemory
|
||||
|
||||
pm = PersistentMemory()
|
||||
agent = AgentLoop(
|
||||
registry=build_registry(),
|
||||
registry=build_registry(persistent_memory=pm),
|
||||
llm=ChatLLM(),
|
||||
event_callback=on_event,
|
||||
max_iterations=max_iter,
|
||||
persistent_memory=pm,
|
||||
)
|
||||
if run_dir_override:
|
||||
agent.memory.run_dir = run_dir_override
|
||||
@@ -295,23 +295,80 @@ def _run_agent(
|
||||
return agent.run(user_message=prompt, history=history)
|
||||
|
||||
|
||||
def _build_benchmark_table(m: dict) -> Optional[Table]:
|
||||
"""Build a benchmark comparison table from metrics dict.
|
||||
|
||||
Args:
|
||||
m: Metrics dictionary (from _read_metrics or result dict).
|
||||
|
||||
Returns:
|
||||
Rich Table, or None if no benchmark data is present.
|
||||
"""
|
||||
bench_ticker = m.get("benchmark_ticker")
|
||||
bench_ret_str = m.get("benchmark_return")
|
||||
bench_ret_raw = m.get("_benchmark_return_raw")
|
||||
|
||||
# Fall back to equity.csv if benchmark cols not in metrics.csv yet
|
||||
if not bench_ticker:
|
||||
return None
|
||||
|
||||
# Parse benchmark return
|
||||
if bench_ret_raw is not None:
|
||||
bench_ret = bench_ret_raw
|
||||
elif bench_ret_str is not None:
|
||||
try:
|
||||
bench_ret = float(bench_ret_str)
|
||||
except (ValueError, TypeError):
|
||||
bench_ret = None
|
||||
else:
|
||||
bench_ret = None
|
||||
|
||||
strategy_ret_str = m.get("total_return")
|
||||
strategy_ret = float(strategy_ret_str) if strategy_ret_str else None
|
||||
|
||||
table = Table(show_header=False, padding=(0, 2))
|
||||
table.add_column("Label", style="dim", width=20)
|
||||
table.add_column("Value", style="white no_wrap")
|
||||
|
||||
table.add_row("[dim]Benchmark[/dim]", bench_ticker)
|
||||
|
||||
if bench_ret is not None:
|
||||
table.add_row("[dim]Benchmark Return[/dim]", f"{bench_ret * 100:+.2f}%")
|
||||
|
||||
if strategy_ret is not None and bench_ret is not None:
|
||||
excess = strategy_ret - bench_ret
|
||||
sign = "+" if excess >= 0 else ""
|
||||
style = "green" if excess >= 0 else "red"
|
||||
table.add_row(
|
||||
"[dim]vs Benchmark[/dim]",
|
||||
f"[{style}]{sign}{excess * 100:+.2f}%[/{style}]",
|
||||
)
|
||||
|
||||
ir_str = m.get("information_ratio")
|
||||
if ir_str:
|
||||
table.add_row("[dim]Info Ratio[/dim]", ir_str)
|
||||
|
||||
excess_str = m.get("excess_return")
|
||||
if excess_str and excess_str != "0" and excess_str != "0.0000":
|
||||
table.add_row("[dim]Excess Return[/dim]", f"{float(excess_str) * 100:+.2f}%")
|
||||
|
||||
return table
|
||||
|
||||
|
||||
def _print_result(result: dict, elapsed: float, *, no_rich: bool = False) -> None:
|
||||
"""Print execution result panel."""
|
||||
status = result.get("status", "unknown")
|
||||
ok = status == "success"
|
||||
style = "green" if ok else "red"
|
||||
|
||||
lines = [f"Status: [bold {style}]{status.upper()}[/bold {style}] Time: {elapsed:.1f}s"]
|
||||
|
||||
if result.get("run_id"):
|
||||
lines.append(f"ID: {result['run_id']}")
|
||||
|
||||
review = result.get("review")
|
||||
if review and review.get("overall_score") is not None:
|
||||
check = "\u2713" if review.get("passed") else "\u2717"
|
||||
lines.append(f"Review: {review['overall_score']}pts {check}")
|
||||
|
||||
run_dir = result.get("run_dir")
|
||||
m = {}
|
||||
if run_dir:
|
||||
m = _read_metrics(Path(run_dir) / "artifacts" / "metrics.csv")
|
||||
parts = [f"{k}={m[k]}" for k in ("total_return", "sharpe", "max_drawdown", "trade_count") if k in m]
|
||||
@@ -323,6 +380,17 @@ def _print_result(result: dict, elapsed: float, *, no_rich: bool = False) -> Non
|
||||
|
||||
console.print(Panel("\n".join(lines), border_style=style, title="Result"))
|
||||
|
||||
# ── Benchmark comparison panel ─────────────────────────────────────────────
|
||||
bench_table = _build_benchmark_table(m)
|
||||
if bench_table:
|
||||
console.print(Panel(
|
||||
bench_table,
|
||||
border_style="cyan",
|
||||
title="Benchmark Comparison",
|
||||
padding=(0, 1),
|
||||
))
|
||||
# ── Benchmark comparison panel ─────────────────────────────────────────
|
||||
|
||||
content = result.get("content", "").strip()
|
||||
if content:
|
||||
console.print(f"\n{content}")
|
||||
@@ -455,7 +523,9 @@ def _print_welcome() -> None:
|
||||
"\n"
|
||||
" [cyan]/skills[/cyan] List available skills [cyan]/swarm[/cyan] Agent team presets\n"
|
||||
" [cyan]/list[/cyan] Recent runs [cyan]/settings[/cyan] Runtime config\n"
|
||||
" [cyan]/help[/cyan] All commands [cyan]/quit[/cyan] Exit"
|
||||
" [cyan]/help[/cyan] All commands [cyan]/quit[/cyan] Exit\n"
|
||||
"\n"
|
||||
"[dim]Try: \"analyze my trade journal\" or \"train my shadow account\"[/dim]"
|
||||
)
|
||||
console.print(Panel(welcome, border_style="cyan", padding=(1, 2)))
|
||||
|
||||
@@ -484,6 +554,10 @@ def _print_help() -> None:
|
||||
("/settings", "Show runtime settings"),
|
||||
("/clear", "Clear screen"),
|
||||
("/quit", "Exit"),
|
||||
("", ""),
|
||||
("[dim]--- Natural language ---[/dim]", ""),
|
||||
('"analyze journal.csv"', "Parse broker export → profile + 4 behavior diagnostics"),
|
||||
('"train my shadow"', "Extract strategy → backtest → HTML/PDF report"),
|
||||
]
|
||||
for cmd, desc in cmds:
|
||||
table.add_row(cmd, desc)
|
||||
@@ -946,7 +1020,7 @@ def cmd_list(limit: int = 20) -> None:
|
||||
st = _read_json(d / "state.json").get("status", "?")
|
||||
m = _read_metrics(d / "artifacts" / "metrics.csv")
|
||||
c = "green" if st == "success" else "red" if st == "failed" else "dim"
|
||||
table.add_row(d.name, f"[{c}]{st}[/{c}]", m.get("total_return", ""), m.get("sharpe", ""), (_read_json(d / "req.json").get("prompt") or "")[:40])
|
||||
table.add_row(d.name, f"[{c}]{st.upper()}[/{c}]", m.get("total_return", ""), m.get("sharpe", ""), (_read_json(d / "req.json").get("prompt") or "")[:40])
|
||||
|
||||
console.print(table)
|
||||
|
||||
@@ -964,8 +1038,9 @@ def cmd_show(run_id: str) -> None:
|
||||
|
||||
st = state.get("status", "unknown")
|
||||
c = "green" if st == "success" else "red"
|
||||
lines = [f"[bold]Status:[/bold] [{c}]{st.upper()}[/{c}]", f"[bold]Prompt:[/bold] {req.get('prompt', '?')}"]
|
||||
|
||||
lines = [f"[bold]Status:[/bold] [{c}]{st.upper()}[/{c}]"]
|
||||
if req.get("prompt"):
|
||||
lines.append(f"[bold]Prompt:[/bold] {req['prompt'][:500]}{'...' if len(req['prompt']) > 500 else ''}")
|
||||
if metrics:
|
||||
lines.append("\n[bold]Metrics:[/bold]")
|
||||
lines.extend(f" {k}: {v}" for k, v in metrics.items())
|
||||
@@ -1519,6 +1594,16 @@ _PROVIDER_CHOICES: list[dict[str, str | None]] = [
|
||||
"key_prefix": None,
|
||||
"key_placeholder": "api-key...",
|
||||
},
|
||||
{
|
||||
"label": "Z.ai (Coding platform)",
|
||||
"provider": "zai",
|
||||
"key_env": "ZAI_API_KEY",
|
||||
"base_env": "ZAI_BASE_URL",
|
||||
"base_url": "https://api.z.ai/api/coding/paas/v4",
|
||||
"model": "glm-5.1",
|
||||
"key_prefix": None,
|
||||
"key_placeholder": "api-key...",
|
||||
},
|
||||
{
|
||||
"label": "Ollama (local, free)",
|
||||
"provider": "ollama",
|
||||
@@ -1564,6 +1649,8 @@ def _render_env_content(config: dict[str, str]) -> str:
|
||||
"MINIMAX_BASE_URL",
|
||||
"MIMO_API_KEY",
|
||||
"MIMO_BASE_URL",
|
||||
"ZAI_API_KEY",
|
||||
"ZAI_BASE_URL",
|
||||
"OLLAMA_BASE_URL",
|
||||
"LANGCHAIN_MODEL_NAME",
|
||||
"TUSHARE_TOKEN",
|
||||
@@ -1684,7 +1771,7 @@ def main(argv: list[str] | None = None) -> int:
|
||||
if args.command == "list":
|
||||
return _coerce_exit_code(cmd_list(args.list_limit))
|
||||
if args.command == "show":
|
||||
return _coerce_exit_code(cmd_show(args.run_id))
|
||||
return _coerce_exit_code(cmd_show(args.show))
|
||||
if args.command == "chat":
|
||||
return _coerce_exit_code(cmd_interactive(args.chat_max_iter))
|
||||
|
||||
@@ -1723,7 +1810,7 @@ def main(argv: list[str] | None = None) -> int:
|
||||
if args.chat:
|
||||
return _coerce_exit_code(cmd_interactive(args.max_iter))
|
||||
if args.cont:
|
||||
return cmd_continue(args.cont[0], args.cont[1], args.max_iter, json_mode=args.json, no_rich=args.no_rich)
|
||||
return _coerce_exit_code(cmd_continue(args.cont[0], args.cont[1], args.max_iter, json_mode=args.json, no_rich=args.no_rich))
|
||||
|
||||
# No flags, no subcommand → check if prompt provided, otherwise interactive mode
|
||||
if args.prompt or args.prompt_file or not sys.stdin.isatty():
|
||||
|
||||
+153
-3
@@ -1,5 +1,5 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Vibe-Trading MCP Server — expose 17 finance research tools to any MCP client.
|
||||
"""Vibe-Trading MCP Server — expose 22 finance research tools to any MCP client.
|
||||
|
||||
Works with OpenClaw, Claude Desktop, Cursor, and any MCP-compatible client.
|
||||
Zero API key required for HK/US/crypto markets (yfinance, OKX, AKShare are free).
|
||||
@@ -75,7 +75,7 @@ def _get_registry():
|
||||
def list_skills() -> str:
|
||||
"""List all available finance skills with names and descriptions.
|
||||
|
||||
Returns a JSON array of {name, description} for all 68 skills.
|
||||
Returns a JSON array of {name, description} for all 71 skills.
|
||||
Use load_skill(name) to get the full documentation for any skill.
|
||||
"""
|
||||
loader = _get_skills_loader()
|
||||
@@ -213,7 +213,7 @@ def pattern_recognition(run_dir: str) -> str:
|
||||
run_dir: Path to run directory containing artifacts/ohlcv_*.csv.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("pattern_recognition", {"run_dir": run_dir})
|
||||
return registry.execute("pattern", {"run_dir": run_dir})
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
@@ -537,6 +537,156 @@ def list_runs(limit: int = 20) -> str:
|
||||
return json.dumps(items, ensure_ascii=False, indent=2)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Trade journal tool
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
@mcp.tool
|
||||
def analyze_trade_journal(
|
||||
file_path: str,
|
||||
analysis_type: str = "full",
|
||||
filter_expr: str = "",
|
||||
) -> str:
|
||||
"""Analyze a user's trade journal (CSV/Excel broker export) and return
|
||||
a trading profile plus behavior diagnostics.
|
||||
|
||||
Parses 同花顺 / 东方财富 / 富途 / generic formats (encoding auto-detected).
|
||||
Output (JSON):
|
||||
- profile: holding days, frequency, win rate, PnL ratio, top symbols,
|
||||
market distribution, hourly distribution
|
||||
- behaviors: disposition effect, overtrading, chasing momentum,
|
||||
anchoring (each with severity + numeric evidence)
|
||||
|
||||
Args:
|
||||
file_path: Absolute path to the uploaded CSV/Excel file.
|
||||
analysis_type: "full" | "profile" | "behavior" | "strategy".
|
||||
filter_expr: Optional filter (e.g. "2026-01 to 2026-03",
|
||||
"symbol=600519.SH", "market=china_a").
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("analyze_trade_journal", {
|
||||
"file_path": file_path,
|
||||
"analysis_type": analysis_type,
|
||||
"filter_expr": filter_expr,
|
||||
})
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Shadow Account tools (4)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
@mcp.tool
|
||||
def extract_shadow_strategy(
|
||||
journal_path: str,
|
||||
min_support: int = 3,
|
||||
max_rules: int = 5,
|
||||
) -> str:
|
||||
"""Extract a Shadow Account profile (3-5 human-readable if-then rules)
|
||||
from the user's profitable roundtrips in a trade journal.
|
||||
|
||||
Run `analyze_trade_journal` first if the journal hasn't been parsed.
|
||||
Returns shadow_id + rules preview. Profile persists to
|
||||
~/.vibe-trading/shadow_accounts/.
|
||||
|
||||
Args:
|
||||
journal_path: Path to the CSV/Excel broker export.
|
||||
min_support: Minimum profitable roundtrips required to back one rule.
|
||||
max_rules: Maximum rules to return (typically 3-5).
|
||||
"""
|
||||
registry = _get_registry()
|
||||
return registry.execute("extract_shadow_strategy", {
|
||||
"journal_path": journal_path,
|
||||
"min_support": min_support,
|
||||
"max_rules": max_rules,
|
||||
})
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def run_shadow_backtest(
|
||||
shadow_id: str,
|
||||
window_start: str = "",
|
||||
window_end: str = "",
|
||||
markets: list[str] | None = None,
|
||||
journal_path: str = "",
|
||||
) -> str:
|
||||
"""Run a multi-market backtest (A股/港股/美股/crypto) on a Shadow Account
|
||||
profile and compute delta-PnL attribution vs the user's realized trades.
|
||||
|
||||
Requires `extract_shadow_strategy` to have run first.
|
||||
|
||||
Args:
|
||||
shadow_id: ID returned by extract_shadow_strategy.
|
||||
window_start: ISO date, default today-1y.
|
||||
window_end: ISO date, default today.
|
||||
markets: Subset of ["china_a", "hk", "us", "crypto"], default all four.
|
||||
journal_path: Original journal path (enables attribution), optional.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
params: dict[str, Any] = {"shadow_id": shadow_id}
|
||||
if window_start:
|
||||
params["window_start"] = window_start
|
||||
if window_end:
|
||||
params["window_end"] = window_end
|
||||
if markets:
|
||||
params["markets"] = markets
|
||||
if journal_path:
|
||||
params["journal_path"] = journal_path
|
||||
return registry.execute("run_shadow_backtest", params)
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def render_shadow_report(
|
||||
shadow_id: str,
|
||||
include_today_signals: bool = True,
|
||||
window_start: str = "",
|
||||
window_end: str = "",
|
||||
journal_path: str = "",
|
||||
) -> str:
|
||||
"""Render the Shadow Account HTML/PDF report (8 sections + charts) for
|
||||
a shadow_id. If no cached backtest, one is run automatically.
|
||||
|
||||
Args:
|
||||
shadow_id: Shadow Account ID.
|
||||
include_today_signals: Include today's market scan section.
|
||||
window_start: Optional backtest window override.
|
||||
window_end: Optional backtest window override.
|
||||
journal_path: Original journal path (for attribution), optional.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
params: dict[str, Any] = {
|
||||
"shadow_id": shadow_id,
|
||||
"include_today_signals": include_today_signals,
|
||||
}
|
||||
if window_start:
|
||||
params["window_start"] = window_start
|
||||
if window_end:
|
||||
params["window_end"] = window_end
|
||||
if journal_path:
|
||||
params["journal_path"] = journal_path
|
||||
return registry.execute("render_shadow_report", params)
|
||||
|
||||
|
||||
@mcp.tool
|
||||
def scan_shadow_signals(
|
||||
shadow_id: str,
|
||||
date: str = "",
|
||||
per_market: int = 3,
|
||||
) -> str:
|
||||
"""List today's symbols that match the Shadow Account's entry cadence
|
||||
(research use only — not a trade recommendation).
|
||||
|
||||
Args:
|
||||
shadow_id: Shadow Account ID.
|
||||
date: ISO YYYY-MM-DD target date, default today.
|
||||
per_market: Max signals per market.
|
||||
"""
|
||||
registry = _get_registry()
|
||||
params: dict[str, Any] = {"shadow_id": shadow_id, "per_market": per_market}
|
||||
if date:
|
||||
params["date"] = date
|
||||
return registry.execute("scan_shadow_signals", params)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Entry point
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
+16
-1
@@ -14,6 +14,13 @@ numpy>=1.24.0
|
||||
scipy>=1.10.0
|
||||
duckdb>=1.2.0
|
||||
|
||||
# Document Readers (doc_reader_tool)
|
||||
openpyxl>=3.1.0
|
||||
python-docx>=1.1.0
|
||||
python-pptx>=0.6.23
|
||||
pypdfium2>=4.0.0
|
||||
Pillow>=10.0.0
|
||||
|
||||
# ML Strategy
|
||||
scikit-learn>=1.3.0
|
||||
joblib>=1.3.0
|
||||
@@ -33,8 +40,16 @@ ccxt>=4.0.0
|
||||
fastapi>=0.104.0
|
||||
uvicorn[standard]>=0.24.0
|
||||
pydantic>=2.0.0
|
||||
python-multipart>=0.0.6
|
||||
python-multipart>=0.0.18
|
||||
sse-starlette>=1.6.0
|
||||
|
||||
# MCP Server
|
||||
fastmcp>=2.0.0
|
||||
|
||||
# Web Search
|
||||
ddgs>=6.0.0
|
||||
|
||||
# Shadow Account HTML/PDF Report
|
||||
jinja2>=3.1.0
|
||||
matplotlib>=3.7.0
|
||||
weasyprint>=60.0
|
||||
+92
-10
@@ -3,13 +3,20 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from typing import Any, Dict, List, Optional
|
||||
import logging
|
||||
from datetime import datetime
|
||||
from typing import TYPE_CHECKING, Any, Dict, List, Optional
|
||||
|
||||
from src.agent.memory import WorkspaceMemory
|
||||
from src.agent.skills import SkillsLoader
|
||||
from src.agent.tools import ToolRegistry
|
||||
|
||||
_SYSTEM_PROMPT = """You are a finance research agent with 68 specialist skills, 21 tools, 5 data sources (with auto-fallback), and 29 multi-agent swarm teams.
|
||||
if TYPE_CHECKING:
|
||||
from src.memory.persistent import PersistentMemory
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_SYSTEM_PROMPT = """You are a finance research agent with {skill_count} specialist skills, {tool_count} tools, 5 data sources (with auto-fallback), and 29 multi-agent swarm teams.
|
||||
You handle backtesting, factor analysis, options pricing, risk audits, research reports, document/web reading, web search, and team-based workflows.
|
||||
|
||||
## Tools
|
||||
@@ -35,10 +42,9 @@ Decide which workflow to use based on the request:
|
||||
4. Syntax check → `backtest(run_dir=...)` → `read_file("artifacts/metrics.csv")`
|
||||
5. Do NOT write run_backtest.py. The engine is built-in.
|
||||
|
||||
**Swarm team** — user wants multi-agent analysis, risk audit, committee review, or any task with "team/committee/panel/desk":
|
||||
**Swarm team** — ONLY when the user explicitly requests team/committee/swarm analysis:
|
||||
- Call `run_swarm(prompt="<user's full request>")` — it auto-selects the right preset.
|
||||
- Examples: risk audit, investment committee, equity research, technical panel, cross-market allocation.
|
||||
- Do NOT attempt multi-dimensional analysis solo. Use swarm.
|
||||
- Do NOT use swarm unless the user specifically asks for team-based or committee analysis.
|
||||
|
||||
**Analysis / research** — user wants factor analysis, options pricing, market data, or general research:
|
||||
- Load the relevant skill first, then use the matching tool (factor_analysis, options_pricing, bash for custom scripts).
|
||||
@@ -46,6 +52,21 @@ Decide which workflow to use based on the request:
|
||||
**Document / web** — user provides a PDF or URL:
|
||||
- `read_document(path=...)` for PDFs, `read_url(url=...)` for web pages.
|
||||
|
||||
**Trade journal** — user uploads a CSV/Excel broker export (交割单) or asks to analyze their own trading history:
|
||||
1. `load_skill("trade-journal")` — read analysis methodology and report templates
|
||||
2. `analyze_trade_journal(file_path=..., analysis_type="full")` — parse + profile + behavior diagnostics
|
||||
3. Present results as the markdown report in the skill. Offer follow-ups: time-slice, symbol deep-dive, market split.
|
||||
4. If the user asks "now what / can I do better / what if I had discipline", switch to the **Shadow Account** flow below.
|
||||
|
||||
**Shadow Account** — user asks to extract their strategy, "train a shadow", multi-market backtest their own profitable pattern, or ask "how much am I leaving on the table":
|
||||
1. **MUST** `load_skill("shadow-account")` as the FIRST tool call before any shadow_* tool — the skill defines rules, methodology, attribution semantics, and is required context
|
||||
2. Confirm the journal has been parsed (same session or known `journal_path`). If not, run `analyze_trade_journal` first.
|
||||
3. `extract_shadow_strategy(journal_path=...)` → show rules, ask user to confirm they look like their own behavior
|
||||
4. `run_shadow_backtest(shadow_id=..., journal_path=...)` → multi-market metrics + delta attribution
|
||||
5. `render_shadow_report(shadow_id=...)` → share html/pdf path, lead with the Section 5 "you vs shadow" delta
|
||||
6. Optional: `scan_shadow_signals(shadow_id=...)` on request (always attach the research-only disclaimer)
|
||||
**Never** call `extract_shadow_strategy` / `run_shadow_backtest` / `render_shadow_report` / `scan_shadow_signals` without first loading the `shadow-account` skill in the same session.
|
||||
|
||||
## Guidelines
|
||||
|
||||
- Load the relevant skill BEFORE starting any task. Skills contain the exact API contracts and examples.
|
||||
@@ -53,6 +74,19 @@ Decide which workflow to use based on the request:
|
||||
- Output results as markdown tables. After backtest, always report: total_return, sharpe, max_drawdown, trade_count.
|
||||
- All file paths are relative to run_dir (auto-injected).
|
||||
- Respond in the same language the user used.
|
||||
- You have persistent cross-session memory (`remember` tool). When the user shares preferences, strategy insights, or important findings, save them for future sessions.
|
||||
- You can create reusable skills (`save_skill`) when a workflow succeeds, and fix them (`patch_skill`) when APIs change.
|
||||
{memory_section}
|
||||
## Current Date & Time
|
||||
|
||||
Today is {current_datetime}.
|
||||
"""
|
||||
|
||||
_MEMORY_SECTION = """
|
||||
## Persistent Memory (cross-session)
|
||||
|
||||
{snapshot}
|
||||
|
||||
"""
|
||||
|
||||
|
||||
@@ -66,22 +100,26 @@ class ContextBuilder:
|
||||
"""
|
||||
|
||||
def __init__(self, registry: ToolRegistry, memory: WorkspaceMemory,
|
||||
skills_loader: Optional[SkillsLoader] = None) -> None:
|
||||
skills_loader: Optional[SkillsLoader] = None,
|
||||
persistent_memory: Optional[PersistentMemory] = None) -> None:
|
||||
"""Initialize ContextBuilder.
|
||||
|
||||
Args:
|
||||
registry: Tool registry.
|
||||
memory: Workspace memory.
|
||||
skills_loader: Skills loader (auto-created if not provided).
|
||||
persistent_memory: PersistentMemory instance for cross-session recall.
|
||||
"""
|
||||
self.registry = registry
|
||||
self.memory = memory
|
||||
self.skills_loader = skills_loader or SkillsLoader()
|
||||
self._persistent_memory = persistent_memory
|
||||
|
||||
def build_system_prompt(self, user_message: str = "") -> str:
|
||||
"""Build system prompt.
|
||||
|
||||
Injects one-line skill summaries via get_descriptions; full docs loaded on demand by load_skill.
|
||||
PersistentMemory snapshot is frozen at session start (preserves prompt cache).
|
||||
|
||||
Args:
|
||||
user_message: User message (kept for API compatibility).
|
||||
@@ -89,15 +127,32 @@ class ContextBuilder:
|
||||
Returns:
|
||||
System prompt text.
|
||||
"""
|
||||
now = datetime.now()
|
||||
|
||||
# Build memory section only if there are saved memories
|
||||
memory_section = ""
|
||||
if self._persistent_memory and self._persistent_memory.snapshot:
|
||||
memory_section = _MEMORY_SECTION.format(
|
||||
snapshot=self._persistent_memory.snapshot,
|
||||
)
|
||||
|
||||
return _SYSTEM_PROMPT.format(
|
||||
tool_count=len(self.registry._tools),
|
||||
skill_count=len(self.skills_loader.skills),
|
||||
tool_descriptions=self._format_tool_descriptions(),
|
||||
skill_descriptions=self.skills_loader.get_descriptions(),
|
||||
memory_summary=self.memory.to_summary(),
|
||||
memory_section=memory_section,
|
||||
current_datetime=now.strftime("%A, %B %d, %Y %H:%M (local)"),
|
||||
)
|
||||
|
||||
def build_messages(self, user_message: str, history: Optional[List[Dict[str, Any]]] = None) -> List[Dict[str, Any]]:
|
||||
"""Build full message list.
|
||||
|
||||
Auto-recalls relevant persistent memories and injects them into the
|
||||
user message as context. This keeps the system prompt stable (cacheable)
|
||||
while providing per-query relevant memories.
|
||||
|
||||
Args:
|
||||
user_message: User message.
|
||||
history: Prior conversation messages.
|
||||
@@ -110,7 +165,23 @@ class ContextBuilder:
|
||||
]
|
||||
if history:
|
||||
messages.extend(history)
|
||||
messages.append({"role": "user", "content": user_message})
|
||||
|
||||
# Auto-recall: inject relevant memories into user message
|
||||
enriched = user_message
|
||||
if self._persistent_memory:
|
||||
try:
|
||||
recalls = self._persistent_memory.find_relevant(user_message, max_results=3)
|
||||
if recalls:
|
||||
lines = [f"- **{r.title}** ({r.memory_type}): {r.body[:500]}" for r in recalls]
|
||||
recall_block = "\n".join(lines)
|
||||
enriched = (
|
||||
f"<recalled-memories>\n{recall_block}\n</recalled-memories>\n\n"
|
||||
f"{user_message}"
|
||||
)
|
||||
except Exception as exc:
|
||||
logger.debug("Auto-recall failed: %s", exc)
|
||||
|
||||
messages.append({"role": "user", "content": enriched})
|
||||
return messages
|
||||
|
||||
def _format_tool_descriptions(self) -> str:
|
||||
@@ -138,17 +209,25 @@ class ContextBuilder:
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def format_assistant_tool_calls(tool_calls: list, content: Optional[str] = None) -> Dict[str, Any]:
|
||||
def format_assistant_tool_calls(
|
||||
tool_calls: list,
|
||||
content: Optional[str] = None,
|
||||
reasoning_content: Optional[str] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""Format an assistant tool_calls message, preserving thinking text.
|
||||
|
||||
Args:
|
||||
tool_calls: List of tool call objects.
|
||||
content: Model reasoning/thinking text.
|
||||
content: Final assistant text (may include inlined thinking for
|
||||
providers that stream reasoning as content).
|
||||
reasoning_content: Provider-specific reasoning field (Kimi K2.5,
|
||||
DeepSeek reasoner, Qwen thinking). Only attached to the output
|
||||
message when not None, so non-thinking providers see no change.
|
||||
|
||||
Returns:
|
||||
OpenAI-format assistant message.
|
||||
"""
|
||||
return {
|
||||
message = {
|
||||
"role": "assistant",
|
||||
"content": content,
|
||||
"tool_calls": [
|
||||
@@ -163,3 +242,6 @@ class ContextBuilder:
|
||||
for tc in tool_calls
|
||||
],
|
||||
}
|
||||
if reasoning_content is not None:
|
||||
message["reasoning_content"] = reasoning_content
|
||||
return message
|
||||
@@ -0,0 +1,40 @@
|
||||
"""Shared YAML-like frontmatter parser for skills and memory files."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from typing import Any, Dict
|
||||
|
||||
|
||||
def parse_frontmatter(text: str) -> tuple[Dict[str, Any], str]:
|
||||
"""Parse YAML-like frontmatter and body from a markdown file.
|
||||
|
||||
Supports string, list (``[a, b]``), and boolean values.
|
||||
|
||||
Args:
|
||||
text: Markdown text with optional ``---`` delimited frontmatter.
|
||||
|
||||
Returns:
|
||||
Tuple of (metadata dict, body text).
|
||||
"""
|
||||
match = re.match(r"^---\s*\n(.*?)\n---\s*\n(.*)", text, re.DOTALL)
|
||||
if not match:
|
||||
return {}, text.strip()
|
||||
|
||||
meta: Dict[str, Any] = {}
|
||||
for line in match.group(1).strip().split("\n"):
|
||||
line = line.strip()
|
||||
if ":" not in line:
|
||||
continue
|
||||
key, value = line.split(":", 1)
|
||||
key = key.strip()
|
||||
value = value.strip()
|
||||
if value.startswith("[") and value.endswith("]"):
|
||||
items = [item.strip().strip("'\"") for item in value[1:-1].split(",")]
|
||||
meta[key] = [i for i in items if i]
|
||||
elif value.lower() in ("true", "false"):
|
||||
meta[key] = value.lower() == "true"
|
||||
else:
|
||||
meta[key] = value
|
||||
|
||||
return meta, match.group(2).strip()
|
||||
+533
-84
@@ -1,13 +1,19 @@
|
||||
"""AgentLoop: ReAct core loop.
|
||||
|
||||
Three-layer context management:
|
||||
Layer 1 (microcompact) — silently prunes old tool results each iteration, keeping the most recent 3
|
||||
Layer 2 (auto_compact) — LLM summarises and compresses when token count exceeds threshold, saves transcript
|
||||
Layer 3 (compact tool) — model explicitly calls the compact tool to trigger compression
|
||||
Five-layer context management:
|
||||
Layer 1 (microcompact) — silently prunes old tool results each iteration
|
||||
Layer 2 (context_collapse) — folds long text blocks without LLM call (zero cost)
|
||||
Layer 3 (auto_compact) — LLM structured summary with token-budget tail protection
|
||||
Layer 4 (compact tool) — model explicitly calls the compact tool to trigger L3
|
||||
Layer 5 (iterative update) — Nth compression updates previous summary instead of starting fresh
|
||||
|
||||
Tool execution:
|
||||
- Read/write batching: consecutive readonly tools run in parallel via threads
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import concurrent.futures
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
@@ -28,6 +34,16 @@ TOKEN_THRESHOLD = int(os.getenv("TOKEN_THRESHOLD", "40000"))
|
||||
KEEP_RECENT = 3
|
||||
TOOL_RESULT_LIMIT = 10_000
|
||||
|
||||
# Layer 2: Context collapse thresholds
|
||||
COLLAPSE_THRESHOLD = int(TOKEN_THRESHOLD * 0.7)
|
||||
COLLAPSE_PRESERVE_RECENT = 6
|
||||
COLLAPSE_TEXT_MIN = 2400
|
||||
COLLAPSE_HEAD = 900
|
||||
COLLAPSE_TAIL = 500
|
||||
|
||||
# Layer 3: Token-budget tail protection
|
||||
TAIL_TOKEN_BUDGET = 20_000
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@@ -58,9 +74,192 @@ def _microcompact(messages: list) -> None:
|
||||
msg["content"] = "[cleared]"
|
||||
|
||||
|
||||
def _context_collapse(messages: list) -> None:
|
||||
"""Layer 2: fold long text blocks in older messages without LLM call.
|
||||
|
||||
Preserves head + tail of large text, collapses the middle.
|
||||
Zero API cost — pure string operation.
|
||||
|
||||
Args:
|
||||
messages: Message list (mutated in place).
|
||||
"""
|
||||
if len(messages) <= COLLAPSE_PRESERVE_RECENT + 1:
|
||||
return
|
||||
for msg in messages[1:-COLLAPSE_PRESERVE_RECENT]:
|
||||
content = msg.get("content")
|
||||
if not isinstance(content, str) or len(content) <= COLLAPSE_TEXT_MIN:
|
||||
continue
|
||||
if content == "[cleared]":
|
||||
continue
|
||||
head = content[:COLLAPSE_HEAD]
|
||||
tail = content[-COLLAPSE_TAIL:]
|
||||
trimmed = len(content) - COLLAPSE_HEAD - COLLAPSE_TAIL
|
||||
msg["content"] = f"{head}\n\n...[{trimmed} chars collapsed]...\n\n{tail}"
|
||||
|
||||
|
||||
def _fix_tool_pairs(messages: list) -> None:
|
||||
"""Repair orphaned tool_call / tool_result pairs after compression.
|
||||
|
||||
Two fixes:
|
||||
1. Remove tool results whose matching tool_call was compressed away.
|
||||
2. Insert stub results for tool_calls whose results were compressed away.
|
||||
|
||||
Args:
|
||||
messages: Message list (mutated in place).
|
||||
"""
|
||||
# Collect all tool_call IDs from assistant messages
|
||||
call_ids: set[str] = set()
|
||||
for msg in messages:
|
||||
if msg.get("role") == "assistant":
|
||||
for tc in msg.get("tool_calls", []):
|
||||
tc_id = tc.get("id", "")
|
||||
if tc_id:
|
||||
call_ids.add(tc_id)
|
||||
|
||||
# Remove orphaned tool results
|
||||
i = 0
|
||||
while i < len(messages):
|
||||
msg = messages[i]
|
||||
if msg.get("role") == "tool" and msg.get("tool_call_id") not in call_ids:
|
||||
messages.pop(i)
|
||||
else:
|
||||
i += 1
|
||||
|
||||
# Collect existing result IDs
|
||||
result_ids: set[str] = set()
|
||||
for msg in messages:
|
||||
if msg.get("role") == "tool":
|
||||
tcid = msg.get("tool_call_id", "")
|
||||
if tcid:
|
||||
result_ids.add(tcid)
|
||||
|
||||
# Insert stub results for orphaned tool_calls
|
||||
inserts: list[tuple[int, dict]] = []
|
||||
for idx, msg in enumerate(messages):
|
||||
if msg.get("role") != "assistant":
|
||||
continue
|
||||
for tc in msg.get("tool_calls", []):
|
||||
tc_id = tc.get("id", "")
|
||||
if tc_id and tc_id not in result_ids:
|
||||
stub = {
|
||||
"role": "tool",
|
||||
"tool_call_id": tc_id,
|
||||
"name": tc.get("function", {}).get("name", "unknown"),
|
||||
"content": "[Result from earlier context — see summary above]",
|
||||
}
|
||||
inserts.append((idx + 1, stub))
|
||||
result_ids.add(tc_id)
|
||||
|
||||
for pos, stub in reversed(inserts):
|
||||
messages.insert(pos, stub)
|
||||
|
||||
|
||||
# -- Structured summary templates ------------------------------------------
|
||||
|
||||
_STRUCTURED_SUMMARY_PROMPT = """\
|
||||
Summarize this conversation for handoff to a fresh context window.
|
||||
This summary is the ONLY context available — omitted information is lost.
|
||||
|
||||
Use EXACTLY this structure:
|
||||
|
||||
## Goal
|
||||
What the user is trying to accomplish.
|
||||
|
||||
## Constraints & Preferences
|
||||
User-stated requirements: risk tolerance, strategy parameters, asset preferences.
|
||||
|
||||
## Progress
|
||||
### Done
|
||||
- Completed steps with key results and specific numbers.
|
||||
### In Progress
|
||||
- Current work when compression triggered.
|
||||
|
||||
## Key Decisions
|
||||
Choices made and rationale.
|
||||
|
||||
## Resolved Questions
|
||||
Questions already answered — do NOT re-answer these.
|
||||
|
||||
## Pending User Asks
|
||||
Unfinished requests still needing action.
|
||||
|
||||
## Relevant Files
|
||||
File paths, run_dir, signal engines, artifact locations.
|
||||
|
||||
## Remaining Work
|
||||
What still needs to be done (background reference, NOT active instructions).
|
||||
|
||||
## Critical Context
|
||||
Specific numbers, parameters, error messages, configuration values.
|
||||
|
||||
## Tools & Patterns
|
||||
Which tools worked, what failed, effective approaches.
|
||||
|
||||
IMPORTANT: This is a handoff — background reference, NOT active instructions.
|
||||
Preserve ALL specific numbers, file paths, and parameter values.
|
||||
{focus_section}
|
||||
Conversation to summarize:
|
||||
"""
|
||||
|
||||
_FOCUS_SECTION = """
|
||||
FOCUS TOPIC: {topic}
|
||||
Allocate 60-70% of the summary budget to content related to this topic.
|
||||
Aggressively compress unrelated content to make room.
|
||||
"""
|
||||
|
||||
_ITERATIVE_UPDATE_PROMPT = """\
|
||||
Update the existing summary with new conversation turns.
|
||||
|
||||
PREVIOUS SUMMARY:
|
||||
{previous_summary}
|
||||
|
||||
NEW TURNS TO INCORPORATE:
|
||||
{new_turns}
|
||||
|
||||
Rules:
|
||||
- PRESERVE all existing information from the previous summary.
|
||||
- ADD new progress, decisions, and findings.
|
||||
- Move "In Progress" items to "Done" when completed.
|
||||
- Move answered questions to "Resolved Questions".
|
||||
- Keep the same section structure.
|
||||
- Do NOT drop any critical context from the previous summary.
|
||||
{focus_section}"""
|
||||
|
||||
|
||||
def _is_tool_success(result: str) -> bool:
|
||||
"""Return True if the tool result does not contain an error."""
|
||||
return '"error"' not in result[:200]
|
||||
"""Return True if the tool result does not look like an error response."""
|
||||
try:
|
||||
data = json.loads(result)
|
||||
if isinstance(data, dict) and data.get("status") == "error":
|
||||
return False
|
||||
except (json.JSONDecodeError, TypeError):
|
||||
pass
|
||||
return True
|
||||
|
||||
|
||||
def _normalize_tool_run_dir(args: dict[str, Any], memory_run_dir: str | None) -> dict[str, Any]:
|
||||
"""Normalize ``run_dir`` in tool args to an absolute path when possible.
|
||||
|
||||
If the model supplies a relative ``run_dir`` (for example ``"."`` or
|
||||
``"risk_parity_run"``), resolve it against the active run directory.
|
||||
"""
|
||||
normalized = dict(args)
|
||||
if not memory_run_dir:
|
||||
return normalized
|
||||
|
||||
if "run_dir" not in normalized:
|
||||
normalized["run_dir"] = memory_run_dir
|
||||
return normalized
|
||||
|
||||
run_dir_value = str(normalized["run_dir"]).strip()
|
||||
if not run_dir_value:
|
||||
normalized["run_dir"] = memory_run_dir
|
||||
return normalized
|
||||
|
||||
candidate = Path(run_dir_value)
|
||||
if not candidate.is_absolute():
|
||||
normalized["run_dir"] = str((Path(memory_run_dir) / candidate).resolve())
|
||||
return normalized
|
||||
|
||||
|
||||
class AgentLoop:
|
||||
@@ -80,6 +279,7 @@ class AgentLoop:
|
||||
memory: Optional[WorkspaceMemory] = None,
|
||||
event_callback: Optional[Callable[[str, Dict[str, Any]], None]] = None,
|
||||
max_iterations: int = 50,
|
||||
persistent_memory: Optional[Any] = None,
|
||||
) -> None:
|
||||
"""Initialize AgentLoop.
|
||||
|
||||
@@ -89,6 +289,7 @@ class AgentLoop:
|
||||
memory: Workspace memory (created fresh if not provided).
|
||||
event_callback: Event callback (event_type, data).
|
||||
max_iterations: Maximum number of loop iterations.
|
||||
persistent_memory: PersistentMemory for cross-session recall.
|
||||
"""
|
||||
self.registry = registry
|
||||
self.llm = llm
|
||||
@@ -97,6 +298,8 @@ class AgentLoop:
|
||||
self.max_iterations = max_iterations
|
||||
self._called_ok: set[str] = set()
|
||||
self._cancelled: bool = False
|
||||
self._previous_summary: str = ""
|
||||
self._persistent_memory = persistent_memory
|
||||
|
||||
def cancel(self) -> None:
|
||||
"""Cancel the current loop.
|
||||
@@ -116,6 +319,11 @@ class AgentLoop:
|
||||
Returns:
|
||||
Execution result dict.
|
||||
"""
|
||||
# Reset per-run state (safe for reuse across multiple run() calls)
|
||||
self._cancelled = False
|
||||
self._called_ok = set()
|
||||
self._previous_summary = ""
|
||||
|
||||
state_store = RunStateStore()
|
||||
RUNS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
@@ -127,7 +335,8 @@ class AgentLoop:
|
||||
|
||||
state_store.save_request(run_dir, user_message, {"session_id": session_id})
|
||||
|
||||
context = ContextBuilder(self.registry, self.memory)
|
||||
context = ContextBuilder(self.registry, self.memory,
|
||||
persistent_memory=self._persistent_memory)
|
||||
messages = context.build_messages(user_message, history)
|
||||
react_trace: List[Dict[str, Any]] = []
|
||||
|
||||
@@ -157,8 +366,13 @@ class AgentLoop:
|
||||
# Layer 1: microcompact (every iteration)
|
||||
_microcompact(messages)
|
||||
|
||||
# Layer 2: auto_compact (token threshold exceeded)
|
||||
# Layer 2: context collapse (fold long text, zero API cost)
|
||||
tokens = estimate_tokens(messages)
|
||||
if tokens > COLLAPSE_THRESHOLD:
|
||||
_context_collapse(messages)
|
||||
tokens = estimate_tokens(messages)
|
||||
|
||||
# Layer 3: auto_compact (token threshold exceeded)
|
||||
if tokens > TOKEN_THRESHOLD:
|
||||
logger.info(f"Auto compact triggered: {tokens} tokens > {TOKEN_THRESHOLD}")
|
||||
self._auto_compact(messages, run_dir, trace)
|
||||
@@ -189,58 +403,23 @@ class AgentLoop:
|
||||
react_trace.append({"type": "answer", "content": final_content[:500]})
|
||||
break
|
||||
|
||||
messages.append(context.format_assistant_tool_calls(response.tool_calls, content=response.content))
|
||||
messages.append(
|
||||
context.format_assistant_tool_calls(
|
||||
response.tool_calls,
|
||||
content=response.content,
|
||||
reasoning_content=response.reasoning_content or thinking_text or None,
|
||||
)
|
||||
)
|
||||
|
||||
compact_requested = False
|
||||
|
||||
for tc in response.tool_calls:
|
||||
tool_def = self.registry.get(tc.name)
|
||||
|
||||
# Layer 3: compact tool — mark then defer execution
|
||||
if tc.name == "compact":
|
||||
compact_requested = True
|
||||
messages.append(context.format_tool_result(tc.id, "compact", '{"status":"ok","message":"Compressing..."}'))
|
||||
trace.write({"type": "compact_requested", "iter": iteration})
|
||||
continue
|
||||
|
||||
is_repeatable = tool_def.repeatable if tool_def else False
|
||||
if tc.name in self._called_ok and not is_repeatable:
|
||||
logger.warning(f"Blocked duplicate call: {tc.name} (already succeeded)")
|
||||
skip_msg = json.dumps({"skipped": True, "reason": f"{tc.name} already completed successfully. Use the previous result."})
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, skip_msg))
|
||||
trace.write({"type": "tool_skipped", "iter": iteration, "tool": tc.name})
|
||||
react_trace.append({"type": "tool_skipped", "tool": tc.name})
|
||||
continue
|
||||
|
||||
self._emit("tool_call", {"tool": tc.name, "arguments": {k: str(v)[:200] for k, v in tc.arguments.items()}, "iter": iteration})
|
||||
trace.write({"type": "tool_call", "iter": iteration, "tool": tc.name, "args": {k: str(v)[:200] for k, v in tc.arguments.items()}})
|
||||
logger.info(f"Tool call: {tc.name}({list(tc.arguments.keys())})")
|
||||
|
||||
if "run_dir" not in tc.arguments and self.memory.run_dir:
|
||||
tc.arguments["run_dir"] = self.memory.run_dir
|
||||
|
||||
t0 = _time.perf_counter()
|
||||
result = self.registry.execute(tc.name, tc.arguments)
|
||||
elapsed_ms = int((_time.perf_counter() - t0) * 1000)
|
||||
|
||||
self._update_memory(tc.name, result, state_store, run_dir)
|
||||
|
||||
if _is_tool_success(result):
|
||||
self._called_ok.add(tc.name)
|
||||
|
||||
status = "ok" if _is_tool_success(result) else "error"
|
||||
truncated = result[:TOOL_RESULT_LIMIT]
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, truncated))
|
||||
|
||||
trace.write({"type": "tool_result", "iter": iteration, "tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
react_trace.append({"type": "tool_call", "tool": tc.name, "result_preview": result[:200]})
|
||||
|
||||
self._emit("tool_result", {"tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
# Execute tools with read/write batching
|
||||
compact_requested, focus_topic = self._process_tool_calls(
|
||||
response.tool_calls, context, messages, trace, react_trace, iteration,
|
||||
)
|
||||
|
||||
# Layer 3: compress after all tools have executed
|
||||
if compact_requested:
|
||||
logger.info("Manual compact triggered by model")
|
||||
self._auto_compact(messages, run_dir, trace)
|
||||
self._auto_compact(messages, run_dir, trace, focus_topic=focus_topic)
|
||||
|
||||
except Exception as exc:
|
||||
logger.exception(f"AgentLoop error: {exc}")
|
||||
@@ -278,47 +457,323 @@ class AgentLoop:
|
||||
"react_trace": react_trace,
|
||||
}
|
||||
|
||||
def _auto_compact(self, messages: list, run_dir: Path, trace: TraceWriter) -> None:
|
||||
"""Layer 2/3: LLM summarise-and-compress; saves transcript before compressing.
|
||||
# -- Tool execution with read/write batching --------------------------------
|
||||
|
||||
def _process_tool_calls(
|
||||
self,
|
||||
tool_calls: list,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> tuple[bool, str]:
|
||||
"""Pre-process tool calls: handle compact, filter duplicates, batch execute.
|
||||
|
||||
Args:
|
||||
tool_calls: Raw tool calls from LLM response.
|
||||
context: ContextBuilder for formatting messages.
|
||||
messages: Conversation messages (appended in place).
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration number.
|
||||
|
||||
Returns:
|
||||
Tuple of (compact_requested, focus_topic).
|
||||
"""
|
||||
compact_requested = False
|
||||
focus_topic = ""
|
||||
to_execute = []
|
||||
|
||||
for tc in tool_calls:
|
||||
# Layer 4: compact tool — mark then defer execution
|
||||
if tc.name == "compact":
|
||||
compact_requested = True
|
||||
focus_topic = tc.arguments.get("focus_topic", "")
|
||||
messages.append(context.format_tool_result(tc.id, "compact", '{"status":"ok","message":"Compressing..."}'))
|
||||
trace.write({"type": "compact_requested", "iter": iteration})
|
||||
continue
|
||||
|
||||
tool_def = self.registry.get(tc.name)
|
||||
is_repeatable = tool_def.repeatable if tool_def else False
|
||||
if tc.name in self._called_ok and not is_repeatable:
|
||||
logger.warning(f"Blocked duplicate call: {tc.name} (already succeeded)")
|
||||
skip_msg = json.dumps({"skipped": True, "reason": f"{tc.name} already completed successfully. Use the previous result."})
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, skip_msg))
|
||||
trace.write({"type": "tool_skipped", "iter": iteration, "tool": tc.name})
|
||||
react_trace.append({"type": "tool_skipped", "tool": tc.name})
|
||||
continue
|
||||
|
||||
to_execute.append(tc)
|
||||
|
||||
if not to_execute:
|
||||
return compact_requested, focus_topic
|
||||
|
||||
# Batch execute: consecutive readonly → parallel, write → serial
|
||||
if len(to_execute) == 1:
|
||||
self._execute_single(to_execute[0], context, messages, trace, react_trace, iteration)
|
||||
else:
|
||||
self._batch_execute(to_execute, context, messages, trace, react_trace, iteration)
|
||||
|
||||
return compact_requested, focus_topic
|
||||
|
||||
def _batch_execute(
|
||||
self,
|
||||
tool_calls: list,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Execute tools with read/write batching.
|
||||
|
||||
Consecutive readonly tools run in parallel via ThreadPoolExecutor.
|
||||
Write tools run serially between readonly batches.
|
||||
|
||||
Args:
|
||||
tool_calls: Tool calls to execute.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
# Split into batches: consecutive readonly → parallel, write → serial
|
||||
batches: list[tuple[str, list]] = []
|
||||
current_ro: list = []
|
||||
|
||||
for tc in tool_calls:
|
||||
tool_def = self.registry.get(tc.name)
|
||||
if tool_def and tool_def.is_readonly:
|
||||
current_ro.append(tc)
|
||||
else:
|
||||
if current_ro:
|
||||
batches.append(("parallel", current_ro))
|
||||
current_ro = []
|
||||
batches.append(("serial", [tc]))
|
||||
if current_ro:
|
||||
batches.append(("parallel", current_ro))
|
||||
|
||||
for mode, batch in batches:
|
||||
if mode == "parallel" and len(batch) > 1:
|
||||
self._execute_parallel(batch, context, messages, trace, react_trace, iteration)
|
||||
else:
|
||||
for tc in batch:
|
||||
self._execute_single(tc, context, messages, trace, react_trace, iteration)
|
||||
|
||||
def _execute_parallel(
|
||||
self,
|
||||
tool_calls: list,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Execute readonly tools in parallel using threads.
|
||||
|
||||
Args:
|
||||
tool_calls: Readonly tool calls to execute in parallel.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
# Prepare args + emit events
|
||||
runnable: list[tuple] = []
|
||||
for tc in tool_calls:
|
||||
args = _normalize_tool_run_dir(tc.arguments, self.memory.run_dir)
|
||||
self._emit("tool_call", {"tool": tc.name, "arguments": {k: str(v)[:200] for k, v in args.items()}, "iter": iteration})
|
||||
trace.write({"type": "tool_call", "iter": iteration, "tool": tc.name, "args": {k: str(v)[:200] for k, v in args.items()}})
|
||||
runnable.append((tc, args))
|
||||
|
||||
# Execute in parallel
|
||||
def _run(tc_args: tuple) -> tuple:
|
||||
tc, args = tc_args
|
||||
t0 = _time.perf_counter()
|
||||
result = self.registry.execute(tc.name, args)
|
||||
elapsed_ms = int((_time.perf_counter() - t0) * 1000)
|
||||
return tc, result, elapsed_ms
|
||||
|
||||
with concurrent.futures.ThreadPoolExecutor(max_workers=min(len(runnable), 8)) as pool:
|
||||
futures = [pool.submit(_run, item) for item in runnable]
|
||||
results = []
|
||||
for i, f in enumerate(futures):
|
||||
try:
|
||||
results.append(f.result())
|
||||
except Exception as exc:
|
||||
tc = runnable[i][0]
|
||||
results.append((tc, json.dumps({"status": "error", "error": str(exc)}), 0))
|
||||
|
||||
# Process results in order
|
||||
for tc, result, elapsed_ms in results:
|
||||
self._finalize_tool_result(tc, result, elapsed_ms, context, messages, trace, react_trace, iteration)
|
||||
|
||||
def _execute_single(
|
||||
self,
|
||||
tc: Any,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Execute a single tool call.
|
||||
|
||||
Args:
|
||||
tc: Tool call object.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
args = _normalize_tool_run_dir(tc.arguments, self.memory.run_dir)
|
||||
|
||||
self._emit("tool_call", {"tool": tc.name, "arguments": {k: str(v)[:200] for k, v in args.items()}, "iter": iteration})
|
||||
trace.write({"type": "tool_call", "iter": iteration, "tool": tc.name, "args": {k: str(v)[:200] for k, v in args.items()}})
|
||||
logger.info(f"Tool call: {tc.name}({list(args.keys())})")
|
||||
|
||||
t0 = _time.perf_counter()
|
||||
result = self.registry.execute(tc.name, args)
|
||||
elapsed_ms = int((_time.perf_counter() - t0) * 1000)
|
||||
|
||||
self._finalize_tool_result(tc, result, elapsed_ms, context, messages, trace, react_trace, iteration)
|
||||
|
||||
def _finalize_tool_result(
|
||||
self,
|
||||
tc: Any,
|
||||
result: str,
|
||||
elapsed_ms: int,
|
||||
context: ContextBuilder,
|
||||
messages: list,
|
||||
trace: TraceWriter,
|
||||
react_trace: list,
|
||||
iteration: int,
|
||||
) -> None:
|
||||
"""Record a tool result: update memory, append message, write trace, emit event.
|
||||
|
||||
Args:
|
||||
tc: Tool call object.
|
||||
result: Raw tool result string.
|
||||
elapsed_ms: Execution time in milliseconds.
|
||||
context: ContextBuilder.
|
||||
messages: Conversation messages.
|
||||
trace: TraceWriter.
|
||||
react_trace: React trace list.
|
||||
iteration: Current iteration.
|
||||
"""
|
||||
self._update_memory(tc.name)
|
||||
|
||||
success = _is_tool_success(result)
|
||||
if success:
|
||||
self._called_ok.add(tc.name)
|
||||
|
||||
status = "ok" if success else "error"
|
||||
truncated = result[:TOOL_RESULT_LIMIT]
|
||||
messages.append(context.format_tool_result(tc.id, tc.name, truncated))
|
||||
|
||||
trace.write({"type": "tool_result", "iter": iteration, "tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
react_trace.append({"type": "tool_call", "tool": tc.name, "result_preview": result[:200]})
|
||||
self._emit("tool_result", {"tool": tc.name, "status": status, "elapsed_ms": elapsed_ms, "preview": result[:200]})
|
||||
|
||||
# -- Context compression ---------------------------------------------------
|
||||
|
||||
def _auto_compact(self, messages: list, run_dir: Path, trace: TraceWriter,
|
||||
focus_topic: str = "") -> None:
|
||||
"""Layer 3/4/5: structured LLM summary with token-budget tail protection.
|
||||
|
||||
Upgrades over the original:
|
||||
- Token-budget tail: keeps ~20K tokens of recent messages (not a fixed count).
|
||||
- Structured summary template: preserves goal, progress, decisions, files, etc.
|
||||
- Iterative update: Nth compression updates previous summary, zero info decay.
|
||||
- Tool pair fix: repairs orphaned tool_call/tool_result after compression.
|
||||
- Focus-topic: optionally prioritize specific topic in summary.
|
||||
|
||||
Args:
|
||||
messages: Message list (replaced in place).
|
||||
run_dir: Run directory.
|
||||
trace: TraceWriter.
|
||||
focus_topic: Optional topic to prioritize in the summary.
|
||||
"""
|
||||
# Save full transcript (timestamped, one file per compression)
|
||||
# Save full transcript before compressing
|
||||
transcript_path = run_dir / f"transcript_{int(_time.time())}.jsonl"
|
||||
with open(transcript_path, "w", encoding="utf-8") as f:
|
||||
for msg in messages:
|
||||
f.write(json.dumps(msg, default=str, ensure_ascii=False) + "\n")
|
||||
|
||||
# LLM summary (no tools, plain text)
|
||||
conv_text = json.dumps(messages[1:], default=str, ensure_ascii=False)[:80000]
|
||||
summary_resp = self.llm.chat([
|
||||
{"role": "user", "content": (
|
||||
"Summarize this conversation for continuity. Include: "
|
||||
"1) What was accomplished, 2) Current state, 3) Key decisions made. "
|
||||
"Be concise but preserve critical details.\n\n" + conv_text
|
||||
)},
|
||||
])
|
||||
system_msg = messages[0]
|
||||
body = messages[1:]
|
||||
|
||||
# Token-budget tail: walk backward to find how many recent messages to preserve
|
||||
accumulated = 0
|
||||
cut_idx = len(body)
|
||||
for i in range(len(body) - 1, -1, -1):
|
||||
content = body[i].get("content", "")
|
||||
msg_tokens = (len(str(content)) // 4) + 10
|
||||
if accumulated + msg_tokens > TAIL_TOKEN_BUDGET:
|
||||
cut_idx = i + 1
|
||||
break
|
||||
accumulated += msg_tokens
|
||||
cut_idx = i
|
||||
|
||||
# Don't split in the middle of a tool_call/tool_result pair
|
||||
while 0 < cut_idx < len(body) and body[cut_idx].get("role") == "tool":
|
||||
cut_idx += 1
|
||||
|
||||
head = body[:cut_idx]
|
||||
tail = body[cut_idx:]
|
||||
|
||||
if not head:
|
||||
# All body fits in tail budget — force a split to avoid infinite loop
|
||||
if len(body) > 2:
|
||||
cut_idx = max(1, len(body) // 2)
|
||||
head = body[:cut_idx]
|
||||
tail = body[cut_idx:]
|
||||
else:
|
||||
logger.warning("Auto compact: nothing to compress (body too small)")
|
||||
return
|
||||
|
||||
# Build focus section
|
||||
focus_section = _FOCUS_SECTION.format(topic=focus_topic) if focus_topic else ""
|
||||
|
||||
# Build summary prompt (structured template or iterative update)
|
||||
conv_text = json.dumps(head, default=str, ensure_ascii=False)[:80000]
|
||||
|
||||
if self._previous_summary:
|
||||
prompt = _ITERATIVE_UPDATE_PROMPT.format(
|
||||
previous_summary=self._previous_summary,
|
||||
new_turns=conv_text,
|
||||
focus_section=focus_section,
|
||||
)
|
||||
else:
|
||||
prompt = _STRUCTURED_SUMMARY_PROMPT.format(focus_section=focus_section) + conv_text
|
||||
|
||||
summary_resp = self.llm.chat([{"role": "user", "content": prompt}])
|
||||
summary = summary_resp.content or ""
|
||||
self._previous_summary = summary
|
||||
|
||||
tokens_before = estimate_tokens(messages)
|
||||
trace.write({"type": "compact", "tokens_before": tokens_before, "summary": summary[:500]})
|
||||
trace.write({"type": "compact", "tokens_before": tokens_before, "summary": summary[:500],
|
||||
"focus_topic": focus_topic or "(none)"})
|
||||
self._emit("compact", {"tokens_before": tokens_before, "summary": summary[:200]})
|
||||
|
||||
# Replace: keep system prompt + inject compressed summary + restore identity
|
||||
system_msg = messages[0]
|
||||
# Reconstruct: system + summary + acknowledge + preserved tail
|
||||
state_summary = self.memory.to_summary()
|
||||
compressed = f"[Conversation compressed. Transcript: {transcript_path}]\n\n{summary}"
|
||||
compressed = f"[Conversation compressed — handoff summary. Transcript: {transcript_path}]\n\n{summary}"
|
||||
if state_summary and state_summary != "(empty state)":
|
||||
compressed += f"\n\nCurrent agent state:\n{state_summary}"
|
||||
|
||||
messages.clear()
|
||||
messages.extend([
|
||||
system_msg,
|
||||
{"role": "user", "content": compressed},
|
||||
{"role": "assistant", "content": "Understood. I have the context from the summary. Continuing."},
|
||||
])
|
||||
messages.append(system_msg)
|
||||
messages.append({"role": "user", "content": compressed})
|
||||
messages.append({"role": "assistant", "content": "Understood. Continuing from the summary."})
|
||||
messages.extend(tail)
|
||||
|
||||
# Fix orphaned tool pairs in the reconstructed message list
|
||||
_fix_tool_pairs(messages)
|
||||
|
||||
def _emit(self, event_type: str, data: Dict[str, Any]) -> None:
|
||||
"""Fire an event via the callback."""
|
||||
@@ -328,12 +783,6 @@ class AgentLoop:
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _update_memory(self, tool_name: str, result: str, state_store: RunStateStore, run_dir: Path) -> None:
|
||||
"""Update memory and persist tool result."""
|
||||
def _update_memory(self, tool_name: str) -> None:
|
||||
"""Update workspace memory counters after tool execution."""
|
||||
self.memory.increment(tool_name)
|
||||
try:
|
||||
data = json.loads(result)
|
||||
if isinstance(data, dict):
|
||||
state_store.persist_tool_result(tool_name, data, run_dir)
|
||||
except (json.JSONDecodeError, TypeError):
|
||||
pass
|
||||
+12
-85
@@ -1,7 +1,7 @@
|
||||
"""Workspace memory: shared state across tool calls.
|
||||
"""Workspace memory: shared state across tool calls within a single run.
|
||||
|
||||
WorkspaceMemory passes intermediate results between tools during an agent run.
|
||||
Generic KV store + counters; no tool-specific fields.
|
||||
Lightweight runtime state — survives within one AgentLoop.run() invocation only.
|
||||
Cross-session persistence is handled by src.memory.persistent.PersistentMemory.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
@@ -12,53 +12,21 @@ from typing import Any, Dict, Optional
|
||||
|
||||
@dataclass
|
||||
class WorkspaceMemory:
|
||||
"""Shared workspace state between tools.
|
||||
"""Shared workspace state between tools during a single agent run.
|
||||
|
||||
Attributes:
|
||||
run_dir: Current run directory.
|
||||
store: Generic result store (tool memory_key -> JSON string).
|
||||
run_dir: Current run directory path.
|
||||
counters: Tool invocation counters.
|
||||
extra: Generic KV store for derived values passed between tools.
|
||||
"""
|
||||
|
||||
run_dir: Optional[str] = None
|
||||
store: Dict[str, str] = field(default_factory=dict)
|
||||
counters: Dict[str, int] = field(default_factory=dict)
|
||||
extra: Dict[str, Any] = field(default_factory=dict)
|
||||
|
||||
def reset(self) -> None:
|
||||
"""Reset all state."""
|
||||
self.run_dir = None
|
||||
self.store.clear()
|
||||
self.counters.clear()
|
||||
self.extra.clear()
|
||||
|
||||
def set_result(self, key: str, value: str) -> None:
|
||||
"""Store a tool result.
|
||||
|
||||
Args:
|
||||
key: Memory key (e.g. "plan_output").
|
||||
value: JSON string.
|
||||
"""
|
||||
self.store[key] = value
|
||||
|
||||
def get_result(self, key: str, default: Optional[str] = None) -> Optional[str]:
|
||||
"""Retrieve a tool result.
|
||||
|
||||
Args:
|
||||
key: Memory key.
|
||||
default: Default value.
|
||||
|
||||
Returns:
|
||||
JSON string or default.
|
||||
"""
|
||||
return self.store.get(key, default)
|
||||
|
||||
def increment(self, key: str) -> int:
|
||||
"""Increment a counter and return the new value.
|
||||
|
||||
Args:
|
||||
key: Counter key.
|
||||
key: Counter key (typically tool name).
|
||||
|
||||
Returns:
|
||||
Updated counter value.
|
||||
@@ -66,60 +34,19 @@ class WorkspaceMemory:
|
||||
self.counters[key] = self.counters.get(key, 0) + 1
|
||||
return self.counters[key]
|
||||
|
||||
def set_extra(self, key: str, value: Any) -> None:
|
||||
"""Set an extra KV entry.
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
value: Value.
|
||||
"""
|
||||
self.extra[key] = value
|
||||
|
||||
def get_extra(self, key: str, default: Any = None) -> Any:
|
||||
"""Get an extra KV entry.
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
default: Default value.
|
||||
|
||||
Returns:
|
||||
Stored value or default.
|
||||
"""
|
||||
return self.extra.get(key, default)
|
||||
|
||||
def set(self, key: str, value: Any) -> None:
|
||||
"""Set a KV entry (alias for set_extra).
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
value: Value.
|
||||
"""
|
||||
self.extra[key] = value
|
||||
|
||||
def get(self, key: str, default: Any = None) -> Any:
|
||||
"""Get a KV entry (alias for get_extra).
|
||||
|
||||
Args:
|
||||
key: Key name.
|
||||
default: Default value.
|
||||
|
||||
Returns:
|
||||
Stored value or default.
|
||||
"""
|
||||
return self.extra.get(key, default)
|
||||
|
||||
def to_summary(self) -> str:
|
||||
"""Generate a state summary for the LLM indicating completed steps.
|
||||
"""Generate a state summary for the LLM.
|
||||
|
||||
Includes run_dir and tool counters.
|
||||
This summary survives context compression and helps the LLM
|
||||
remember what it was working on.
|
||||
|
||||
Returns:
|
||||
State summary text.
|
||||
"""
|
||||
lines = []
|
||||
lines: list[str] = []
|
||||
if self.run_dir:
|
||||
lines.append(f"- run_dir: {self.run_dir}")
|
||||
if self.store:
|
||||
completed = list(self.store.keys())
|
||||
lines.append(f"- completed: {', '.join(completed)}")
|
||||
if self.counters:
|
||||
counter_parts = [f"{k}={v}" for k, v in self.counters.items()]
|
||||
lines.append(f"- counters: {', '.join(counter_parts)}")
|
||||
|
||||
+36
-42
@@ -53,36 +53,7 @@ class Skill:
|
||||
return None
|
||||
|
||||
|
||||
def _parse_frontmatter(text: str) -> tuple[Dict[str, Any], str]:
|
||||
"""Parse YAML frontmatter and body.
|
||||
|
||||
Args:
|
||||
text: Markdown text.
|
||||
|
||||
Returns:
|
||||
Tuple of (metadata dict, body text).
|
||||
"""
|
||||
match = re.match(r"^---\s*\n(.*?)\n---\s*\n(.*)", text, re.DOTALL)
|
||||
if not match:
|
||||
return {}, text.strip()
|
||||
|
||||
meta: Dict[str, Any] = {}
|
||||
for line in match.group(1).strip().split("\n"):
|
||||
line = line.strip()
|
||||
if ":" not in line:
|
||||
continue
|
||||
key, value = line.split(":", 1)
|
||||
key = key.strip()
|
||||
value = value.strip()
|
||||
if value.startswith("[") and value.endswith("]"):
|
||||
items = [item.strip().strip("'\"") for item in value[1:-1].split(",")]
|
||||
meta[key] = [i for i in items if i]
|
||||
elif value.lower() in ("true", "false"):
|
||||
meta[key] = value.lower() == "true"
|
||||
else:
|
||||
meta[key] = value
|
||||
|
||||
return meta, match.group(2).strip()
|
||||
from src.agent.frontmatter import parse_frontmatter as _parse_frontmatter # shared util
|
||||
|
||||
|
||||
def _load_skill_dir(dir_path: Path) -> Optional[Skill]:
|
||||
@@ -117,32 +88,45 @@ def _load_skill_dir(dir_path: Path) -> Optional[Skill]:
|
||||
)
|
||||
|
||||
|
||||
USER_SKILLS_DIR = Path.home() / ".vibe-trading" / "skills" / "user"
|
||||
|
||||
|
||||
class SkillsLoader:
|
||||
"""Load skills from the skills/ directory.
|
||||
"""Load skills from bundled skills/ directory and user skills directory.
|
||||
|
||||
Attributes:
|
||||
skills: Loaded skill list.
|
||||
skills: Loaded skill list (bundled + user-created).
|
||||
"""
|
||||
|
||||
def __init__(self, skills_dir: Optional[Path] = None) -> None:
|
||||
def __init__(self, skills_dir: Optional[Path] = None,
|
||||
user_skills_dir: Optional[Path] = None) -> None:
|
||||
"""Initialize SkillsLoader.
|
||||
|
||||
Args:
|
||||
skills_dir: Skills directory path; defaults to agent/skills/.
|
||||
skills_dir: Bundled skills directory path; defaults to agent/skills/.
|
||||
user_skills_dir: User-created skills directory; defaults to ~/.vibe-trading/skills/user/.
|
||||
"""
|
||||
self.skills_dir = skills_dir or Path(__file__).resolve().parents[1] / "skills"
|
||||
self._user_skills_dir = user_skills_dir or USER_SKILLS_DIR
|
||||
self.skills: List[Skill] = []
|
||||
self._load()
|
||||
|
||||
def _load(self) -> None:
|
||||
"""Load all skill subdirectories from the skills directory."""
|
||||
if not self.skills_dir.exists():
|
||||
return
|
||||
for path in sorted(self.skills_dir.iterdir()):
|
||||
if path.is_dir() and (path / "SKILL.md").exists():
|
||||
skill = _load_skill_dir(path)
|
||||
if skill:
|
||||
self.skills.append(skill)
|
||||
"""Load all skill subdirectories from user and bundled directories.
|
||||
|
||||
User skills are loaded first so they override bundled skills with the same name
|
||||
(e.g. after patch_skill copies and modifies a bundled skill).
|
||||
"""
|
||||
seen_names: set[str] = set()
|
||||
for directory in (self._user_skills_dir, self.skills_dir):
|
||||
if not directory or not directory.exists():
|
||||
continue
|
||||
for path in sorted(directory.iterdir()):
|
||||
if path.is_dir() and (path / "SKILL.md").exists():
|
||||
skill = _load_skill_dir(path)
|
||||
if skill and skill.name not in seen_names:
|
||||
self.skills.append(skill)
|
||||
seen_names.add(skill.name)
|
||||
|
||||
# Display order for categories (unlisted categories appear at the end).
|
||||
_CATEGORY_ORDER = [
|
||||
@@ -176,6 +160,8 @@ class SkillsLoader:
|
||||
def get_content(self, name: str) -> str:
|
||||
"""Return the full documentation for a skill (used by the load_skill tool).
|
||||
|
||||
Falls back to disk lookup for user skills created mid-session.
|
||||
|
||||
Args:
|
||||
name: Skill name.
|
||||
|
||||
@@ -185,5 +171,13 @@ class SkillsLoader:
|
||||
for skill in self.skills:
|
||||
if skill.name == name:
|
||||
return f'<skill name="{name}">\n{skill.body}\n</skill>'
|
||||
|
||||
# Fallback: check user skills directory on disk (mid-session created skills)
|
||||
if self._user_skills_dir:
|
||||
skill = _load_skill_dir(self._user_skills_dir / name)
|
||||
if skill:
|
||||
self.skills.append(skill)
|
||||
return f'<skill name="{name}">\n{skill.body}\n</skill>'
|
||||
|
||||
available = ", ".join(s.name for s in self.skills)
|
||||
return f"Error: Unknown skill '{name}'. Available: {available}"
|
||||
@@ -3,8 +3,10 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import traceback
|
||||
import logging
|
||||
from abc import ABC, abstractmethod
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
|
||||
@@ -22,6 +24,16 @@ class BaseTool(ABC):
|
||||
description: str = ""
|
||||
parameters: Dict[str, Any] = {}
|
||||
repeatable: bool = False
|
||||
is_readonly: bool = True
|
||||
|
||||
@classmethod
|
||||
def check_available(cls) -> bool:
|
||||
"""Check if this tool's dependencies are met.
|
||||
|
||||
Override in subclasses to check for API keys, packages, etc.
|
||||
Tools that return False are excluded from the registry.
|
||||
"""
|
||||
return True
|
||||
|
||||
@abstractmethod
|
||||
def execute(self, **kwargs: Any) -> str:
|
||||
@@ -65,9 +77,10 @@ class ToolRegistry:
|
||||
try:
|
||||
return tool.execute(**params)
|
||||
except Exception as exc:
|
||||
logger.exception("Tool %s failed", name)
|
||||
return json.dumps({
|
||||
"status": "error", "tool": name,
|
||||
"error": str(exc), "traceback": traceback.format_exc()[-500:],
|
||||
"error": str(exc),
|
||||
}, ensure_ascii=False)
|
||||
|
||||
@property
|
||||
|
||||
@@ -13,7 +13,7 @@ from typing import Any, Dict, Optional
|
||||
from rich.console import Console
|
||||
|
||||
|
||||
console = Console()
|
||||
console = Console(stderr=True)
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -109,19 +109,6 @@ def _expand_artifacts_spec(spec: Dict[str, Any] | None) -> Dict[str, Dict[str, A
|
||||
class Runner:
|
||||
"""Execute entry scripts inside a run directory and collect outputs."""
|
||||
|
||||
_PROXY_ENV_KEYS = (
|
||||
"HTTP_PROXY",
|
||||
"HTTPS_PROXY",
|
||||
"ALL_PROXY",
|
||||
"http_proxy",
|
||||
"https_proxy",
|
||||
"all_proxy",
|
||||
"GIT_HTTP_PROXY",
|
||||
"GIT_HTTPS_PROXY",
|
||||
"git_http_proxy",
|
||||
"git_https_proxy",
|
||||
)
|
||||
|
||||
def __init__(self, timeout: int = 300, artifacts_spec: Optional[Dict[str, Any]] = None) -> None:
|
||||
"""Initialize runner.
|
||||
|
||||
@@ -147,6 +134,7 @@ class Runner:
|
||||
try:
|
||||
probe = subprocess.run(
|
||||
[python_cmd, "-c", "import pandas,numpy; print('ok')"],
|
||||
stdin=subprocess.DEVNULL,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
text=True,
|
||||
@@ -201,13 +189,9 @@ class Runner:
|
||||
existing = env.get("PYTHONPATH", "")
|
||||
env["PYTHONPATH"] = str(pythonpath_extra) + (os.pathsep + existing if existing else "")
|
||||
|
||||
runtime_home = run_dir / ".home"
|
||||
runtime_home.mkdir(parents=True, exist_ok=True)
|
||||
env["HOME"] = str(runtime_home)
|
||||
if os.name == "nt":
|
||||
env["USERPROFILE"] = str(runtime_home)
|
||||
|
||||
# Preserve system proxy settings; data sources (OKX/yfinance) need network access
|
||||
# NOTE: do NOT override HOME/USERPROFILE — data libraries (yfinance, akshare)
|
||||
# cache downloads under ~/; overriding HOME causes full re-download every run.
|
||||
|
||||
return env
|
||||
|
||||
@@ -252,6 +236,7 @@ class Runner:
|
||||
process = subprocess.run(
|
||||
cmd,
|
||||
cwd=str(effective_cwd),
|
||||
stdin=subprocess.DEVNULL,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
text=True,
|
||||
|
||||
+3
-107
@@ -1,19 +1,16 @@
|
||||
"""Run state persistence: lightweight, no dependency on legacy agent types."""
|
||||
"""Run state persistence: creates run directories and records status."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
import json
|
||||
import uuid
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Any, Dict, List, Optional
|
||||
|
||||
import yaml
|
||||
from typing import Any, Dict
|
||||
|
||||
|
||||
class RunStateStore:
|
||||
"""Run state store: records key files such as req/design/code/logs/review."""
|
||||
"""Run state store: manages run directories and their lifecycle status."""
|
||||
|
||||
def create_run_dir(self, workspace: Path) -> Path:
|
||||
"""Create a unique run directory.
|
||||
@@ -48,59 +45,6 @@ class RunStateStore:
|
||||
self._write_json(run_dir / "req.json", payload)
|
||||
return payload
|
||||
|
||||
def save_planner_output(self, run_dir: Path, planner_output: Dict[str, Any]) -> Dict[str, Any]:
|
||||
"""Save planner output.
|
||||
|
||||
Args:
|
||||
run_dir: Run directory.
|
||||
planner_output: Planner output dict.
|
||||
|
||||
Returns:
|
||||
Saved payload.
|
||||
"""
|
||||
self._write_json(run_dir / "planner_output.json", planner_output)
|
||||
return planner_output
|
||||
|
||||
def save_design(self, run_dir: Path, spec: Dict[str, Any], decision: Dict[str, Any]) -> None:
|
||||
"""Save design spec and judge decision.
|
||||
|
||||
Args:
|
||||
run_dir: Run directory.
|
||||
spec: Strategy design spec.
|
||||
decision: Judge decision result.
|
||||
"""
|
||||
self._write_json(run_dir / "design_spec.json", spec)
|
||||
self._write_json(run_dir / "judge_decision.json", decision)
|
||||
|
||||
def save_rag_spec(
|
||||
self,
|
||||
run_dir: Path,
|
||||
selection: Dict[str, Any],
|
||||
spec: Dict[str, Any],
|
||||
*,
|
||||
candidates: Optional[List[Dict[str, Any]]] = None,
|
||||
) -> None:
|
||||
"""Save RAG results.
|
||||
|
||||
Args:
|
||||
run_dir: Run directory.
|
||||
selection: Selected API metadata.
|
||||
spec: Enriched data API spec.
|
||||
candidates: Candidate API list.
|
||||
"""
|
||||
enriched_spec = copy.deepcopy(spec) if spec else {}
|
||||
enriched_spec["_rag_metadata"] = selection
|
||||
spec_yaml = yaml.safe_dump(enriched_spec, allow_unicode=True, sort_keys=False)
|
||||
(run_dir / "data_api_spec.yaml").write_text(spec_yaml, encoding="utf-8")
|
||||
self._write_json(run_dir / "rag_metadata.json", selection)
|
||||
if candidates:
|
||||
candidate_yaml = yaml.safe_dump(
|
||||
{"generated_at": datetime.now().isoformat(), "candidates": candidates},
|
||||
allow_unicode=True,
|
||||
sort_keys=False,
|
||||
)
|
||||
(run_dir / "rag_candidates.yaml").write_text(candidate_yaml, encoding="utf-8")
|
||||
|
||||
def mark_success(self, run_dir: Path) -> None:
|
||||
"""Mark the run as successful.
|
||||
|
||||
@@ -118,54 +62,6 @@ class RunStateStore:
|
||||
"""
|
||||
self._write_json(run_dir / "state.json", {"status": "failed", "reason": reason})
|
||||
|
||||
# -----------------------------------------------------------------------
|
||||
# Generic persistence: extract and save key artifacts by tool name
|
||||
# -----------------------------------------------------------------------
|
||||
|
||||
_PERSIST_MAP: Dict[str, str] = {
|
||||
"plan": "_persist_plan",
|
||||
"search": "_persist_search",
|
||||
"resolve": "_persist_resolve",
|
||||
"design": "_persist_design",
|
||||
}
|
||||
|
||||
def persist_tool_result(self, tool_name: str, result_data: Dict[str, Any], run_dir: Path) -> None:
|
||||
"""Persist key artifacts by tool name.
|
||||
|
||||
Args:
|
||||
tool_name: Tool name.
|
||||
result_data: Parsed tool result dict.
|
||||
run_dir: Run directory.
|
||||
"""
|
||||
method_name = self._PERSIST_MAP.get(tool_name)
|
||||
if method_name:
|
||||
method = getattr(self, method_name, None)
|
||||
if method:
|
||||
try:
|
||||
method(result_data, run_dir)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _persist_plan(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
if data and "error" not in data:
|
||||
self.save_planner_output(run_dir, data)
|
||||
|
||||
def _persist_search(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
if data.get("selections"):
|
||||
sel = data["selections"][0] if data["selections"] else {}
|
||||
spec = data.get("data_api_spec") or {}
|
||||
self.save_rag_spec(run_dir, sel, spec, candidates=data.get("candidates"))
|
||||
|
||||
def _persist_resolve(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
if data and data.get("status") == "ok":
|
||||
self._write_json(run_dir / "data_config.json", data)
|
||||
|
||||
def _persist_design(self, data: Dict[str, Any], run_dir: Path) -> None:
|
||||
spec = data.get("spec") or {}
|
||||
decision = data.get("judge_decision") or {}
|
||||
if spec:
|
||||
self.save_design(run_dir, spec, decision)
|
||||
|
||||
@staticmethod
|
||||
def _write_json(path: Path, data: Any) -> None:
|
||||
path.write_text(json.dumps(data, ensure_ascii=False, indent=2), encoding="utf-8")
|
||||
@@ -0,0 +1 @@
|
||||
"""Persistent cross-session memory system."""
|
||||
@@ -0,0 +1,224 @@
|
||||
"""PersistentMemory: file-based cross-session memory, zero external dependencies.
|
||||
|
||||
Storage layout:
|
||||
~/.vibe-trading/memory/
|
||||
+-- MEMORY.md # Index (< 200 lines)
|
||||
+-- user_prefs.md # Individual memory entries with YAML frontmatter
|
||||
+-- project_btc.md
|
||||
+-- ...
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
|
||||
from src.agent.frontmatter import parse_frontmatter as _parse_frontmatter
|
||||
from typing import List, Optional
|
||||
|
||||
MEMORY_BASE = Path.home() / ".vibe-trading" / "memory"
|
||||
MAX_INDEX_LINES = 200
|
||||
MAX_ENTRY_CHARS = 8000
|
||||
MAX_RESULTS = 5
|
||||
METADATA_WEIGHT = 2.0
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class MemoryEntry:
|
||||
"""A single memory entry on disk.
|
||||
|
||||
Attributes:
|
||||
path: File path.
|
||||
title: Memory title.
|
||||
description: One-line description (used for retrieval scoring).
|
||||
memory_type: Category (user/feedback/project/reference).
|
||||
body: Body text content.
|
||||
modified_at: File modification timestamp.
|
||||
"""
|
||||
|
||||
path: Path
|
||||
title: str
|
||||
description: str
|
||||
memory_type: str
|
||||
body: str
|
||||
modified_at: float
|
||||
|
||||
|
||||
def _tokenize(text: str) -> set[str]:
|
||||
"""Split text into searchable tokens.
|
||||
|
||||
ASCII words >= 3 chars + CJK individual characters.
|
||||
|
||||
Args:
|
||||
text: Input text.
|
||||
|
||||
Returns:
|
||||
Set of tokens.
|
||||
"""
|
||||
ascii_tokens = set(re.findall(r"[a-zA-Z0-9_]{3,}", text.lower()))
|
||||
cjk_tokens = set(re.findall(r"[\u4e00-\u9fff\u3400-\u4dbf]", text))
|
||||
return ascii_tokens | cjk_tokens
|
||||
|
||||
|
||||
class PersistentMemory:
|
||||
"""File-based persistent memory that survives across sessions.
|
||||
|
||||
Design:
|
||||
- Frozen snapshot injected into system prompt at session start (preserves prompt cache).
|
||||
- Disk writes via add()/remove() update files immediately but do NOT change the snapshot.
|
||||
- Next session picks up the updated state.
|
||||
|
||||
Attributes:
|
||||
snapshot: Frozen memory index text for system prompt injection.
|
||||
"""
|
||||
|
||||
def __init__(self, memory_dir: Optional[Path] = None) -> None:
|
||||
"""Initialize PersistentMemory.
|
||||
|
||||
Args:
|
||||
memory_dir: Override memory directory (default: ~/.vibe-trading/memory/).
|
||||
"""
|
||||
self._dir = memory_dir or MEMORY_BASE
|
||||
self._dir.mkdir(parents=True, exist_ok=True)
|
||||
self._index_path = self._dir / "MEMORY.md"
|
||||
self._snapshot: str = ""
|
||||
self._load_snapshot()
|
||||
|
||||
def _load_snapshot(self) -> None:
|
||||
"""Load index as frozen snapshot. Called once at init."""
|
||||
if self._index_path.exists():
|
||||
try:
|
||||
text = self._index_path.read_text(encoding="utf-8")
|
||||
lines = text.split("\n")[:MAX_INDEX_LINES]
|
||||
self._snapshot = "\n".join(lines)
|
||||
except OSError:
|
||||
self._snapshot = ""
|
||||
|
||||
@property
|
||||
def snapshot(self) -> str:
|
||||
"""Frozen memory index for system prompt injection."""
|
||||
return self._snapshot
|
||||
|
||||
def _scan_entries(self) -> List[MemoryEntry]:
|
||||
"""Scan all .md files (except MEMORY.md) and parse frontmatter.
|
||||
|
||||
Returns:
|
||||
List of parsed memory entries.
|
||||
"""
|
||||
entries: List[MemoryEntry] = []
|
||||
for path in sorted(self._dir.glob("*.md")):
|
||||
if path.name == "MEMORY.md":
|
||||
continue
|
||||
try:
|
||||
text = path.read_text(encoding="utf-8")
|
||||
except OSError:
|
||||
continue
|
||||
meta, body = _parse_frontmatter(text)
|
||||
entries.append(MemoryEntry(
|
||||
path=path,
|
||||
title=meta.get("name", path.stem),
|
||||
description=meta.get("description", ""),
|
||||
memory_type=meta.get("type", "project"),
|
||||
body=body[:MAX_ENTRY_CHARS],
|
||||
modified_at=path.stat().st_mtime,
|
||||
))
|
||||
return entries
|
||||
|
||||
def find_relevant(self, query: str, max_results: int = MAX_RESULTS) -> List[MemoryEntry]:
|
||||
"""Keyword search across all memory entries.
|
||||
|
||||
Scoring: metadata_hits * 2.0 + body_hits * 1.0.
|
||||
|
||||
Args:
|
||||
query: Search query.
|
||||
max_results: Maximum entries to return.
|
||||
|
||||
Returns:
|
||||
Top-scoring memory entries.
|
||||
"""
|
||||
query_tokens = _tokenize(query)
|
||||
if not query_tokens:
|
||||
return []
|
||||
|
||||
scored: list[tuple[float, MemoryEntry]] = []
|
||||
for entry in self._scan_entries():
|
||||
meta_tokens = _tokenize(f"{entry.title} {entry.description}")
|
||||
body_tokens = _tokenize(entry.body)
|
||||
score = len(query_tokens & meta_tokens) * METADATA_WEIGHT + len(query_tokens & body_tokens)
|
||||
if score > 0:
|
||||
scored.append((score, entry))
|
||||
|
||||
scored.sort(key=lambda x: (-x[0], -x[1].modified_at))
|
||||
return [entry for _, entry in scored[:max_results]]
|
||||
|
||||
def add(self, name: str, content: str, memory_type: str = "project",
|
||||
description: str = "") -> Path:
|
||||
"""Save a new memory entry and update the index.
|
||||
|
||||
Args:
|
||||
name: Memory name (used as filename slug).
|
||||
content: Memory body text.
|
||||
memory_type: One of user/feedback/project/reference.
|
||||
description: One-line description for retrieval scoring.
|
||||
|
||||
Returns:
|
||||
Path to the created memory file.
|
||||
"""
|
||||
slug = re.sub(r"[^a-z0-9_-]", "_", name.lower().strip())[:60]
|
||||
filename = f"{memory_type}_{slug}.md"
|
||||
path = self._dir / filename
|
||||
|
||||
safe_name = name.replace("\n", " ").replace("\r", " ")
|
||||
safe_desc = (description or name).replace("\n", " ").replace("\r", " ")
|
||||
frontmatter = (
|
||||
f"---\nname: {safe_name}\n"
|
||||
f"description: {safe_desc}\n"
|
||||
f"type: {memory_type}\n---\n\n"
|
||||
f"{content}"
|
||||
)
|
||||
path.write_text(frontmatter, encoding="utf-8")
|
||||
self._update_index(name, filename, description or name)
|
||||
return path
|
||||
|
||||
def remove(self, name: str) -> bool:
|
||||
"""Remove a memory entry by name.
|
||||
|
||||
Args:
|
||||
name: Memory name to remove.
|
||||
|
||||
Returns:
|
||||
True if found and removed.
|
||||
"""
|
||||
for entry in self._scan_entries():
|
||||
if entry.title == name:
|
||||
entry.path.unlink(missing_ok=True)
|
||||
self._rebuild_index()
|
||||
return True
|
||||
return False
|
||||
|
||||
def _update_index(self, title: str, filename: str, description: str) -> None:
|
||||
"""Append or update an entry in MEMORY.md."""
|
||||
new_line = f"- [{title}]({filename}) — {description}"
|
||||
|
||||
if self._index_path.exists():
|
||||
lines = self._index_path.read_text(encoding="utf-8").split("\n")
|
||||
updated = False
|
||||
for i, line in enumerate(lines):
|
||||
if f"[{title}]" in line:
|
||||
lines[i] = new_line
|
||||
updated = True
|
||||
break
|
||||
if not updated:
|
||||
lines.append(new_line)
|
||||
text = "\n".join(lines[:MAX_INDEX_LINES])
|
||||
else:
|
||||
text = new_line
|
||||
|
||||
self._index_path.write_text(text, encoding="utf-8")
|
||||
|
||||
def _rebuild_index(self) -> None:
|
||||
"""Rebuild MEMORY.md from all existing entry files."""
|
||||
entries = self._scan_entries()
|
||||
lines = [f"- [{e.title}]({e.path.name}) — {e.description}" for e in entries]
|
||||
self._index_path.write_text("\n".join(lines[:MAX_INDEX_LINES]), encoding="utf-8")
|
||||
+27
-17
@@ -11,6 +11,18 @@ from typing import Any, Dict, List, Optional
|
||||
from src.providers.llm import build_llm
|
||||
|
||||
|
||||
def _dedupe_finish_reason(raw: str) -> str:
|
||||
"""Relays (OpenRouter) emit finish_reason per chunk; AIMessageChunk.__add__
|
||||
concatenates into 'stopstop', 'tool_callstool_calls', etc. Return the
|
||||
canonical suffix so ReAct equality checks survive.
|
||||
"""
|
||||
return next(
|
||||
(m for m in ("tool_calls", "function_call", "content_filter", "length", "stop")
|
||||
if raw.endswith(m)),
|
||||
raw,
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ToolCallRequest:
|
||||
"""Tool call request returned by the LLM.
|
||||
@@ -38,6 +50,7 @@ class LLMResponse:
|
||||
|
||||
content: Optional[str] = None
|
||||
tool_calls: List[ToolCallRequest] = field(default_factory=list)
|
||||
reasoning_content: Optional[str] = None
|
||||
finish_reason: str = "stop"
|
||||
|
||||
@property
|
||||
@@ -133,22 +146,19 @@ class ChatLLM:
|
||||
|
||||
@staticmethod
|
||||
def _parse_response(ai_message: Any) -> LLMResponse:
|
||||
"""Convert a LangChain AIMessage to ``LLMResponse``.
|
||||
"""Convert a LangChain AIMessage (or AIMessageChunk) to ``LLMResponse``.
|
||||
|
||||
Args:
|
||||
ai_message: LangChain AIMessage instance.
|
||||
|
||||
Returns:
|
||||
``LLMResponse``.
|
||||
Single source for reasoning: ``additional_kwargs["reasoning_content"]``,
|
||||
populated by ``ChatOpenAIWithReasoning`` on both stream and non-stream paths.
|
||||
"""
|
||||
content = ai_message.content if hasattr(ai_message, "content") else None
|
||||
raw_calls = getattr(ai_message, "tool_calls", None) or []
|
||||
tool_calls = []
|
||||
for tc in raw_calls:
|
||||
tool_calls.append(ToolCallRequest(
|
||||
id=tc.get("id", ""),
|
||||
name=tc.get("name", ""),
|
||||
arguments=tc.get("args", {}),
|
||||
))
|
||||
finish = getattr(ai_message, "response_metadata", {}).get("finish_reason", "stop")
|
||||
return LLMResponse(content=content, tool_calls=tool_calls, finish_reason=finish)
|
||||
return LLMResponse(
|
||||
content=ai_message.content,
|
||||
tool_calls=[
|
||||
ToolCallRequest(id=tc["id"], name=tc["name"], arguments=tc["args"])
|
||||
for tc in ai_message.tool_calls
|
||||
],
|
||||
reasoning_content=ai_message.additional_kwargs.get("reasoning_content"),
|
||||
finish_reason=_dedupe_finish_reason(
|
||||
ai_message.response_metadata.get("finish_reason", "stop")
|
||||
),
|
||||
)
|
||||
@@ -17,6 +17,75 @@ try:
|
||||
except ImportError:
|
||||
ChatOpenAI = None # type: ignore
|
||||
|
||||
|
||||
if ChatOpenAI is not None:
|
||||
class ChatOpenAIWithReasoning(ChatOpenAI): # type: ignore[misc,valid-type]
|
||||
"""ChatOpenAI that preserves provider reasoning across invoke + stream.
|
||||
|
||||
langchain-openai 0.3.x drops non-standard fields in three paths:
|
||||
* _convert_dict_to_message — invoke / ainvoke (inbound)
|
||||
* _convert_delta_to_message_chunk — stream / astream (inbound)
|
||||
* _convert_message_to_dict — request serialization (outbound)
|
||||
Moonshot/DeepSeek emit `reasoning_content`; OpenRouter relays as
|
||||
`reasoning`. Inbound paths normalize to additional_kwargs["reasoning_content"];
|
||||
outbound path re-injects it so strict providers (kimi-k2.5) accept
|
||||
multi-turn continuations.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def _capture(src: Any, msg: Any) -> None:
|
||||
if value := src.get("reasoning_content") or src.get("reasoning"):
|
||||
msg.additional_kwargs["reasoning_content"] = value
|
||||
|
||||
def _create_chat_result(self, response, generation_info=None): # type: ignore[override]
|
||||
result = super()._create_chat_result(response, generation_info)
|
||||
raw = response if isinstance(response, dict) else response.model_dump()
|
||||
for gen, choice in zip(result.generations, raw["choices"]):
|
||||
self._capture(choice["message"], gen.message)
|
||||
return result
|
||||
|
||||
def _convert_chunk_to_generation_chunk( # type: ignore[override]
|
||||
self,
|
||||
chunk: dict,
|
||||
default_chunk_class: type,
|
||||
base_generation_info: Optional[dict],
|
||||
):
|
||||
gen = super()._convert_chunk_to_generation_chunk(
|
||||
chunk, default_chunk_class, base_generation_info
|
||||
)
|
||||
if gen is None:
|
||||
return None
|
||||
choices = chunk.get("choices") or chunk.get("chunk", {}).get("choices")
|
||||
if choices:
|
||||
self._capture(choices[0]["delta"], gen.message)
|
||||
return gen
|
||||
|
||||
def _get_request_payload( # type: ignore[override]
|
||||
self,
|
||||
input_: Any,
|
||||
*,
|
||||
stop: Optional[list[str]] = None,
|
||||
**kwargs: Any,
|
||||
) -> dict:
|
||||
"""Re-inject reasoning_content and normalize assistant content.
|
||||
|
||||
LangChain strips ``reasoning_content`` when serializing AIMessages
|
||||
back to OpenAI wire format. Moonshot kimi-k2.5 also rejects
|
||||
assistant turns where ``content`` is null or ``reasoning_content``
|
||||
is absent, breaking ReAct continuations after a tool call (#39).
|
||||
"""
|
||||
payload = super()._get_request_payload(input_, stop=stop, **kwargs)
|
||||
messages = super()._convert_input(input_).to_messages()
|
||||
for i, m in enumerate(payload["messages"]):
|
||||
if m.get("role") != "assistant":
|
||||
continue
|
||||
if m.get("content") is None:
|
||||
m["content"] = ""
|
||||
m["reasoning_content"] = messages[i].additional_kwargs.get("reasoning_content", "")
|
||||
return payload
|
||||
else:
|
||||
ChatOpenAIWithReasoning = None # type: ignore
|
||||
|
||||
AGENT_DIR = Path(__file__).resolve().parents[2]
|
||||
|
||||
# .env search order: ~/.vibe-trading/.env → agent/.env → $CWD/.env
|
||||
@@ -79,6 +148,7 @@ def _sync_provider_env() -> None:
|
||||
"moonshot": ("MOONSHOT_API_KEY", "MOONSHOT_BASE_URL"),
|
||||
"minimax": ("MINIMAX_API_KEY", "MINIMAX_BASE_URL"),
|
||||
"mimo": ("MIMO_API_KEY", "MIMO_BASE_URL"),
|
||||
"zai": ("ZAI_API_KEY", "ZAI_BASE_URL"),
|
||||
"ollama": (None, "OLLAMA_BASE_URL"),
|
||||
}
|
||||
|
||||
@@ -121,14 +191,20 @@ def build_llm(*, model_name: Optional[str] = None, callbacks: Any = None) -> Any
|
||||
if not name:
|
||||
raise RuntimeError("LANGCHAIN_MODEL_NAME is not set")
|
||||
temperature = float(os.getenv("LANGCHAIN_TEMPERATURE", "0.0"))
|
||||
timeout = int(os.getenv("TIMEOUT_SECONDS", "120"))
|
||||
max_retries = int(os.getenv("MAX_RETRIES", "2"))
|
||||
return ChatOpenAI(
|
||||
# MiniMax requires temperature in (0.0, 1.0] — clamp to 0.01 when the
|
||||
# default 0.0 is used to avoid an API validation error.
|
||||
if os.getenv("LANGCHAIN_PROVIDER", "openai").lower() == "minimax" and temperature <= 0.0:
|
||||
temperature = 0.01
|
||||
# Optional reasoning activation for relays requiring opt-in (e.g. OpenRouter).
|
||||
# Moonshot/DeepSeek official APIs emit reasoning by default and ignore this field.
|
||||
effort = os.getenv("LANGCHAIN_REASONING_EFFORT", "").strip().lower()
|
||||
return ChatOpenAIWithReasoning(
|
||||
model=name,
|
||||
temperature=temperature,
|
||||
timeout=timeout,
|
||||
max_retries=max_retries,
|
||||
timeout=int(os.getenv("TIMEOUT_SECONDS", "120")),
|
||||
max_retries=int(os.getenv("MAX_RETRIES", "2")),
|
||||
callbacks=callbacks,
|
||||
extra_body={"reasoning": {"effort": effort}} if effort else None,
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,343 @@
|
||||
"""SQLite FTS5 session search index for cross-session full-text search.
|
||||
|
||||
Stores an inverted index of all conversation messages. The primary data
|
||||
remains in the file-based SessionStore; this module provides a fast search
|
||||
layer on top.
|
||||
|
||||
Database location: ~/.vibe-trading/sessions.db (WAL mode for concurrent reads).
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import logging
|
||||
import sqlite3
|
||||
import time
|
||||
from dataclasses import dataclass
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import List, Optional
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_DB_PATH = Path.home() / ".vibe-trading" / "sessions.db"
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class SearchMatch:
|
||||
"""A single search result from the FTS5 index.
|
||||
|
||||
Attributes:
|
||||
session_id: Session ID.
|
||||
title: Session title.
|
||||
started_at: Human-readable start time.
|
||||
message_count: Total messages in the session.
|
||||
snippet: FTS5 snippet with match highlights (>>> <<<).
|
||||
rank: FTS5 relevance rank (lower is better).
|
||||
"""
|
||||
|
||||
session_id: str
|
||||
title: str
|
||||
started_at: str
|
||||
message_count: int
|
||||
snippet: str
|
||||
rank: float
|
||||
|
||||
def to_dict(self) -> dict:
|
||||
"""Serialize to JSON-safe dict."""
|
||||
return {
|
||||
"session_id": self.session_id,
|
||||
"title": self.title,
|
||||
"started_at": self.started_at,
|
||||
"message_count": self.message_count,
|
||||
"snippet": self.snippet,
|
||||
}
|
||||
|
||||
|
||||
class SessionSearchIndex:
|
||||
"""SQLite FTS5 index for cross-session search.
|
||||
|
||||
Supports:
|
||||
- Indexing individual messages as they arrive
|
||||
- Full-text search with relevance ranking
|
||||
- Bulk reindex from the file-based SessionStore
|
||||
"""
|
||||
|
||||
def __init__(self, db_path: Path = _DB_PATH) -> None:
|
||||
"""Initialize the search index.
|
||||
|
||||
Args:
|
||||
db_path: Path to SQLite database file.
|
||||
"""
|
||||
self.db_path = db_path
|
||||
self.db_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
self._conn: Optional[sqlite3.Connection] = None
|
||||
self._init_db()
|
||||
|
||||
def _get_conn(self) -> sqlite3.Connection:
|
||||
"""Get or create the SQLite connection (WAL mode)."""
|
||||
if self._conn is None:
|
||||
self._conn = sqlite3.connect(str(self.db_path), check_same_thread=False)
|
||||
self._conn.execute("PRAGMA journal_mode=WAL")
|
||||
self._conn.execute("PRAGMA synchronous=NORMAL")
|
||||
return self._conn
|
||||
|
||||
def _init_db(self) -> None:
|
||||
"""Create tables and FTS5 virtual table if they don't exist."""
|
||||
conn = self._get_conn()
|
||||
conn.executescript("""
|
||||
CREATE TABLE IF NOT EXISTS sessions (
|
||||
id TEXT PRIMARY KEY,
|
||||
title TEXT NOT NULL DEFAULT '',
|
||||
started_at REAL NOT NULL,
|
||||
message_count INTEGER NOT NULL DEFAULT 0
|
||||
);
|
||||
|
||||
CREATE TABLE IF NOT EXISTS messages (
|
||||
id INTEGER PRIMARY KEY AUTOINCREMENT,
|
||||
session_id TEXT NOT NULL,
|
||||
role TEXT NOT NULL,
|
||||
content TEXT NOT NULL,
|
||||
tool_name TEXT,
|
||||
timestamp REAL NOT NULL
|
||||
);
|
||||
|
||||
CREATE INDEX IF NOT EXISTS idx_messages_session
|
||||
ON messages(session_id);
|
||||
""")
|
||||
# FTS5 virtual table — create separately (not inside executescript with IF NOT EXISTS
|
||||
# because FTS5 syntax varies across SQLite versions)
|
||||
try:
|
||||
conn.execute("""
|
||||
CREATE VIRTUAL TABLE IF NOT EXISTS messages_fts
|
||||
USING fts5(content, content=messages, content_rowid=id)
|
||||
""")
|
||||
except sqlite3.OperationalError:
|
||||
pass # already exists or FTS5 not available
|
||||
|
||||
# Auto-sync triggers
|
||||
for trigger_sql in [
|
||||
"""CREATE TRIGGER IF NOT EXISTS messages_ai AFTER INSERT ON messages BEGIN
|
||||
INSERT INTO messages_fts(rowid, content) VALUES (new.id, new.content);
|
||||
END""",
|
||||
"""CREATE TRIGGER IF NOT EXISTS messages_ad AFTER DELETE ON messages BEGIN
|
||||
INSERT INTO messages_fts(messages_fts, rowid, content)
|
||||
VALUES ('delete', old.id, old.content);
|
||||
END""",
|
||||
]:
|
||||
try:
|
||||
conn.execute(trigger_sql)
|
||||
except sqlite3.OperationalError:
|
||||
pass
|
||||
conn.commit()
|
||||
|
||||
def index_session(self, session_id: str, title: str = "") -> None:
|
||||
"""Upsert a session record.
|
||||
|
||||
Args:
|
||||
session_id: Session ID.
|
||||
title: Session title.
|
||||
"""
|
||||
conn = self._get_conn()
|
||||
conn.execute(
|
||||
"INSERT OR REPLACE INTO sessions (id, title, started_at, message_count) "
|
||||
"VALUES (?, ?, ?, COALESCE((SELECT message_count FROM sessions WHERE id = ?), 0))",
|
||||
(session_id, title, time.time(), session_id),
|
||||
)
|
||||
conn.commit()
|
||||
|
||||
def index_message(self, session_id: str, role: str, content: str,
|
||||
tool_name: Optional[str] = None) -> None:
|
||||
"""Index a single message.
|
||||
|
||||
Args:
|
||||
session_id: Session ID.
|
||||
role: Message role (user/assistant/tool).
|
||||
content: Message text.
|
||||
tool_name: Tool name if this is a tool result.
|
||||
"""
|
||||
if not content or not content.strip():
|
||||
return
|
||||
conn = self._get_conn()
|
||||
conn.execute(
|
||||
"INSERT INTO messages (session_id, role, content, tool_name, timestamp) "
|
||||
"VALUES (?, ?, ?, ?, ?)",
|
||||
(session_id, role, content[:50_000], tool_name, time.time()),
|
||||
)
|
||||
conn.execute(
|
||||
"UPDATE sessions SET message_count = message_count + 1 WHERE id = ?",
|
||||
(session_id,),
|
||||
)
|
||||
conn.commit()
|
||||
|
||||
@staticmethod
|
||||
def _sanitize_fts_query(query: str) -> str:
|
||||
"""Sanitize a user query for FTS5 MATCH syntax.
|
||||
|
||||
- Splits on non-alphanumeric/CJK to extract tokens
|
||||
- Joins with OR so any-word-matches (not all-words-required)
|
||||
- Quotes each token to prevent FTS5 operator interpretation
|
||||
|
||||
Args:
|
||||
query: Raw user query string.
|
||||
|
||||
Returns:
|
||||
FTS5-safe MATCH expression.
|
||||
"""
|
||||
import re as _re
|
||||
# Extract alphanumeric tokens (3+ chars) and CJK characters
|
||||
tokens = _re.findall(r"[a-zA-Z0-9_]{2,}|[\u4e00-\u9fff\u3400-\u4dbf]", query)
|
||||
if not tokens:
|
||||
return '""'
|
||||
# Quote each token and join with OR for broader matching
|
||||
return " OR ".join(f'"{t}"' for t in tokens)
|
||||
|
||||
def search(self, query: str, max_sessions: int = 3) -> List[SearchMatch]:
|
||||
"""Full-text search across all sessions.
|
||||
|
||||
Args:
|
||||
query: Search query (keywords or phrase).
|
||||
max_sessions: Maximum number of distinct sessions to return.
|
||||
|
||||
Returns:
|
||||
List of SearchMatch results, grouped by session, ranked by relevance.
|
||||
"""
|
||||
conn = self._get_conn()
|
||||
fts_query = self._sanitize_fts_query(query)
|
||||
try:
|
||||
cursor = conn.execute(
|
||||
"""
|
||||
SELECT
|
||||
m.session_id,
|
||||
s.title,
|
||||
s.started_at,
|
||||
s.message_count,
|
||||
snippet(messages_fts, 0, '>>>', '<<<', '...', 64) AS snippet,
|
||||
rank
|
||||
FROM messages_fts
|
||||
JOIN messages m ON m.id = messages_fts.rowid
|
||||
JOIN sessions s ON s.id = m.session_id
|
||||
WHERE messages_fts MATCH ?
|
||||
ORDER BY rank
|
||||
LIMIT ?
|
||||
""",
|
||||
(fts_query, max_sessions * 5),
|
||||
)
|
||||
except sqlite3.OperationalError as exc:
|
||||
logger.warning("FTS5 search failed: %s", exc)
|
||||
return []
|
||||
|
||||
seen: dict[str, SearchMatch] = {}
|
||||
for row in cursor.fetchall():
|
||||
sid = row[0]
|
||||
if sid in seen:
|
||||
continue
|
||||
seen[sid] = SearchMatch(
|
||||
session_id=row[0],
|
||||
title=row[1] or "(untitled)",
|
||||
started_at=self._format_time(row[2]),
|
||||
message_count=row[3],
|
||||
snippet=row[4],
|
||||
rank=row[5],
|
||||
)
|
||||
if len(seen) >= max_sessions:
|
||||
break
|
||||
|
||||
return list(seen.values())
|
||||
|
||||
def reindex_from_store(self, store_base_dir: Path) -> int:
|
||||
"""Rebuild the entire index from file-based session store.
|
||||
|
||||
Args:
|
||||
store_base_dir: Root directory of the SessionStore (contains session subdirs).
|
||||
|
||||
Returns:
|
||||
Number of messages indexed.
|
||||
"""
|
||||
if not store_base_dir.exists():
|
||||
return 0
|
||||
|
||||
conn = self._get_conn()
|
||||
conn.execute("DELETE FROM messages")
|
||||
conn.execute("DELETE FROM sessions")
|
||||
try:
|
||||
conn.execute("INSERT INTO messages_fts(messages_fts) VALUES ('rebuild')")
|
||||
except sqlite3.OperationalError:
|
||||
pass
|
||||
conn.commit()
|
||||
|
||||
count = 0
|
||||
for session_dir in store_base_dir.iterdir():
|
||||
if not session_dir.is_dir():
|
||||
continue
|
||||
|
||||
session_file = session_dir / "session.json"
|
||||
messages_file = session_dir / "messages.jsonl"
|
||||
|
||||
if not session_file.exists():
|
||||
continue
|
||||
|
||||
try:
|
||||
session_data = json.loads(session_file.read_text(encoding="utf-8"))
|
||||
sid = session_data.get("session_id", session_dir.name)
|
||||
title = session_data.get("title", "")
|
||||
|
||||
try:
|
||||
ts = datetime.fromisoformat(session_data.get("created_at", "")).timestamp()
|
||||
except (ValueError, TypeError):
|
||||
ts = time.time()
|
||||
|
||||
self.index_session(sid, title)
|
||||
|
||||
if messages_file.exists():
|
||||
for line in messages_file.read_text(encoding="utf-8").strip().splitlines():
|
||||
if not line.strip():
|
||||
continue
|
||||
try:
|
||||
msg = json.loads(line)
|
||||
role = msg.get("role", "")
|
||||
content = msg.get("content", "")
|
||||
if content and role in ("user", "assistant"):
|
||||
self.index_message(sid, role, content)
|
||||
count += 1
|
||||
except json.JSONDecodeError:
|
||||
continue
|
||||
except Exception as exc:
|
||||
logger.warning("Failed to index session %s: %s", session_dir.name, exc)
|
||||
|
||||
return count
|
||||
|
||||
@staticmethod
|
||||
def _format_time(epoch: float) -> str:
|
||||
"""Format epoch timestamp to human-readable string."""
|
||||
try:
|
||||
return datetime.fromtimestamp(epoch).strftime("%Y-%m-%d %H:%M")
|
||||
except (OSError, ValueError):
|
||||
return "unknown"
|
||||
|
||||
def close(self) -> None:
|
||||
"""Close the database connection."""
|
||||
if self._conn:
|
||||
self._conn.close()
|
||||
self._conn = None
|
||||
|
||||
|
||||
import threading as _threading
|
||||
|
||||
_shared_index: Optional[SessionSearchIndex] = None
|
||||
_shared_lock = _threading.Lock()
|
||||
|
||||
|
||||
def get_shared_index() -> SessionSearchIndex:
|
||||
"""Return a process-wide singleton SessionSearchIndex.
|
||||
|
||||
Thread-safe via double-checked locking. Used by both
|
||||
SessionService (indexing) and SessionSearchTool (searching)
|
||||
so they share one SQLite connection.
|
||||
"""
|
||||
global _shared_index
|
||||
if _shared_index is None:
|
||||
with _shared_lock:
|
||||
if _shared_index is None:
|
||||
_shared_index = SessionSearchIndex()
|
||||
return _shared_index
|
||||
@@ -21,6 +21,7 @@ from src.session.models import (
|
||||
Message,
|
||||
Session,
|
||||
)
|
||||
from src.session.search import get_shared_index
|
||||
from src.session.store import SessionStore
|
||||
|
||||
|
||||
@@ -50,6 +51,7 @@ class SessionService:
|
||||
self.event_bus = event_bus
|
||||
self.runs_dir = runs_dir
|
||||
self._active_loops: Dict[str, "AgentLoop"] = {}
|
||||
self._search_index = get_shared_index()
|
||||
|
||||
def create_session(self, title: str = "", config: Optional[Dict[str, Any]] = None) -> Session:
|
||||
"""Create a new session.
|
||||
@@ -63,6 +65,7 @@ class SessionService:
|
||||
"""
|
||||
session = Session(title=title, config=config or {})
|
||||
self.store.create_session(session)
|
||||
self._search_index.index_session(session.session_id, title)
|
||||
self.event_bus.emit(session.session_id, "session.created", {"session_id": session.session_id, "title": title})
|
||||
return session
|
||||
|
||||
@@ -96,6 +99,7 @@ class SessionService:
|
||||
|
||||
message = Message(session_id=session_id, role=role, content=content)
|
||||
self.store.append_message(message)
|
||||
self._search_index.index_message(session_id, role, content)
|
||||
self.event_bus.emit(session_id, "message.received", {"message_id": message.message_id, "role": role, "content": content})
|
||||
|
||||
if role != "user":
|
||||
@@ -200,6 +204,7 @@ class SessionService:
|
||||
metadata=reply_metadata,
|
||||
)
|
||||
self.store.append_message(reply)
|
||||
self._search_index.index_message(session.session_id, "assistant", reply.content)
|
||||
self.event_bus.emit(
|
||||
session.session_id,
|
||||
"attempt.completed" if attempt.status == AttemptStatus.COMPLETED else "attempt.failed",
|
||||
@@ -225,9 +230,10 @@ class SessionService:
|
||||
from src.tools import build_registry
|
||||
from src.providers.chat import ChatLLM
|
||||
from src.agent.loop import AgentLoop
|
||||
from src.memory.persistent import PersistentMemory
|
||||
|
||||
registry = build_registry()
|
||||
llm = ChatLLM()
|
||||
pm = PersistentMemory()
|
||||
|
||||
session_id = attempt.session_id
|
||||
attempt_id = attempt.attempt_id
|
||||
@@ -238,10 +244,11 @@ class SessionService:
|
||||
self.event_bus.emit(session_id, event_type, data)
|
||||
|
||||
agent = AgentLoop(
|
||||
registry=registry,
|
||||
registry=build_registry(persistent_memory=pm),
|
||||
llm=llm,
|
||||
event_callback=event_callback,
|
||||
max_iterations=50,
|
||||
persistent_memory=pm,
|
||||
)
|
||||
self._active_loops[session_id] = agent
|
||||
|
||||
@@ -249,7 +256,7 @@ class SessionService:
|
||||
history = self._convert_messages_to_history(messages) if messages else None
|
||||
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
loop = asyncio.get_running_loop()
|
||||
result = await loop.run_in_executor(
|
||||
_AGENT_EXECUTOR,
|
||||
lambda: agent.run(
|
||||
|
||||
@@ -0,0 +1,53 @@
|
||||
"""Shadow Account — extract a user's profitable pattern as a re-runnable shadow.
|
||||
|
||||
Public API (for tools/tests/external callers):
|
||||
extract_shadow_profile: journal → ShadowProfile
|
||||
ShadowProfile / ShadowRule / ShadowBacktestResult / AttributionBreakdown
|
||||
storage: save_profile / load_profile / find_by_journal_hash
|
||||
"""
|
||||
|
||||
from src.shadow_account.backtester import (
|
||||
SUPPORTED_MARKETS,
|
||||
run_shadow_backtest,
|
||||
select_multi_market_codes,
|
||||
)
|
||||
from src.shadow_account.codegen import (
|
||||
render_config,
|
||||
render_signal_engine,
|
||||
validate_generated,
|
||||
write_run_dir,
|
||||
)
|
||||
from src.shadow_account.extractor import extract_shadow_profile
|
||||
from src.shadow_account.reporter import render_shadow_report
|
||||
from src.shadow_account.models import (
|
||||
AttributionBreakdown,
|
||||
ShadowBacktestResult,
|
||||
ShadowProfile,
|
||||
ShadowRule,
|
||||
)
|
||||
from src.shadow_account.storage import (
|
||||
find_by_journal_hash,
|
||||
load_profile,
|
||||
new_shadow_id,
|
||||
save_profile,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"AttributionBreakdown",
|
||||
"SUPPORTED_MARKETS",
|
||||
"ShadowBacktestResult",
|
||||
"ShadowProfile",
|
||||
"ShadowRule",
|
||||
"extract_shadow_profile",
|
||||
"find_by_journal_hash",
|
||||
"load_profile",
|
||||
"new_shadow_id",
|
||||
"render_config",
|
||||
"render_shadow_report",
|
||||
"render_signal_engine",
|
||||
"run_shadow_backtest",
|
||||
"save_profile",
|
||||
"select_multi_market_codes",
|
||||
"validate_generated",
|
||||
"write_run_dir",
|
||||
]
|
||||
@@ -0,0 +1,529 @@
|
||||
"""Shadow Account — multi-market backtest driver + delta-PnL attribution.
|
||||
|
||||
Responsibilities:
|
||||
1. Pick representative symbols per market based on the user's preferred
|
||||
markets (with a liquid-basket fallback).
|
||||
2. Render a run_dir (via ``codegen.write_run_dir``) and call
|
||||
``src.tools.backtest_tool.run_backtest``.
|
||||
3. Parse the emitted artifacts (metrics JSON / equity CSV) back into a
|
||||
``ShadowBacktestResult``.
|
||||
4. Compute attribution: noise trades, missed signals, early/late exits,
|
||||
overtrading — each as signed PnL.
|
||||
|
||||
The attribution algorithm is deliberately arithmetic-only: no LLM, no
|
||||
simulation rebuild. This keeps the numbers auditable and reproducible.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import logging
|
||||
from dataclasses import replace
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from src.shadow_account.codegen import write_run_dir
|
||||
from src.shadow_account.models import (
|
||||
AttributionBreakdown,
|
||||
ShadowBacktestResult,
|
||||
ShadowProfile,
|
||||
)
|
||||
from src.shadow_account.storage import runs_dir
|
||||
from src.tools.trade_journal_parsers import parse_file, records_to_dataframe
|
||||
from src.tools.trade_journal_tool import pair_trades_fifo
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
SUPPORTED_MARKETS: tuple[str, ...] = ("china_a", "hk", "us", "crypto")
|
||||
|
||||
_LIQUID_BASKETS: dict[str, list[str]] = {
|
||||
"china_a": ["600519.SH", "000858.SZ", "300750.SZ", "600036.SH", "000001.SZ"],
|
||||
"hk": ["00700.HK", "09988.HK", "03690.HK", "00388.HK", "01810.HK"],
|
||||
"us": ["AAPL", "MSFT", "NVDA", "AMZN", "GOOGL"],
|
||||
"crypto": ["BTC-USDT", "ETH-USDT", "SOL-USDT", "BNB-USDT", "XRP-USDT"],
|
||||
}
|
||||
|
||||
|
||||
# ---------------- Code selection ----------------
|
||||
|
||||
def select_multi_market_codes(
|
||||
profile: ShadowProfile,
|
||||
*,
|
||||
per_market_count: int = 5,
|
||||
markets: tuple[str, ...] = SUPPORTED_MARKETS,
|
||||
) -> dict[str, list[str]]:
|
||||
"""Pick representative tickers for each target market.
|
||||
|
||||
Priority:
|
||||
1. If the profile's source_market is in the target set and is in the
|
||||
liquid basket, surface it first.
|
||||
2. Fill remaining markets from their liquid basket.
|
||||
|
||||
Args:
|
||||
profile: Shadow profile (source_market guides prioritization).
|
||||
per_market_count: Cap per market (clamped to basket size).
|
||||
markets: Markets to include.
|
||||
|
||||
Returns:
|
||||
Dict market → list of codes, non-empty for every requested market
|
||||
that has a known basket.
|
||||
"""
|
||||
selection: dict[str, list[str]] = {}
|
||||
for market in markets:
|
||||
basket = _LIQUID_BASKETS.get(market)
|
||||
if not basket:
|
||||
continue
|
||||
selection[market] = basket[: max(1, per_market_count)]
|
||||
return selection
|
||||
|
||||
|
||||
def flatten_codes(selection: dict[str, list[str]]) -> list[str]:
|
||||
"""Flatten per-market selection into a unique, order-preserving code list."""
|
||||
seen: set[str] = set()
|
||||
out: list[str] = []
|
||||
for codes in selection.values():
|
||||
for c in codes:
|
||||
if c not in seen:
|
||||
out.append(c)
|
||||
seen.add(c)
|
||||
return out
|
||||
|
||||
|
||||
# ---------------- Backtest execution ----------------
|
||||
|
||||
def run_shadow_backtest(
|
||||
profile: ShadowProfile,
|
||||
*,
|
||||
window_start: str,
|
||||
window_end: str,
|
||||
markets: tuple[str, ...] = SUPPORTED_MARKETS,
|
||||
per_market_count: int = 5,
|
||||
source: str = "auto",
|
||||
initial_capital: float = 1_000_000.0,
|
||||
journal_path: str | Path | None = None,
|
||||
run_backtest_fn: Any | None = None,
|
||||
) -> ShadowBacktestResult:
|
||||
"""Drive a multi-market backtest from a ShadowProfile.
|
||||
|
||||
Args:
|
||||
profile: ShadowProfile to replay.
|
||||
window_start / window_end: ISO dates.
|
||||
markets: Target market buckets.
|
||||
per_market_count: Codes per market.
|
||||
source: Loader source (``auto`` routes by suffix).
|
||||
initial_capital: Starting cash.
|
||||
journal_path: Original journal path (used to compute attribution
|
||||
against the user's realized trades). Attribution is skipped if
|
||||
None or the file is missing.
|
||||
run_backtest_fn: Injection point for tests — callable(run_dir_str)
|
||||
returning the same JSON payload as
|
||||
``src.tools.backtest_tool.run_backtest``. Defaults to the real
|
||||
entrypoint.
|
||||
|
||||
Returns:
|
||||
ShadowBacktestResult with per-market + combined metrics, equity
|
||||
curves (when emitted), and attribution (zeros when unavailable).
|
||||
"""
|
||||
selection = select_multi_market_codes(
|
||||
profile, per_market_count=per_market_count, markets=markets,
|
||||
)
|
||||
codes = flatten_codes(selection)
|
||||
if not codes:
|
||||
raise ValueError("No codes available for requested markets.")
|
||||
|
||||
run_dir = runs_dir(profile.shadow_id)
|
||||
write_run_dir(
|
||||
profile,
|
||||
run_dir,
|
||||
codes=codes,
|
||||
start_date=window_start,
|
||||
end_date=window_end,
|
||||
source=source,
|
||||
initial_capital=initial_capital,
|
||||
)
|
||||
|
||||
backtest_fn = run_backtest_fn or _default_run_backtest_fn()
|
||||
payload = json.loads(backtest_fn(str(run_dir)))
|
||||
|
||||
per_market, combined, equity_curves = _summarize_artifacts(
|
||||
payload=payload, run_dir=run_dir, selection=selection,
|
||||
)
|
||||
|
||||
attribution, shadow_pnl, real_pnl = _attribution_or_zero(
|
||||
profile=profile,
|
||||
journal_path=journal_path,
|
||||
combined=combined,
|
||||
)
|
||||
|
||||
result = ShadowBacktestResult(
|
||||
shadow_id=profile.shadow_id,
|
||||
per_market=per_market,
|
||||
combined=combined,
|
||||
equity_curves=equity_curves,
|
||||
attribution=attribution,
|
||||
shadow_total_pnl=shadow_pnl,
|
||||
real_total_pnl=real_pnl,
|
||||
delta_pnl=round(shadow_pnl - real_pnl, 2),
|
||||
)
|
||||
_cache_result(run_dir, result)
|
||||
return result
|
||||
|
||||
|
||||
def load_cached_result(shadow_id: str) -> ShadowBacktestResult | None:
|
||||
"""Load the last cached backtest result for a shadow, if any."""
|
||||
cache_path = runs_dir(shadow_id) / "shadow_result.json"
|
||||
if not cache_path.exists():
|
||||
return None
|
||||
try:
|
||||
data = json.loads(cache_path.read_text(encoding="utf-8"))
|
||||
except (OSError, json.JSONDecodeError):
|
||||
return None
|
||||
attr = data.get("attribution") or {}
|
||||
return ShadowBacktestResult(
|
||||
shadow_id=data["shadow_id"],
|
||||
per_market=data.get("per_market") or {},
|
||||
combined=data.get("combined") or {},
|
||||
equity_curves={
|
||||
k: [(str(pt[0]), float(pt[1])) for pt in v]
|
||||
for k, v in (data.get("equity_curves") or {}).items()
|
||||
},
|
||||
attribution=AttributionBreakdown(
|
||||
missed_signals_pnl=float(attr.get("missed_signals_pnl", 0.0)),
|
||||
noise_trades_pnl=float(attr.get("noise_trades_pnl", 0.0)),
|
||||
early_exit_pnl=float(attr.get("early_exit_pnl", 0.0)),
|
||||
late_exit_pnl=float(attr.get("late_exit_pnl", 0.0)),
|
||||
overtrading_pnl=float(attr.get("overtrading_pnl", 0.0)),
|
||||
counterfactual_trades=tuple(attr.get("counterfactual_trades") or ()),
|
||||
),
|
||||
shadow_total_pnl=float(data.get("shadow_total_pnl", 0.0)),
|
||||
real_total_pnl=float(data.get("real_total_pnl", 0.0)),
|
||||
delta_pnl=float(data.get("delta_pnl", 0.0)),
|
||||
)
|
||||
|
||||
|
||||
def _cache_result(run_dir: Path, result: ShadowBacktestResult) -> None:
|
||||
"""Persist a ShadowBacktestResult so downstream tools don't re-backtest."""
|
||||
from dataclasses import asdict as _asdict
|
||||
|
||||
payload = _asdict(result)
|
||||
try:
|
||||
(run_dir / "shadow_result.json").write_text(
|
||||
json.dumps(payload, ensure_ascii=False, indent=2, default=str),
|
||||
encoding="utf-8",
|
||||
)
|
||||
except OSError as exc: # pragma: no cover — disk failure is non-fatal
|
||||
logger.warning("Failed to cache shadow result: %s", exc)
|
||||
|
||||
|
||||
def _default_run_backtest_fn():
|
||||
from src.tools.backtest_tool import run_backtest
|
||||
return run_backtest
|
||||
|
||||
|
||||
# ---------------- Artifact parsing ----------------
|
||||
|
||||
def _summarize_artifacts(
|
||||
*,
|
||||
payload: dict[str, Any],
|
||||
run_dir: Path,
|
||||
selection: dict[str, list[str]],
|
||||
) -> tuple[dict[str, dict[str, float]], dict[str, float], dict[str, list[tuple[str, float]]]]:
|
||||
"""Turn raw backtest output into (per_market, combined, equity_curves).
|
||||
|
||||
Gracefully degrades when artifacts are missing (e.g. data fetch failed):
|
||||
returns empty dicts and a combined dict containing the error reason.
|
||||
"""
|
||||
artifacts = payload.get("artifacts") or {}
|
||||
status = payload.get("status", "error")
|
||||
|
||||
combined = _load_metrics(artifacts, run_dir)
|
||||
equity_points = _load_equity_curve(artifacts, run_dir)
|
||||
|
||||
# Only surface an error when we genuinely have no metrics. A non-ok
|
||||
# status with usable metrics typically means a transient data-source
|
||||
# warning (e.g. yfinance flaked on one market) — downgrading to ok is
|
||||
# more faithful to what the user actually has.
|
||||
if not combined and status != "ok":
|
||||
combined = {"error": payload.get("stderr", "")[-200:] or "backtest failed"}
|
||||
|
||||
per_market = _per_market_breakdown(combined, selection)
|
||||
equity_curves = {"combined": equity_points} if equity_points else {}
|
||||
return per_market, combined, equity_curves
|
||||
|
||||
|
||||
def _load_metrics(artifacts: dict[str, str], run_dir: Path) -> dict[str, float]:
|
||||
"""Pull a numeric metrics dict from the run_dir.
|
||||
|
||||
Looks for ``metrics.json`` first (preferred), then ``metrics.csv``.
|
||||
Unknown shape → empty dict (caller treats as failure).
|
||||
"""
|
||||
for key in ("metrics.json", "metrics", "metrics.csv"):
|
||||
path_str = artifacts.get(key)
|
||||
if not path_str:
|
||||
continue
|
||||
path = Path(path_str)
|
||||
if not path.exists():
|
||||
continue
|
||||
try:
|
||||
if path.suffix == ".json":
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
return _coerce_numeric(data)
|
||||
if path.suffix == ".csv":
|
||||
df = pd.read_csv(path)
|
||||
if df.empty:
|
||||
return {}
|
||||
row = df.iloc[-1].to_dict()
|
||||
return _coerce_numeric(row)
|
||||
except (OSError, json.JSONDecodeError, ValueError) as exc:
|
||||
logger.warning("Failed to parse metrics %s: %s", path, exc)
|
||||
|
||||
# Fallback: scan run_dir for a metrics file.
|
||||
for path in run_dir.glob("**/metrics.*"):
|
||||
try:
|
||||
if path.suffix == ".json":
|
||||
return _coerce_numeric(json.loads(path.read_text(encoding="utf-8")))
|
||||
if path.suffix == ".csv":
|
||||
df = pd.read_csv(path)
|
||||
if not df.empty:
|
||||
return _coerce_numeric(df.iloc[-1].to_dict())
|
||||
except Exception:
|
||||
continue
|
||||
return {}
|
||||
|
||||
|
||||
def _load_equity_curve(artifacts: dict[str, str], run_dir: Path) -> list[tuple[str, float]]:
|
||||
"""Load the equity curve as [(iso_date, equity), ...]."""
|
||||
candidates: list[Path] = []
|
||||
for key in ("equity.csv", "equity", "equity_curve.csv"):
|
||||
path_str = artifacts.get(key)
|
||||
if path_str:
|
||||
candidates.append(Path(path_str))
|
||||
candidates.extend(run_dir.glob("**/equity*.csv"))
|
||||
|
||||
seen: set[Path] = set()
|
||||
for path in candidates:
|
||||
if path in seen or not path.exists():
|
||||
continue
|
||||
seen.add(path)
|
||||
try:
|
||||
df = pd.read_csv(path)
|
||||
except (OSError, pd.errors.ParserError) as exc:
|
||||
logger.warning("Failed to read equity csv %s: %s", path, exc)
|
||||
continue
|
||||
if df.empty:
|
||||
continue
|
||||
date_col = next((c for c in df.columns if c.lower() in ("date", "datetime", "timestamp")), df.columns[0])
|
||||
equity_col = next(
|
||||
(c for c in df.columns if c.lower() in ("equity", "equity_curve", "value", "net_value")),
|
||||
df.columns[-1],
|
||||
)
|
||||
return [(str(row[date_col]), float(row[equity_col])) for _, row in df.iterrows()]
|
||||
return []
|
||||
|
||||
|
||||
def _coerce_numeric(data: dict[str, Any]) -> dict[str, float]:
|
||||
"""Keep only the scalar numeric fields from a metrics dict."""
|
||||
out: dict[str, float] = {}
|
||||
for key, value in data.items():
|
||||
if isinstance(value, bool):
|
||||
continue
|
||||
if isinstance(value, (int, float)):
|
||||
out[str(key)] = float(value)
|
||||
return out
|
||||
|
||||
|
||||
def _per_market_breakdown(
|
||||
combined: dict[str, float],
|
||||
selection: dict[str, list[str]],
|
||||
) -> dict[str, dict[str, float]]:
|
||||
"""Project the combined metrics into each requested market.
|
||||
|
||||
v1 limitation: the runner emits a single combined metrics file regardless
|
||||
of cross-market composition, so per-market rows reuse the combined
|
||||
metrics. This is faithful (same backtest) but intentionally lossy; a
|
||||
follow-up can split equity by market attribution.
|
||||
"""
|
||||
if not combined:
|
||||
return {market: {} for market in selection}
|
||||
return {market: dict(combined) for market in selection}
|
||||
|
||||
|
||||
# ---------------- Attribution ----------------
|
||||
|
||||
def _attribution_or_zero(
|
||||
*,
|
||||
profile: ShadowProfile,
|
||||
journal_path: str | Path | None,
|
||||
combined: dict[str, float],
|
||||
) -> tuple[AttributionBreakdown, float, float]:
|
||||
"""Compute attribution if the journal is available, else return zeros."""
|
||||
shadow_pnl = float(combined.get("total_return_abs") or combined.get("total_pnl") or 0.0)
|
||||
if not journal_path:
|
||||
return _zero_attribution(), shadow_pnl, 0.0
|
||||
path = Path(journal_path)
|
||||
if not path.exists():
|
||||
return _zero_attribution(), shadow_pnl, 0.0
|
||||
|
||||
try:
|
||||
_, records = parse_file(path)
|
||||
trades_df = records_to_dataframe(records)
|
||||
roundtrips = pair_trades_fifo(trades_df)
|
||||
except Exception as exc:
|
||||
logger.warning("Attribution skipped — journal parse failed: %s", exc)
|
||||
return _zero_attribution(), shadow_pnl, 0.0
|
||||
|
||||
if not roundtrips:
|
||||
return _zero_attribution(), shadow_pnl, 0.0
|
||||
|
||||
return _compute_attribution(profile=profile, roundtrips=roundtrips, shadow_pnl=shadow_pnl)
|
||||
|
||||
|
||||
def _zero_attribution() -> AttributionBreakdown:
|
||||
return AttributionBreakdown(
|
||||
missed_signals_pnl=0.0,
|
||||
noise_trades_pnl=0.0,
|
||||
early_exit_pnl=0.0,
|
||||
late_exit_pnl=0.0,
|
||||
overtrading_pnl=0.0,
|
||||
counterfactual_trades=(),
|
||||
)
|
||||
|
||||
|
||||
def _compute_attribution(
|
||||
*,
|
||||
profile: ShadowProfile,
|
||||
roundtrips: list[dict[str, Any]],
|
||||
shadow_pnl: float,
|
||||
) -> tuple[AttributionBreakdown, float, float]:
|
||||
"""Attribute the delta between user's real PnL and shadow PnL.
|
||||
|
||||
Decomposition (signed — positive means shadow would have earned more):
|
||||
|
||||
noise_trades_pnl = -Σ realized_pnl on rule-violating trades
|
||||
(user's unexplained losses that shadow avoids)
|
||||
early_exit_pnl = +Σ shortfall on winning trades exited before
|
||||
the median rule holding range
|
||||
late_exit_pnl = +Σ excess loss on losing trades held past the
|
||||
median rule holding range
|
||||
overtrading_pnl = -Σ realized_pnl on trades beyond the shadow's
|
||||
expected trade budget (1 trade per 2*hold_days)
|
||||
missed_signals_pnl = shadow_pnl - real_pnl - (noise+early+late+over)
|
||||
(residual — everything the above can't explain)
|
||||
|
||||
``counterfactual_trades`` lists the top-5 |impact| roundtrips for
|
||||
Section 6 of the report.
|
||||
"""
|
||||
rule_hold_lo, rule_hold_hi = _aggregate_holding_range(profile)
|
||||
noise = 0.0
|
||||
early = 0.0
|
||||
late = 0.0
|
||||
real_pnl = 0.0
|
||||
counterfactuals: list[dict[str, Any]] = []
|
||||
|
||||
for rt in roundtrips:
|
||||
pnl = float(rt["pnl"])
|
||||
real_pnl += pnl
|
||||
hold = float(rt["hold_days"])
|
||||
within_rule = rule_hold_lo <= hold <= rule_hold_hi
|
||||
impact = 0.0
|
||||
reason = ""
|
||||
if not within_rule:
|
||||
noise += -pnl
|
||||
impact += -pnl
|
||||
reason = "rule_violation"
|
||||
if pnl > 0 and hold < rule_hold_lo:
|
||||
shortfall = pnl * max(0.0, (rule_hold_lo - hold) / max(rule_hold_lo, 1))
|
||||
early += shortfall
|
||||
impact += shortfall
|
||||
reason = reason or "early_exit"
|
||||
if pnl < 0 and hold > rule_hold_hi:
|
||||
excess = -pnl * max(0.0, (hold - rule_hold_hi) / max(rule_hold_hi, 1))
|
||||
late += excess
|
||||
impact += excess
|
||||
reason = reason or "late_exit"
|
||||
if impact != 0.0:
|
||||
counterfactuals.append({
|
||||
"symbol": rt["symbol"],
|
||||
"buy_dt": str(rt["buy_dt"]),
|
||||
"sell_dt": str(rt["sell_dt"]),
|
||||
"hold_days": hold,
|
||||
"pnl": round(pnl, 2),
|
||||
"impact": round(impact, 2),
|
||||
"reason": reason,
|
||||
})
|
||||
|
||||
overtrading = _overtrading_pnl(profile=profile, roundtrips=roundtrips)
|
||||
explained = noise + early + late + overtrading
|
||||
missed = round(shadow_pnl - real_pnl - explained, 2)
|
||||
|
||||
counterfactuals.sort(key=lambda r: abs(r["impact"]), reverse=True)
|
||||
top5 = tuple(counterfactuals[:5])
|
||||
|
||||
return (
|
||||
AttributionBreakdown(
|
||||
missed_signals_pnl=round(missed, 2),
|
||||
noise_trades_pnl=round(noise, 2),
|
||||
early_exit_pnl=round(early, 2),
|
||||
late_exit_pnl=round(late, 2),
|
||||
overtrading_pnl=round(overtrading, 2),
|
||||
counterfactual_trades=top5,
|
||||
),
|
||||
round(shadow_pnl, 2),
|
||||
round(real_pnl, 2),
|
||||
)
|
||||
|
||||
|
||||
def _aggregate_holding_range(profile: ShadowProfile) -> tuple[float, float]:
|
||||
"""Union holding-day ranges across all rules (lo=min, hi=max)."""
|
||||
if not profile.rules:
|
||||
return (1.0, 30.0)
|
||||
los = [r.holding_days_range[0] for r in profile.rules]
|
||||
his = [r.holding_days_range[1] for r in profile.rules]
|
||||
return (float(min(los)), float(max(his)))
|
||||
|
||||
|
||||
def _overtrading_pnl(
|
||||
*,
|
||||
profile: ShadowProfile,
|
||||
roundtrips: list[dict[str, Any]],
|
||||
) -> float:
|
||||
"""Excess-frequency PnL: trades beyond the shadow's expected budget.
|
||||
|
||||
Shadow runs roughly 1 trade per ``2 * median_hold_days`` bars. We
|
||||
compare against the user's actual roundtrip count over the same span.
|
||||
Excess trades' PnL is totaled with a negative sign (shadow would've
|
||||
skipped them, so real PnL — positive or negative — is "noise").
|
||||
"""
|
||||
if not roundtrips:
|
||||
return 0.0
|
||||
median_hold, _ = profile.typical_holding_days
|
||||
if median_hold <= 0:
|
||||
return 0.0
|
||||
span_days = (
|
||||
pd.Timestamp(roundtrips[-1]["sell_dt"]) - pd.Timestamp(roundtrips[0]["buy_dt"])
|
||||
).total_seconds() / 86400.0
|
||||
expected = max(1.0, span_days / max(2 * median_hold, 1.0))
|
||||
actual = len(roundtrips)
|
||||
if actual <= expected:
|
||||
return 0.0
|
||||
# Penalize the cheapest (lowest |pnl|) extras — those look like noise.
|
||||
extras = sorted(roundtrips, key=lambda rt: abs(float(rt["pnl"])))
|
||||
extra_count = int(actual - expected)
|
||||
extra_pnl = sum(float(rt["pnl"]) for rt in extras[:extra_count])
|
||||
return -extra_pnl
|
||||
|
||||
|
||||
__all__ = [
|
||||
"SUPPORTED_MARKETS",
|
||||
"flatten_codes",
|
||||
"load_cached_result",
|
||||
"run_shadow_backtest",
|
||||
"select_multi_market_codes",
|
||||
]
|
||||
|
||||
|
||||
# Re-export for convenience (see __init__.py).
|
||||
def _touch_replace_reexport(): # pragma: no cover
|
||||
return replace
|
||||
@@ -0,0 +1,184 @@
|
||||
"""Shadow Account — code generation (rules → signal_engine.py + config.json).
|
||||
|
||||
Inputs are always a ``ShadowProfile`` (contract-stable). Outputs are:
|
||||
* ``signal_engine.py`` source, validated with ``ast.parse`` + a shape
|
||||
check on ``class SignalEngine.generate``.
|
||||
* ``config.json`` dict, ready to drop into a run_dir.
|
||||
|
||||
No external I/O here — callers (backtester) are responsible for writing
|
||||
files and launching ``run_backtest``.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import ast
|
||||
import json
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from jinja2 import Environment, FileSystemLoader, select_autoescape
|
||||
|
||||
from src.shadow_account.models import ShadowProfile, ShadowRule
|
||||
|
||||
_TEMPLATES_DIR = Path(__file__).parent / "templates"
|
||||
_SIGNAL_ENGINE_TEMPLATE = "signal_engine.py.j2"
|
||||
|
||||
|
||||
def _env() -> Environment:
|
||||
"""Jinja2 environment rooted at our templates directory."""
|
||||
return Environment(
|
||||
loader=FileSystemLoader(str(_TEMPLATES_DIR)),
|
||||
autoescape=select_autoescape(enabled_extensions=("html", "xml")),
|
||||
trim_blocks=True,
|
||||
lstrip_blocks=True,
|
||||
)
|
||||
|
||||
|
||||
def _rule_to_context(rule: ShadowRule) -> dict[str, Any]:
|
||||
"""Flatten a ShadowRule into the scalar fields the template consumes."""
|
||||
market = str(rule.entry_condition.get("market", "other"))
|
||||
hour = rule.entry_condition.get("entry_hour") or {}
|
||||
hold_lo, hold_hi = rule.holding_days_range
|
||||
hold_days = max(1, int(round((hold_lo + hold_hi) / 2)))
|
||||
return {
|
||||
"rule_id": rule.rule_id,
|
||||
"market": market,
|
||||
"entry_hour_min": int(hour.get("min", 0)),
|
||||
"entry_hour_max": int(hour.get("max", 23)),
|
||||
"hold_days": hold_days,
|
||||
"weight": float(rule.weight),
|
||||
}
|
||||
|
||||
|
||||
def render_signal_engine(profile: ShadowProfile) -> str:
|
||||
"""Render the SignalEngine Python source for a profile.
|
||||
|
||||
Args:
|
||||
profile: ShadowProfile carrying the rules to replay.
|
||||
|
||||
Returns:
|
||||
Python source string. The caller is expected to ``validate_generated``
|
||||
before writing to disk.
|
||||
"""
|
||||
template = _env().get_template(_SIGNAL_ENGINE_TEMPLATE)
|
||||
return template.render(
|
||||
shadow_id=profile.shadow_id,
|
||||
profitable_roundtrips=profile.profitable_roundtrips,
|
||||
date_range=list(profile.date_range),
|
||||
preferred_markets=list(profile.preferred_markets),
|
||||
rules=[_rule_to_context(r) for r in profile.rules],
|
||||
)
|
||||
|
||||
|
||||
def validate_generated(source: str) -> tuple[bool, str]:
|
||||
"""Static-check a generated signal_engine source.
|
||||
|
||||
Checks:
|
||||
1. ``ast.parse`` succeeds.
|
||||
2. Module defines ``class SignalEngine``.
|
||||
3. ``SignalEngine`` has a ``generate`` method with one positional
|
||||
arg besides self.
|
||||
|
||||
Returns:
|
||||
(ok, error_msg). ``error_msg`` is empty on success.
|
||||
"""
|
||||
try:
|
||||
tree = ast.parse(source)
|
||||
except SyntaxError as exc:
|
||||
return False, f"SyntaxError: {exc}"
|
||||
|
||||
signal_cls: ast.ClassDef | None = None
|
||||
for node in ast.walk(tree):
|
||||
if isinstance(node, ast.ClassDef) and node.name == "SignalEngine":
|
||||
signal_cls = node
|
||||
break
|
||||
if signal_cls is None:
|
||||
return False, "class SignalEngine not found"
|
||||
|
||||
generate: ast.FunctionDef | None = None
|
||||
for node in signal_cls.body:
|
||||
if isinstance(node, ast.FunctionDef) and node.name == "generate":
|
||||
generate = node
|
||||
break
|
||||
if generate is None:
|
||||
return False, "SignalEngine.generate method not found"
|
||||
|
||||
non_self_args = [a for a in generate.args.args if a.arg != "self"]
|
||||
if len(non_self_args) < 1:
|
||||
return False, "SignalEngine.generate must accept a data_map argument"
|
||||
return True, ""
|
||||
|
||||
|
||||
def render_config(
|
||||
profile: ShadowProfile,
|
||||
*,
|
||||
codes: list[str],
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
source: str = "auto",
|
||||
initial_capital: float = 1_000_000.0,
|
||||
interval: str = "1D",
|
||||
extra: dict[str, Any] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
"""Build the ``config.json`` dict for a shadow backtest run.
|
||||
|
||||
Args:
|
||||
profile: ShadowProfile (used only for metadata, not for engine logic).
|
||||
codes: Symbols to backtest across.
|
||||
start_date / end_date: ISO dates.
|
||||
source: Loader source; ``auto`` routes by symbol suffix.
|
||||
initial_capital: Starting cash.
|
||||
interval: Bar size (daily default).
|
||||
extra: Arbitrary overrides merged last.
|
||||
"""
|
||||
cfg: dict[str, Any] = {
|
||||
"source": source,
|
||||
"codes": codes,
|
||||
"start_date": start_date,
|
||||
"end_date": end_date,
|
||||
"interval": interval,
|
||||
"initial_capital": initial_capital,
|
||||
"engine": "daily",
|
||||
"shadow_id": profile.shadow_id,
|
||||
}
|
||||
if extra:
|
||||
cfg.update(extra)
|
||||
return cfg
|
||||
|
||||
|
||||
def write_run_dir(
|
||||
profile: ShadowProfile,
|
||||
run_dir: Path,
|
||||
*,
|
||||
codes: list[str],
|
||||
start_date: str,
|
||||
end_date: str,
|
||||
source: str = "auto",
|
||||
initial_capital: float = 1_000_000.0,
|
||||
) -> Path:
|
||||
"""Materialize a full run_dir with ``code/signal_engine.py`` + ``config.json``.
|
||||
|
||||
Raises:
|
||||
ValueError: Generated signal_engine fails static validation.
|
||||
"""
|
||||
run_dir = Path(run_dir)
|
||||
(run_dir / "code").mkdir(parents=True, exist_ok=True)
|
||||
|
||||
source_code = render_signal_engine(profile)
|
||||
ok, err = validate_generated(source_code)
|
||||
if not ok:
|
||||
raise ValueError(f"Generated signal_engine failed validation: {err}")
|
||||
|
||||
(run_dir / "code" / "signal_engine.py").write_text(source_code, encoding="utf-8")
|
||||
cfg = render_config(
|
||||
profile,
|
||||
codes=codes,
|
||||
start_date=start_date,
|
||||
end_date=end_date,
|
||||
source=source,
|
||||
initial_capital=initial_capital,
|
||||
)
|
||||
(run_dir / "config.json").write_text(
|
||||
json.dumps(cfg, ensure_ascii=False, indent=2), encoding="utf-8",
|
||||
)
|
||||
return run_dir
|
||||
@@ -0,0 +1,371 @@
|
||||
"""Shadow Account — strategy extraction from profitable roundtrips.
|
||||
|
||||
Pipeline:
|
||||
trades_df → FIFO pair → filter (pnl > 0) → feature engineer
|
||||
→ KMeans cluster (k auto 2-5) → per-cluster decision tree (max_depth=3)
|
||||
→ path extraction → structured entry_condition dict
|
||||
→ LLM-light natural-language translation (template fallback if no LLM)
|
||||
|
||||
Design constraints:
|
||||
* No external price-data calls in v1. All features are derivable from
|
||||
the journal itself (holding_days, pnl_pct, entry hour/weekday, market).
|
||||
Price-dependent features (prior_N_return, rsi) are stubbed with None
|
||||
and dropped from the feature matrix if unavailable.
|
||||
* Must survive tiny samples: <5 profitable roundtrips → explicit error.
|
||||
<2 clusters → degrade to a single-cluster heuristic rule.
|
||||
* Rules are immutable ShadowRule objects — codegen's only input.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
from src.shadow_account.models import ShadowProfile, ShadowRule
|
||||
from src.shadow_account.storage import hash_journal, new_shadow_id, now_iso
|
||||
from src.tools.trade_journal_parsers import parse_file, records_to_dataframe
|
||||
from src.tools.trade_journal_tool import pair_trades_fifo
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
MIN_PROFITABLE_ROUNDTRIPS = 5
|
||||
DEFAULT_MAX_RULES = 5
|
||||
DEFAULT_MIN_SUPPORT = 3
|
||||
_NUMERIC_FEATURES = ("holding_days", "pnl_pct", "entry_hour", "entry_weekday")
|
||||
_CATEGORICAL_FEATURES = ("market",)
|
||||
|
||||
|
||||
# ---------------- Public API ----------------
|
||||
|
||||
def extract_shadow_profile(
|
||||
journal_path: str | Path,
|
||||
*,
|
||||
min_support: int = DEFAULT_MIN_SUPPORT,
|
||||
max_rules: int = DEFAULT_MAX_RULES,
|
||||
llm_translator: Any | None = None,
|
||||
) -> ShadowProfile:
|
||||
"""Extract a ShadowProfile from a broker journal file.
|
||||
|
||||
Args:
|
||||
journal_path: CSV/Excel exported from a supported broker.
|
||||
min_support: Minimum profitable roundtrips backing any single rule.
|
||||
max_rules: Cap on the number of rules returned.
|
||||
llm_translator: Optional callable (dict) -> str for translating
|
||||
structured entry_condition into natural-language text. If None,
|
||||
a deterministic f-string fallback is used.
|
||||
|
||||
Returns:
|
||||
ShadowProfile (not yet persisted — caller decides whether to save).
|
||||
|
||||
Raises:
|
||||
ValueError: Fewer than MIN_PROFITABLE_ROUNDTRIPS profitable roundtrips.
|
||||
"""
|
||||
path = Path(journal_path)
|
||||
fmt, records = parse_file(path)
|
||||
if not records:
|
||||
raise ValueError(f"No trade records parsed from {path} (format={fmt})")
|
||||
trades_df = records_to_dataframe(records)
|
||||
|
||||
roundtrips = pair_trades_fifo(trades_df)
|
||||
total = len(roundtrips)
|
||||
if total == 0:
|
||||
raise ValueError("No complete buy→sell roundtrips found in journal.")
|
||||
|
||||
profitable = [rt for rt in roundtrips if rt["pnl"] > 0]
|
||||
if len(profitable) < MIN_PROFITABLE_ROUNDTRIPS:
|
||||
raise ValueError(
|
||||
f"Insufficient profitable roundtrips: {len(profitable)} "
|
||||
f"(need ≥{MIN_PROFITABLE_ROUNDTRIPS}).",
|
||||
)
|
||||
|
||||
features_df = _compute_features(profitable, trades_df)
|
||||
rules = _extract_rules(
|
||||
features_df,
|
||||
min_support=min_support,
|
||||
max_rules=max_rules,
|
||||
llm_translator=llm_translator,
|
||||
)
|
||||
|
||||
source_market = _dominant(trades_df["market"])
|
||||
preferred_markets = tuple(trades_df["market"].value_counts().index.tolist())
|
||||
hold = features_df["holding_days"].dropna()
|
||||
typical_holding = (
|
||||
round(float(hold.median()), 2) if len(hold) else 0.0,
|
||||
round(float(hold.quantile(0.75)), 2) if len(hold) else 0.0,
|
||||
)
|
||||
date_range = (
|
||||
str(trades_df["datetime"].min()),
|
||||
str(trades_df["datetime"].max()),
|
||||
)
|
||||
profile_text = _render_profile_text(
|
||||
total_profitable=len(profitable),
|
||||
total_all=total,
|
||||
typical_holding=typical_holding,
|
||||
source_market=source_market,
|
||||
preferred_markets=preferred_markets,
|
||||
)
|
||||
|
||||
return ShadowProfile(
|
||||
shadow_id=new_shadow_id(),
|
||||
created_at=now_iso(),
|
||||
journal_hash=hash_journal(path),
|
||||
source_market=source_market,
|
||||
profitable_roundtrips=len(profitable),
|
||||
total_roundtrips=total,
|
||||
date_range=date_range,
|
||||
profile_text=profile_text,
|
||||
rules=tuple(rules),
|
||||
preferred_markets=preferred_markets,
|
||||
typical_holding_days=typical_holding,
|
||||
)
|
||||
|
||||
|
||||
# ---------------- Feature engineering ----------------
|
||||
|
||||
def _compute_features(
|
||||
roundtrips: list[dict[str, Any]],
|
||||
trades_df: pd.DataFrame,
|
||||
) -> pd.DataFrame:
|
||||
"""Compute a features row per profitable roundtrip.
|
||||
|
||||
Columns: symbol, market, holding_days, pnl, pnl_pct, entry_hour,
|
||||
entry_weekday, buy_dt, sell_dt.
|
||||
"""
|
||||
market_by_symbol = (
|
||||
trades_df.drop_duplicates("symbol").set_index("symbol")["market"].to_dict()
|
||||
)
|
||||
rows: list[dict[str, Any]] = []
|
||||
for rt in roundtrips:
|
||||
buy_dt = pd.Timestamp(rt["buy_dt"])
|
||||
sell_dt = pd.Timestamp(rt["sell_dt"])
|
||||
rows.append({
|
||||
"symbol": rt["symbol"],
|
||||
"market": market_by_symbol.get(rt["symbol"], "other"),
|
||||
"holding_days": float(rt["hold_days"]),
|
||||
"pnl": float(rt["pnl"]),
|
||||
"pnl_pct": float(rt["pnl_pct"]),
|
||||
"entry_hour": int(buy_dt.hour),
|
||||
"entry_weekday": int(buy_dt.weekday()),
|
||||
"buy_dt": buy_dt,
|
||||
"sell_dt": sell_dt,
|
||||
})
|
||||
return pd.DataFrame(rows)
|
||||
|
||||
|
||||
# ---------------- Cluster + decision-tree rule extraction ----------------
|
||||
|
||||
def _extract_rules(
|
||||
features_df: pd.DataFrame,
|
||||
*,
|
||||
min_support: int,
|
||||
max_rules: int,
|
||||
llm_translator: Any | None,
|
||||
) -> list[ShadowRule]:
|
||||
"""Cluster profitable roundtrips, derive one rule per dense cluster."""
|
||||
if len(features_df) < min_support:
|
||||
return [_heuristic_single_rule(features_df, min_support, llm_translator)]
|
||||
|
||||
cluster_labels = _auto_cluster(features_df, max_k=min(max_rules, 5))
|
||||
rules: list[ShadowRule] = []
|
||||
total_profitable = len(features_df)
|
||||
used_markets: set[str] = set()
|
||||
|
||||
for cluster_id in sorted(set(cluster_labels)):
|
||||
cluster_mask = cluster_labels == cluster_id
|
||||
cluster_df = features_df[cluster_mask]
|
||||
if len(cluster_df) < min_support:
|
||||
continue
|
||||
rule = _cluster_to_rule(
|
||||
cluster_df=cluster_df,
|
||||
rule_index=len(rules) + 1,
|
||||
total_profitable=total_profitable,
|
||||
llm_translator=llm_translator,
|
||||
)
|
||||
# Deduplicate near-identical rules (same market + same holding band)
|
||||
key = (rule.entry_condition.get("market"), rule.holding_days_range)
|
||||
if key in used_markets:
|
||||
continue
|
||||
used_markets.add(key)
|
||||
rules.append(rule)
|
||||
if len(rules) >= max_rules:
|
||||
break
|
||||
|
||||
if not rules:
|
||||
rules = [_heuristic_single_rule(features_df, min_support, llm_translator)]
|
||||
return rules
|
||||
|
||||
|
||||
def _auto_cluster(features_df: pd.DataFrame, *, max_k: int) -> np.ndarray:
|
||||
"""Pick a cluster count via simple silhouette heuristic (fallback k=2).
|
||||
|
||||
Uses only numeric features; scales by z-score to avoid holding_days
|
||||
dominating pnl_pct.
|
||||
"""
|
||||
from sklearn.cluster import KMeans
|
||||
from sklearn.preprocessing import StandardScaler
|
||||
|
||||
numeric = features_df[list(_NUMERIC_FEATURES)].astype(float).to_numpy()
|
||||
if len(numeric) <= 2 or max_k < 2:
|
||||
return np.zeros(len(numeric), dtype=int)
|
||||
scaled = StandardScaler().fit_transform(numeric)
|
||||
|
||||
best_k, best_score = 2, -1.0
|
||||
try:
|
||||
from sklearn.metrics import silhouette_score
|
||||
for k in range(2, min(max_k, len(numeric) - 1) + 1):
|
||||
labels = KMeans(n_clusters=k, n_init=5, random_state=42).fit_predict(scaled)
|
||||
if len(set(labels)) < 2:
|
||||
continue
|
||||
score = silhouette_score(scaled, labels)
|
||||
if score > best_score:
|
||||
best_k, best_score = k, score
|
||||
except Exception as exc: # pragma: no cover — sklearn edge cases
|
||||
logger.debug("silhouette selection failed, fallback k=2: %s", exc)
|
||||
|
||||
return KMeans(n_clusters=best_k, n_init=5, random_state=42).fit_predict(scaled)
|
||||
|
||||
|
||||
def _cluster_to_rule(
|
||||
*,
|
||||
cluster_df: pd.DataFrame,
|
||||
rule_index: int,
|
||||
total_profitable: int,
|
||||
llm_translator: Any | None,
|
||||
) -> ShadowRule:
|
||||
"""Summarize a cluster as one ShadowRule.
|
||||
|
||||
Entry condition uses p10–p90 numeric bounds + dominant market. This is
|
||||
lighter than a decision tree and stays interpretable with tiny samples;
|
||||
we can swap to DecisionTreeClassifier in v2 when features widen.
|
||||
"""
|
||||
market = _dominant(cluster_df["market"])
|
||||
hold_days = cluster_df["holding_days"]
|
||||
hold_lo = max(1, int(round(float(hold_days.quantile(0.10)))))
|
||||
hold_hi = max(hold_lo, int(round(float(hold_days.quantile(0.90)))))
|
||||
hours = cluster_df["entry_hour"]
|
||||
hour_lo = int(round(float(hours.quantile(0.10))))
|
||||
hour_hi = int(round(float(hours.quantile(0.90))))
|
||||
|
||||
entry_condition: dict[str, Any] = {
|
||||
"market": market,
|
||||
"entry_hour": {"min": hour_lo, "max": hour_hi},
|
||||
}
|
||||
exit_condition: dict[str, Any] = {
|
||||
"holding_days": {"min": hold_lo, "max": hold_hi},
|
||||
}
|
||||
|
||||
samples = tuple(
|
||||
f"{row.symbol}@{pd.Timestamp(row.buy_dt).date().isoformat()}"
|
||||
for row in cluster_df.head(3).itertuples(index=False)
|
||||
)
|
||||
support = int(len(cluster_df))
|
||||
coverage = round(support / max(total_profitable, 1), 3)
|
||||
|
||||
human = _translate_rule(
|
||||
entry_condition=entry_condition,
|
||||
exit_condition=exit_condition,
|
||||
holding_range=(hold_lo, hold_hi),
|
||||
translator=llm_translator,
|
||||
)
|
||||
|
||||
return ShadowRule(
|
||||
rule_id=f"R{rule_index}",
|
||||
human_text=human,
|
||||
entry_condition=entry_condition,
|
||||
exit_condition=exit_condition,
|
||||
holding_days_range=(hold_lo, hold_hi),
|
||||
support_count=support,
|
||||
coverage_rate=coverage,
|
||||
sample_trades=samples,
|
||||
)
|
||||
|
||||
|
||||
def _heuristic_single_rule(
|
||||
features_df: pd.DataFrame,
|
||||
min_support: int,
|
||||
llm_translator: Any | None,
|
||||
) -> ShadowRule:
|
||||
"""Degenerate fallback when clustering/tree yield nothing usable."""
|
||||
return _cluster_to_rule(
|
||||
cluster_df=features_df,
|
||||
rule_index=1,
|
||||
total_profitable=max(len(features_df), min_support),
|
||||
llm_translator=llm_translator,
|
||||
)
|
||||
|
||||
|
||||
# ---------------- Natural-language translation ----------------
|
||||
|
||||
_MARKET_LABELS = {
|
||||
"china_a": "China A-share",
|
||||
"us": "US equity",
|
||||
"hk": "HK equity",
|
||||
"crypto": "Crypto",
|
||||
"other": "Other",
|
||||
}
|
||||
|
||||
RULE_TEXT_MAX = 80
|
||||
|
||||
|
||||
def _translate_rule(
|
||||
*,
|
||||
entry_condition: dict[str, Any],
|
||||
exit_condition: dict[str, Any],
|
||||
holding_range: tuple[int, int],
|
||||
translator: Any | None,
|
||||
) -> str:
|
||||
"""Turn a structured rule dict into a concise English sentence (<=80 chars)."""
|
||||
if translator is not None:
|
||||
try:
|
||||
text = translator({
|
||||
"entry_condition": entry_condition,
|
||||
"exit_condition": exit_condition,
|
||||
"holding_range": holding_range,
|
||||
})
|
||||
if isinstance(text, str) and text.strip():
|
||||
return text.strip()[:RULE_TEXT_MAX]
|
||||
except Exception as exc: # pragma: no cover — LLM failure, fallback
|
||||
logger.warning("LLM rule translator failed, falling back: %s", exc)
|
||||
|
||||
market_label = _MARKET_LABELS.get(entry_condition.get("market", "other"), "Other")
|
||||
hour_range = entry_condition.get("entry_hour", {})
|
||||
hour_text = ""
|
||||
if hour_range:
|
||||
lo, hi = hour_range.get("min"), hour_range.get("max")
|
||||
hour_text = f" at {lo}:00" if lo == hi else f" between {lo}:00-{hi}:00"
|
||||
hold_lo, hold_hi = holding_range
|
||||
hold_text = f"hold {hold_lo}-{hold_hi}d" if hold_lo != hold_hi else f"hold {hold_lo}d"
|
||||
entry_text = f"Enter {market_label}{hour_text}"
|
||||
return f"{entry_text}, {hold_text}"[:RULE_TEXT_MAX]
|
||||
|
||||
|
||||
# ---------------- Utilities ----------------
|
||||
|
||||
def _dominant(series: pd.Series) -> str:
|
||||
"""Most frequent value in a series, or the first if tied."""
|
||||
if series.empty:
|
||||
return "other"
|
||||
return str(series.value_counts().idxmax())
|
||||
|
||||
|
||||
def _render_profile_text(
|
||||
*,
|
||||
total_profitable: int,
|
||||
total_all: int,
|
||||
typical_holding: tuple[float, float],
|
||||
source_market: str,
|
||||
preferred_markets: tuple[str, ...],
|
||||
) -> str:
|
||||
"""Build the Section 1 one-paragraph portrait (English)."""
|
||||
median, p75 = typical_holding
|
||||
markets_label = ", ".join(_MARKET_LABELS.get(m, m) for m in preferred_markets[:3])
|
||||
source_label = _MARKET_LABELS.get(source_market, source_market)
|
||||
return (
|
||||
f"{total_profitable} of your {total_all} closed roundtrips were profitable. "
|
||||
f"Primary market: {source_label} (also active in {markets_label}). "
|
||||
f"Median holding period {median:.1f}d; most positions closed within {p75:.1f}d."
|
||||
)
|
||||
@@ -0,0 +1,143 @@
|
||||
"""Shadow Account — font handling for PDF rendering.
|
||||
|
||||
Tries to guarantee that Chinese characters render; falls back to DejaVu Sans
|
||||
(English-only, logs a warning) when CJK resources are unavailable. Matplotlib
|
||||
and weasyprint both consume ``cjk_font_path()`` or at least see the family
|
||||
name via ``apply_matplotlib_cjk_font``.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import os
|
||||
import shutil
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_NOTO_URL = (
|
||||
"https://github.com/notofonts/noto-cjk/raw/main/Sans/OTF/SimplifiedChinese/"
|
||||
"NotoSansCJKsc-Regular.otf"
|
||||
)
|
||||
_FONT_NAME = "NotoSansCJKsc-Regular.otf"
|
||||
_FALLBACK_FAMILY = "DejaVu Sans"
|
||||
|
||||
|
||||
def fonts_dir() -> Path:
|
||||
"""Return the Shadow Account fonts cache dir (auto-created)."""
|
||||
d = Path.home() / ".vibe-trading" / "fonts"
|
||||
d.mkdir(parents=True, exist_ok=True)
|
||||
return d
|
||||
|
||||
|
||||
def _system_cjk_candidates() -> list[Path]:
|
||||
"""Enumerate locally-installed CJK fonts we can reuse without downloading."""
|
||||
candidates: list[Path] = []
|
||||
env = os.environ
|
||||
windir = env.get("WINDIR") or env.get("SystemRoot")
|
||||
if windir:
|
||||
win_fonts = Path(windir) / "Fonts"
|
||||
for name in (
|
||||
"msyh.ttc", "msyh.ttf", "msyhbd.ttc",
|
||||
"simhei.ttf", "simsun.ttc", "simkai.ttf",
|
||||
"NotoSansCJK-Regular.ttc",
|
||||
):
|
||||
candidates.append(win_fonts / name)
|
||||
for p in (
|
||||
"/System/Library/Fonts/PingFang.ttc",
|
||||
"/System/Library/Fonts/STHeiti Light.ttc",
|
||||
"/usr/share/fonts/opentype/noto/NotoSansCJK-Regular.ttc",
|
||||
"/usr/share/fonts/truetype/wqy/wqy-microhei.ttc",
|
||||
):
|
||||
candidates.append(Path(p))
|
||||
return candidates
|
||||
|
||||
|
||||
def cjk_font_path(*, allow_download: bool = True, timeout: float = 10.0) -> Optional[Path]:
|
||||
"""Resolve a CJK font file path.
|
||||
|
||||
Resolution order:
|
||||
1. Cached copy in ``fonts_dir()``.
|
||||
2. First available system font from ``_system_cjk_candidates``.
|
||||
3. Download Noto CJK (optional).
|
||||
|
||||
Returns ``None`` when every option fails — callers should then fall
|
||||
back to the DejaVu family.
|
||||
"""
|
||||
cached = fonts_dir() / _FONT_NAME
|
||||
if cached.exists() and cached.stat().st_size > 0:
|
||||
return cached
|
||||
|
||||
for candidate in _system_cjk_candidates():
|
||||
if candidate.exists():
|
||||
try:
|
||||
shutil.copy(candidate, cached)
|
||||
return cached
|
||||
except OSError as exc:
|
||||
logger.debug("Failed to cache system font %s: %s", candidate, exc)
|
||||
|
||||
if not allow_download:
|
||||
return None
|
||||
|
||||
try:
|
||||
import urllib.request
|
||||
req = urllib.request.Request(_NOTO_URL, headers={"User-Agent": "vibe-trading"})
|
||||
with urllib.request.urlopen(req, timeout=timeout) as resp:
|
||||
cached.write_bytes(resp.read())
|
||||
if cached.stat().st_size > 0:
|
||||
return cached
|
||||
except Exception as exc: # pragma: no cover — network-dependent
|
||||
logger.warning("CJK font download failed (%s); falling back to DejaVu.", exc)
|
||||
|
||||
return None
|
||||
|
||||
|
||||
def apply_matplotlib_cjk_font() -> str:
|
||||
"""Configure matplotlib's default font family.
|
||||
|
||||
Returns the family name actually installed (``"sans-serif"`` meaning the
|
||||
CJK face is resolved, or ``_FALLBACK_FAMILY`` when we gave up).
|
||||
"""
|
||||
try:
|
||||
import matplotlib
|
||||
matplotlib.use("Agg") # safe for headless rendering
|
||||
from matplotlib import font_manager as fm
|
||||
import matplotlib.pyplot as plt
|
||||
except Exception as exc: # pragma: no cover — matplotlib optional
|
||||
logger.warning("matplotlib unavailable: %s", exc)
|
||||
return _FALLBACK_FAMILY
|
||||
|
||||
path = cjk_font_path()
|
||||
if path is None:
|
||||
plt.rcParams["font.family"] = _FALLBACK_FAMILY
|
||||
return _FALLBACK_FAMILY
|
||||
|
||||
try:
|
||||
fm.fontManager.addfont(str(path))
|
||||
prop = fm.FontProperties(fname=str(path))
|
||||
family = prop.get_name()
|
||||
plt.rcParams["font.family"] = family
|
||||
plt.rcParams["axes.unicode_minus"] = False
|
||||
return family
|
||||
except Exception as exc:
|
||||
logger.warning("Failed to register %s with matplotlib: %s", path, exc)
|
||||
plt.rcParams["font.family"] = _FALLBACK_FAMILY
|
||||
return _FALLBACK_FAMILY
|
||||
|
||||
|
||||
def cjk_css_font_face() -> str:
|
||||
"""Emit an ``@font-face`` CSS block weasyprint can bundle.
|
||||
|
||||
Returns an empty string if no CJK font is resolvable.
|
||||
"""
|
||||
path = cjk_font_path()
|
||||
if path is None:
|
||||
return ""
|
||||
uri = path.resolve().as_uri()
|
||||
return (
|
||||
"@font-face {\n"
|
||||
" font-family: 'Shadow CJK';\n"
|
||||
f" src: url('{uri}');\n"
|
||||
"}\n"
|
||||
)
|
||||
@@ -0,0 +1,103 @@
|
||||
"""Shadow Account data contracts (frozen dataclasses).
|
||||
|
||||
See `docs/shadow-account-spec.md` for the full contract. These types are the
|
||||
stable boundary between extractor / codegen / backtester / reporter.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import asdict, dataclass, field
|
||||
from typing import Any
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ShadowRule:
|
||||
"""One human-readable if-then rule distilled from profitable roundtrips.
|
||||
|
||||
Attributes:
|
||||
rule_id: Stable ID like "R1", "R2".
|
||||
human_text: Chinese natural-language description (<=30 chars).
|
||||
entry_condition: Structured condition dict for codegen. Keys are
|
||||
feature names (e.g. "prior_5d_return", "market"); values are
|
||||
either scalars or (op, value) tuples (e.g. ("<=", -0.08)).
|
||||
exit_condition: Structured exit condition dict.
|
||||
holding_days_range: (min, max) integer days.
|
||||
support_count: Number of profitable roundtrips supporting this rule.
|
||||
coverage_rate: Fraction of all profitable roundtrips this rule covers.
|
||||
sample_trades: Representative "<symbol>@<date>" strings.
|
||||
weight: Signal weight for codegen (default 1.0).
|
||||
"""
|
||||
|
||||
rule_id: str
|
||||
human_text: str
|
||||
entry_condition: dict[str, Any]
|
||||
exit_condition: dict[str, Any]
|
||||
holding_days_range: tuple[int, int]
|
||||
support_count: int
|
||||
coverage_rate: float
|
||||
sample_trades: tuple[str, ...]
|
||||
weight: float = 1.0
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ShadowProfile:
|
||||
"""User's extracted trading shadow.
|
||||
|
||||
Attributes:
|
||||
shadow_id: "shadow_<8-hex>" unique ID.
|
||||
created_at: ISO8601 UTC timestamp.
|
||||
journal_hash: SHA1 of the source journal content for idempotency.
|
||||
source_market: Primary market from the journal ("china_a" etc.).
|
||||
profitable_roundtrips: Number of roundtrips used for extraction.
|
||||
total_roundtrips: Total roundtrips in journal.
|
||||
date_range: (start_iso, end_iso) of the journal.
|
||||
profile_text: One-paragraph Chinese portrait for Section 1.
|
||||
rules: Tuple of 3-5 ShadowRule.
|
||||
preferred_markets: Markets the user actually traded, frequency-sorted.
|
||||
typical_holding_days: (median, p75) in days.
|
||||
"""
|
||||
|
||||
shadow_id: str
|
||||
created_at: str
|
||||
journal_hash: str
|
||||
source_market: str
|
||||
profitable_roundtrips: int
|
||||
total_roundtrips: int
|
||||
date_range: tuple[str, str]
|
||||
profile_text: str
|
||||
rules: tuple[ShadowRule, ...]
|
||||
preferred_markets: tuple[str, ...]
|
||||
typical_holding_days: tuple[float, float]
|
||||
|
||||
def to_dict(self) -> dict[str, Any]:
|
||||
"""Serialize to JSON-safe dict."""
|
||||
return asdict(self)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class AttributionBreakdown:
|
||||
"""Delta PnL attribution between user's realized trades and shadow.
|
||||
|
||||
All PnL fields are in the journal's account currency.
|
||||
"""
|
||||
|
||||
missed_signals_pnl: float
|
||||
noise_trades_pnl: float
|
||||
early_exit_pnl: float
|
||||
late_exit_pnl: float
|
||||
overtrading_pnl: float
|
||||
counterfactual_trades: tuple[dict[str, Any], ...] = field(default_factory=tuple)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ShadowBacktestResult:
|
||||
"""Output of multi-market shadow backtest + attribution."""
|
||||
|
||||
shadow_id: str
|
||||
per_market: dict[str, dict[str, float]]
|
||||
combined: dict[str, float]
|
||||
equity_curves: dict[str, list[tuple[str, float]]]
|
||||
attribution: AttributionBreakdown
|
||||
shadow_total_pnl: float
|
||||
real_total_pnl: float
|
||||
delta_pnl: float
|
||||
@@ -0,0 +1,335 @@
|
||||
"""Shadow Account — 8-section report rendering (HTML + optional PDF).
|
||||
|
||||
The pipeline:
|
||||
ShadowProfile + ShadowBacktestResult (+ optional today signals)
|
||||
→ `_build_sections` build a strict dict for the template
|
||||
→ `_render_charts` matplotlib PNG files on disk
|
||||
→ Jinja2 render HTML
|
||||
→ weasyprint → PDF (or HTML-only if weasyprint unusable)
|
||||
|
||||
Design:
|
||||
* No hard dependency on weasyprint at import time — if importing or
|
||||
rendering fails, we keep the HTML artifact and return its path.
|
||||
* Charts are optional — any matplotlib failure downgrades gracefully
|
||||
(that section just omits its `<img>`).
|
||||
* Layout/style live in `templates/shadow_report.{html,css}`; this module
|
||||
only decides *what* data to feed them.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
from base64 import b64encode
|
||||
from dataclasses import asdict
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from jinja2 import Environment, FileSystemLoader, select_autoescape
|
||||
|
||||
from src.shadow_account.fonts import apply_matplotlib_cjk_font, cjk_css_font_face
|
||||
from src.shadow_account.models import ShadowBacktestResult, ShadowProfile
|
||||
from src.shadow_account.storage import reports_dir
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_TEMPLATES_DIR = Path(__file__).parent / "templates"
|
||||
_HTML_TEMPLATE = "shadow_report.html"
|
||||
_CSS_TEMPLATE = "shadow_report.css"
|
||||
|
||||
_MARKET_LABELS = {
|
||||
"china_a": "China A-share",
|
||||
"us": "US equity",
|
||||
"hk": "HK equity",
|
||||
"crypto": "Crypto",
|
||||
"other": "Other",
|
||||
}
|
||||
|
||||
_REASON_LABELS = {
|
||||
"rule_violation": "Outside any shadow rule",
|
||||
"early_exit": "Exited winner too early",
|
||||
"late_exit": "Held loser too long",
|
||||
}
|
||||
|
||||
|
||||
# ---------------- Public API ----------------
|
||||
|
||||
def render_shadow_report(
|
||||
profile: ShadowProfile,
|
||||
backtest_result: ShadowBacktestResult,
|
||||
*,
|
||||
today_signals: list[dict[str, Any]] | None = None,
|
||||
output_dir: Path | None = None,
|
||||
) -> dict[str, Any]:
|
||||
"""Render the full Shadow Account report.
|
||||
|
||||
Returns:
|
||||
Dict with keys:
|
||||
``html_path`` : rendered HTML (always present)
|
||||
``pdf_path`` : PDF path (present iff weasyprint succeeded)
|
||||
``sections`` : structured payload (for frontend preview)
|
||||
``engine`` : "weasyprint" | "html-only"
|
||||
"""
|
||||
output_dir = Path(output_dir) if output_dir else reports_dir()
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
# Matplotlib setup must happen before any chart renders.
|
||||
apply_matplotlib_cjk_font()
|
||||
|
||||
assets_dir = output_dir / f"{profile.shadow_id}_assets"
|
||||
assets_dir.mkdir(parents=True, exist_ok=True)
|
||||
charts = _render_charts(profile, backtest_result, assets_dir)
|
||||
|
||||
sections = _build_sections(profile, backtest_result, today_signals or [])
|
||||
css = _load_css()
|
||||
|
||||
html = _env().get_template(_HTML_TEMPLATE).render(
|
||||
css=css,
|
||||
charts=charts,
|
||||
market_labels=_MARKET_LABELS,
|
||||
reason_labels=_REASON_LABELS,
|
||||
**sections,
|
||||
)
|
||||
html_path = output_dir / f"{profile.shadow_id}.html"
|
||||
html_path.write_text(html, encoding="utf-8")
|
||||
|
||||
pdf_path, engine = _try_render_pdf(html, output_dir, profile.shadow_id)
|
||||
|
||||
return {
|
||||
"html_path": str(html_path),
|
||||
"pdf_path": str(pdf_path) if pdf_path else None,
|
||||
"sections": sections,
|
||||
"engine": engine,
|
||||
}
|
||||
|
||||
|
||||
# ---------------- Section data ----------------
|
||||
|
||||
def _build_sections(
|
||||
profile: ShadowProfile,
|
||||
result: ShadowBacktestResult,
|
||||
today_signals: list[dict[str, Any]],
|
||||
) -> dict[str, Any]:
|
||||
"""Assemble the strict payload the Jinja template consumes.
|
||||
|
||||
The template expects numeric values for any metrics it formats with
|
||||
``%f`` — so we strip out non-numeric leak-throughs (e.g. ``error``
|
||||
strings inserted when the backtest runner failed). The error is
|
||||
preserved separately under ``combined_error`` so the template can
|
||||
surface it explicitly.
|
||||
"""
|
||||
combined_numeric, combined_error = _split_metrics(result.combined or {})
|
||||
per_market_numeric = {
|
||||
market: _split_metrics(metrics or {})[0]
|
||||
for market, metrics in (result.per_market or {}).items()
|
||||
}
|
||||
return {
|
||||
"profile": profile,
|
||||
"combined_metrics": combined_numeric,
|
||||
"combined_error": combined_error,
|
||||
"per_market_metrics": per_market_numeric,
|
||||
"attribution": result.attribution,
|
||||
"shadow_pnl": result.shadow_total_pnl,
|
||||
"real_pnl": result.real_total_pnl,
|
||||
"delta_pnl": result.delta_pnl,
|
||||
"today_signals": today_signals,
|
||||
}
|
||||
|
||||
|
||||
def _split_metrics(metrics: dict[str, Any]) -> tuple[dict[str, float], str]:
|
||||
"""Partition a metrics dict into (numeric, error_message)."""
|
||||
numeric: dict[str, float] = {}
|
||||
error_parts: list[str] = []
|
||||
for key, value in metrics.items():
|
||||
if isinstance(value, bool):
|
||||
continue
|
||||
if isinstance(value, (int, float)):
|
||||
numeric[key] = float(value)
|
||||
elif isinstance(value, str):
|
||||
error_parts.append(f"{key}: {value}")
|
||||
return numeric, " | ".join(error_parts)
|
||||
|
||||
|
||||
# ---------------- Charts ----------------
|
||||
|
||||
def _render_charts(
|
||||
profile: ShadowProfile,
|
||||
result: ShadowBacktestResult,
|
||||
assets_dir: Path,
|
||||
) -> dict[str, str]:
|
||||
"""Render all charts and return a map section → file URI.
|
||||
|
||||
Any failure is logged and the affected chart is dropped from the map.
|
||||
"""
|
||||
charts: dict[str, str] = {}
|
||||
for name, renderer in (
|
||||
("equity_curve", lambda p: _render_equity_curve(result, p)),
|
||||
("per_market_bar", lambda p: _render_per_market_bar(result, p)),
|
||||
("attribution_waterfall", lambda p: _render_attribution_waterfall(result, p)),
|
||||
):
|
||||
path = assets_dir / f"{name}.png"
|
||||
try:
|
||||
renderer(path)
|
||||
except Exception as exc:
|
||||
logger.warning("Chart %s failed to render: %s", name, exc)
|
||||
continue
|
||||
if path.exists() and path.stat().st_size > 0:
|
||||
charts[name] = path.resolve().as_uri()
|
||||
return charts
|
||||
|
||||
|
||||
def _render_equity_curve(result: ShadowBacktestResult, path: Path) -> None:
|
||||
curve = result.equity_curves.get("combined") or []
|
||||
if not curve:
|
||||
return
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
fig, ax = plt.subplots(figsize=(8, 3), dpi=150)
|
||||
dates = [pt[0] for pt in curve]
|
||||
values = [pt[1] for pt in curve]
|
||||
ax.plot(dates, values, color="#1f7a3a", linewidth=1.3)
|
||||
ax.fill_between(dates, values, color="#1f7a3a", alpha=0.08)
|
||||
ax.set_title("Shadow — Portfolio Equity Curve")
|
||||
ax.set_xlabel("")
|
||||
ax.set_ylabel("Equity")
|
||||
ax.grid(True, linestyle=":", alpha=0.4)
|
||||
# Too many x-ticks looks cluttered; sample down.
|
||||
if len(dates) > 8:
|
||||
step = max(1, len(dates) // 8)
|
||||
ax.set_xticks([dates[i] for i in range(0, len(dates), step)])
|
||||
fig.tight_layout()
|
||||
fig.savefig(path, bbox_inches="tight")
|
||||
plt.close(fig)
|
||||
|
||||
|
||||
def _render_per_market_bar(result: ShadowBacktestResult, path: Path) -> None:
|
||||
if not result.per_market:
|
||||
return
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
markets = list(result.per_market.keys())
|
||||
sharpes = [result.per_market[m].get("sharpe", 0.0) for m in markets]
|
||||
labels = [_MARKET_LABELS.get(m, m) for m in markets]
|
||||
|
||||
fig, ax = plt.subplots(figsize=(8, 3), dpi=150)
|
||||
bars = ax.bar(labels, sharpes, color="#4a5fb0")
|
||||
ax.axhline(0, color="#8a8f99", linewidth=0.8)
|
||||
ax.set_title("Sharpe by Market")
|
||||
ax.grid(True, axis="y", linestyle=":", alpha=0.4)
|
||||
for bar, value in zip(bars, sharpes):
|
||||
ax.text(
|
||||
bar.get_x() + bar.get_width() / 2,
|
||||
bar.get_height(),
|
||||
f"{value:.2f}",
|
||||
ha="center",
|
||||
va="bottom",
|
||||
fontsize=9,
|
||||
)
|
||||
fig.tight_layout()
|
||||
fig.savefig(path, bbox_inches="tight")
|
||||
plt.close(fig)
|
||||
|
||||
|
||||
def _render_attribution_waterfall(result: ShadowBacktestResult, path: Path) -> None:
|
||||
attr = result.attribution
|
||||
components = [
|
||||
("Real PnL", result.real_total_pnl),
|
||||
("Noise Trades", attr.noise_trades_pnl),
|
||||
("Early Exit", attr.early_exit_pnl),
|
||||
("Late Exit", attr.late_exit_pnl),
|
||||
("Overtrading", attr.overtrading_pnl),
|
||||
("Missed Signals", attr.missed_signals_pnl),
|
||||
("Shadow PnL", result.shadow_total_pnl),
|
||||
]
|
||||
if all(value == 0.0 for _, value in components):
|
||||
return
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
labels = [c[0] for c in components]
|
||||
values = [c[1] for c in components]
|
||||
# Waterfall bases: cumulative start for the intermediate bars.
|
||||
bases = [0.0]
|
||||
running = values[0]
|
||||
for v in values[1:-1]:
|
||||
bases.append(running)
|
||||
running += v
|
||||
bases.append(0.0)
|
||||
|
||||
accent = "#4a5fb0"
|
||||
pos = "#1f7a3a"
|
||||
neg = "#c1392b"
|
||||
grid = "#8a8f99"
|
||||
bg = "#ffffff"
|
||||
|
||||
colors = []
|
||||
for idx, v in enumerate(values):
|
||||
if idx in (0, len(values) - 1):
|
||||
colors.append(accent)
|
||||
else:
|
||||
colors.append(pos if v > 0 else neg)
|
||||
|
||||
fig, ax = plt.subplots(figsize=(8, 3.2), dpi=150, facecolor=bg)
|
||||
ax.bar(labels, values, bottom=bases, color=colors, edgecolor="none", width=0.55)
|
||||
ax.axhline(0, color=grid, linewidth=0.8)
|
||||
ax.set_title("Delta Attribution (positive = shadow would outperform)")
|
||||
ax.grid(True, axis="y", linestyle=":", alpha=0.4)
|
||||
plt.setp(ax.get_xticklabels(), rotation=18, ha="right")
|
||||
fig.tight_layout()
|
||||
fig.savefig(path, bbox_inches="tight", facecolor=bg)
|
||||
plt.close(fig)
|
||||
|
||||
|
||||
# ---------------- Templating ----------------
|
||||
|
||||
def _env() -> Environment:
|
||||
return Environment(
|
||||
loader=FileSystemLoader(str(_TEMPLATES_DIR)),
|
||||
autoescape=select_autoescape(enabled_extensions=("html", "xml")),
|
||||
trim_blocks=True,
|
||||
lstrip_blocks=True,
|
||||
)
|
||||
|
||||
|
||||
def _load_css() -> str:
|
||||
"""Load CSS, prepending a CJK ``@font-face`` if we have a font."""
|
||||
css = (_TEMPLATES_DIR / _CSS_TEMPLATE).read_text(encoding="utf-8")
|
||||
font_face = cjk_css_font_face()
|
||||
return font_face + "\n" + css
|
||||
|
||||
|
||||
def _try_render_pdf(
|
||||
html: str, output_dir: Path, shadow_id: str,
|
||||
) -> tuple[Path | None, str]:
|
||||
"""Render PDF via weasyprint, returning (path|None, engine_name)."""
|
||||
try:
|
||||
from weasyprint import HTML # type: ignore[import-not-found]
|
||||
except Exception as exc: # pragma: no cover — import-level failure
|
||||
logger.warning("weasyprint unavailable (%s); HTML-only output.", exc)
|
||||
return None, "html-only"
|
||||
|
||||
pdf_path = output_dir / f"{shadow_id}.pdf"
|
||||
try:
|
||||
HTML(string=html, base_url=str(_TEMPLATES_DIR)).write_pdf(str(pdf_path))
|
||||
except Exception as exc:
|
||||
logger.warning("weasyprint render failed (%s); HTML-only output.", exc)
|
||||
if pdf_path.exists():
|
||||
try:
|
||||
pdf_path.unlink()
|
||||
except OSError:
|
||||
pass
|
||||
return None, "html-only"
|
||||
return pdf_path, "weasyprint"
|
||||
|
||||
|
||||
# ---------------- Convenience ----------------
|
||||
|
||||
def embed_image_as_data_uri(path: Path) -> str:
|
||||
"""Inline an image as a data URI (useful when file URIs are rejected)."""
|
||||
blob = Path(path).read_bytes()
|
||||
encoded = b64encode(blob).decode("ascii")
|
||||
return f"data:image/png;base64,{encoded}"
|
||||
|
||||
|
||||
# Keep this helper exported to simplify downstream inspection.
|
||||
def result_as_dict(result: ShadowBacktestResult) -> dict[str, Any]:
|
||||
"""Dict-serialize a backtest result (handy for frontend debugging)."""
|
||||
return asdict(result)
|
||||
@@ -0,0 +1,74 @@
|
||||
"""Shadow Account — today signals scanner.
|
||||
|
||||
Deterministic, data-free MVP: for each rule in a profile, pick up to N
|
||||
symbols from the market's liquid basket that are "in phase" with the
|
||||
rule's holding cadence on the target date. No external price fetches.
|
||||
|
||||
Future work: swap the phase test for a real feature check (e.g. the
|
||||
rule's entry condition evaluated on the most recent bar).
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from datetime import date, datetime
|
||||
from typing import Any
|
||||
|
||||
from src.shadow_account.backtester import _LIQUID_BASKETS, SUPPORTED_MARKETS
|
||||
from src.shadow_account.models import ShadowProfile, ShadowRule
|
||||
|
||||
|
||||
def scan_today_signals(
|
||||
profile: ShadowProfile,
|
||||
*,
|
||||
target_date: str | date | None = None,
|
||||
per_market: int = 3,
|
||||
) -> list[dict[str, Any]]:
|
||||
"""Return a list of {symbol, market, rule_id, reason} matches.
|
||||
|
||||
Args:
|
||||
profile: ShadowProfile holding the rules.
|
||||
target_date: ISO "YYYY-MM-DD" string, date object, or None (today).
|
||||
per_market: Cap per market bucket.
|
||||
|
||||
Returns:
|
||||
Possibly-empty list of matched candidates. Always research-only —
|
||||
callers should surface the disclaimer from the skill.
|
||||
"""
|
||||
if target_date is None:
|
||||
d = date.today()
|
||||
elif isinstance(target_date, date):
|
||||
d = target_date
|
||||
else:
|
||||
d = datetime.strptime(str(target_date), "%Y-%m-%d").date()
|
||||
|
||||
matches: list[dict[str, Any]] = []
|
||||
for rule in profile.rules:
|
||||
market = rule.entry_condition.get("market", "other")
|
||||
if market not in SUPPORTED_MARKETS:
|
||||
continue
|
||||
basket = _LIQUID_BASKETS.get(market, [])
|
||||
if not _date_in_phase(d, rule):
|
||||
continue
|
||||
lo, hi = rule.holding_days_range
|
||||
reason = f"Within {rule.rule_id} entry window (hold {lo}-{hi}d)"
|
||||
for symbol in basket[:per_market]:
|
||||
matches.append({
|
||||
"symbol": symbol,
|
||||
"market": market,
|
||||
"rule_id": rule.rule_id,
|
||||
"reason": reason,
|
||||
})
|
||||
return matches
|
||||
|
||||
|
||||
def _date_in_phase(target: date, rule: ShadowRule) -> bool:
|
||||
"""True when `target`'s ordinal mod `2 * hold_median` is inside the entry band.
|
||||
|
||||
This keeps the scanner deterministic and reviewable without needing
|
||||
real-time market data.
|
||||
"""
|
||||
lo, hi = rule.holding_days_range
|
||||
hold = max(1, int((lo + hi) / 2))
|
||||
period = max(2, 2 * hold)
|
||||
phase = target.toordinal() % period
|
||||
return phase < hold
|
||||
@@ -0,0 +1,128 @@
|
||||
"""Shadow Account persistence (~/.vibe-trading/shadow_accounts/).
|
||||
|
||||
Layout:
|
||||
~/.vibe-trading/shadow_accounts/<shadow_id>.json ShadowProfile
|
||||
~/.vibe-trading/shadow_runs/<shadow_id>/ backtest run dir
|
||||
~/.vibe-trading/shadow_reports/<shadow_id>.pdf rendered report
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import json
|
||||
import uuid
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from src.shadow_account.models import ShadowProfile, ShadowRule
|
||||
|
||||
|
||||
def _root() -> Path:
|
||||
"""Return the Shadow Account root directory (auto-created)."""
|
||||
root = Path.home() / ".vibe-trading"
|
||||
root.mkdir(parents=True, exist_ok=True)
|
||||
return root
|
||||
|
||||
|
||||
def profiles_dir() -> Path:
|
||||
d = _root() / "shadow_accounts"
|
||||
d.mkdir(parents=True, exist_ok=True)
|
||||
return d
|
||||
|
||||
|
||||
def runs_dir(shadow_id: str) -> Path:
|
||||
d = _root() / "shadow_runs" / shadow_id
|
||||
d.mkdir(parents=True, exist_ok=True)
|
||||
return d
|
||||
|
||||
|
||||
def reports_dir() -> Path:
|
||||
d = _root() / "shadow_reports"
|
||||
d.mkdir(parents=True, exist_ok=True)
|
||||
return d
|
||||
|
||||
|
||||
def new_shadow_id() -> str:
|
||||
"""Mint a fresh shadow_id."""
|
||||
return f"shadow_{uuid.uuid4().hex[:8]}"
|
||||
|
||||
|
||||
def hash_journal(journal_path: Path | str) -> str:
|
||||
"""SHA1 over the raw journal bytes for idempotent extraction."""
|
||||
p = Path(journal_path)
|
||||
h = hashlib.sha1()
|
||||
with p.open("rb") as f:
|
||||
for chunk in iter(lambda: f.read(65536), b""):
|
||||
h.update(chunk)
|
||||
return h.hexdigest()
|
||||
|
||||
|
||||
def now_iso() -> str:
|
||||
"""UTC ISO8601 timestamp (seconds precision)."""
|
||||
return datetime.now(timezone.utc).isoformat(timespec="seconds")
|
||||
|
||||
|
||||
def save_profile(profile: ShadowProfile) -> Path:
|
||||
"""Persist a ShadowProfile to disk as JSON."""
|
||||
path = profiles_dir() / f"{profile.shadow_id}.json"
|
||||
path.write_text(
|
||||
json.dumps(profile.to_dict(), ensure_ascii=False, indent=2, default=str),
|
||||
encoding="utf-8",
|
||||
)
|
||||
return path
|
||||
|
||||
|
||||
def load_profile(shadow_id: str) -> ShadowProfile:
|
||||
"""Load a ShadowProfile back from disk.
|
||||
|
||||
Raises:
|
||||
FileNotFoundError: No profile with that id.
|
||||
"""
|
||||
path = profiles_dir() / f"{shadow_id}.json"
|
||||
if not path.exists():
|
||||
raise FileNotFoundError(f"Shadow profile not found: {shadow_id}")
|
||||
data: dict[str, Any] = json.loads(path.read_text(encoding="utf-8"))
|
||||
rules = tuple(
|
||||
ShadowRule(
|
||||
rule_id=r["rule_id"],
|
||||
human_text=r["human_text"],
|
||||
entry_condition=r["entry_condition"],
|
||||
exit_condition=r["exit_condition"],
|
||||
holding_days_range=tuple(r["holding_days_range"]),
|
||||
support_count=r["support_count"],
|
||||
coverage_rate=r["coverage_rate"],
|
||||
sample_trades=tuple(r["sample_trades"]),
|
||||
weight=r.get("weight", 1.0),
|
||||
)
|
||||
for r in data["rules"]
|
||||
)
|
||||
return ShadowProfile(
|
||||
shadow_id=data["shadow_id"],
|
||||
created_at=data["created_at"],
|
||||
journal_hash=data["journal_hash"],
|
||||
source_market=data["source_market"],
|
||||
profitable_roundtrips=data["profitable_roundtrips"],
|
||||
total_roundtrips=data["total_roundtrips"],
|
||||
date_range=tuple(data["date_range"]),
|
||||
profile_text=data["profile_text"],
|
||||
rules=rules,
|
||||
preferred_markets=tuple(data["preferred_markets"]),
|
||||
typical_holding_days=tuple(data["typical_holding_days"]),
|
||||
)
|
||||
|
||||
|
||||
def find_by_journal_hash(journal_hash: str) -> ShadowProfile | None:
|
||||
"""Return the most recent profile sharing this journal_hash, else None."""
|
||||
latest: ShadowProfile | None = None
|
||||
for path in profiles_dir().glob("*.json"):
|
||||
try:
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
except (json.JSONDecodeError, OSError):
|
||||
continue
|
||||
if data.get("journal_hash") != journal_hash:
|
||||
continue
|
||||
candidate = load_profile(data["shadow_id"])
|
||||
if latest is None or candidate.created_at > latest.created_at:
|
||||
latest = candidate
|
||||
return latest
|
||||
@@ -0,0 +1,339 @@
|
||||
:root {
|
||||
--bg: #0b0d12;
|
||||
--surface: #12151c;
|
||||
--surface2: #1a1f29;
|
||||
--border: #242a36;
|
||||
--text: #e6e9ef;
|
||||
--text-dim: #9099a8;
|
||||
--text-mute:#5f6878;
|
||||
--accent: #6aa8ff;
|
||||
--pos: #3dd68c;
|
||||
--neg: #ff7b6b;
|
||||
--warn: #f4b454;
|
||||
--mono: 'JetBrains Mono', 'SF Mono', 'Consolas', 'Menlo', monospace;
|
||||
--sans: 'Inter', 'SF Pro Text', -apple-system, 'Segoe UI', 'Roboto', sans-serif;
|
||||
}
|
||||
|
||||
@page {
|
||||
size: A4;
|
||||
margin: 14mm 12mm;
|
||||
@bottom-right {
|
||||
content: "Shadow Account " counter(page) " / " counter(pages);
|
||||
font-size: 7.5pt;
|
||||
color: var(--text-mute);
|
||||
font-family: var(--mono);
|
||||
letter-spacing: 0.3pt;
|
||||
}
|
||||
}
|
||||
|
||||
* { box-sizing: border-box; }
|
||||
|
||||
body {
|
||||
font-family: var(--sans);
|
||||
color: var(--text);
|
||||
background: var(--bg);
|
||||
font-size: 10pt;
|
||||
line-height: 1.55;
|
||||
margin: 0;
|
||||
-webkit-font-smoothing: antialiased;
|
||||
}
|
||||
|
||||
.mono {
|
||||
font-family: var(--mono);
|
||||
font-variant-numeric: tabular-nums;
|
||||
font-size: 9.5pt;
|
||||
}
|
||||
|
||||
/* ============ Cover ============ */
|
||||
|
||||
header.cover {
|
||||
padding: 20mm 14mm 18mm;
|
||||
margin: -14mm -12mm 0 -12mm;
|
||||
background:
|
||||
radial-gradient(1200px 400px at 15% 0%, rgba(106,168,255,0.18), transparent 60%),
|
||||
radial-gradient(900px 350px at 100% 0%, rgba(255,123,107,0.10), transparent 55%),
|
||||
linear-gradient(180deg, #0e1119 0%, #0b0d12 100%);
|
||||
border-bottom: 1pt solid var(--border);
|
||||
page-break-after: always;
|
||||
position: relative;
|
||||
}
|
||||
|
||||
header.cover::before {
|
||||
content: "";
|
||||
position: absolute;
|
||||
top: 0; left: 0; right: 0;
|
||||
height: 2pt;
|
||||
background: linear-gradient(90deg, var(--accent), #b46aff 50%, var(--neg));
|
||||
}
|
||||
|
||||
.eyebrow {
|
||||
font-family: var(--mono);
|
||||
font-size: 8.5pt;
|
||||
letter-spacing: 4pt;
|
||||
text-transform: uppercase;
|
||||
color: var(--accent);
|
||||
margin: 0 0 6mm;
|
||||
}
|
||||
|
||||
h1 {
|
||||
font-size: 38pt;
|
||||
font-weight: 700;
|
||||
letter-spacing: -1pt;
|
||||
margin: 0 0 4mm;
|
||||
line-height: 1.05;
|
||||
color: #fafbfd;
|
||||
}
|
||||
|
||||
.subtitle {
|
||||
font-family: var(--mono);
|
||||
font-size: 9pt;
|
||||
color: var(--text-mute);
|
||||
margin: 0 0 14mm;
|
||||
letter-spacing: 0.3pt;
|
||||
}
|
||||
|
||||
.cover-delta {
|
||||
padding: 14mm 12mm;
|
||||
background: var(--surface);
|
||||
border: 1pt solid var(--border);
|
||||
border-radius: 4pt;
|
||||
text-align: center;
|
||||
margin-bottom: 10mm;
|
||||
position: relative;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
.cover-delta::after {
|
||||
content: "";
|
||||
position: absolute;
|
||||
inset: 0;
|
||||
background: radial-gradient(600px 200px at 50% 120%, rgba(61,214,140,0.08), transparent 70%);
|
||||
pointer-events: none;
|
||||
}
|
||||
|
||||
.delta-label {
|
||||
font-family: var(--mono);
|
||||
font-size: 8.5pt;
|
||||
color: var(--text-mute);
|
||||
letter-spacing: 3pt;
|
||||
text-transform: uppercase;
|
||||
margin-bottom: 4mm;
|
||||
}
|
||||
|
||||
.delta-value {
|
||||
font-family: var(--mono);
|
||||
font-size: 52pt;
|
||||
font-weight: 700;
|
||||
line-height: 1;
|
||||
letter-spacing: -2pt;
|
||||
margin: 2mm 0 4mm;
|
||||
}
|
||||
|
||||
.delta-value.positive { color: var(--pos); }
|
||||
.delta-value.negative { color: var(--neg); }
|
||||
|
||||
.delta-caption {
|
||||
font-family: var(--mono);
|
||||
font-size: 9pt;
|
||||
color: var(--text-dim);
|
||||
letter-spacing: 0.3pt;
|
||||
}
|
||||
|
||||
header.cover .disclaimer {
|
||||
font-size: 8pt;
|
||||
color: var(--warn);
|
||||
margin-top: 10mm;
|
||||
padding: 3mm 5mm;
|
||||
background: rgba(244,180,84,0.08);
|
||||
border-left: 2pt solid var(--warn);
|
||||
border-radius: 2pt;
|
||||
}
|
||||
|
||||
/* ============ Panels ============ */
|
||||
|
||||
section.panel {
|
||||
page-break-inside: avoid;
|
||||
padding: 8mm 0 6mm;
|
||||
border-bottom: 1pt solid var(--border);
|
||||
}
|
||||
|
||||
section.panel:last-of-type {
|
||||
border-bottom: none;
|
||||
}
|
||||
|
||||
section.panel.gut-punch {
|
||||
background: linear-gradient(180deg, rgba(255,123,107,0.06), rgba(255,123,107,0.02));
|
||||
border-left: 2pt solid var(--neg);
|
||||
padding: 7mm 7mm 6mm;
|
||||
border-radius: 2pt;
|
||||
margin: 3mm -3mm;
|
||||
}
|
||||
|
||||
h2 {
|
||||
font-size: 13pt;
|
||||
font-weight: 600;
|
||||
margin: 0 0 4mm;
|
||||
letter-spacing: -0.2pt;
|
||||
color: #f0f3f8;
|
||||
}
|
||||
|
||||
h2::before {
|
||||
content: "";
|
||||
display: inline-block;
|
||||
width: 3pt;
|
||||
height: 10pt;
|
||||
background: var(--accent);
|
||||
margin-right: 3mm;
|
||||
vertical-align: -1pt;
|
||||
border-radius: 1pt;
|
||||
}
|
||||
|
||||
.panel.gut-punch h2::before { background: var(--neg); }
|
||||
|
||||
.lede {
|
||||
font-size: 10.5pt;
|
||||
color: var(--text);
|
||||
margin: 0 0 4mm;
|
||||
max-width: 165mm;
|
||||
}
|
||||
|
||||
.lede strong {
|
||||
font-family: var(--mono);
|
||||
font-weight: 600;
|
||||
}
|
||||
|
||||
.lede strong.positive { color: var(--pos); }
|
||||
.lede strong.negative { color: var(--neg); }
|
||||
|
||||
/* ============ Fact list ============ */
|
||||
|
||||
dl.facts {
|
||||
display: grid;
|
||||
grid-template-columns: max-content 1fr;
|
||||
column-gap: 8mm;
|
||||
row-gap: 2mm;
|
||||
margin: 3mm 0 0;
|
||||
padding: 4mm 5mm;
|
||||
background: var(--surface);
|
||||
border: 1pt solid var(--border);
|
||||
border-radius: 3pt;
|
||||
}
|
||||
|
||||
dl.facts dt {
|
||||
font-family: var(--mono);
|
||||
font-size: 8.5pt;
|
||||
color: var(--text-mute);
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 0.5pt;
|
||||
}
|
||||
|
||||
dl.facts dd {
|
||||
margin: 0;
|
||||
font-size: 9.5pt;
|
||||
color: var(--text);
|
||||
}
|
||||
|
||||
/* ============ Tables ============ */
|
||||
|
||||
table {
|
||||
width: 100%;
|
||||
border-collapse: separate;
|
||||
border-spacing: 0;
|
||||
font-size: 9pt;
|
||||
margin-top: 2mm;
|
||||
background: var(--surface);
|
||||
border: 1pt solid var(--border);
|
||||
border-radius: 3pt;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
thead th {
|
||||
background: var(--surface2);
|
||||
font-family: var(--mono);
|
||||
font-size: 7.5pt;
|
||||
font-weight: 500;
|
||||
color: var(--text-mute);
|
||||
letter-spacing: 1pt;
|
||||
text-transform: uppercase;
|
||||
padding: 2.5mm 3mm;
|
||||
text-align: left;
|
||||
border-bottom: 1pt solid var(--border);
|
||||
}
|
||||
|
||||
tbody td, tbody th {
|
||||
padding: 2mm 3mm;
|
||||
border-bottom: 1pt solid rgba(36,42,54,0.6);
|
||||
vertical-align: top;
|
||||
}
|
||||
|
||||
tbody tr:last-child td, tbody tr:last-child th {
|
||||
border-bottom: none;
|
||||
}
|
||||
|
||||
table.metrics tbody th {
|
||||
font-family: var(--mono);
|
||||
font-size: 8.5pt;
|
||||
color: var(--text-mute);
|
||||
font-weight: 500;
|
||||
width: 45%;
|
||||
text-transform: none;
|
||||
letter-spacing: 0;
|
||||
}
|
||||
|
||||
tbody td.mono {
|
||||
color: var(--text);
|
||||
}
|
||||
|
||||
tbody td.pos, .pos { color: var(--pos); }
|
||||
tbody td.neg, .neg { color: var(--neg); }
|
||||
|
||||
/* ============ Charts ============ */
|
||||
|
||||
img.chart {
|
||||
display: block;
|
||||
width: 100%;
|
||||
max-height: 78mm;
|
||||
object-fit: contain;
|
||||
margin: 3mm 0;
|
||||
background: var(--surface);
|
||||
border: 1pt solid var(--border);
|
||||
border-radius: 3pt;
|
||||
padding: 2mm;
|
||||
}
|
||||
|
||||
/* ============ Misc ============ */
|
||||
|
||||
.muted {
|
||||
color: var(--text-mute);
|
||||
font-size: 9pt;
|
||||
font-style: italic;
|
||||
padding: 2mm 3mm;
|
||||
background: rgba(95,104,120,0.08);
|
||||
border-radius: 2pt;
|
||||
}
|
||||
|
||||
.panel .disclaimer {
|
||||
font-size: 8pt;
|
||||
color: var(--warn);
|
||||
font-family: var(--mono);
|
||||
margin: 3mm 0 0;
|
||||
padding: 2mm 3mm;
|
||||
background: rgba(244,180,84,0.07);
|
||||
border-left: 2pt solid var(--warn);
|
||||
letter-spacing: 0.2pt;
|
||||
}
|
||||
|
||||
.caveats {
|
||||
margin: 3mm 0 0;
|
||||
padding-left: 6mm;
|
||||
}
|
||||
|
||||
.caveats li {
|
||||
margin-bottom: 2mm;
|
||||
color: var(--text-dim);
|
||||
font-size: 9.5pt;
|
||||
}
|
||||
|
||||
.caveats li::marker {
|
||||
color: var(--accent);
|
||||
}
|
||||
@@ -0,0 +1,171 @@
|
||||
<!DOCTYPE html>
|
||||
<html lang="en">
|
||||
<head>
|
||||
<meta charset="utf-8" />
|
||||
<title>Shadow Account Report - {{ profile.shadow_id }}</title>
|
||||
<style>{{ css }}</style>
|
||||
</head>
|
||||
<body>
|
||||
<header class="cover">
|
||||
<p class="eyebrow">Shadow Account Report</p>
|
||||
<h1>You vs Your Shadow</h1>
|
||||
<p class="subtitle">{{ profile.shadow_id }} | {{ profile.created_at }}</p>
|
||||
<div class="cover-delta">
|
||||
<div class="delta-label">Delta PnL</div>
|
||||
<div class="delta-value {{ 'positive' if delta_pnl > 0 else 'negative' }}">
|
||||
{{ '%+.2f' | format(delta_pnl) }}
|
||||
</div>
|
||||
<div class="delta-caption">Shadow {{ '%.2f' | format(shadow_pnl) }} | Real {{ '%.2f' | format(real_pnl) }}</div>
|
||||
</div>
|
||||
<p class="disclaimer">Research use only - not investment advice. Data window: {{ profile.date_range[0] }} -> {{ profile.date_range[1] }}</p>
|
||||
</header>
|
||||
|
||||
<section class="panel">
|
||||
<h2>1. Your Shadow Profile</h2>
|
||||
<p class="lede">{{ profile.profile_text }}</p>
|
||||
<dl class="facts">
|
||||
<dt>Profitable roundtrips</dt><dd>{{ profile.profitable_roundtrips }} / {{ profile.total_roundtrips }}</dd>
|
||||
<dt>Primary market</dt><dd>{{ market_labels[profile.source_market] | default(profile.source_market) }}</dd>
|
||||
<dt>Holding median / p75</dt><dd>{{ '%.1f' | format(profile.typical_holding_days[0]) }}d / {{ '%.1f' | format(profile.typical_holding_days[1]) }}d</dd>
|
||||
<dt>Preferred markets</dt><dd>{% for m in profile.preferred_markets %}{{ market_labels[m] | default(m) }}{% if not loop.last %}, {% endif %}{% endfor %}</dd>
|
||||
</dl>
|
||||
</section>
|
||||
|
||||
<section class="panel">
|
||||
<h2>2. Shadow Rules</h2>
|
||||
<table class="rules">
|
||||
<thead>
|
||||
<tr><th>ID</th><th>Rule</th><th>Support</th><th>Coverage</th><th>Holding</th></tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
{% for rule in profile.rules %}
|
||||
<tr>
|
||||
<td class="mono">{{ rule.rule_id }}</td>
|
||||
<td>{{ rule.human_text }}</td>
|
||||
<td class="mono">{{ rule.support_count }}</td>
|
||||
<td class="mono">{{ '%.0f%%' | format(rule.coverage_rate * 100) }}</td>
|
||||
<td class="mono">{{ rule.holding_days_range[0] }}-{{ rule.holding_days_range[1] }}d</td>
|
||||
</tr>
|
||||
{% endfor %}
|
||||
</tbody>
|
||||
</table>
|
||||
</section>
|
||||
|
||||
<section class="panel">
|
||||
<h2>3. Shadow Backtest - Combined</h2>
|
||||
{% if charts.equity_curve %}
|
||||
<img class="chart" src="{{ charts.equity_curve }}" alt="equity curve"/>
|
||||
{% endif %}
|
||||
{% if combined_error %}
|
||||
<p class="muted">Backtest warning: {{ combined_error }}</p>
|
||||
{% endif %}
|
||||
{% if combined_metrics %}
|
||||
<table class="metrics">
|
||||
{% for key, value in combined_metrics.items() %}
|
||||
<tr><th>{{ key }}</th><td class="mono">{{ '%.4f' | format(value) }}</td></tr>
|
||||
{% endfor %}
|
||||
</table>
|
||||
{% else %}
|
||||
<p class="muted">Backtest produced no usable metrics (see warning above).</p>
|
||||
{% endif %}
|
||||
</section>
|
||||
|
||||
<section class="panel">
|
||||
<h2>4. Shadow Backtest - By Market</h2>
|
||||
{% if charts.per_market_bar %}
|
||||
<img class="chart" src="{{ charts.per_market_bar }}" alt="per-market bar"/>
|
||||
{% endif %}
|
||||
<table class="metrics">
|
||||
<thead>
|
||||
<tr><th>Market</th><th>Sharpe</th><th>Annual</th><th>Max Drawdown</th></tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
{% for market, metrics in per_market_metrics.items() %}
|
||||
<tr>
|
||||
<td>{{ market_labels[market] | default(market) }}</td>
|
||||
<td class="mono">{{ '%.2f' | format(metrics.get('sharpe', 0.0)) }}</td>
|
||||
<td class="mono">{{ '%.2f%%' | format(metrics.get('annual_return', 0.0) * 100) }}</td>
|
||||
<td class="mono">{{ '%.2f%%' | format(metrics.get('max_drawdown', 0.0) * 100) }}</td>
|
||||
</tr>
|
||||
{% endfor %}
|
||||
</tbody>
|
||||
</table>
|
||||
</section>
|
||||
|
||||
<section class="panel gut-punch">
|
||||
<h2>5. You vs Shadow - Delta Attribution</h2>
|
||||
<p class="lede">Shadow PnL <strong class="{{ 'pos' if shadow_pnl > 0 else 'neg' if shadow_pnl < 0 else '' }}">{{ '%+.2f' | format(shadow_pnl) }}</strong>, your real PnL <strong class="{{ 'pos' if real_pnl > 0 else 'neg' if real_pnl < 0 else '' }}">{{ '%+.2f' | format(real_pnl) }}</strong>, delta <strong class="{{ 'pos' if delta_pnl > 0 else 'neg' if delta_pnl < 0 else '' }}">{{ '%+.2f' | format(delta_pnl) }}</strong>.</p>
|
||||
{% if charts.attribution_waterfall %}
|
||||
<img class="chart" src="{{ charts.attribution_waterfall }}" alt="attribution waterfall"/>
|
||||
{% endif %}
|
||||
<table class="metrics">
|
||||
<tr><th>Noise trades</th><td class="mono {{ 'pos' if attribution.noise_trades_pnl > 0 else 'neg' if attribution.noise_trades_pnl < 0 else '' }}">{{ '%+.2f' | format(attribution.noise_trades_pnl) }}</td></tr>
|
||||
<tr><th>Early exit (winners)</th><td class="mono {{ 'pos' if attribution.early_exit_pnl > 0 else 'neg' if attribution.early_exit_pnl < 0 else '' }}">{{ '%+.2f' | format(attribution.early_exit_pnl) }}</td></tr>
|
||||
<tr><th>Late exit (losers)</th><td class="mono {{ 'pos' if attribution.late_exit_pnl > 0 else 'neg' if attribution.late_exit_pnl < 0 else '' }}">{{ '%+.2f' | format(attribution.late_exit_pnl) }}</td></tr>
|
||||
<tr><th>Overtrading</th><td class="mono {{ 'pos' if attribution.overtrading_pnl > 0 else 'neg' if attribution.overtrading_pnl < 0 else '' }}">{{ '%+.2f' | format(attribution.overtrading_pnl) }}</td></tr>
|
||||
<tr><th>Missed signals (residual)</th><td class="mono {{ 'pos' if attribution.missed_signals_pnl > 0 else 'neg' if attribution.missed_signals_pnl < 0 else '' }}">{{ '%+.2f' | format(attribution.missed_signals_pnl) }}</td></tr>
|
||||
</table>
|
||||
</section>
|
||||
|
||||
<section class="panel">
|
||||
<h2>6. Counterfactual Top 5</h2>
|
||||
{% if attribution.counterfactual_trades %}
|
||||
<table class="rules">
|
||||
<thead>
|
||||
<tr><th>#</th><th>Symbol</th><th>Buy</th><th>Sell</th><th>Hold</th><th>Real PnL</th><th>Impact</th><th>Reason</th></tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
{% for t in attribution.counterfactual_trades %}
|
||||
<tr>
|
||||
<td class="mono">{{ loop.index }}</td>
|
||||
<td>{{ t.symbol }}</td>
|
||||
<td class="mono">{{ t.buy_dt[:10] }}</td>
|
||||
<td class="mono">{{ t.sell_dt[:10] }}</td>
|
||||
<td class="mono">{{ '%.1f' | format(t.hold_days) }}d</td>
|
||||
<td class="mono {{ 'pos' if t.pnl > 0 else 'neg' if t.pnl < 0 else '' }}">{{ '%+.2f' | format(t.pnl) }}</td>
|
||||
<td class="mono {{ 'pos' if t.impact > 0 else 'neg' if t.impact < 0 else '' }}">{{ '%+.2f' | format(t.impact) }}</td>
|
||||
<td>{{ reason_labels.get(t.reason, t.reason) }}</td>
|
||||
</tr>
|
||||
{% endfor %}
|
||||
</tbody>
|
||||
</table>
|
||||
{% else %}
|
||||
<p class="muted">No material counterfactual trades - every roundtrip falls inside the shadow rules.</p>
|
||||
{% endif %}
|
||||
</section>
|
||||
|
||||
<section class="panel">
|
||||
<h2>7. Today's Signal Scan</h2>
|
||||
{% if today_signals %}
|
||||
<table class="rules">
|
||||
<thead>
|
||||
<tr><th>Symbol</th><th>Market</th><th>Rule</th><th>Reason</th></tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
{% for s in today_signals %}
|
||||
<tr>
|
||||
<td class="mono">{{ s.symbol }}</td>
|
||||
<td>{{ market_labels[s.market] | default(s.market) }}</td>
|
||||
<td class="mono">{{ s.rule_id }}</td>
|
||||
<td>{{ s.reason }}</td>
|
||||
</tr>
|
||||
{% endfor %}
|
||||
</tbody>
|
||||
</table>
|
||||
{% else %}
|
||||
<p class="muted">No shadow-matching symbols today (or scan skipped).</p>
|
||||
{% endif %}
|
||||
<p class="disclaimer">For research reference only - not a buy/sell recommendation.</p>
|
||||
</section>
|
||||
|
||||
<section class="panel">
|
||||
<h2>8. Confidence & Caveats</h2>
|
||||
<ul class="caveats">
|
||||
<li>Sample size: {{ profile.profitable_roundtrips }} profitable roundtrips support {{ profile.rules | length }} rule(s).</li>
|
||||
<li>Backtest assumptions: slippage/fees use engine defaults; cross-market annualization uses calendar days.</li>
|
||||
<li>Style decay: rules reflect the user's historical window and may not hold in future regimes.</li>
|
||||
<li>Red line: this report is research-only and never routes to any live trading system.</li>
|
||||
</ul>
|
||||
</section>
|
||||
</body>
|
||||
</html>
|
||||
@@ -0,0 +1,80 @@
|
||||
"""Shadow Account generated signal engine — {{ shadow_id }}
|
||||
|
||||
Rules distilled from {{ profitable_roundtrips }} profitable roundtrips
|
||||
over {{ date_range[0] }} → {{ date_range[1] }}.
|
||||
|
||||
This file is auto-generated; do not hand-edit. Regenerate via
|
||||
`src.shadow_account.codegen.render_signal_engine`.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import pandas as pd
|
||||
|
||||
SHADOW_ID = "{{ shadow_id }}"
|
||||
PREFERRED_MARKETS = {{ preferred_markets | tojson }}
|
||||
|
||||
RULES = [
|
||||
{% for rule in rules %} {
|
||||
"rule_id": "{{ rule.rule_id }}",
|
||||
"market": {{ rule.market | tojson }},
|
||||
"entry_hour_min": {{ rule.entry_hour_min }},
|
||||
"entry_hour_max": {{ rule.entry_hour_max }},
|
||||
"hold_days": {{ rule.hold_days }},
|
||||
"weight": {{ rule.weight }},
|
||||
},
|
||||
{% endfor %}]
|
||||
|
||||
|
||||
def _market_of(code: str) -> str:
|
||||
"""Infer a coarse market bucket from a symbol (matches backtest.runner)."""
|
||||
c = (code or "").upper()
|
||||
if c.endswith(".SH") or c.endswith(".SZ") or c.endswith(".BJ"):
|
||||
return "china_a"
|
||||
if c.endswith(".HK"):
|
||||
return "hk"
|
||||
if "-USDT" in c or "-USD" in c or "/" in c:
|
||||
return "crypto"
|
||||
if c and c[0].isalpha():
|
||||
return "us"
|
||||
return "other"
|
||||
|
||||
|
||||
class SignalEngine:
|
||||
"""Shadow Account signal engine (rule-replay, daily timeframe).
|
||||
|
||||
For each code we pick the first rule whose market matches, then emit
|
||||
a long signal (= rule.weight) for ``hold_days`` bars every
|
||||
``2 * hold_days`` bars — a deliberate period-replay of the user's
|
||||
profitable holding cadence. Non-matching codes yield a zero series.
|
||||
"""
|
||||
|
||||
def generate(self, data_map: dict) -> dict:
|
||||
signals: dict[str, pd.Series] = {}
|
||||
for code, df in data_map.items():
|
||||
sig = pd.Series(0.0, index=df.index)
|
||||
rule = self._pick_rule(code)
|
||||
if rule is not None:
|
||||
sig = self._replay_rule(df.index, rule)
|
||||
signals[code] = sig
|
||||
return signals
|
||||
|
||||
def _pick_rule(self, code: str) -> dict | None:
|
||||
market = _market_of(code)
|
||||
for rule in RULES:
|
||||
if rule["market"] == market or rule["market"] == "other":
|
||||
return rule
|
||||
# Fallback: first rule, regardless of market match.
|
||||
return RULES[0] if RULES else None
|
||||
|
||||
@staticmethod
|
||||
def _replay_rule(index: pd.Index, rule: dict) -> pd.Series:
|
||||
hold = max(1, int(rule["hold_days"]))
|
||||
period = max(2, hold * 2)
|
||||
weight = float(rule["weight"])
|
||||
values = [0.0] * len(index)
|
||||
i = 0
|
||||
while i < len(index):
|
||||
for j in range(i, min(i + hold, len(index))):
|
||||
values[j] = weight
|
||||
i += period
|
||||
return pd.Series(values, index=index)
|
||||
@@ -0,0 +1,113 @@
|
||||
---
|
||||
name: cross-market-strategy
|
||||
description: Write signal_engine.py for portfolios spanning multiple markets (A-shares + crypto, equity + forex, etc.)
|
||||
category: strategy
|
||||
---
|
||||
|
||||
## When to Use
|
||||
|
||||
When the user requests a backtest with codes from **different markets** — e.g. `["000001.SZ", "BTC-USDT"]` or `["AAPL.US", "EUR/USD", "600519.SH"]`.
|
||||
|
||||
The `CompositeEngine` handles calendar alignment, shared capital, and market rules automatically. The strategy only needs to output per-symbol signals.
|
||||
|
||||
## Key Concepts
|
||||
|
||||
### 1. Market Classification in generate()
|
||||
|
||||
Group symbols by market type and apply market-specific indicator parameters:
|
||||
|
||||
```python
|
||||
def generate(self, data_map):
|
||||
groups = {}
|
||||
for code, df in data_map.items():
|
||||
market = self._detect_market(code)
|
||||
groups.setdefault(market, {})[code] = df
|
||||
|
||||
signals = {}
|
||||
for market, market_data in groups.items():
|
||||
params = MARKET_PARAMS[market]
|
||||
for code, df in market_data.items():
|
||||
signals[code] = self._market_signal(df, params)
|
||||
return signals
|
||||
```
|
||||
|
||||
### 2. Per-Market Parameter Tables
|
||||
|
||||
Different markets have very different dynamics. Using the same parameters everywhere produces poor results.
|
||||
|
||||
| Parameter | A-Share | Crypto | US Equity | Forex |
|
||||
|-----------|---------|--------|-----------|-------|
|
||||
| MA fast | 5 | 7 | 10 | 10 |
|
||||
| MA slow | 20 | 25 | 50 | 30 |
|
||||
| RSI period | 14 | 10 | 14 | 14 |
|
||||
| Vol lookback | 20 | 14 | 20 | 20 |
|
||||
| Typical daily vol | 1-2% | 3-8% | 1-2% | 0.3-0.8% |
|
||||
|
||||
### 3. Volatility-Adjusted Weights (Critical)
|
||||
|
||||
BTC daily vol ~ 5%, A-share daily vol ~ 1.5%. Without vol-adjustment, crypto eats the entire risk budget.
|
||||
|
||||
```python
|
||||
def _vol_adjust(self, signals, data_map):
|
||||
vols = {}
|
||||
for code, df in data_map.items():
|
||||
ret = df["close"].pct_change().dropna()
|
||||
vols[code] = ret.rolling(20).std().iloc[-1] if len(ret) > 20 else ret.std()
|
||||
|
||||
inv_vols = {c: 1.0 / (v + 1e-10) for c, v in vols.items()}
|
||||
total_inv = sum(inv_vols.values())
|
||||
|
||||
adjusted = {}
|
||||
for code, sig in signals.items():
|
||||
weight = inv_vols[code] / total_inv * len(signals)
|
||||
adjusted[code] = (sig * weight).clip(-1.0, 1.0)
|
||||
return adjusted
|
||||
```
|
||||
|
||||
### 4. Cross-Market Signal Patterns
|
||||
|
||||
1. **Momentum spillover**: BTC 7-day momentum as overlay for A-share tech sectors
|
||||
2. **Risk-on/Risk-off**: USD/CNH rate + VIX proxy to reduce equity exposure
|
||||
3. **Hedging**: Long A-shares + short crypto delta as tail hedge
|
||||
4. **Correlation regime**: When rolling correlation > 0.6, reduce to single-market exposure; when < 0.2, maximize diversification
|
||||
|
||||
### 5. What the Engine Handles (Don't Worry About)
|
||||
|
||||
- **Trading calendar alignment**: signals are shifted on each symbol's own calendar, then ffill'd to unified dates
|
||||
- **Market rules**: T+1 for A-shares, funding fees for crypto, swap for forex — all per-symbol
|
||||
- **Capital allocation**: shared pool, strategy just sets target weights via signals
|
||||
- **Commission/slippage**: dispatched to correct sub-engine per symbol
|
||||
|
||||
## config.json for Cross-Market
|
||||
|
||||
```json
|
||||
{
|
||||
"source": "auto",
|
||||
"codes": ["000001.SZ", "BTC-USDT"],
|
||||
"start_date": "2024-01-01",
|
||||
"end_date": "2025-03-31",
|
||||
"interval": "1D",
|
||||
"initial_cash": 1000000,
|
||||
"engine": "daily"
|
||||
}
|
||||
```
|
||||
|
||||
- `source` **must** be `"auto"` for cross-market (routes each symbol to its loader)
|
||||
- `extra_fields` should be `null` (not all markets support fundamentals)
|
||||
- `leverage` defaults to 1.0 (CompositeEngine inherits from config)
|
||||
|
||||
## Market Detection Heuristics
|
||||
|
||||
| Pattern | Market |
|
||||
|---------|--------|
|
||||
| `000001.SZ`, `600519.SH` | A-share |
|
||||
| `AAPL.US` | US equity |
|
||||
| `700.HK` | HK equity |
|
||||
| `BTC-USDT` | Crypto |
|
||||
| `IF2406.CFFEX` | China futures |
|
||||
| `ESZ4` | Global futures |
|
||||
| `EUR/USD` | Forex |
|
||||
|
||||
## Supporting Files
|
||||
|
||||
- [example_signal_engine.py](example_signal_engine.py) — complete cross-market strategy example
|
||||
@@ -0,0 +1,80 @@
|
||||
"""Cross-market strategy example: vol-adjusted dual-MA with per-market parameters.
|
||||
|
||||
Supports any combination of A-shares, crypto, US/HK equity, forex, and futures.
|
||||
The CompositeEngine handles calendar alignment, market rules, and shared capital.
|
||||
"""
|
||||
|
||||
import re
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
|
||||
# Per-market indicator parameters
|
||||
MARKET_PARAMS = {
|
||||
"a_share": {"ma_fast": 5, "ma_slow": 20, "vol_lookback": 20},
|
||||
"crypto": {"ma_fast": 7, "ma_slow": 25, "vol_lookback": 14},
|
||||
"us_equity": {"ma_fast": 10, "ma_slow": 50, "vol_lookback": 20},
|
||||
"hk_equity": {"ma_fast": 10, "ma_slow": 50, "vol_lookback": 20},
|
||||
"forex": {"ma_fast": 10, "ma_slow": 30, "vol_lookback": 20},
|
||||
"futures": {"ma_fast": 5, "ma_slow": 20, "vol_lookback": 20},
|
||||
}
|
||||
|
||||
_MARKET_PATTERNS = [
|
||||
(re.compile(r"^\d{6}\.(SZ|SH|BJ)$", re.I), "a_share"),
|
||||
(re.compile(r"^[A-Z]+\.US$", re.I), "us_equity"),
|
||||
(re.compile(r"^\d{3,5}\.HK$", re.I), "hk_equity"),
|
||||
(re.compile(r"^[A-Z]+-USDT$", re.I), "crypto"),
|
||||
(re.compile(r"^[A-Z]+/USDT$", re.I), "crypto"),
|
||||
(re.compile(r"^[A-Z]{3}/[A-Z]{3}$"), "forex"),
|
||||
(re.compile(r"^[A-Z]{6}\.FX$"), "forex"),
|
||||
]
|
||||
|
||||
|
||||
class SignalEngine:
|
||||
def generate(self, data_map: dict) -> dict:
|
||||
# Step 1: raw signals per market
|
||||
raw_signals = {}
|
||||
for code, df in data_map.items():
|
||||
market = self._detect_market(code)
|
||||
params = MARKET_PARAMS.get(market, MARKET_PARAMS["a_share"])
|
||||
raw_signals[code] = self._market_signal(df, params)
|
||||
|
||||
# Step 2: volatility-adjusted weights
|
||||
return self._vol_adjust(raw_signals, data_map)
|
||||
|
||||
def _detect_market(self, code: str) -> str:
|
||||
for pattern, market in _MARKET_PATTERNS:
|
||||
if pattern.match(code):
|
||||
return market
|
||||
return "a_share"
|
||||
|
||||
def _market_signal(self, df: pd.DataFrame, params: dict) -> pd.Series:
|
||||
close = df["close"]
|
||||
ma_fast = close.rolling(params["ma_fast"]).mean()
|
||||
ma_slow = close.rolling(params["ma_slow"]).mean()
|
||||
|
||||
sig = pd.Series(0.0, index=df.index)
|
||||
sig[ma_fast > ma_slow] = 1.0
|
||||
sig[ma_fast < ma_slow] = -1.0
|
||||
return sig
|
||||
|
||||
def _vol_adjust(self, signals: dict, data_map: dict) -> dict:
|
||||
vols = {}
|
||||
for code, df in data_map.items():
|
||||
ret = df["close"].pct_change().dropna()
|
||||
vols[code] = (
|
||||
ret.rolling(20).std().iloc[-1]
|
||||
if len(ret) > 20
|
||||
else ret.std()
|
||||
)
|
||||
|
||||
inv_vols = {c: 1.0 / (v + 1e-10) for c, v in vols.items()}
|
||||
total_inv = sum(inv_vols.values())
|
||||
|
||||
adjusted = {}
|
||||
n = len(signals)
|
||||
for code, sig in signals.items():
|
||||
weight = inv_vols[code] / total_inv * n
|
||||
adjusted[code] = (sig * weight).clip(-1.0, 1.0)
|
||||
return adjusted
|
||||
@@ -1,75 +1,114 @@
|
||||
---
|
||||
name: doc-reader
|
||||
description: Read PDF documents (papers, annual reports, research reports), automatically extracting text pages and applying OCR to image/scanned pages. Use the `read_document` tool.
|
||||
description: Read any common document/data file — PDF, Word (.docx), Excel (.xlsx/.xls), PowerPoint (.pptx), images (OCR), CSV/TSV, plain text, JSON/YAML/TOML, HTML/XML, and most source-code files. Use the `read_document` tool.
|
||||
category: tool
|
||||
---
|
||||
# PDF Document Reading
|
||||
# Universal Document Reader
|
||||
|
||||
## Purpose
|
||||
|
||||
Read the full text of PDF documents and automatically handle two page types:
|
||||
- **Text pages** (most papers and digital reports) → extracted directly in milliseconds
|
||||
- **Image / scanned pages** (annual report charts, scanned research reports) → OCR recognition with Chinese and English support
|
||||
Return extracted text from any supported file in a single unified JSON
|
||||
envelope. The tool dispatches by file extension — you always call the same
|
||||
tool regardless of format.
|
||||
|
||||
Applicable to PDF documents such as papers, annual reports, research reports, announcements, and contracts.
|
||||
### Supported formats
|
||||
|
||||
| Category | Extensions | Notes |
|
||||
|---|---|---|
|
||||
| PDF | `.pdf` | Text pages extracted in ms; scanned/image pages fall back to OCR |
|
||||
| Word | `.docx` | Paragraphs + table cells |
|
||||
| Excel | `.xlsx`, `.xls` | All sheets, first 100 rows per sheet as preview |
|
||||
| PowerPoint | `.pptx` | Slide text content |
|
||||
| Images | `.png/.jpg/.jpeg/.gif/.bmp/.webp/.tiff` | OCR only |
|
||||
| CSV / TSV | `.csv`, `.tsv` | Raw text with encoding fallback |
|
||||
| Plain text | `.txt/.md/.log/.rst` | Encoding fallback |
|
||||
| Config | `.json/.yaml/.yml/.toml/.ini/.cfg/.env` | Raw text |
|
||||
| Markup | `.html/.htm/.xml` | Raw text (no HTML stripping) |
|
||||
| Source code | `.py/.js/.ts/.tsx/.go/.rs/.java/.cpp/.c/.sql/.sh/...` | Raw text |
|
||||
| Unknown extension | anything else | Best-effort read as UTF-8/GBK text |
|
||||
|
||||
**Blocked** (rejected at `/upload`): executables (`.exe/.dll/.so/...`) and
|
||||
archives (`.zip/.tar/...`). Ask the user to unpack archives locally first.
|
||||
|
||||
## Usage
|
||||
|
||||
**Call the `read_document` tool directly (do not use bash to write a Python script):**
|
||||
**Always call the tool directly — do not run Python from bash.**
|
||||
|
||||
```
|
||||
read_document(file_path="uploads/paper.pdf")
|
||||
read_document(file_path="uploads/annual_report.pdf", pages="1-10")
|
||||
read_document(file_path="uploads/research.pdf", pages="1,3,15-20")
|
||||
read_document(file_path="uploads/contract.docx")
|
||||
read_document(file_path="uploads/sales.xlsx")
|
||||
read_document(file_path="uploads/deck.pptx")
|
||||
read_document(file_path="uploads/chart.png") # image → OCR
|
||||
read_document(file_path="uploads/config.yaml")
|
||||
read_document(file_path="uploads/notes.md")
|
||||
```
|
||||
|
||||
**Forbidden**: do not run a Python script from bash to read PDFs. Call the tool directly.
|
||||
The `pages` parameter only applies to PDF; other formats ignore it.
|
||||
|
||||
## Return Format
|
||||
## Return envelope
|
||||
|
||||
All formats share this shape:
|
||||
|
||||
```json
|
||||
{
|
||||
"status": "ok",
|
||||
"file": "paper.pdf",
|
||||
"total_pages": 45,
|
||||
"pages_read": 45,
|
||||
"ocr_pages": 3,
|
||||
"format": "pdf",
|
||||
"char_count": 52000,
|
||||
"truncated": true,
|
||||
"text": "--- Page 1 ---\n...\n--- Page 5 [OCR] ---\n..."
|
||||
"text": "..."
|
||||
}
|
||||
```
|
||||
|
||||
- `ocr_pages`: number of pages recognized via OCR (image / scanned pages)
|
||||
- `truncated`: content is truncated when it exceeds 15000 characters
|
||||
- `[OCR]` indicates that the page content was obtained via image recognition
|
||||
Format-specific extra fields:
|
||||
|
||||
## Typical Workflows
|
||||
| Format | Extra keys |
|
||||
|---|---|
|
||||
| `pdf` | `total_pages`, `pages_read`, `ocr_pages` |
|
||||
| `docx` | `paragraphs`, `tables` |
|
||||
| `excel` | `sheets` (array of `{name, rows, cols}`) |
|
||||
| `pptx` | `slides` |
|
||||
| `text` | `encoding`, `size` |
|
||||
|
||||
### Paper Summary
|
||||
Content longer than 15000 chars is truncated; for PDFs use the `pages`
|
||||
parameter to read slices.
|
||||
|
||||
## Workflows
|
||||
|
||||
### Paper / report summary
|
||||
```
|
||||
1. read_document(file_path="paper.pdf") → get the full text
|
||||
2. Analyze the text and extract the abstract, methodology, and conclusion
|
||||
3. Output the summary
|
||||
1. read_document(file_path="paper.pdf") → full text
|
||||
2. Extract abstract, methodology, conclusion → summarize
|
||||
```
|
||||
|
||||
### Annual Report Analysis
|
||||
### Contract review
|
||||
```
|
||||
1. read_document(file_path="annual_report.pdf", pages="1-5") → read the summary first
|
||||
2. Determine the key sections from the summary
|
||||
3. read_document(file_path="...", pages="15-25") → read the financial-data section
|
||||
4. Extract key metrics
|
||||
1. read_document(file_path="contract.docx") → paragraphs + tables
|
||||
2. Flag key clauses (termination, liability, payment, IP)
|
||||
```
|
||||
|
||||
### Research Report Review
|
||||
### Spreadsheet quick-look
|
||||
```
|
||||
1. read_document(file_path="research.pdf") → full text
|
||||
2. Extract the core thesis, target price, and risk factors
|
||||
1. read_document(file_path="sales.xlsx") → all sheet previews
|
||||
2. If user wants trade journal analysis specifically, pivot to
|
||||
`analyze_trade_journal` tool instead (see trade-journal skill).
|
||||
```
|
||||
|
||||
### Chart / screenshot / scanned PDF
|
||||
```
|
||||
1. read_document(file_path="scan.png") → OCR text
|
||||
2. If OCR returns empty, tell the user; don't fabricate.
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
- Content longer than 15000 characters will be truncated. For long documents, read them in chunks with the `pages` parameter
|
||||
- OCR pages are slower (about 1-3 seconds per page), while pure text pages are processed in milliseconds
|
||||
- OCR for charts and tables inside images may be imperfect, so complex tables should be checked manually
|
||||
- Only PDF format is supported
|
||||
- **Encoding fallback** order for text: utf-8 → utf-8-sig → gbk → gb2312 → big5 → latin-1.
|
||||
- **OCR** uses RapidOCR; if the package is missing, image/scanned files
|
||||
return empty `text` with a `note` field — tell the user to install
|
||||
`rapidocr-onnxruntime`.
|
||||
- **Excel previews** are limited to 100 rows per sheet to stay in budget.
|
||||
If the user needs full data (e.g. trade journals), call
|
||||
`analyze_trade_journal` instead.
|
||||
- **Source-code files** are returned raw; do not re-format or re-indent.
|
||||
@@ -1,34 +1,73 @@
|
||||
---
|
||||
name: pine-script
|
||||
description: Convert Python backtest strategies to TradingView Pine Script v6, or generate Pine Script from natural language descriptions.
|
||||
description: Export backtest strategies to indicator/strategy code for major trading platforms — TradingView, 通达信, 同花顺, 东方财富, MT5.
|
||||
category: tool
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
This skill enables two workflows:
|
||||
1. **Export**: convert an existing `signal_engine.py` (from a completed backtest run) into a TradingView Pine Script v6 strategy
|
||||
2. **Generate**: write Pine Script v6 directly from a natural-language strategy description
|
||||
This skill exports a Vibe-Trading strategy to **all major trading platforms** in one go.
|
||||
Output file: `artifacts/strategy.pine` (inside the run directory).
|
||||
|
||||
Output file: `artifacts/strategy.pine` (inside the run directory, or a new run directory).
|
||||
Supported platforms (always generate ALL):
|
||||
|
||||
| Group | Platforms | Language |
|
||||
|-------|-----------|----------|
|
||||
| International Charts | TradingView | Pine Script v6 |
|
||||
| China Equities | 通达信 / 同花顺 / 东方财富 | TDX Formula |
|
||||
| Forex / CFD | MetaTrader 5 | MQL5 |
|
||||
|
||||
## Workflow: Export from Backtest
|
||||
|
||||
1. `load_skill("pine-script")` — read this conversion guide
|
||||
1. `load_skill("pine-script")` — read this guide
|
||||
2. `read_file("config.json")` — understand instruments, dates, parameters
|
||||
3. `read_file("code/signal_engine.py")` — understand the Python strategy logic
|
||||
4. **Translate** the strategy to Pine Script v6 using the mapping table below
|
||||
5. `write_file("artifacts/strategy.pine")` — save the output
|
||||
6. Return the Pine Script in a code block with usage instructions
|
||||
4. **Translate** the strategy to ALL platforms using the references below
|
||||
5. `write_file("artifacts/strategy.pine")` — save the combined output
|
||||
6. Return the code in a code block with usage instructions per platform
|
||||
|
||||
## Workflow: Generate from Description
|
||||
|
||||
1. `load_skill("pine-script")` — read this guide
|
||||
2. Write Pine Script v6 directly based on the user's description
|
||||
3. `write_file("artifacts/strategy.pine")` — save the output
|
||||
2. Write indicator/strategy code for ALL platforms based on the user's description
|
||||
3. `write_file("artifacts/strategy.pine")` — save the combined output
|
||||
4. Return the code with usage instructions
|
||||
|
||||
## Pine Script v6 Strategy Template
|
||||
## Output Format
|
||||
|
||||
The output file uses this structure (all platforms in one file):
|
||||
|
||||
```
|
||||
================================================================================
|
||||
TRADINGVIEW — Pine Script v6
|
||||
Paste into: Pine Editor → New blank indicator → Add to Chart
|
||||
================================================================================
|
||||
|
||||
[Pine Script code here]
|
||||
|
||||
================================================================================
|
||||
通达信 / 同花顺 / 东方财富 (TDX Formula)
|
||||
Paste into: 功能 → 公式管理器 → 新建指标公式
|
||||
================================================================================
|
||||
|
||||
[TDX formula code here]
|
||||
|
||||
================================================================================
|
||||
MT5 — MQL5
|
||||
Save as: .mq5 file → MetaEditor → Compile → Navigator → Attach to Chart
|
||||
================================================================================
|
||||
|
||||
[MQL5 code here]
|
||||
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
# Platform Reference
|
||||
|
||||
## 1. TradingView — Pine Script v6
|
||||
|
||||
### Template
|
||||
|
||||
```pinescript
|
||||
// This strategy was generated by Vibe-Trading
|
||||
@@ -78,9 +117,7 @@ alertcondition(longCondition, title="Long Signal", message="Long entry signal tr
|
||||
alertcondition(shortCondition, title="Short Signal", message="Short entry signal triggered")
|
||||
```
|
||||
|
||||
## Python → Pine Script Mapping Table
|
||||
|
||||
### Technical Indicators
|
||||
### Python → Pine Script Mapping
|
||||
|
||||
| Python (pandas/numpy) | Pine Script v6 |
|
||||
|------------------------|----------------|
|
||||
@@ -94,13 +131,13 @@ alertcondition(shortCondition, title="Short Signal", message="Short entry signal
|
||||
| `df['close'].pct_change()` | `(close - close[1]) / close[1]` |
|
||||
| `df['volume'].rolling(n).mean()` | `ta.sma(volume, n)` |
|
||||
| `df['close'] > df['close'].shift(1)` | `close > close[1]` |
|
||||
| Bollinger Bands (manual) | `[mid, upper, lower] = ta.bb(close, length, mult)` |
|
||||
| ATR (manual or ta-lib) | `ta.atr(length)` |
|
||||
| ADX | `ta.adx(high, low, close, length)` (returns adx value) |
|
||||
| Bollinger Bands | `[mid, upper, lower] = ta.bb(close, length, mult)` |
|
||||
| ATR | `ta.atr(length)` |
|
||||
| ADX | `ta.adx(high, low, close, length)` |
|
||||
| Stochastic | `ta.stoch(close, high, low, length, smoothK, smoothD)` |
|
||||
| CCI | `ta.cci(close, length)` (Pine v6: `ta.cci(close, length)`) |
|
||||
| CCI | `ta.cci(close, length)` |
|
||||
| Williams %R | `ta.wpr(length)` |
|
||||
| MFI | `ta.mfi(hlc3, volume, length)` — Pine v6: `ta.mfi(close, length)` |
|
||||
| MFI | `ta.mfi(close, length)` |
|
||||
| OBV | `ta.obv` |
|
||||
| VWAP | `ta.vwap` |
|
||||
|
||||
@@ -138,94 +175,212 @@ alertcondition(shortCondition, title="Short Signal", message="Short entry signal
|
||||
| Stop-loss | `strategy.exit("Exit", stop=entryPrice * (1 - stopPct))` |
|
||||
| Take-profit | `strategy.exit("Exit", limit=entryPrice * (1 + tpPct))` |
|
||||
|
||||
## Pine Script v6 Syntax Rules
|
||||
|
||||
### Critical Rules (common errors)
|
||||
### Syntax Rules (Critical)
|
||||
|
||||
1. **Version declaration must be first line**: `//@version=6`
|
||||
2. **Ternary operators MUST stay on one line** or use intermediate variables:
|
||||
```pinescript
|
||||
// WRONG — causes "end of line without line continuation"
|
||||
text = condition ? "value1" :
|
||||
"value2"
|
||||
|
||||
// CORRECT
|
||||
text = condition ? "value1" : "value2"
|
||||
```
|
||||
2. **Ternary operators MUST stay on one line**: `text = condition ? "a" : "b"`
|
||||
3. **Line continuation**: continuation lines must be indented MORE than the starting line
|
||||
4. **No plot() in local scope** (if/for/function):
|
||||
```pinescript
|
||||
// WRONG
|
||||
if condition
|
||||
plot(value)
|
||||
4. **No plot() in local scope** (if/for/function) — use `plot(condition ? value : na)`
|
||||
5. **var**: persistent state across bars; regular assignment recalculates each bar
|
||||
6. **Avoid repainting**: use `barstate.isconfirmed`, `lookahead=barmerge.lookahead_off`
|
||||
7. **Limits**: max 500 bars lookback, 500 plot calls, 64 entry/exit per bar, 40 request.security()
|
||||
|
||||
// CORRECT
|
||||
plot(condition ? value : na)
|
||||
```
|
||||
5. **var vs regular variables**: use `var` for persistent state across bars, regular assignment recalculates each bar
|
||||
6. **varip**: persistent even on real-time bar updates (intrabar persistence)
|
||||
---
|
||||
|
||||
### Script Types
|
||||
## 2. 通达信 / 同花顺 / 东方财富 — TDX Formula
|
||||
|
||||
| Type | Declaration | Use Case |
|
||||
|------|-------------|----------|
|
||||
| `strategy` | `strategy("Name", ...)` | Backtestable with entry/exit orders |
|
||||
| `indicator` | `indicator("Name", ...)` | Visual indicators, no backtesting |
|
||||
| `library` | `library("Name")` | Reusable functions |
|
||||
These platforms share 95%+ identical formula syntax. Write ONE version that works on all three.
|
||||
|
||||
**Default output: `strategy`** (matches Vibe-Trading's backtest-first philosophy).
|
||||
|
||||
### Avoid Repainting
|
||||
|
||||
- Use `barstate.isconfirmed` for signals on confirmed bars only
|
||||
- Use `request.security()` with `lookahead=barmerge.lookahead_off` (default in v6)
|
||||
- Do NOT use `security()` on lower timeframes without understanding implications
|
||||
|
||||
### Platform Limits
|
||||
|
||||
- Max 500 bars lookback for `[]` operator
|
||||
- Max 500 plot calls
|
||||
- Max 64 `strategy.entry/exit` calls per bar
|
||||
- Max 40 `request.security()` calls
|
||||
|
||||
## TradingView Symbol Format
|
||||
|
||||
When generating Pine Script, map Vibe-Trading codes to TradingView symbols:
|
||||
|
||||
| Vibe-Trading Format | TradingView Format | Exchange |
|
||||
|---------------------|-------------------|----------|
|
||||
| `000001.SZ` | `SZSE:000001` | Shenzhen |
|
||||
| `600519.SH` | `SSE:600519` | Shanghai |
|
||||
| `AAPL.US` | `NASDAQ:AAPL` | US (auto-detect) |
|
||||
| `700.HK` | `HKEX:0700` | Hong Kong |
|
||||
| `BTC-USDT` | `OKX:BTCUSDT.P` or `BINANCE:BTCUSDT` | Crypto |
|
||||
|
||||
**Note**: Pine Script strategies are chart-independent — the user applies them to whichever symbol they want on TradingView. Include a comment noting the original instrument.
|
||||
|
||||
## Usage Instructions (include in response)
|
||||
|
||||
After generating the Pine Script, always include:
|
||||
### Template
|
||||
|
||||
```
|
||||
How to use in TradingView:
|
||||
1. Open TradingView → Pine Editor (bottom panel)
|
||||
2. Click "Open" → "New blank indicator"
|
||||
3. Delete all existing code
|
||||
4. Paste the Pine Script above
|
||||
5. Click "Add to Chart"
|
||||
6. The strategy will appear on your chart with entry/exit markers
|
||||
7. Open "Strategy Tester" tab to see backtest results
|
||||
{Vibe-Trading 策略导出}
|
||||
{策略名称: XXX}
|
||||
|
||||
{——————— 参数 ———————}
|
||||
N:=14;
|
||||
M:=6;
|
||||
|
||||
{——————— 指标计算 ———————}
|
||||
RSI_VAL:=RSI(CLOSE,N);
|
||||
MA_FAST:=MA(CLOSE,5);
|
||||
MA_SLOW:=MA(CLOSE,20);
|
||||
|
||||
{——————— 买卖信号 ———————}
|
||||
BUY:CROSS(MA_FAST,MA_SLOW) AND RSI_VAL<40,COLORRED;
|
||||
SELL:CROSS(MA_SLOW,MA_FAST) AND RSI_VAL>60,COLORGREEN;
|
||||
|
||||
DRAWTEXT(BUY,LOW,'B'),COLORYELLOW;
|
||||
DRAWTEXT(SELL,HIGH,'S'),COLORWHITE;
|
||||
```
|
||||
|
||||
### Python → TDX Mapping
|
||||
|
||||
| Python | TDX Formula |
|
||||
|--------|-------------|
|
||||
| `df['close'].rolling(n).mean()` | `MA(CLOSE,N)` |
|
||||
| `df['close'].ewm(span=n).mean()` | `EMA(CLOSE,N)` |
|
||||
| RSI | `RSI(CLOSE,N)` (returns 0-100) |
|
||||
| MACD | `MACD.DIF`, `MACD.DEA`, `MACD.MACD` or manual: `DIF:=EMA(CLOSE,12)-EMA(CLOSE,26); DEA:=EMA(DIF,9); MACD:=(DIF-DEA)*2;` |
|
||||
| Bollinger Bands | `BOLL(N,M)` → `BOLL.UPPER`, `BOLL.MID`, `BOLL.LOWER` or manual |
|
||||
| ATR | `ATR:=MA(MAX(MAX(HIGH-LOW,ABS(HIGH-REF(CLOSE,1))),ABS(LOW-REF(CLOSE,1))),N);` |
|
||||
| `df['close'].shift(n)` | `REF(CLOSE,N)` |
|
||||
| `df['high'].rolling(n).max()` | `HHV(HIGH,N)` |
|
||||
| `df['low'].rolling(n).min()` | `LLV(LOW,N)` |
|
||||
| crossover(fast, slow) | `CROSS(FAST,SLOW)` |
|
||||
| crossunder(fast, slow) | `CROSS(SLOW,FAST)` |
|
||||
| `df['volume']` | `VOL` |
|
||||
| `abs(x)` | `ABS(X)` |
|
||||
| `max(a,b)` | `MAX(A,B)` |
|
||||
| `min(a,b)` | `MIN(A,B)` |
|
||||
| conditional | `IF(COND,A,B)` |
|
||||
| `df['close'].pct_change()` | `(CLOSE-REF(CLOSE,1))/REF(CLOSE,1)` |
|
||||
| count true in N bars | `COUNT(COND,N)` |
|
||||
| sum over N bars | `SUM(X,N)` |
|
||||
| std over N bars | `STD(CLOSE,N)` |
|
||||
| slope / linear regression | `SLOPE(CLOSE,N)` |
|
||||
|
||||
### Syntax Rules
|
||||
|
||||
1. **Assignment**: `:=` for intermediate variables, `:` for output (plotted) lines
|
||||
2. **Comments**: `{comment}` — curly braces, NOT `//`
|
||||
3. **No semicolons optional**: each statement ends with `;`
|
||||
4. **Colors**: `COLORRED`, `COLORGREEN`, `COLORYELLOW`, `COLORWHITE`, `COLORBLUE`, `COLORCYAN`, `COLORMAGENTA`
|
||||
5. **Line styles**: `LINETHICK2`, `POINTDOT`, `STICK`, `VOLSTICK`
|
||||
6. **Draw text**: `DRAWTEXT(COND, PRICE, 'TEXT'), COLOR;`
|
||||
7. **Draw icon**: `DRAWICON(COND, PRICE, ICON_ID);`
|
||||
8. **All function/variable names UPPERCASE**
|
||||
9. **No loops / no arrays** — everything is vectorized bar-by-bar
|
||||
10. **Max formula length**: ~10,000 characters per formula
|
||||
|
||||
### Platform Differences
|
||||
|
||||
| Feature | 通达信 | 同花顺 | 东方财富 |
|
||||
|---------|--------|--------|----------|
|
||||
| MACD built-in | `MACD(12,26,9)` | `MACD(12,26,9)` | same |
|
||||
| Stochastic | `KDJ(N,M1,M2)` | same | same |
|
||||
| Custom color | `COLOR+RRGGBB` | `COLOR+RRGGBB` | limited |
|
||||
| Strategy backtest | 条件选股 only | 条件选股 only | 条件选股 only |
|
||||
|
||||
For maximum compatibility, avoid platform-specific extensions. Stick to core functions.
|
||||
|
||||
---
|
||||
|
||||
## 3. MetaTrader 5 — MQL5
|
||||
|
||||
### Template (Custom Indicator)
|
||||
|
||||
```mql5
|
||||
//+------------------------------------------------------------------+
|
||||
//| Generated by Vibe-Trading |
|
||||
//+------------------------------------------------------------------+
|
||||
#property copyright "Vibe-Trading"
|
||||
#property indicator_chart_window // or indicator_separate_window
|
||||
#property indicator_buffers 2
|
||||
#property indicator_plots 2
|
||||
#property indicator_color1 clrDodgerBlue
|
||||
#property indicator_color2 clrRed
|
||||
|
||||
input int InpPeriod = 14; // Period
|
||||
|
||||
double BuyBuffer[];
|
||||
double SellBuffer[];
|
||||
|
||||
int OnInit()
|
||||
{
|
||||
SetIndexBuffer(0, BuyBuffer, INDICATOR_DATA);
|
||||
SetIndexBuffer(1, SellBuffer, INDICATOR_DATA);
|
||||
PlotIndexSetInteger(0, PLOT_ARROW, 233); // up arrow
|
||||
PlotIndexSetInteger(1, PLOT_ARROW, 234); // down arrow
|
||||
PlotIndexSetInteger(0, PLOT_DRAW_TYPE, DRAW_ARROW);
|
||||
PlotIndexSetInteger(1, PLOT_DRAW_TYPE, DRAW_ARROW);
|
||||
return(INIT_SUCCEEDED);
|
||||
}
|
||||
|
||||
int OnCalculate(const int rates_total,
|
||||
const int prev_calculated,
|
||||
const datetime &time[],
|
||||
const double &open[],
|
||||
const double &high[],
|
||||
const double &low[],
|
||||
const double &close[],
|
||||
const long &tick_volume[],
|
||||
const long &volume[],
|
||||
const int &spread[])
|
||||
{
|
||||
int start = MathMax(prev_calculated - 1, InpPeriod);
|
||||
for(int i = start; i < rates_total; i++)
|
||||
{
|
||||
BuyBuffer[i] = EMPTY_VALUE;
|
||||
SellBuffer[i] = EMPTY_VALUE;
|
||||
|
||||
// === YOUR LOGIC HERE ===
|
||||
// Example: if(buyCondition) BuyBuffer[i] = low[i];
|
||||
// if(sellCondition) SellBuffer[i] = high[i];
|
||||
}
|
||||
return(rates_total);
|
||||
}
|
||||
```
|
||||
|
||||
### Python → MQL5 Mapping
|
||||
|
||||
| Python | MQL5 |
|
||||
|--------|------|
|
||||
| `df['close'].rolling(n).mean()` | `iMA(_Symbol, PERIOD_CURRENT, n, 0, MODE_SMA, PRICE_CLOSE)` or manual loop |
|
||||
| EMA | `iMA(..., MODE_EMA, ...)` |
|
||||
| RSI | `iRSI(_Symbol, PERIOD_CURRENT, n, PRICE_CLOSE)` |
|
||||
| MACD | `iMACD(_Symbol, PERIOD_CURRENT, 12, 26, 9, PRICE_CLOSE)` |
|
||||
| Bollinger | `iBands(_Symbol, PERIOD_CURRENT, n, 0, mult, PRICE_CLOSE)` |
|
||||
| ATR | `iATR(_Symbol, PERIOD_CURRENT, n)` |
|
||||
| Stochastic | `iStochastic(_Symbol, PERIOD_CURRENT, K, D, slowing, MODE_SMA, STO_LOWHIGH)` |
|
||||
| `df['close'].shift(n)` | `close[i-n]` (in OnCalculate loop) |
|
||||
| crossover | `buf[i] > ref[i] && buf[i-1] <= ref[i-1]` |
|
||||
|
||||
### Syntax Rules
|
||||
|
||||
1. **Indicator handles**: call `iMA()` etc. in `OnInit()`, use `CopyBuffer()` to get values
|
||||
2. **Buffer direction**: MQL5 buffers are indexed 0=oldest by default; use `ArraySetAsSeries()` to reverse
|
||||
3. **EMPTY_VALUE**: use for "no signal" on arrow plots
|
||||
4. **Indicator vs EA**: generate indicator (`.mq5`), not Expert Advisor, to match "indicator export" purpose
|
||||
5. **Handle-based API**: MQL5 uses handles — create in `OnInit`, read in `OnCalculate`
|
||||
|
||||
---
|
||||
|
||||
## Symbol Format Mapping
|
||||
|
||||
When generating code, map Vibe-Trading instrument codes appropriately:
|
||||
|
||||
| Vibe-Trading | TradingView | 通达信/同花顺 | MT5 |
|
||||
|-------------|-------------|---------------|-----|
|
||||
| `000001.SZ` | `SZSE:000001` | `000001` | N/A |
|
||||
| `600519.SH` | `SSE:600519` | `600519` | N/A |
|
||||
| `AAPL.US` | `NASDAQ:AAPL` | N/A | `AAPL` |
|
||||
| `BTC-USDT` | `BINANCE:BTCUSDT` | N/A | `BTCUSD` |
|
||||
|
||||
**Note**: Most indicator code is instrument-agnostic — the user applies it to whatever chart they're viewing. Include a comment noting the original instrument for reference only.
|
||||
|
||||
## Limitations & Transparency
|
||||
|
||||
When a Python strategy uses features that can't be directly translated, clearly note it:
|
||||
|
||||
| Python Feature | Platform Limitation |
|
||||
|---------------|-------------------|
|
||||
| ML models (sklearn, etc.) | None — flag as "manual implementation required" |
|
||||
| Custom pandas operations | TDX — limited to built-in functions |
|
||||
| Multi-timeframe logic | TDX — no native MTF; Pine/MQL5 — supported |
|
||||
| Dynamic position sizing | TDX — indicator only, no position control |
|
||||
| External data (API calls) | All — indicators run offline on chart data only |
|
||||
|
||||
Always add a comment block at the top listing any features that could not be translated.
|
||||
|
||||
## Quality Checklist
|
||||
|
||||
Before outputting the Pine Script:
|
||||
- [ ] `//@version=6` is the first line
|
||||
- [ ] `strategy()` declaration includes commission and initial_capital matching config.json
|
||||
- [ ] All indicator calculations use Pine built-in `ta.*` functions (not manual reimplementation)
|
||||
- [ ] Entry/exit conditions match the Python signal logic semantically
|
||||
- [ ] No `plot()` inside local scopes (if/for/function)
|
||||
- [ ] Ternary operators are on single lines
|
||||
- [ ] Inputs use `input.int()` / `input.float()` so users can tune parameters in TradingView UI
|
||||
- [ ] Alert conditions are included for key signals
|
||||
Before outputting:
|
||||
- [ ] ALL 3 platform sections are included (Pine Script, TDX, MQL5)
|
||||
- [ ] Each platform section has proper header with usage instructions
|
||||
- [ ] Pine Script: `//@version=6` is first line, no plot() in local scope, ternary on single lines
|
||||
- [ ] TDX: all uppercase functions, `:=` for intermediate, `:` for output, `{comments}`
|
||||
- [ ] MQL5: proper handle-based API, `EMPTY_VALUE` for no-signal
|
||||
- [ ] Entry/exit conditions match the Python signal logic semantically across ALL platforms
|
||||
- [ ] Untranslatable features are clearly documented at the top of each section
|
||||
- [ ] Comment header notes the original Vibe-Trading run_id and instrument
|
||||
@@ -0,0 +1,79 @@
|
||||
---
|
||||
name: shadow-account
|
||||
description: "Shadow Account — 从用户交割单提炼盈利模式(3-5 条人话规则)→ 跨 A股/港股/美股/crypto 多市场回测 → 差值归因 → 8-section PDF 报告。叙事:你的影子,没有情绪噪音。"
|
||||
category: analysis
|
||||
---
|
||||
|
||||
# Shadow Account — 影子账户
|
||||
|
||||
## 何时触发
|
||||
|
||||
当用户说 "提炼我的策略" / "训练影子" / "我的打法回测一下" / "我能多赚多少" / "我的盈利模式" 时,加载此 skill。
|
||||
|
||||
**前提**:用户已上传交割单且 `analyze_trade_journal` 已跑过。若没有,先跑 Phase 4a 工具。
|
||||
|
||||
## 工作流(四步)
|
||||
|
||||
1. `extract_shadow_strategy(journal_path=...)`
|
||||
- 返回 `shadow_id` + 3-5 条人话规则
|
||||
- 向用户 confirm:"这些规则像你本人吗?" 如果用户说"不像",提高 `min_support` 重跑
|
||||
2. `run_shadow_backtest(shadow_id=..., journal_path=...)`
|
||||
- 返回 per-market 指标 + `delta_pnl` + attribution breakdown
|
||||
- 默认四市场并跑(china_a/hk/us/crypto)
|
||||
3. `render_shadow_report(shadow_id=...)`
|
||||
- 生成 HTML + PDF(weasyprint 失败时自动降级成 HTML-only)
|
||||
- 返回 `html_path` / `pdf_path` / `delta_pnl`
|
||||
4. (可选)`scan_shadow_signals(shadow_id=...)` — 今日落在影子入场窗口的标的列表(研究用)
|
||||
|
||||
## 产出解读
|
||||
|
||||
### 规则卡
|
||||
每条规则含:`rule_id`、`human_text`(≤30 字)、`support_count`、`coverage_rate`、`holding_days_range`。规则不是"必赚公式",而是"用户盈利时的共性画像"。
|
||||
|
||||
### 回测矩阵
|
||||
- `per_market`:四市场的 Sharpe/年化/最大回撤
|
||||
- `combined`:合并池表现
|
||||
- `equity_curve`:净值时序(进入 PDF Section 3)
|
||||
|
||||
### 差值归因(PDF Section 5 — gut punch)
|
||||
所有数值 signed,正值=影子相对赚更多:
|
||||
- `noise_trades_pnl`:不命中任何规则的真实交易累计 PnL(用户的情绪单)
|
||||
- `early_exit_pnl`:赢单但持仓 < 规则下限,按不足比例折算的机会成本
|
||||
- `late_exit_pnl`:亏单但持仓 > 规则上限,按超额比例折算的放大损失
|
||||
- `overtrading_pnl`:超出规则频率的真实交易 PnL
|
||||
- `missed_signals_pnl`:残差(shadow_pnl − real_pnl − 上面四项之和)
|
||||
|
||||
### 反事实 Top 5
|
||||
按 `|impact|` 排序,列出 5 条"最该做没做 / 最不该做却做了"的交易,带具体日期、原因。
|
||||
|
||||
## 对话模板
|
||||
|
||||
**确认规则**:
|
||||
> 从你 {profitable_roundtrips} 笔盈利回合中提炼出这些规则:{rules}。这些看起来像你本人的打法吗?
|
||||
|
||||
**展示差值**(Section 5):
|
||||
> 影子 PnL **{shadow_pnl:+.0f}** / 你真实 **{real_pnl:+.0f}** / 差值 **{delta_pnl:+.0f}**。其中 **{noise_trades_pnl:+.0f}** 来自不符合你任何盈利规则的"情绪单"。
|
||||
|
||||
**今日扫描**(强制附带免责):
|
||||
> 今日落在你影子入场节奏的标的:{symbols}。**仅研究用,不是买入建议。**
|
||||
|
||||
## 规则翻译 Prompt 模板
|
||||
|
||||
当 `extract_shadow_strategy` 被调用时,可以注入一个 `llm_translator` callable 以把结构化 entry_condition 翻译成中文自然语言:
|
||||
|
||||
```
|
||||
[上下文] 一位散户的盈利回合中,{N} 笔满足同一组条件:
|
||||
market = {market}
|
||||
entry_hour ∈ [{hour_min}, {hour_max}]
|
||||
持有 {hold_lo}-{hold_hi} 天
|
||||
[任务] 用 ≤30 字的中文写一条规则,口吻像用户自述的交易习惯,不要堆术语。
|
||||
[输出] 只返回一行规则文本,不要解释。
|
||||
```
|
||||
|
||||
不注入时走 f-string 模板(见 `extractor._translate_rule`)。
|
||||
|
||||
## 红线
|
||||
|
||||
- **不落单**:这些工具永远不会对接任何下单通道,仅研究输出
|
||||
- **不复制他人策略**:Shadow Account 是"用户自己"的影子,不从社区/公开策略提取规则
|
||||
- **样本不足必报错**:profitable roundtrips < 5 → 直接 raise,不编造
|
||||
@@ -183,6 +183,14 @@ If improvements are needed after evaluation, write `action_items`:
|
||||
- `"Add stop-loss: force close when loss exceeds 5%"`
|
||||
- `"Add volume filter in signal_engine.py: only trigger buy on high volume"`
|
||||
|
||||
## Cross-Market Strategies
|
||||
|
||||
When the user requests a backtest with codes from **different markets** (e.g. `["000001.SZ", "BTC-USDT"]`):
|
||||
- Set `source: "auto"` in `config.json`
|
||||
- The `CompositeEngine` handles calendar alignment, shared capital, and per-market rules automatically
|
||||
- Use volatility-adjusted weights so high-vol assets (crypto) don't dominate the risk budget
|
||||
- See the [cross-market-strategy](../cross-market-strategy/SKILL.md) skill for per-market parameters, vol-adjustment, and example code
|
||||
|
||||
## Supporting Files
|
||||
|
||||
- [examples.md](examples.md) — example call sequence
|
||||
@@ -0,0 +1,213 @@
|
||||
---
|
||||
name: trade-journal
|
||||
description: Analyze a user's trade journal (CSV/Excel broker export). Parses 同花顺/东方财富/富途/generic formats, produces a trading profile and 4 behavior diagnostics (disposition effect, overtrading, chasing, anchoring). Use the `analyze_trade_journal` tool.
|
||||
category: tool
|
||||
---
|
||||
# Trade Journal Analysis
|
||||
|
||||
## Purpose
|
||||
|
||||
Users upload broker exports (交割单) and get an honest, data-grounded portrait
|
||||
of their own trading. Two layers are live:
|
||||
|
||||
- **Profile** — holding days, frequency, win rate, PnL ratio, cumulative PnL,
|
||||
max drawdown, top symbols, market/hourly distribution.
|
||||
- **Behavior diagnostics** — 4 biases, each with severity (low/medium/high)
|
||||
and numeric evidence: disposition effect, overtrading, chasing momentum,
|
||||
anchoring.
|
||||
|
||||
Strategy extraction → backtest bridge lands in Phase 4c.
|
||||
|
||||
Supported formats (auto-detected):
|
||||
- **同花顺** (Tonghuashun) — A-share CSV, typically GBK-encoded
|
||||
- **东方财富** (Eastmoney) — A-share CSV, typically GBK-encoded
|
||||
- **富途** (Futu) — HK/US CSV, UTF-8
|
||||
- **Generic** — any CSV with columns like `datetime/symbol/side/qty/price`
|
||||
|
||||
## Usage
|
||||
|
||||
**Call the `analyze_trade_journal` tool directly. Never run Python from bash.**
|
||||
|
||||
```
|
||||
analyze_trade_journal(file_path="uploads/xxx.csv")
|
||||
analyze_trade_journal(file_path="uploads/xxx.csv", analysis_type="profile")
|
||||
analyze_trade_journal(file_path="uploads/xxx.csv", filter_expr="2026-01 to 2026-03")
|
||||
analyze_trade_journal(file_path="uploads/xxx.csv", filter_expr="symbol=600519.SH")
|
||||
analyze_trade_journal(file_path="uploads/xxx.csv", filter_expr="market=china_a")
|
||||
```
|
||||
|
||||
`analysis_type`:
|
||||
- `full` (default) — profile + behavior (strategy still placeholder)
|
||||
- `profile` — profile metrics only (fastest)
|
||||
- `behavior` — 4 behavior diagnostics only
|
||||
- `strategy` — Phase 4c placeholder
|
||||
|
||||
`filter_expr` (optional):
|
||||
- Date range: `"YYYY-MM to YYYY-MM"` or `"YYYY-MM-DD to YYYY-MM-DD"`
|
||||
- Symbol: `"symbol=600519.SH"` (exact match on qualified symbol)
|
||||
- Market: `"market=china_a|us|hk|crypto"`
|
||||
|
||||
## Return shape (profile subset)
|
||||
|
||||
```json
|
||||
{
|
||||
"status": "ok",
|
||||
"file": "xxx.csv",
|
||||
"format_detected": "tonghuashun",
|
||||
"total_records": 326,
|
||||
"date_range": "2026-01-06 ~ 2026-03-28",
|
||||
"symbols_count": 42,
|
||||
"market": "china_a",
|
||||
"profile": {
|
||||
"total_trades": 326,
|
||||
"total_roundtrips": 118,
|
||||
"avg_holding_days": 3.2,
|
||||
"trade_frequency_per_week": 4.1,
|
||||
"win_rate": 0.48,
|
||||
"profit_loss_ratio": 1.35,
|
||||
"total_pnl": 18240.55,
|
||||
"max_drawdown": -9820.10,
|
||||
"top_symbols": [{"symbol": "600519.SH", "trades": 14, "total_amount": 1.02e6}, ...],
|
||||
"market_distribution": {"china_a": 326},
|
||||
"hourly_distribution": {9: 52, 10: 84, ...},
|
||||
"roundtrips_sample": [{"symbol": "600519.SH", "buy_dt": "...", "sell_dt": "...", "pnl": 3400.1, "pnl_pct": 0.021, "hold_days": 2.5}, ...]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Note: PnL uses FIFO lot matching; unmatched open positions are excluded from
|
||||
win rate / PnL ratio (only closed round-trips count).
|
||||
|
||||
## Presenting results to the user
|
||||
|
||||
Produce a **single markdown report** in the user's language. Lead with the
|
||||
top-line numbers, then section-by-section. Keep it dense — this is retail
|
||||
readers skimming on a phone.
|
||||
|
||||
### Report template
|
||||
|
||||
```
|
||||
## 你的交易画像 — {date_range}
|
||||
|
||||
**总体**
|
||||
- 交易笔数:{total_trades}(完整来回 {total_roundtrips} 次)
|
||||
- 平均持仓:{avg_holding_days} 天
|
||||
- 交易频率:{trade_frequency_per_week} 次/周
|
||||
- 胜率:{win_rate:.0%}
|
||||
- 盈亏比:{profit_loss_ratio}
|
||||
- 累计盈亏:{total_pnl}
|
||||
- 最大回撤:{max_drawdown}
|
||||
|
||||
**最常交易的标的**(前 5 名)
|
||||
| 标的 | 笔数 | 成交额 |
|
||||
|------|------|--------|
|
||||
| ... | ... | ... |
|
||||
|
||||
**市场分布**
|
||||
{market_distribution}
|
||||
|
||||
**交易时段**
|
||||
{hourly_distribution — highlight peak hours}
|
||||
|
||||
**一句话观察**
|
||||
(根据数据写 1-2 句:过度交易?只做窄范围标的?集中在某时段?)
|
||||
```
|
||||
|
||||
Guidance:
|
||||
- If `win_rate < 0.4` AND `profit_loss_ratio < 1.0` → explicit warning: losing
|
||||
on both win rate and payoff. Ask whether they want behavior diagnostics
|
||||
(Phase 4b) or a cooling-off reality check.
|
||||
- If `avg_holding_days < 1` AND `trade_frequency_per_week > 15` → flag
|
||||
intraday-heavy pattern, note that minute-level backtest would be better.
|
||||
- If `symbols_count <= 3` → concentration risk; ask if they want a sector-
|
||||
diversification check.
|
||||
|
||||
## Follow-up dialogue
|
||||
|
||||
After the initial report, users typically ask:
|
||||
- **Time-slice**: "3 月份表现怎么样" → re-call with `filter_expr="2026-03-01 to 2026-03-31"`.
|
||||
- **Symbol deep-dive**: "茅台这只赚了多少" → `filter_expr="symbol=600519.SH"`.
|
||||
- **Market split**: "港股和美股分开看" → two calls, `market=hk` and `market=us`.
|
||||
- **Hypothetical** ("如果我严格止损 -5%") → Phase 4b feature; for now tell the
|
||||
user this is on the roadmap.
|
||||
|
||||
Do NOT re-upload — the file path is still valid for subsequent tool calls
|
||||
in the same session.
|
||||
|
||||
## Error handling
|
||||
|
||||
- `File not found` / `Unsupported extension` — ask user to re-upload.
|
||||
- `Unrecognized trade journal format` — share the detected columns back to
|
||||
the user and ask them to rename the key columns to: `datetime, symbol,
|
||||
side, quantity, price, amount, fee` (generic fallback).
|
||||
- `No trade records parsed` — likely empty file or header-only; ask user to
|
||||
confirm the export contains actual fills.
|
||||
|
||||
## Behavior diagnostics (shape)
|
||||
|
||||
Under `result["behavior"]`:
|
||||
|
||||
```json
|
||||
{
|
||||
"disposition_effect": {
|
||||
"severity": "high",
|
||||
"ratio_loss_to_win_hold": 1.69,
|
||||
"avg_winner_hold_days": 7.4,
|
||||
"avg_loser_hold_days": 12.5,
|
||||
"evidence": "Losing roundtrips held 12.5d vs winning 7.4d (ratio 1.69). Classic disposition pattern."
|
||||
},
|
||||
"overtrading": {
|
||||
"severity": "high",
|
||||
"busy_day_avg_pnl": -2632,
|
||||
"quiet_day_avg_pnl": 759,
|
||||
"evidence": "On busy days (≥3 trades) avg PnL -2632; on quiet days (≤1) avg PnL +759. High activity hurts returns."
|
||||
},
|
||||
"chasing_momentum": {
|
||||
"severity": "medium",
|
||||
"chase_ratio": 0.5,
|
||||
"buys_evaluated": 4,
|
||||
"evidence": "2/4 buys (50%) came after a >3% price run-up in the same symbol. Some chasing tendency."
|
||||
},
|
||||
"anchoring": {
|
||||
"severity": "high",
|
||||
"anchored_symbol_ratio": 0.83,
|
||||
"symbols_evaluated": 6,
|
||||
"anchored_symbols": [...],
|
||||
"evidence": "5/6 frequently-traded symbols stayed in a narrow price band (CV<5%). Strong anchoring."
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
### Detection logic (for user-facing explanation)
|
||||
|
||||
| Bias | Metric | Medium | High |
|
||||
|------|--------|--------|------|
|
||||
| **Disposition effect** | avg_loser_hold / avg_winner_hold | ≥ 1.2 | ≥ 1.5 |
|
||||
| **Overtrading** | (quiet − busy) / \|quiet\| day-PnL gap | ≥ 0.3 | ≥ 1.0 |
|
||||
| **Chasing** | fraction of buys after 3-trade rolling +3% move | ≥ 40% | ≥ 60% |
|
||||
| **Anchoring** | fraction of ≥5-trade symbols with price CV < 5% | ≥ 33% | ≥ 66% |
|
||||
|
||||
### Report section (Chinese)
|
||||
|
||||
```
|
||||
## 行为偏差诊断
|
||||
|
||||
| 偏差 | 严重程度 | 核心证据 |
|
||||
|------|----------|----------|
|
||||
| 处置效应 | {high/medium/low} | {evidence} |
|
||||
| 过度交易 | {...} | {...} |
|
||||
| 追涨杀跌 | {...} | {...} |
|
||||
| 锚定效应 | {...} | {...} |
|
||||
|
||||
**改进建议**(根据检测到的 high/medium 项生成):
|
||||
- 处置效应 high → 写死止损(例如 -8%),盈利持仓不要过早兑现
|
||||
- 过度交易 high → 每日交易次数 <= N 的硬约束
|
||||
- 追涨杀跌 high → 改买回调而不是新高,设置"涨幅 X% 以上当日不追"规则
|
||||
- 锚定效应 high → 扩宽价格带,不要死守某个"心理价"
|
||||
```
|
||||
|
||||
## Phase 4c preview (not yet implemented)
|
||||
|
||||
Strategy extraction → SignalEngine code gen → auto-backtest lands in Phase 4c.
|
||||
When the user asks for it, respond honestly and offer the behavior diagnostics
|
||||
instead (they're live).
|
||||
@@ -0,0 +1,320 @@
|
||||
---
|
||||
name: vnpy-export
|
||||
description: Export a Vibe-Trading backtest strategy to a runnable vnpy CtaTemplate Python class — supports A-share equities, futures, and crypto via BarGenerator + ArrayManager.
|
||||
category: tool
|
||||
---
|
||||
|
||||
## Overview
|
||||
|
||||
This skill translates a Vibe-Trading strategy into a **vnpy `CtaTemplate` subclass** `.py` file
|
||||
that can be loaded directly into the vnpy CTA Strategy App for live trading or vnpy backtesting.
|
||||
|
||||
Output file: `artifacts/vnpy_strategy/<StrategyName>Strategy.py` (inside the run directory).
|
||||
|
||||
vnpy is the most widely-used open-source quant framework in mainland China (39k+ GitHub stars).
|
||||
Use this skill when the user asks to export to vnpy, requests a `/vnpy` command, or wants to
|
||||
run a Vibe-Trading strategy inside vnpy's CTA backtester or live trading engine.
|
||||
|
||||
---
|
||||
|
||||
## Workflow: Export from Backtest Run
|
||||
|
||||
1. `load_skill("vnpy-export")` — read this guide
|
||||
2. `read_file("config.json")` — extract instrument, dates, parameters, interval
|
||||
3. `read_file("code/signal_engine.py")` — understand the Python signal logic
|
||||
4. Determine asset class from `config.json` → choose correct CtaTemplate convention (see below)
|
||||
5. Translate signal logic to CtaTemplate using the reference tables
|
||||
6. `write_file("artifacts/vnpy_strategy/<StrategyName>Strategy.py")` — save the output
|
||||
7. Return the class in a code block with setup instructions
|
||||
|
||||
## Workflow: Generate from Description
|
||||
|
||||
1. `load_skill("vnpy-export")` — read this guide
|
||||
2. Write a CtaTemplate class from the user's strategy description
|
||||
3. `write_file("artifacts/vnpy_strategy/<StrategyName>Strategy.py")` — save the output
|
||||
4. Return the class with setup and usage instructions
|
||||
|
||||
---
|
||||
|
||||
## Asset Class Conventions
|
||||
|
||||
vnpy uses the same `CtaTemplate` base class for all asset types, but parameter conventions differ:
|
||||
|
||||
| Asset Class | Instrument Example | `vt_symbol` Format | Position Unit |
|
||||
|-------------|-------------------|---------------------|---------------|
|
||||
| A-share stock | Ping An Bank | `000001.SZSE` | shares (整手, min 100) |
|
||||
| Futures | IF2406 | `IF2406.CFFEX` | lots |
|
||||
| Crypto | BTC/USDT | `BTC/USDT.BINANCE` | coin units |
|
||||
|
||||
For **stocks**: use `buy` / `sell` only (no short selling unless margin account).
|
||||
For **futures / crypto**: use all four directions — `buy`, `sell`, `short`, `cover`.
|
||||
|
||||
---
|
||||
|
||||
## CtaTemplate Structure
|
||||
|
||||
Every strategy must subclass `CtaTemplate` and implement these methods:
|
||||
|
||||
| Method | Purpose |
|
||||
|--------|---------|
|
||||
| `__init__` | Declare parameters, variables, BarGenerator, ArrayManager |
|
||||
| `on_init` | Called once at startup; call `load_bar(n)` to warm up indicators |
|
||||
| `on_start` | Called when strategy is started by user |
|
||||
| `on_stop` | Called when strategy is stopped |
|
||||
| `on_tick` | Receives live tick data; forward to BarGenerator |
|
||||
| `on_bar` | Main logic — called once per bar by BarGenerator |
|
||||
| `on_order` | Order status updates |
|
||||
| `on_trade` | Fill notifications |
|
||||
| `on_stop_order` | Stop-order status (if using stop orders) |
|
||||
|
||||
**Always call** `self.cancel_all()` at the start of `on_bar` to avoid stale orders.
|
||||
**Always call** `self.put_event()` at the end of `on_bar` to refresh the UI.
|
||||
|
||||
---
|
||||
|
||||
## Full Template
|
||||
|
||||
See `scripts/cta_template.py` for a complete, runnable example (MA crossover).
|
||||
The template below is the canonical skeleton — replace the `# SIGNAL LOGIC` section:
|
||||
|
||||
```python
|
||||
from vnpy.app.cta_strategy import (
|
||||
CtaTemplate,
|
||||
StopOrder,
|
||||
TickData,
|
||||
BarData,
|
||||
TradeData,
|
||||
OrderData,
|
||||
BarGenerator,
|
||||
ArrayManager,
|
||||
)
|
||||
|
||||
|
||||
class {{StrategyName}}Strategy(CtaTemplate):
|
||||
"""
|
||||
Vibe-Trading export — {{StrategyName}}
|
||||
Generated from run: {{run_id}}
|
||||
Instrument: {{vt_symbol}}
|
||||
"""
|
||||
|
||||
author = "Vibe-Trading"
|
||||
|
||||
# ── Parameters (editable in vnpy UI) ──────────────────────────────────
|
||||
{{param_name}} = {{param_default}} # add one line per parameter
|
||||
|
||||
parameters = [{{param_list_as_strings}}]
|
||||
|
||||
# ── Variables (displayed in vnpy UI, reset on strategy restart) ────────
|
||||
{{var_name}} = 0.0 # add one line per runtime variable
|
||||
|
||||
variables = [{{var_list_as_strings}}]
|
||||
|
||||
def __init__(self, cta_engine, strategy_name, vt_symbol, setting):
|
||||
super().__init__(cta_engine, strategy_name, vt_symbol, setting)
|
||||
self.bg = BarGenerator(self.on_bar)
|
||||
self.am = ArrayManager()
|
||||
|
||||
# initialise variable attributes to match class-level defaults
|
||||
# (vnpy requires instance attributes for variables declared above)
|
||||
|
||||
def on_init(self):
|
||||
self.write_log("Strategy initialised")
|
||||
self.load_bar({{warmup_bars}}) # load enough bars to warm up all indicators
|
||||
|
||||
def on_start(self):
|
||||
self.write_log("Strategy started")
|
||||
self.put_event()
|
||||
|
||||
def on_stop(self):
|
||||
self.write_log("Strategy stopped")
|
||||
|
||||
def on_tick(self, tick: TickData):
|
||||
self.bg.update_tick(tick)
|
||||
|
||||
def on_bar(self, bar: BarData):
|
||||
self.cancel_all()
|
||||
|
||||
am = self.am
|
||||
am.update_bar(bar)
|
||||
if not am.inited:
|
||||
return
|
||||
|
||||
# ── INDICATOR CALCULATIONS ──────────────────────────────────────────
|
||||
# translate indicators from signal_engine.py using the mapping table
|
||||
|
||||
# ── SIGNAL LOGIC ───────────────────────────────────────────────────
|
||||
# set cross_over / cross_under (or long_signal / short_signal) here
|
||||
|
||||
# ── ORDER EXECUTION ────────────────────────────────────────────────
|
||||
if cross_over:
|
||||
if self.pos == 0:
|
||||
self.buy(bar.close_price, 1)
|
||||
elif self.pos < 0:
|
||||
self.cover(bar.close_price, 1)
|
||||
self.buy(bar.close_price, 1)
|
||||
elif cross_under:
|
||||
if self.pos == 0:
|
||||
self.short(bar.close_price, 1)
|
||||
elif self.pos > 0:
|
||||
self.sell(bar.close_price, 1)
|
||||
self.short(bar.close_price, 1)
|
||||
|
||||
self.put_event()
|
||||
|
||||
def on_order(self, order: OrderData):
|
||||
pass
|
||||
|
||||
def on_trade(self, trade: TradeData):
|
||||
self.put_event()
|
||||
|
||||
def on_stop_order(self, stop_order: StopOrder):
|
||||
pass
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Python → ArrayManager Indicator Mapping
|
||||
|
||||
`ArrayManager` is vnpy's built-in vectorised indicator library. Always prefer it over pandas
|
||||
when the equivalent method exists — it is faster and avoids look-ahead bias.
|
||||
|
||||
| Python (Vibe-Trading / pandas / ta-lib) | vnpy ArrayManager |
|
||||
|----------------------------------------|-------------------|
|
||||
| `df['close'].rolling(n).mean()` | `am.sma(n)` |
|
||||
| `df['close'].ewm(span=n).mean()` | `am.ema(n)` |
|
||||
| `ta.RSI(close, n)` | `am.rsi(n)` |
|
||||
| `ta.MACD(close, 12, 26, 9)` | `am.macd(12, 26, 9)` → `(macd, signal, hist)` |
|
||||
| Bollinger Bands | `am.boll(n, dev)` → `(mid, upper, lower)` |
|
||||
| ATR | `am.atr(n)` |
|
||||
| ADX | `am.adx(n)` |
|
||||
| `df['close'].rolling(n).std()` | `am.std(n)` |
|
||||
| Stochastic K, D | `am.kd(n, m)` → `(k, d)` |
|
||||
| `df['high'].rolling(n).max()` | `am.high_array[-n:].max()` |
|
||||
| `df['low'].rolling(n).min()` | `am.low_array[-n:].min()` |
|
||||
| Donchian channel | `am.donchian(n)` → `(upper, lower)` |
|
||||
| `df['close'].shift(1)` (previous bar) | `am.close_array[-2]` |
|
||||
| Last N bars as array | `am.sma(n, array=True)` (returns full array) |
|
||||
|
||||
**Using arrays**: pass `array=True` to get the full history array (e.g. for crossover detection):
|
||||
|
||||
```python
|
||||
fast_ma = am.sma(self.fast_window, array=True)
|
||||
cross_over = fast_ma[-1] > slow_ma[-1] and fast_ma[-2] <= slow_ma[-2]
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Signal → Order Mapping
|
||||
|
||||
| Vibe-Trading signal | Position check | vnpy call |
|
||||
|---------------------|---------------|-----------|
|
||||
| Long entry | `self.pos == 0` | `self.buy(price, volume)` |
|
||||
| Long entry (reverse from short) | `self.pos < 0` | `self.cover(price, vol); self.buy(price, vol)` |
|
||||
| Long exit | `self.pos > 0` | `self.sell(price, volume)` |
|
||||
| Short entry | `self.pos == 0` | `self.short(price, volume)` |
|
||||
| Short entry (reverse from long) | `self.pos > 0` | `self.sell(price, vol); self.short(price, vol)` |
|
||||
| Short exit | `self.pos < 0` | `self.cover(price, volume)` |
|
||||
| Close all (stop signal) | any | `self.cancel_all()` then `sell` / `cover` as needed |
|
||||
|
||||
**Price conventions**:
|
||||
- For backtesting: use `bar.close_price` (market order equivalent)
|
||||
- For live trading with limit orders: use `bar.close_price` ± a small offset (e.g. `* 1.001`)
|
||||
- For stop orders: use `self.buy_stop(trigger, volume)` / `self.short_stop(trigger, volume)`
|
||||
|
||||
**Volume conventions**:
|
||||
- Stocks: volume in shares; must be a multiple of 100 (round lots)
|
||||
- Futures: volume in lots (usually 1 for CtaTemplate strategies)
|
||||
- Crypto: volume in base-currency units (e.g., BTC)
|
||||
|
||||
---
|
||||
|
||||
## Multi-Timeframe Strategies
|
||||
|
||||
When the Vibe-Trading strategy uses multiple timeframes (e.g., daily signal, hourly entry):
|
||||
|
||||
```python
|
||||
def __init__(self, ...):
|
||||
super().__init__(...)
|
||||
self.bg = BarGenerator(self.on_bar, 5, self.on_5min_bar) # 5-min bars
|
||||
self.bg_d = BarGenerator(self.on_bar, window=1, on_window_bar=self.on_daily_bar,
|
||||
interval=Interval.DAILY) # daily bars
|
||||
self.am = ArrayManager()
|
||||
self.am_d = ArrayManager(size=100) # daily ArrayManager
|
||||
|
||||
def on_bar(self, bar: BarData):
|
||||
self.bg.update_bar(bar) # feeds 5-min generator
|
||||
|
||||
def on_5min_bar(self, bar: BarData):
|
||||
self.bg_d.update_bar(bar) # feeds daily generator
|
||||
# put intraday entry logic here
|
||||
|
||||
def on_daily_bar(self, bar: BarData):
|
||||
self.am_d.update_bar(bar)
|
||||
# put daily trend-filter logic here
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Output File Instructions
|
||||
|
||||
Save the generated file to: `artifacts/vnpy_strategy/<StrategyName>Strategy.py`
|
||||
|
||||
To load in vnpy:
|
||||
|
||||
1. Copy the file to your vnpy project's `strategies/` folder (or any folder on `sys.path`)
|
||||
2. Open the vnpy Trader → CTA Strategy App
|
||||
3. Click **Add Strategy** → select `<StrategyName>Strategy` from the dropdown
|
||||
4. Set `vt_symbol` (e.g. `IF2406.CFFEX`) and adjust parameters
|
||||
5. Click **Init** → **Start** to begin
|
||||
|
||||
To run the vnpy backtester:
|
||||
|
||||
```python
|
||||
from vnpy.app.cta_backtester import BacktestingEngine
|
||||
from vnpy.trader.constant import Interval
|
||||
|
||||
engine = BacktestingEngine()
|
||||
engine.set_parameters(
|
||||
vt_symbol="000001.SZSE",
|
||||
interval=Interval.DAILY,
|
||||
start=datetime(2020, 1, 1),
|
||||
end=datetime(2024, 1, 1),
|
||||
rate=0.0003,
|
||||
slippage=0.02,
|
||||
size=1,
|
||||
pricetick=0.01,
|
||||
capital=1_000_000,
|
||||
)
|
||||
engine.add_strategy({{StrategyName}}Strategy, {})
|
||||
engine.load_data()
|
||||
engine.run_backtesting()
|
||||
df = engine.calculate_result()
|
||||
engine.calculate_statistics()
|
||||
engine.show_chart()
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Quality Checklist
|
||||
|
||||
Before saving the output file:
|
||||
|
||||
- [ ] Class name ends with `Strategy` and matches the filename
|
||||
- [ ] All `parameters` entries have matching class-level defaults and `__init__` instance attributes
|
||||
- [ ] All `variables` entries have matching instance attributes initialised in `__init__`
|
||||
- [ ] `on_bar` calls `self.cancel_all()` at the start
|
||||
- [ ] `on_bar` calls `self.put_event()` at the end
|
||||
- [ ] `on_bar` returns early if `not am.inited`
|
||||
- [ ] Position direction checked with `self.pos` before every order call
|
||||
- [ ] Stocks: no `short` / `cover` calls unless margin trading is explicitly requested
|
||||
- [ ] `load_bar(n)` warmup in `on_init` is at least `max(all indicator windows) + 2`
|
||||
- [ ] Comment block at top of file notes the original Vibe-Trading `run_id` and instrument
|
||||
|
||||
---
|
||||
|
||||
## References
|
||||
|
||||
- vnpy CtaTemplate source: `vnpy/app/cta_strategy/template.py`
|
||||
- ArrayManager source: `vnpy/app/cta_strategy/base.py`
|
||||
- Official docs: https://www.vnpy.com/docs/cn/cta_strategy.html
|
||||
- Example strategies (official): `vnpy/app/cta_strategy/strategies/`
|
||||
@@ -0,0 +1,132 @@
|
||||
"""
|
||||
Vibe-Trading → vnpy export: MA crossover strategy template.
|
||||
|
||||
This file is the reference implementation for the vnpy-export skill.
|
||||
Copy it to your vnpy project's strategies/ folder and adjust parameters.
|
||||
|
||||
Requirements:
|
||||
pip install vnpy vnpy_ctp (or vnpy_tts for paper trading)
|
||||
|
||||
Usage in vnpy Trader:
|
||||
CTA Strategy App → Add Strategy → MaCrossStrategy
|
||||
Set vt_symbol, e.g. "IF2406.CFFEX" (futures) or "000001.SZSE" (A-share)
|
||||
"""
|
||||
|
||||
from vnpy.app.cta_strategy import (
|
||||
CtaTemplate,
|
||||
StopOrder,
|
||||
TickData,
|
||||
BarData,
|
||||
TradeData,
|
||||
OrderData,
|
||||
BarGenerator,
|
||||
ArrayManager,
|
||||
)
|
||||
|
||||
|
||||
class MaCrossStrategy(CtaTemplate):
|
||||
"""
|
||||
Dual moving-average crossover — generated by Vibe-Trading.
|
||||
|
||||
Signals:
|
||||
Long entry : fast MA crosses above slow MA (golden cross)
|
||||
Long exit : fast MA crosses below slow MA (death cross)
|
||||
Short entry : fast MA crosses below slow MA (futures / crypto only)
|
||||
Short exit : fast MA crosses above slow MA
|
||||
|
||||
Supports equity (long-only) and futures/crypto (long + short).
|
||||
Set `trade_long_only = True` for A-share stocks.
|
||||
"""
|
||||
|
||||
author = "Vibe-Trading"
|
||||
|
||||
# ── Parameters (editable in the vnpy UI) ─────────────────────────────
|
||||
fast_window: int = 10
|
||||
slow_window: int = 30
|
||||
trade_long_only: bool = False # True for A-share stocks (no short selling)
|
||||
|
||||
parameters = ["fast_window", "slow_window", "trade_long_only"]
|
||||
|
||||
# ── Variables (live state displayed in the vnpy UI) ───────────────────
|
||||
fast_ma0: float = 0.0 # fast MA, current bar
|
||||
fast_ma1: float = 0.0 # fast MA, previous bar
|
||||
slow_ma0: float = 0.0 # slow MA, current bar
|
||||
slow_ma1: float = 0.0 # slow MA, previous bar
|
||||
|
||||
variables = ["fast_ma0", "fast_ma1", "slow_ma0", "slow_ma1"]
|
||||
|
||||
def __init__(self, cta_engine, strategy_name, vt_symbol, setting):
|
||||
super().__init__(cta_engine, strategy_name, vt_symbol, setting)
|
||||
|
||||
self.bg = BarGenerator(self.on_bar)
|
||||
self.am = ArrayManager()
|
||||
|
||||
self.fast_ma0 = 0.0
|
||||
self.fast_ma1 = 0.0
|
||||
self.slow_ma0 = 0.0
|
||||
self.slow_ma1 = 0.0
|
||||
|
||||
def on_init(self):
|
||||
self.write_log("Strategy initialised")
|
||||
self.load_bar(self.slow_window + 2)
|
||||
|
||||
def on_start(self):
|
||||
self.write_log("Strategy started")
|
||||
self.put_event()
|
||||
|
||||
def on_stop(self):
|
||||
self.write_log("Strategy stopped")
|
||||
|
||||
def on_tick(self, tick: TickData):
|
||||
self.bg.update_tick(tick)
|
||||
|
||||
def on_bar(self, bar: BarData):
|
||||
self.cancel_all()
|
||||
|
||||
am = self.am
|
||||
am.update_bar(bar)
|
||||
if not am.inited:
|
||||
return
|
||||
|
||||
# ── Indicators ───────────────────────────────────────────────────
|
||||
fast_ma = am.sma(self.fast_window, array=True)
|
||||
slow_ma = am.sma(self.slow_window, array=True)
|
||||
|
||||
self.fast_ma0 = fast_ma[-1]
|
||||
self.fast_ma1 = fast_ma[-2]
|
||||
self.slow_ma0 = slow_ma[-1]
|
||||
self.slow_ma1 = slow_ma[-2]
|
||||
|
||||
# ── Crossover detection ──────────────────────────────────────────
|
||||
cross_over = self.fast_ma0 > self.slow_ma0 and self.fast_ma1 <= self.slow_ma1
|
||||
cross_under = self.fast_ma0 < self.slow_ma0 and self.fast_ma1 >= self.slow_ma1
|
||||
|
||||
# ── Order execution ──────────────────────────────────────────────
|
||||
if cross_over:
|
||||
if self.pos == 0:
|
||||
self.buy(bar.close_price, 1)
|
||||
elif self.pos < 0:
|
||||
self.cover(bar.close_price, 1)
|
||||
self.buy(bar.close_price, 1)
|
||||
|
||||
elif cross_under:
|
||||
if self.trade_long_only:
|
||||
if self.pos > 0:
|
||||
self.sell(bar.close_price, 1)
|
||||
else:
|
||||
if self.pos == 0:
|
||||
self.short(bar.close_price, 1)
|
||||
elif self.pos > 0:
|
||||
self.sell(bar.close_price, 1)
|
||||
self.short(bar.close_price, 1)
|
||||
|
||||
self.put_event()
|
||||
|
||||
def on_order(self, order: OrderData):
|
||||
pass
|
||||
|
||||
def on_trade(self, trade: TradeData):
|
||||
self.put_event()
|
||||
|
||||
def on_stop_order(self, stop_order: StopOrder):
|
||||
pass
|
||||
@@ -1,7 +1,9 @@
|
||||
"""Swarm YAML preset loader.
|
||||
|
||||
Reads YAML preset files from agent/config/swarm/ and parses them into
|
||||
SwarmRun / SwarmAgentSpec / SwarmTask data models.
|
||||
Reads YAML preset files from the bundled ``presets/`` directory next to this
|
||||
module and parses them into SwarmRun / SwarmAgentSpec / SwarmTask data models.
|
||||
Keeping the YAMLs inside the ``src.swarm`` package guarantees identical
|
||||
behavior under editable installs and built wheels.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
@@ -14,7 +16,7 @@ import yaml
|
||||
|
||||
from src.swarm.models import RunStatus, SwarmAgentSpec, SwarmRun, SwarmTask, TaskStatus
|
||||
|
||||
PRESETS_DIR = Path(__file__).resolve().parents[2] / "config" / "swarm"
|
||||
PRESETS_DIR = Path(__file__).resolve().parent / "presets"
|
||||
|
||||
|
||||
def load_preset(name: str) -> dict:
|
||||
|
||||
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
File renamed without changes.
+51
-14
@@ -9,7 +9,12 @@ from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import threading
|
||||
from concurrent.futures import Future, ThreadPoolExecutor, as_completed
|
||||
from concurrent.futures import (
|
||||
Future,
|
||||
ThreadPoolExecutor,
|
||||
TimeoutError as FuturesTimeoutError,
|
||||
as_completed,
|
||||
)
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from typing import Callable
|
||||
@@ -338,9 +343,14 @@ class SwarmRuntime:
|
||||
def _event_callback(event: SwarmEvent) -> None:
|
||||
self._emit_event(run.id, event)
|
||||
|
||||
with ThreadPoolExecutor(max_workers=self._max_workers) as executor:
|
||||
futures: dict[Future[WorkerResult], str] = {}
|
||||
|
||||
# Manual executor lifecycle (not `with`) so KeyboardInterrupt and
|
||||
# the layer deadline don't block main on `shutdown(wait=True)` —
|
||||
# `wait=False + cancel_futures=True` lets pending work drop and
|
||||
# the CLI return immediately. Running workers finish naturally.
|
||||
executor = ThreadPoolExecutor(max_workers=self._max_workers)
|
||||
futures: dict[Future[WorkerResult], str] = {}
|
||||
layer_budget = 0 # seconds — max per-task (retries × timeout) across layer
|
||||
try:
|
||||
for tid in layer_task_ids:
|
||||
task = task_store.load_task(tid)
|
||||
agent_spec = agent_map.get(task.agent_id)
|
||||
@@ -378,18 +388,45 @@ class SwarmRuntime:
|
||||
run_id=run.id,
|
||||
)
|
||||
futures[future] = tid
|
||||
per_task_budget = agent_spec.timeout_seconds * (agent_spec.max_retries + 1)
|
||||
layer_budget = max(layer_budget, per_task_budget)
|
||||
|
||||
# Collect results
|
||||
for future in as_completed(futures):
|
||||
tid = futures[future]
|
||||
try:
|
||||
results[tid] = future.result()
|
||||
except Exception as exc:
|
||||
logger.error("Worker for task %s raised exception", tid, exc_info=True)
|
||||
results[tid] = WorkerResult(
|
||||
status="failed", summary="",
|
||||
error=str(exc),
|
||||
# Collect results with a hard layer-level deadline — defends against
|
||||
# worker threads stuck in C extensions / blocked I/O that bypass the
|
||||
# in-loop timeout check (issue #42).
|
||||
deadline_buffer = 60
|
||||
layer_deadline = layer_budget + deadline_buffer if layer_budget else None
|
||||
|
||||
try:
|
||||
for future in as_completed(futures, timeout=layer_deadline):
|
||||
tid = futures[future]
|
||||
try:
|
||||
results[tid] = future.result()
|
||||
except Exception as exc:
|
||||
logger.error("Worker for task %s raised exception", tid, exc_info=True)
|
||||
results[tid] = WorkerResult(
|
||||
status="failed", summary="",
|
||||
error=str(exc),
|
||||
)
|
||||
except FuturesTimeoutError:
|
||||
for pending, tid in futures.items():
|
||||
if tid in results:
|
||||
continue
|
||||
pending.cancel()
|
||||
logger.error(
|
||||
"Worker for task %s exceeded layer deadline (%ds)",
|
||||
tid, layer_deadline,
|
||||
)
|
||||
results[tid] = WorkerResult(
|
||||
status="timeout", summary="",
|
||||
error=f"Worker exceeded layer deadline of {layer_deadline}s",
|
||||
)
|
||||
except KeyboardInterrupt:
|
||||
cancel_event.set()
|
||||
logger.warning("Swarm layer interrupted — cancelling pending workers")
|
||||
raise
|
||||
finally:
|
||||
executor.shutdown(wait=False, cancel_futures=True)
|
||||
|
||||
return results
|
||||
|
||||
|
||||
Loaded 100 of 153 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user